TL;DR: An AI-native engineer has rebuilt the working loop around AI coding agents, including the tests and reviews that catch wrong output, while a traditional engineer writes and reviews most code by hand and adds AI at the edges. With 90% of developers already using AI at work, according to Google's 2025 DORA report, tool use no longer separates the two. Screen for the verification habit instead, because Veracode's Spring 2026 tests still found security flaws in 45% of AI-generated code.
Two engineers on the same team can hold the same Cursor licence and give their reviewers different weeks.
One writes the failing test before asking the agent for code, so a wrong answer dies in CI within a minute. The other reads the output, judges it plausible and opens the pull request. The habit around the tool is what separates an AI-native engineer from a traditional one who happens to use AI.
- 1In METR's 2025 trial, experienced maintainers took 19% longer with AI while believing it had made them 20% faster.
- 2METR's February 2026 follow-up estimated an 18% time saving for returning developers, which METR itself calls "only very weak evidence".
- 3AI-generated Java passed Veracode's security checks 29% of the time, against 62% for Python.
- 4PwC's 2026 Barometer puts the wage premium for AI skills in job ads at 62%, up from 57% a year earlier.
What is the difference between an AI-native engineer and a traditional engineer?
An AI-native engineer is a software engineer whose default workflow runs through AI coding agents such as Claude Code, Codex or Cursor. Around that workflow sit checks: a test before generation, a read of every diff, and generated code treated as untrusted input.
A traditional engineer writes and reviews most code by hand and uses AI for lookups and autocomplete, if at all. Both labels describe how someone works, not a job title. A backend, frontend or DevOps engineer can be either.
Our guide to hiring AI-native engineers covers the full toolkit, from agent frameworks to MCP. The profile below is what we see when we screen both types. The usage hours and onboarding times come from our own placements, not from a survey.
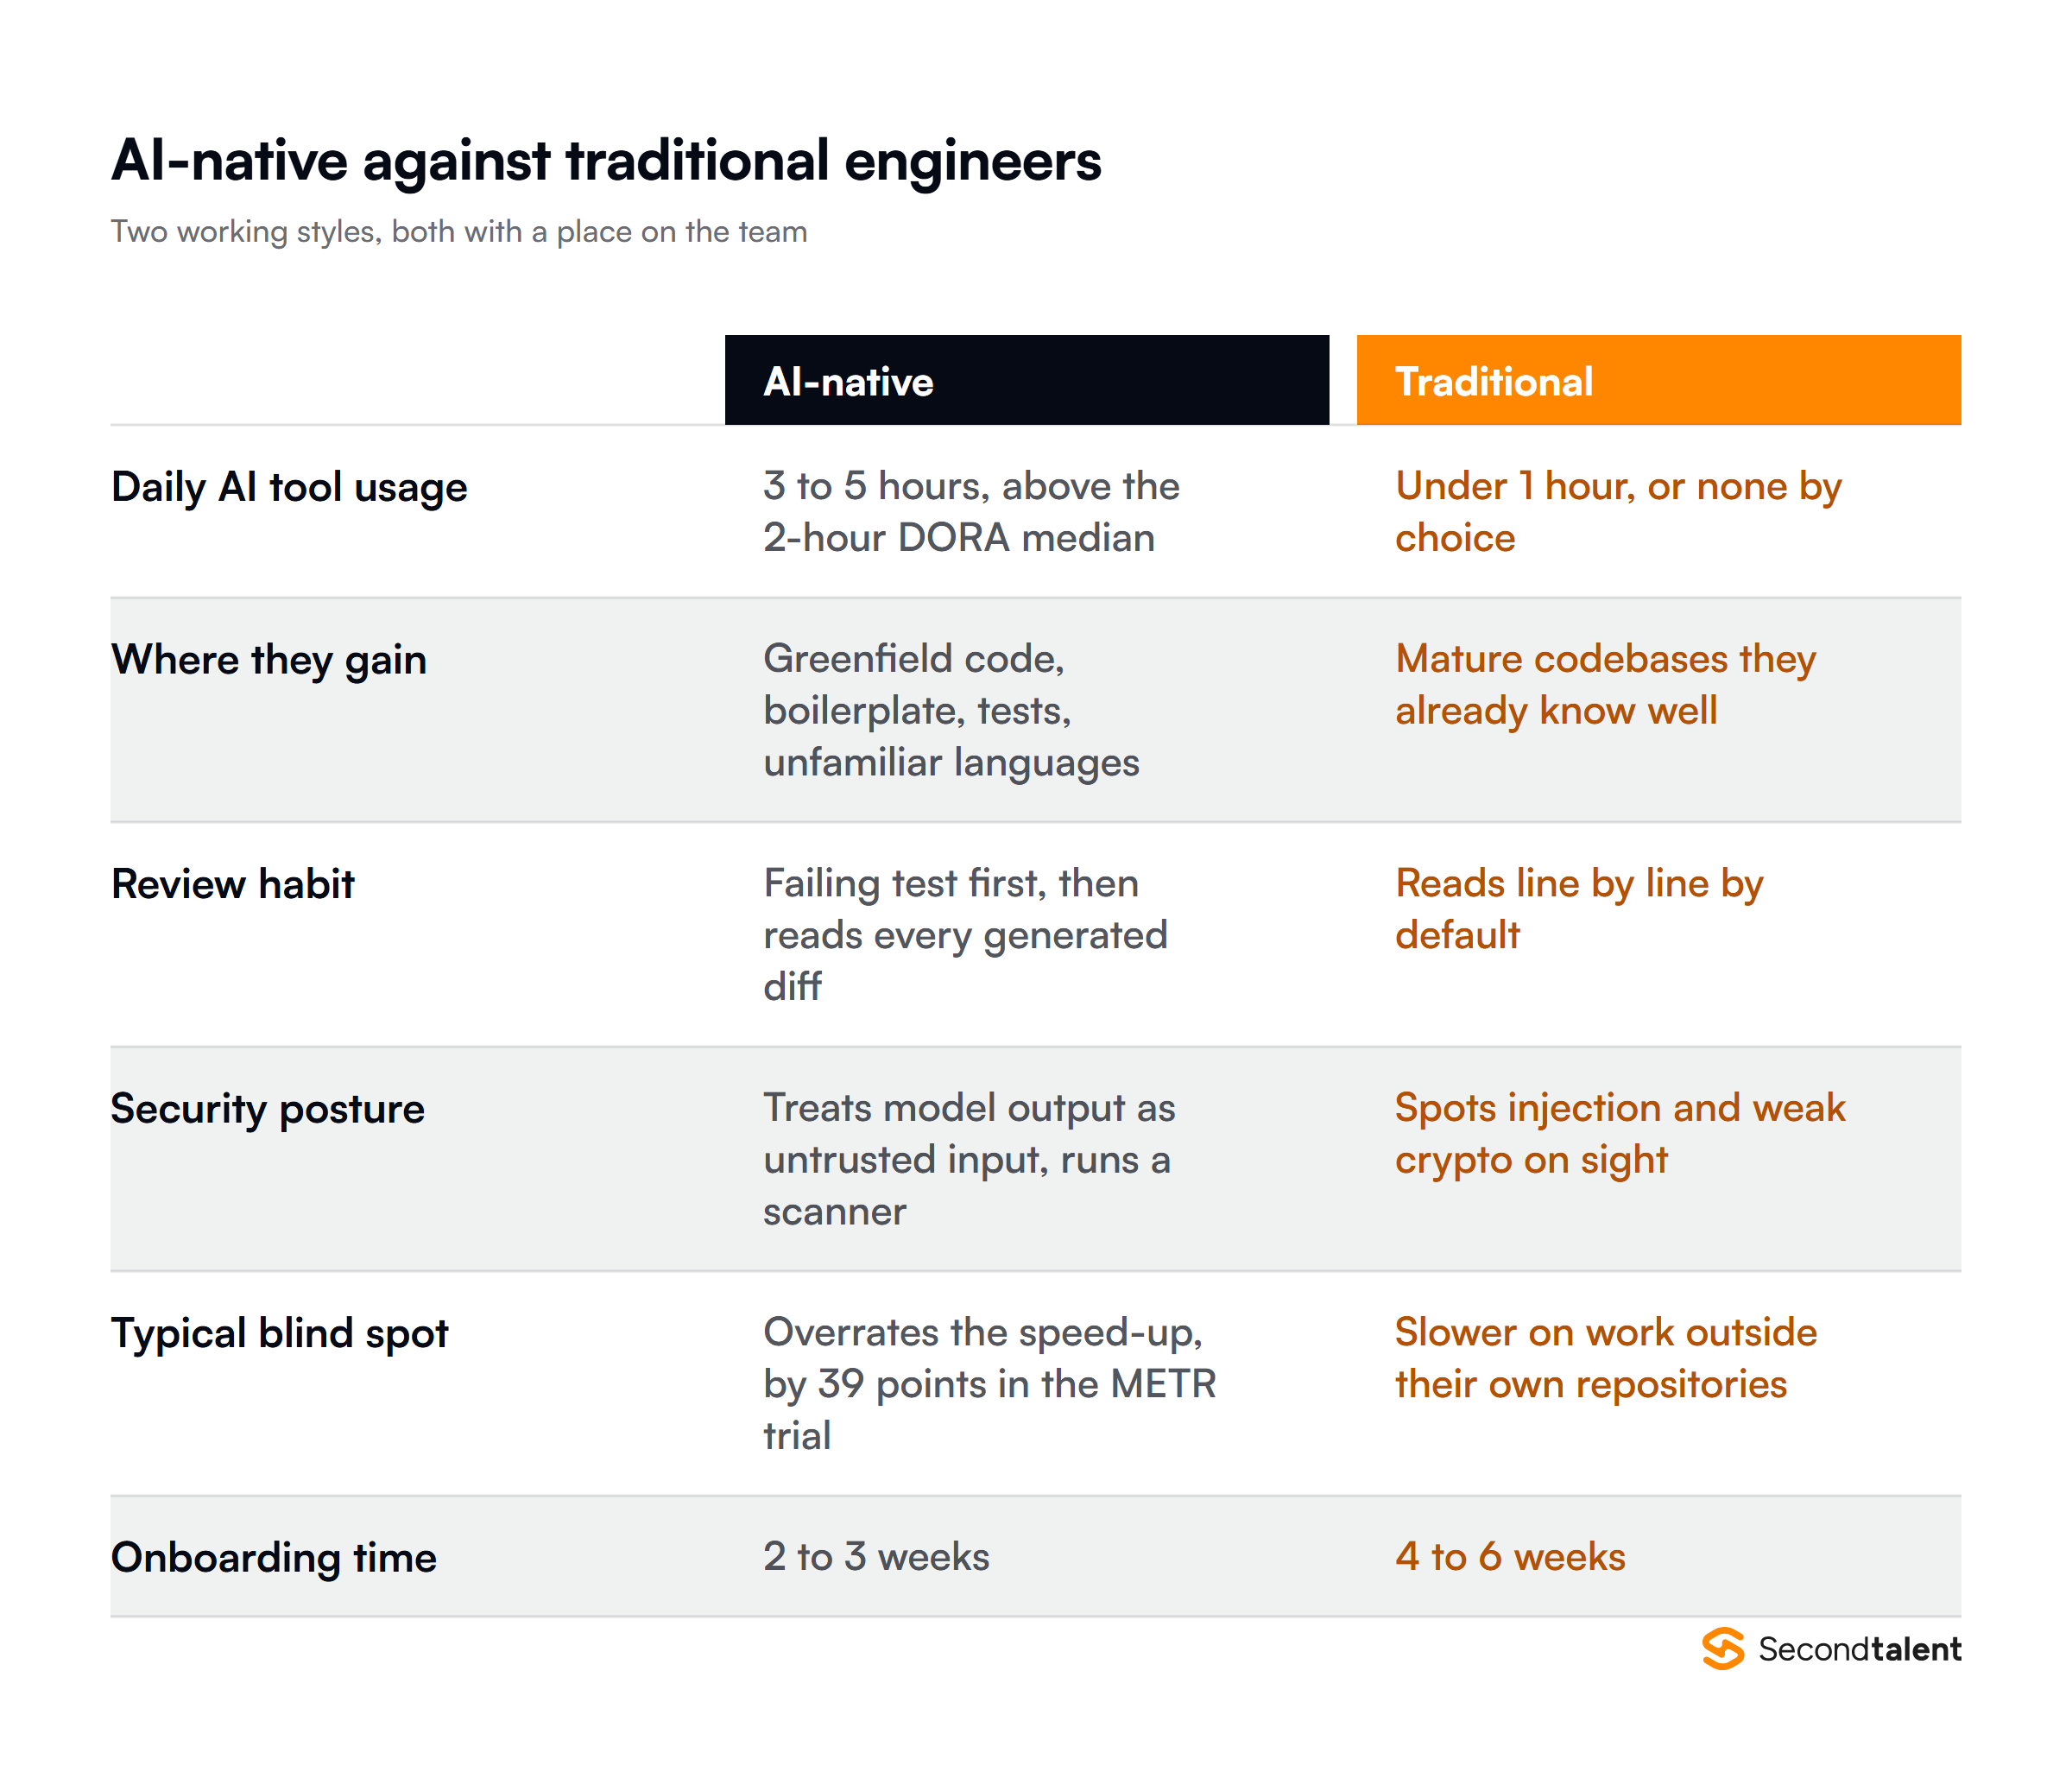
Neither profile wins in general. The AI-native engineer gains on greenfield code, tests and unfamiliar languages. The traditional engineer is often faster inside a mature codebase they know well, which is the setting where METR measured AI slowing experts down.
What the research says about AI productivity
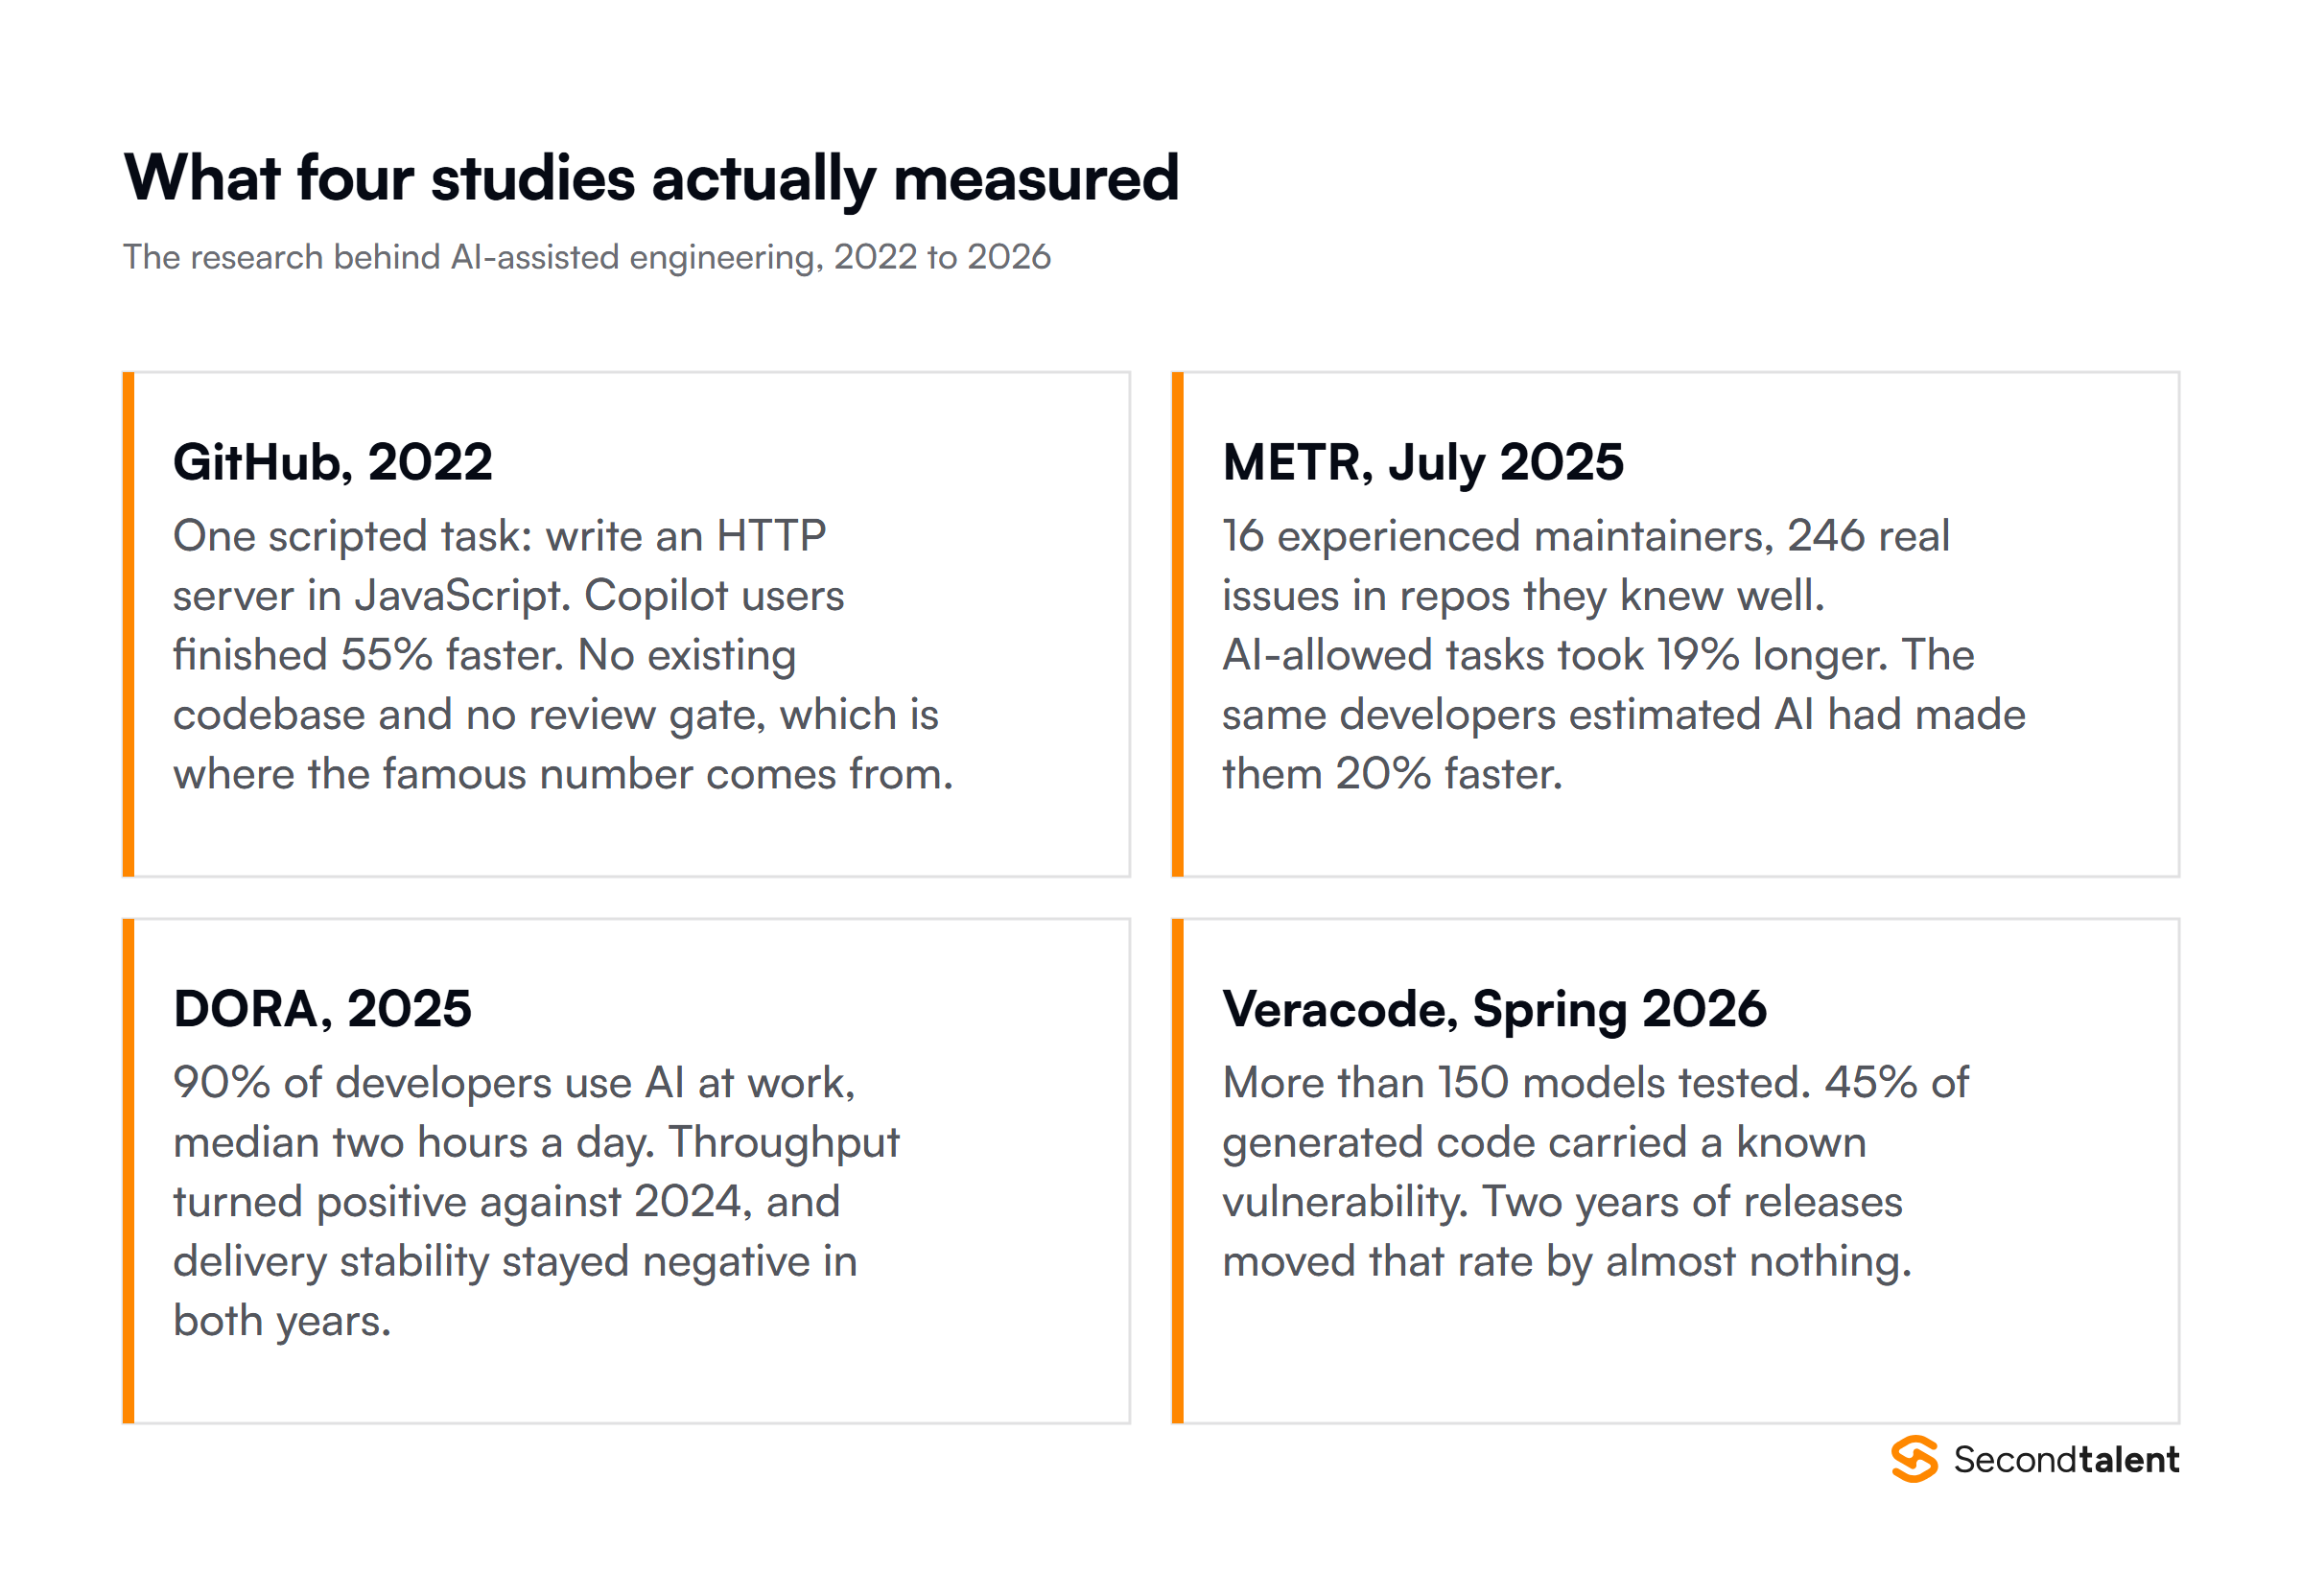
The most quoted number comes from GitHub's 2022 experiment. Ninety-five professional developers wrote an HTTP server in JavaScript, and the Copilot group finished 55% faster: 1 hour 11 minutes against 2 hours 41 minutes. It was one scripted task, with no existing codebase and no review gate.
METR's randomised controlled trial tested the opposite setting. Sixteen experienced open-source developers worked on 246 real issues in large repositories they knew, using Cursor Pro with Claude 3.5 and 3.7 Sonnet. Tasks where AI was allowed took 19% longer. They had forecast a 24% speed-up and still estimated 20% afterwards.
METR now marks that result as out of date. Its February 2026 update covered 57 developers and more than 800 tasks with late-2025 tools. Returning developers took an estimated 18% less time with AI, with a confidence interval from 38% less to 9% more. New recruits saved an estimated 4%.
METR calls that data "only very weak evidence" for the size of the gain. A growing share of developers declined to take part because they did not want to work without AI, so the most enthusiastic users and the tasks AI suits best dropped out of the sample. The perception gap from 2025 still stands: engineers are poor judges of their own speed-up.
Google's 2025 DORA report, built on nearly 5,000 technology professionals, puts AI use at work at 90%, and the median user spends two hours a day with it. AI adoption now has a positive relationship with delivery throughput, which was negative the year before. Its relationship with delivery stability stayed negative. DORA's authors describe AI as an amplifier of whatever a team already does well or badly.
Trust has not kept pace with use. In Stack Overflow's 2025 survey, 84% of respondents use or plan to use AI tools, and 50.6% of professional developers use them daily. Few trust what comes back:
Developers in Asia report the same split. A survey by Agoda and Macramé Consulting of more than 600 developers in Indonesia, Malaysia, Singapore, Thailand, the Philippines, Vietnam and India found 95% using AI weekly. Yet 70% routinely rework its output for correctness, and 67% review all AI-generated code before merging.
Skills: where each engineer is stronger
The AI-native engineer's skills sit around the agent. The traditional engineer's skills sit underneath it. A strong senior hire carries both sets in different proportions.
- Task routing: knows which work to hand the agent and which to keep
- Context engineering: a rules file such as AGENTS.md or CLAUDE.md, the failing test, the constraint
- Verification before trust: a test, a reproduction or a scanner before review
- Builds LLM features with evals in CI and writes MCP servers
- Absorbs tool changes without losing a sprint
- Explains every line in the diff, which auditors in finance and healthcare ask for
- Reads security flaws on sight, including the ones models keep missing
- System design across service boundaries
- Debugs from the trace, not from a prompt
- Mentors juniors on fundamentals
Security is where the traditional skill set earns its place. Veracode's Spring 2026 update, covering more than 150 models, found that only 55% of generation tasks produced secure code. That rate has barely moved in two years, while syntax correctness passed 95%. Java fared worst at 29%, against 62% for Python, 58% for C# and 57% for JavaScript.
The failures cluster in a few places. Models now pass 82% of SQL injection tests and 86% of insecure-cryptography tests, but only 15% for cross-site scripting and 13% for log injection. A reviewer who checks output encoding and log handling by habit catches what the model misses.
Mentorship is the other thing traditional engineers bring. Juniors who learn fundamentals from a strong reviewer get better at judging AI output than juniors who learn only from the agent. On the AI-native side, our AI agent developer role guide covers the build skills, and our list of AI code review tools covers the tooling that sits between the two.
How to spot each in an interview
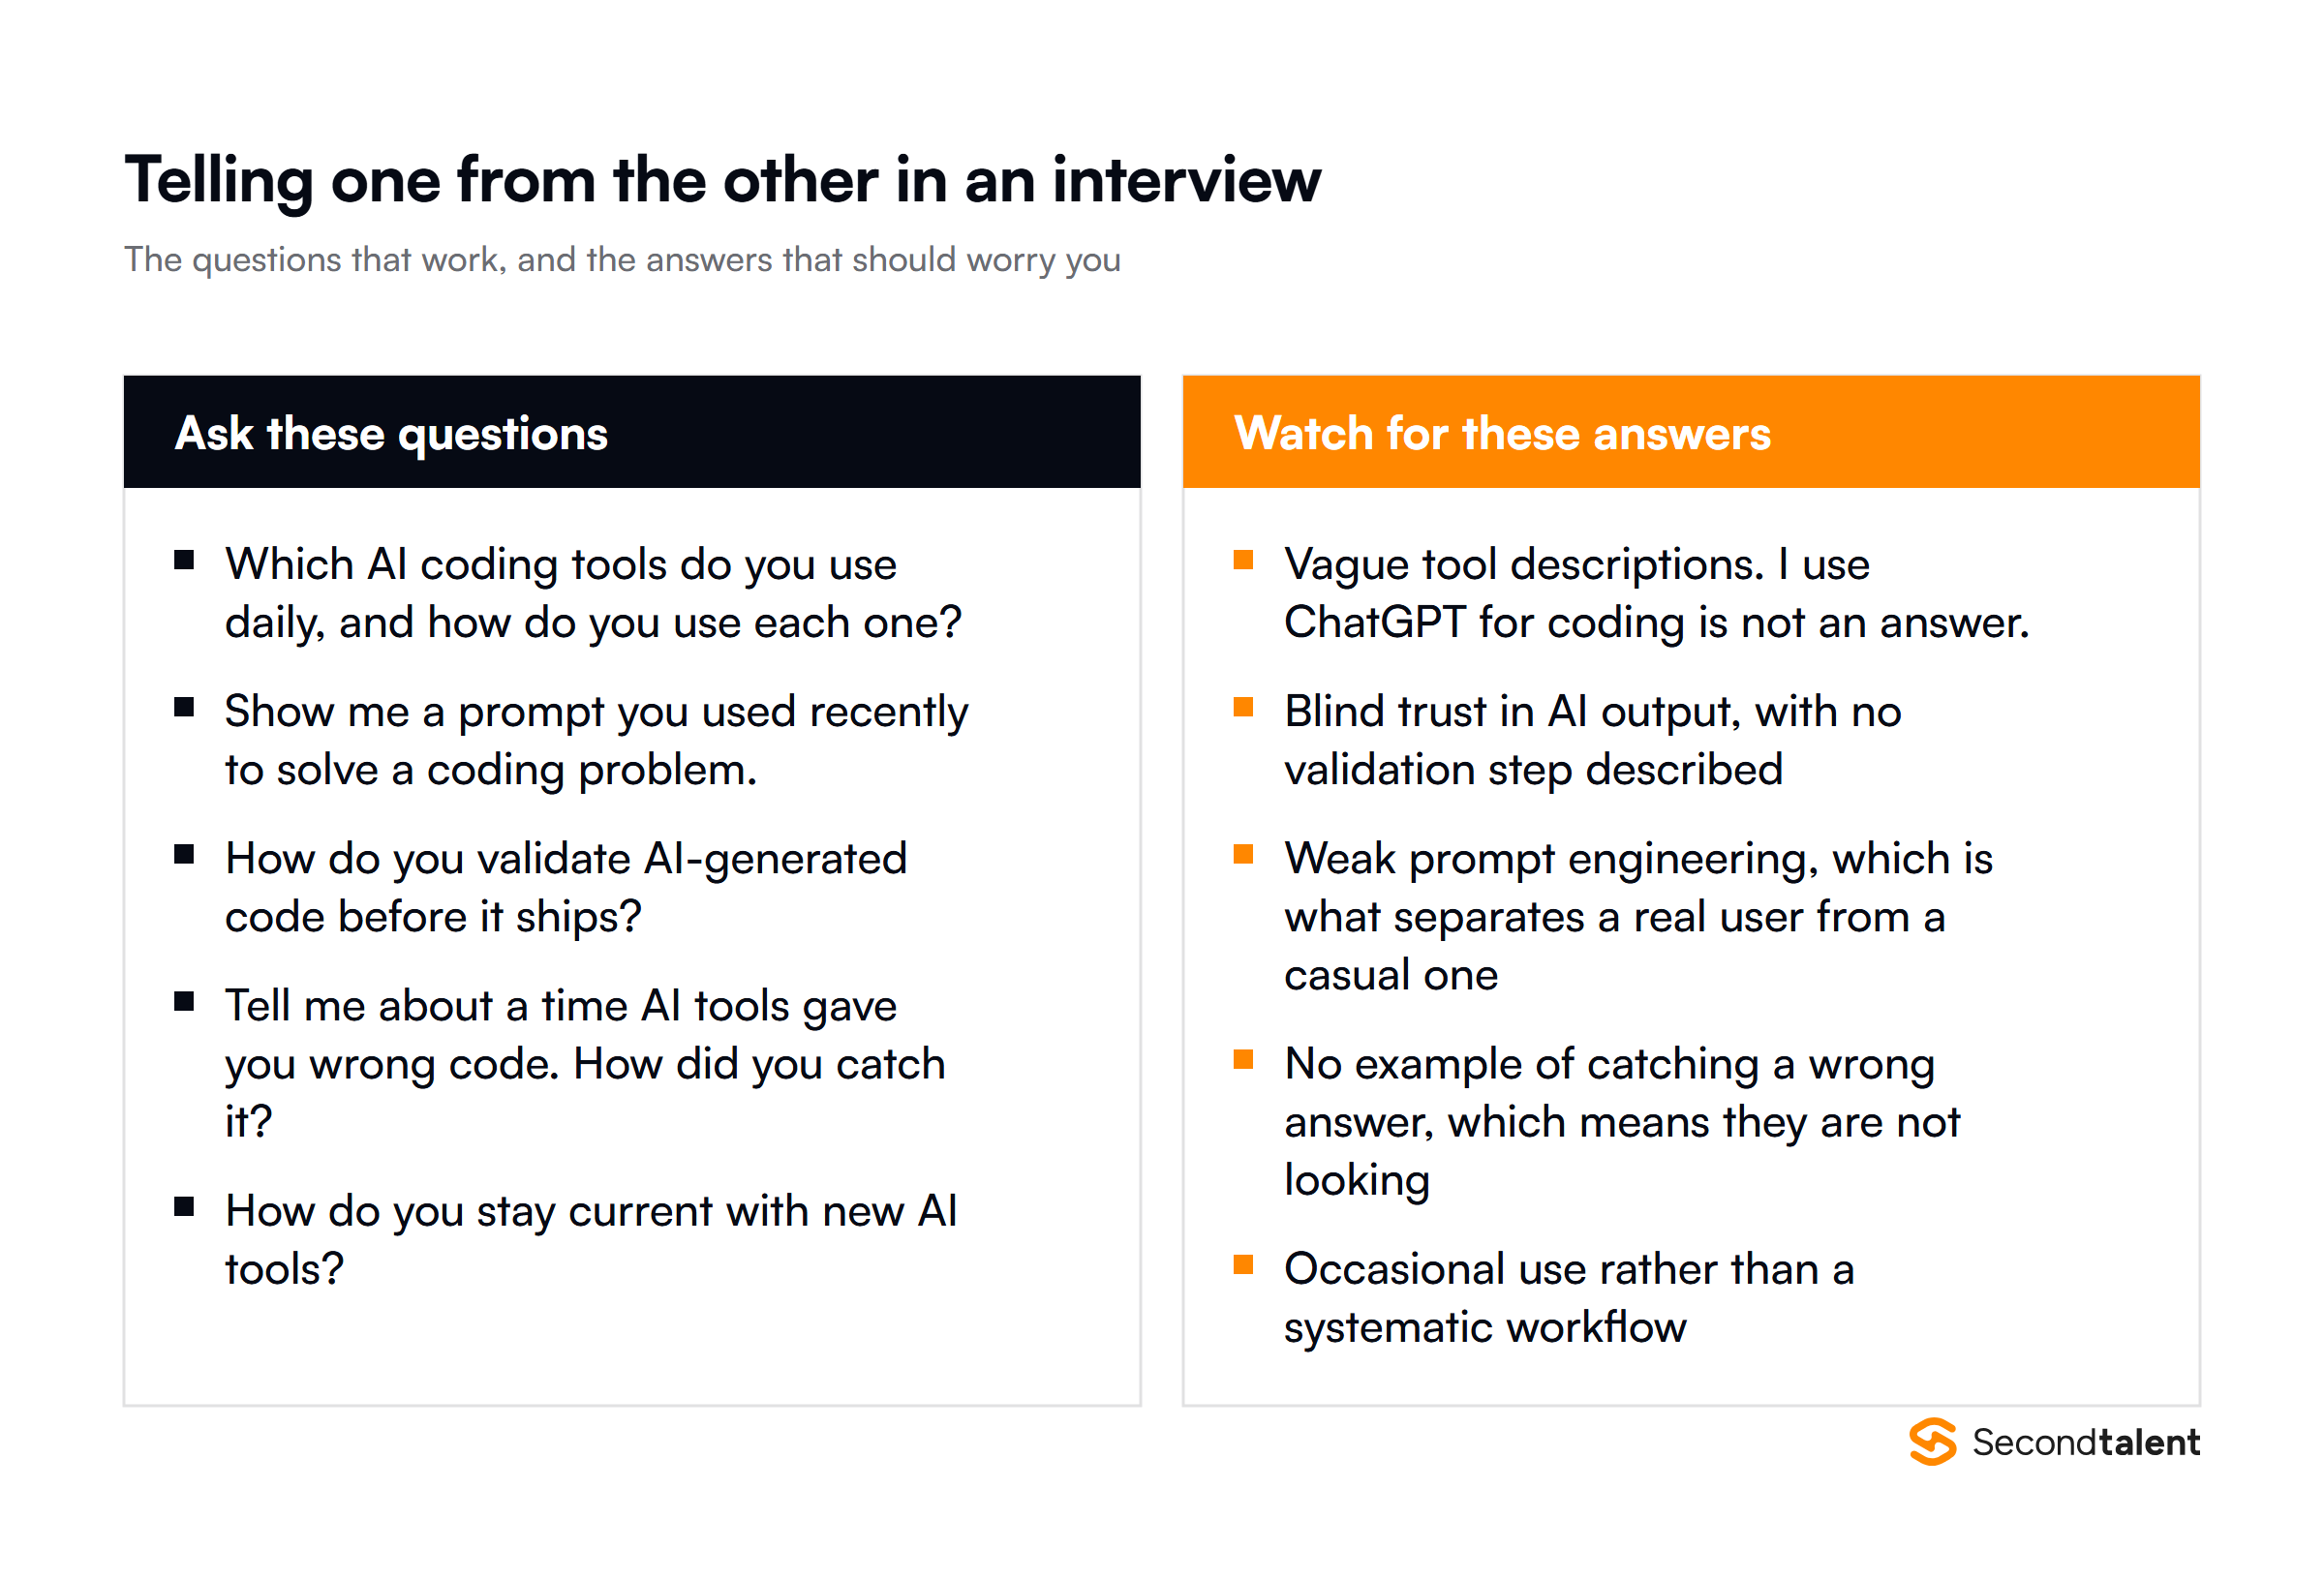
Test the verification loop, not the tool list. Any candidate can name five tools. Far fewer can describe the last time a model handed them something wrong and what caught it. We ask these five questions and score the follow-ups:
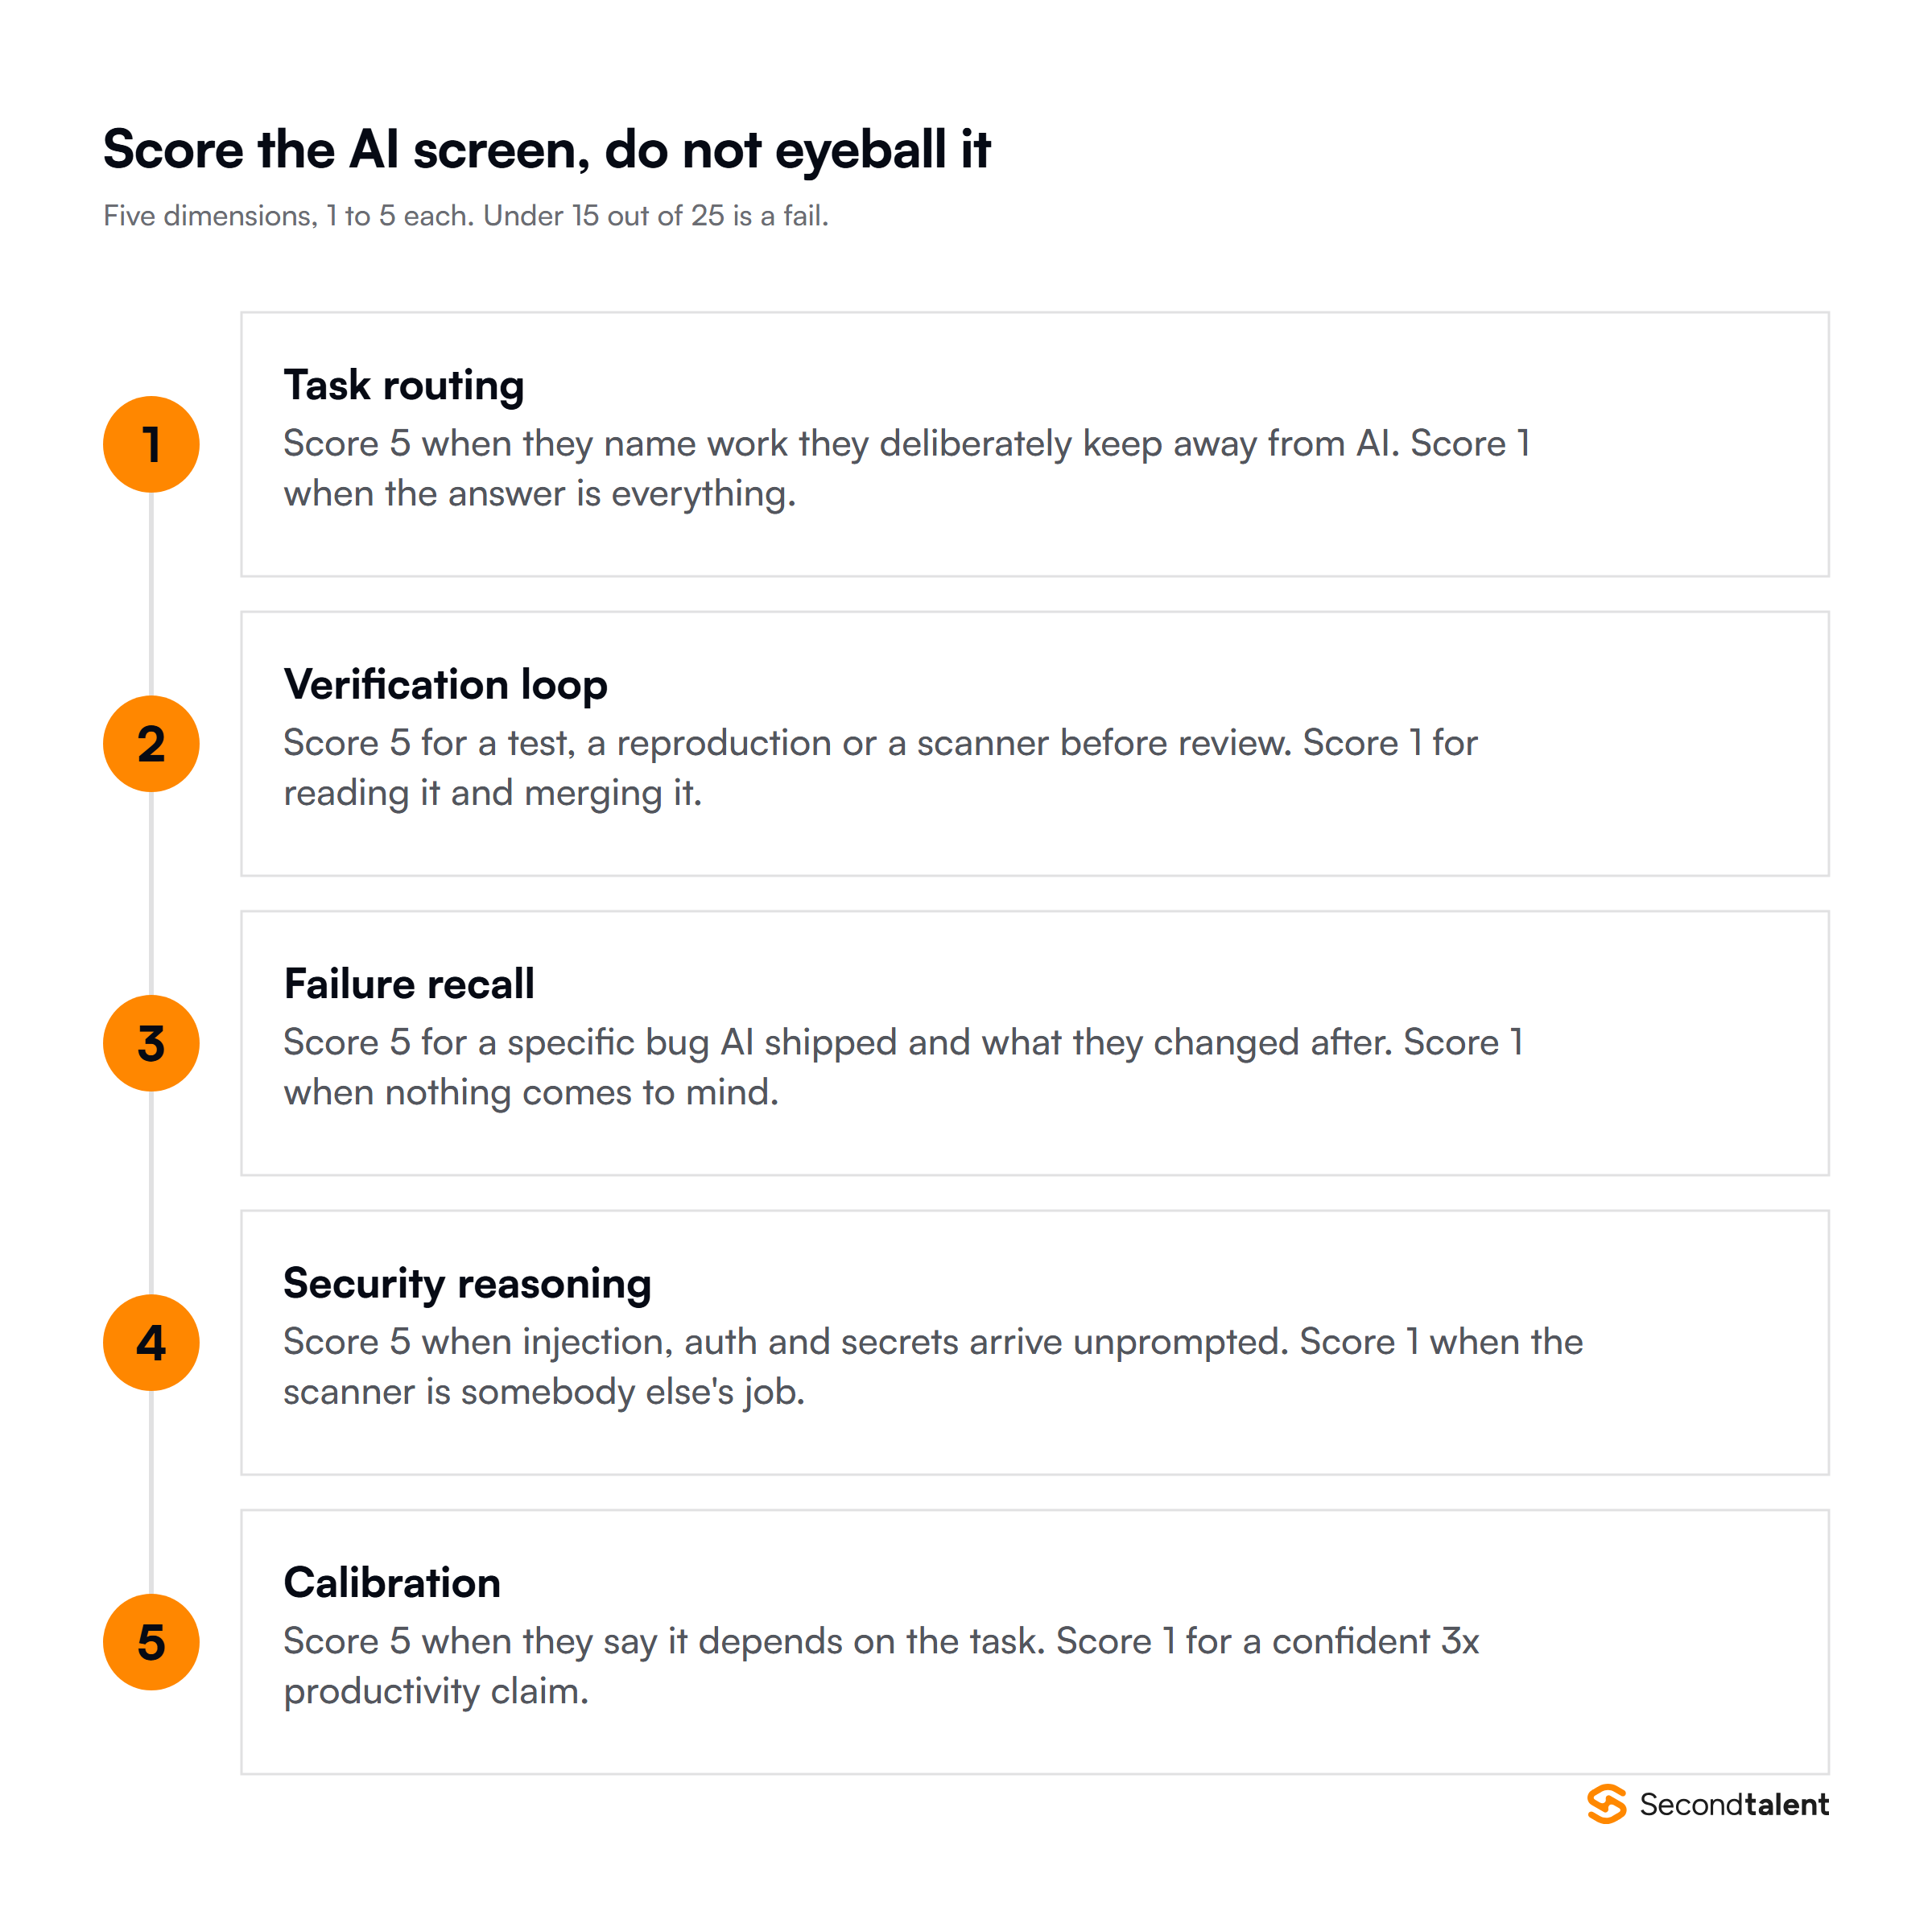
- Routing: "Which parts of your last project did you deliberately not use AI for?" Strong candidates have a real boundary. Weak ones use it for everything.
- Verification: "Walk me through what happens between the model producing code and that code reaching your pull request." Listen for a test, a reproduction or a scanner.
- Failure recall: "Tell me about AI code that shipped a bug. How did it get through, and what did you change afterwards?" The change is what you are grading.
- Security: "Here is a generated endpoint. What would you check before merging it?" Injection, auth, secrets and output encoding should come up unprompted.
- Calibration: "How much faster does AI make you, and how do you know?" After METR, the honest answer is that it depends on the task.
The opening questions and the answers that should worry you look like this:
Our live exercise gives candidates a small brief and their own agent, then a second where the generated code carries a planted flaw, such as a missing auth check. The first measures throughput. The second shows whether the candidate catches the flaw, which predicts how much of your senior engineers' review time the hire will need.
Score the screen on five dimensions
Score each dimension from 1 to 5 for every candidate in the loop. Anything under 15 out of 25 is a fail, however good the conversation felt.
Red flags
- No story of AI being wrong. Anyone using these tools daily has one. A missing story means the tools are not in daily use, or the candidate checks nothing.
- A precise speed claim. "Copilot makes me 3x faster" ignores a trial where developers misjudged their own speed by 39 percentage points.
- Security as somebody else's step. A candidate who leaves it to the scanner, against a 45% failure rate, adds to your reviewers' workload.
A strong traditional engineer shows the reverse pattern: deep answers on design and debugging, thin answers on agent workflow. Treat that as a training gap to close after hiring, covered in the career section below.
Pay and cost: what the data says
US software developers earned a median of $135,980 in May 2025, according to the Bureau of Labor Statistics. The BLS does not split that figure by AI fluency, so any premium estimate has to come from job ads.
PwC's 2026 Global AI Jobs Barometer analysed more than a billion job ads in 27 countries and territories. It puts the average wage premium for AI skills at 62%, up from 57% a year earlier. Jobs asking for AI skills grew 69%, against 9% for the jobs market overall.
Lightcast's 2025 analysis found a smaller gap. Postings that listed AI skills offered 28% higher salaries, close to $18,000 more a year.
Tool subscriptions are the small line in the budget. Reviewer time is the large one. DORA's stability finding means a team shipping more AI-generated code should expect more failed changes unless review capacity grows with it. Our list of engineering productivity metrics covers which numbers to watch.
For budgets, our cost to hire an AI engineer and cost to hire an AI developer guides compare US and offshore totals. The Vietnam AI engineer rate card lists local salary bands.
Building mixed teams
The useful split is generation capacity against verification capacity. An engineer who produces more code per day also produces more code to review, and the reviewer's week is the constraint that breaks first.
We start client teams from the ratios below and adjust. They are our starting point, not a measured benchmark. Early teams writing code they expect to rewrite lean AI-native, and larger codebases with paying customers need more review.
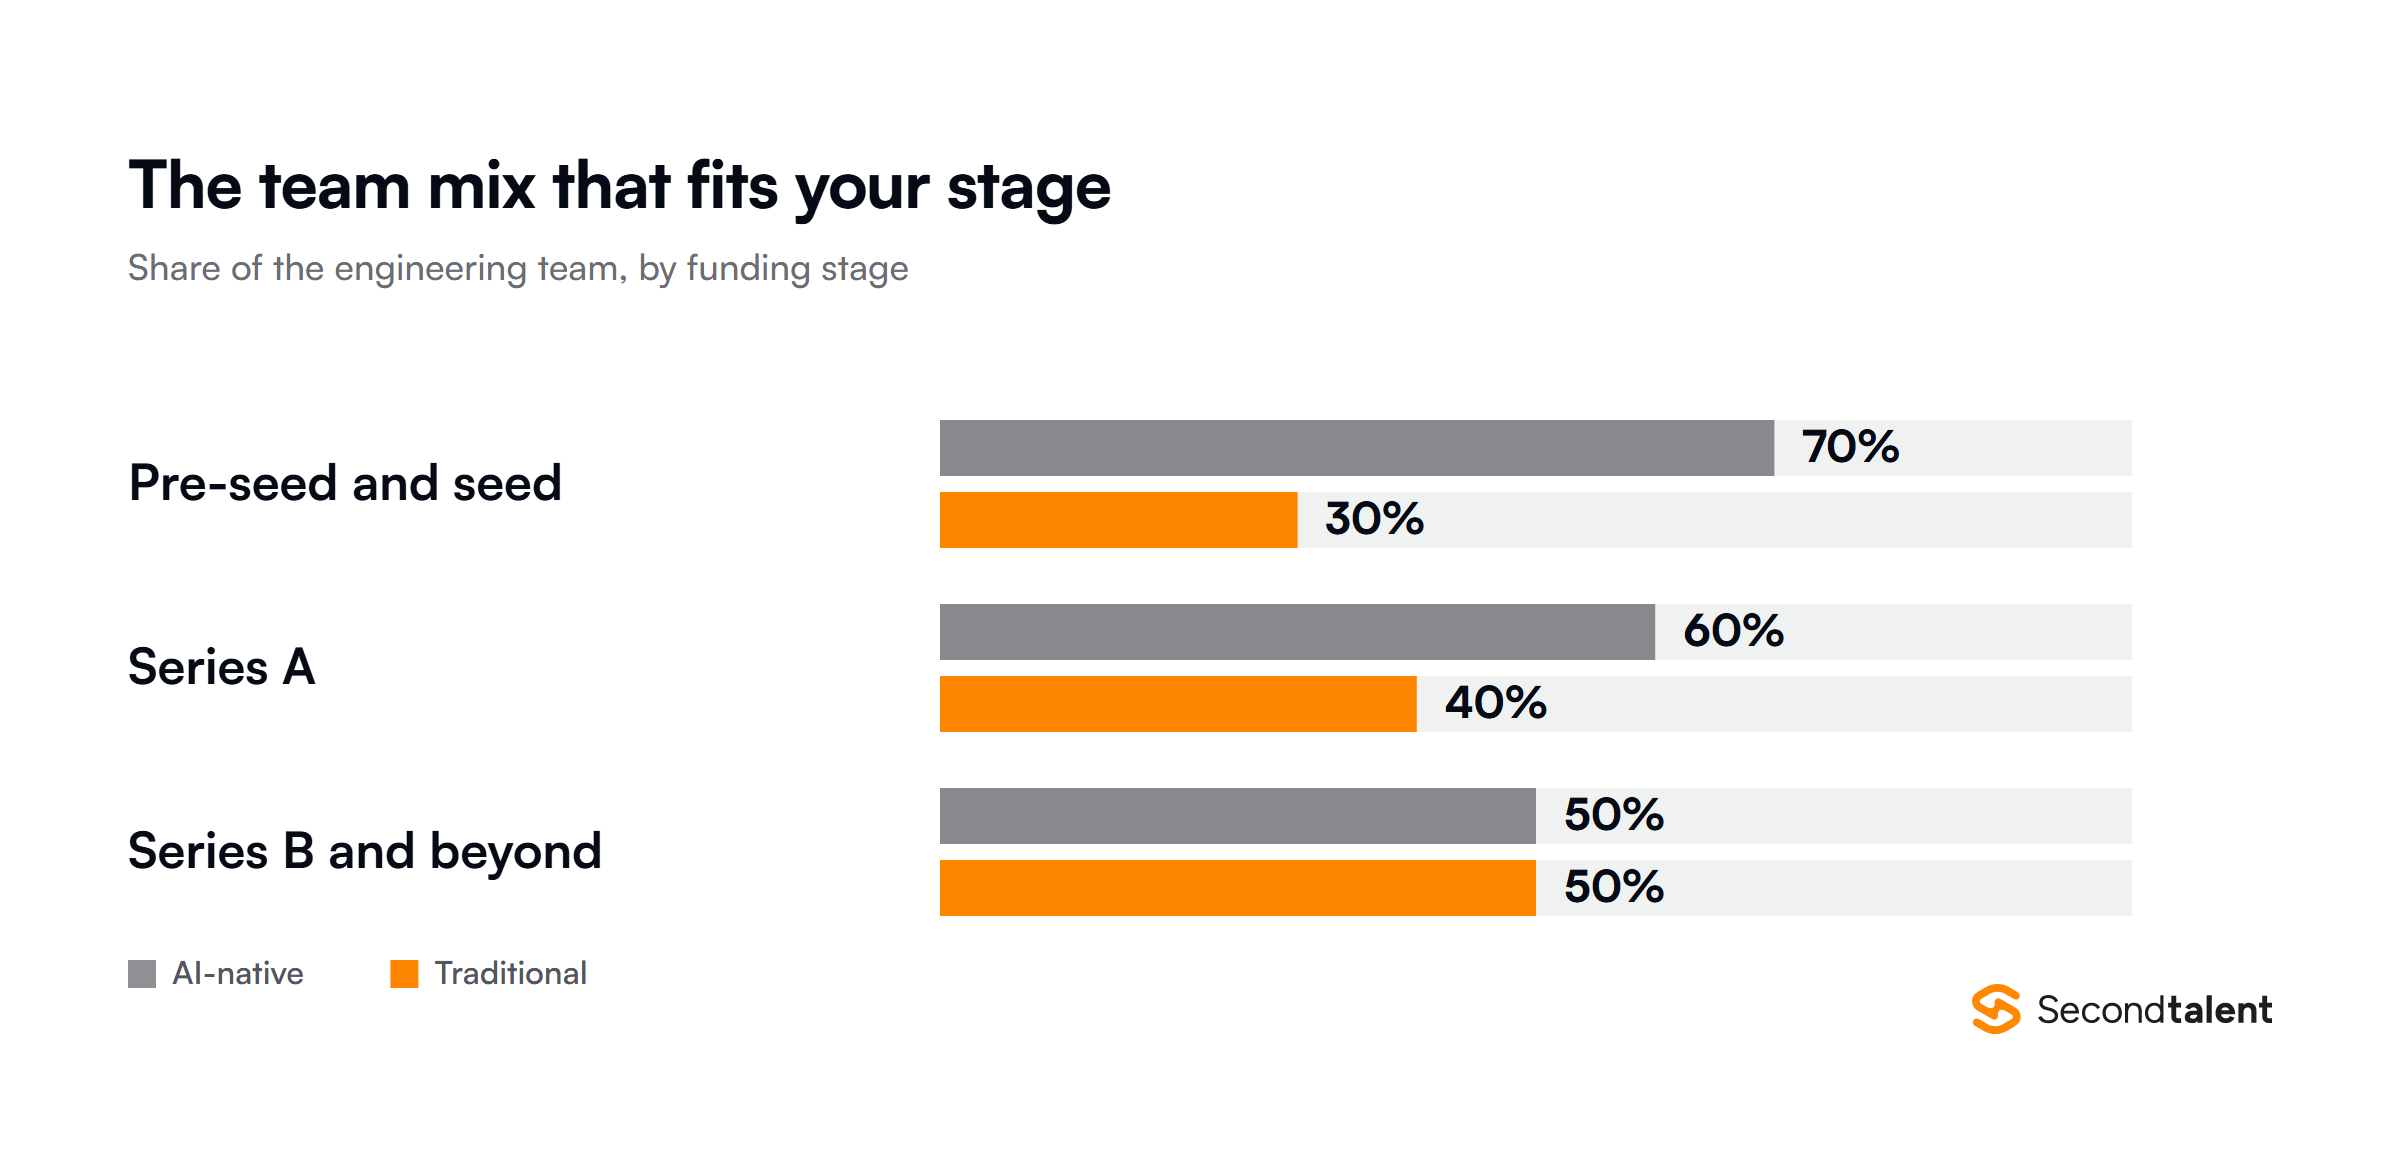
Shift the mix toward review in four cases:
- A Java-heavy stack. At a 29% security pass rate on Veracode's tests, generated Java needs about twice the scrutiny of generated Python.
- Regulated code. "The model wrote it" is not an answer an auditor accepts.
- Legacy systems. Models trained on public code struggle with an undocumented internal framework.
- A single approver. If one engineer approves most pull requests, more generation capacity makes that bottleneck worse.
Two working rules help the mix hold. Cap AI-assisted pull requests by size, so a 900-line generated diff goes back to be split before anyone reads it. Pair an AI-native engineer with a reviewer for a few weeks, so threat instincts move one way and agent habits move the other. Merge-gate ownership usually sits with the lead, and our lead engineer vs senior engineer comparison covers how the two roles split review and design.
Career paths for each
AI-native engineers tend to move toward roles where the agent is part of the product: LLMOps engineer, AI integration engineer or AI forward deployed engineer. Traditional engineers with strong review and design skills move toward lead roles and toward platform engineering or site reliability, where stability is the job.
Infrastructure is open to both. Our ML infrastructure engineer vs MLOps engineer comparison covers that path.
The two paths also converge. A traditional engineer can pick up the agent workflow in a quarter, though most are left to do it alone. In the Agoda survey, 71% of developers in Asia were teaching themselves through tutorials, side projects and online communities, and 28% had access to employer-led training. A structured programme closes the gap faster:
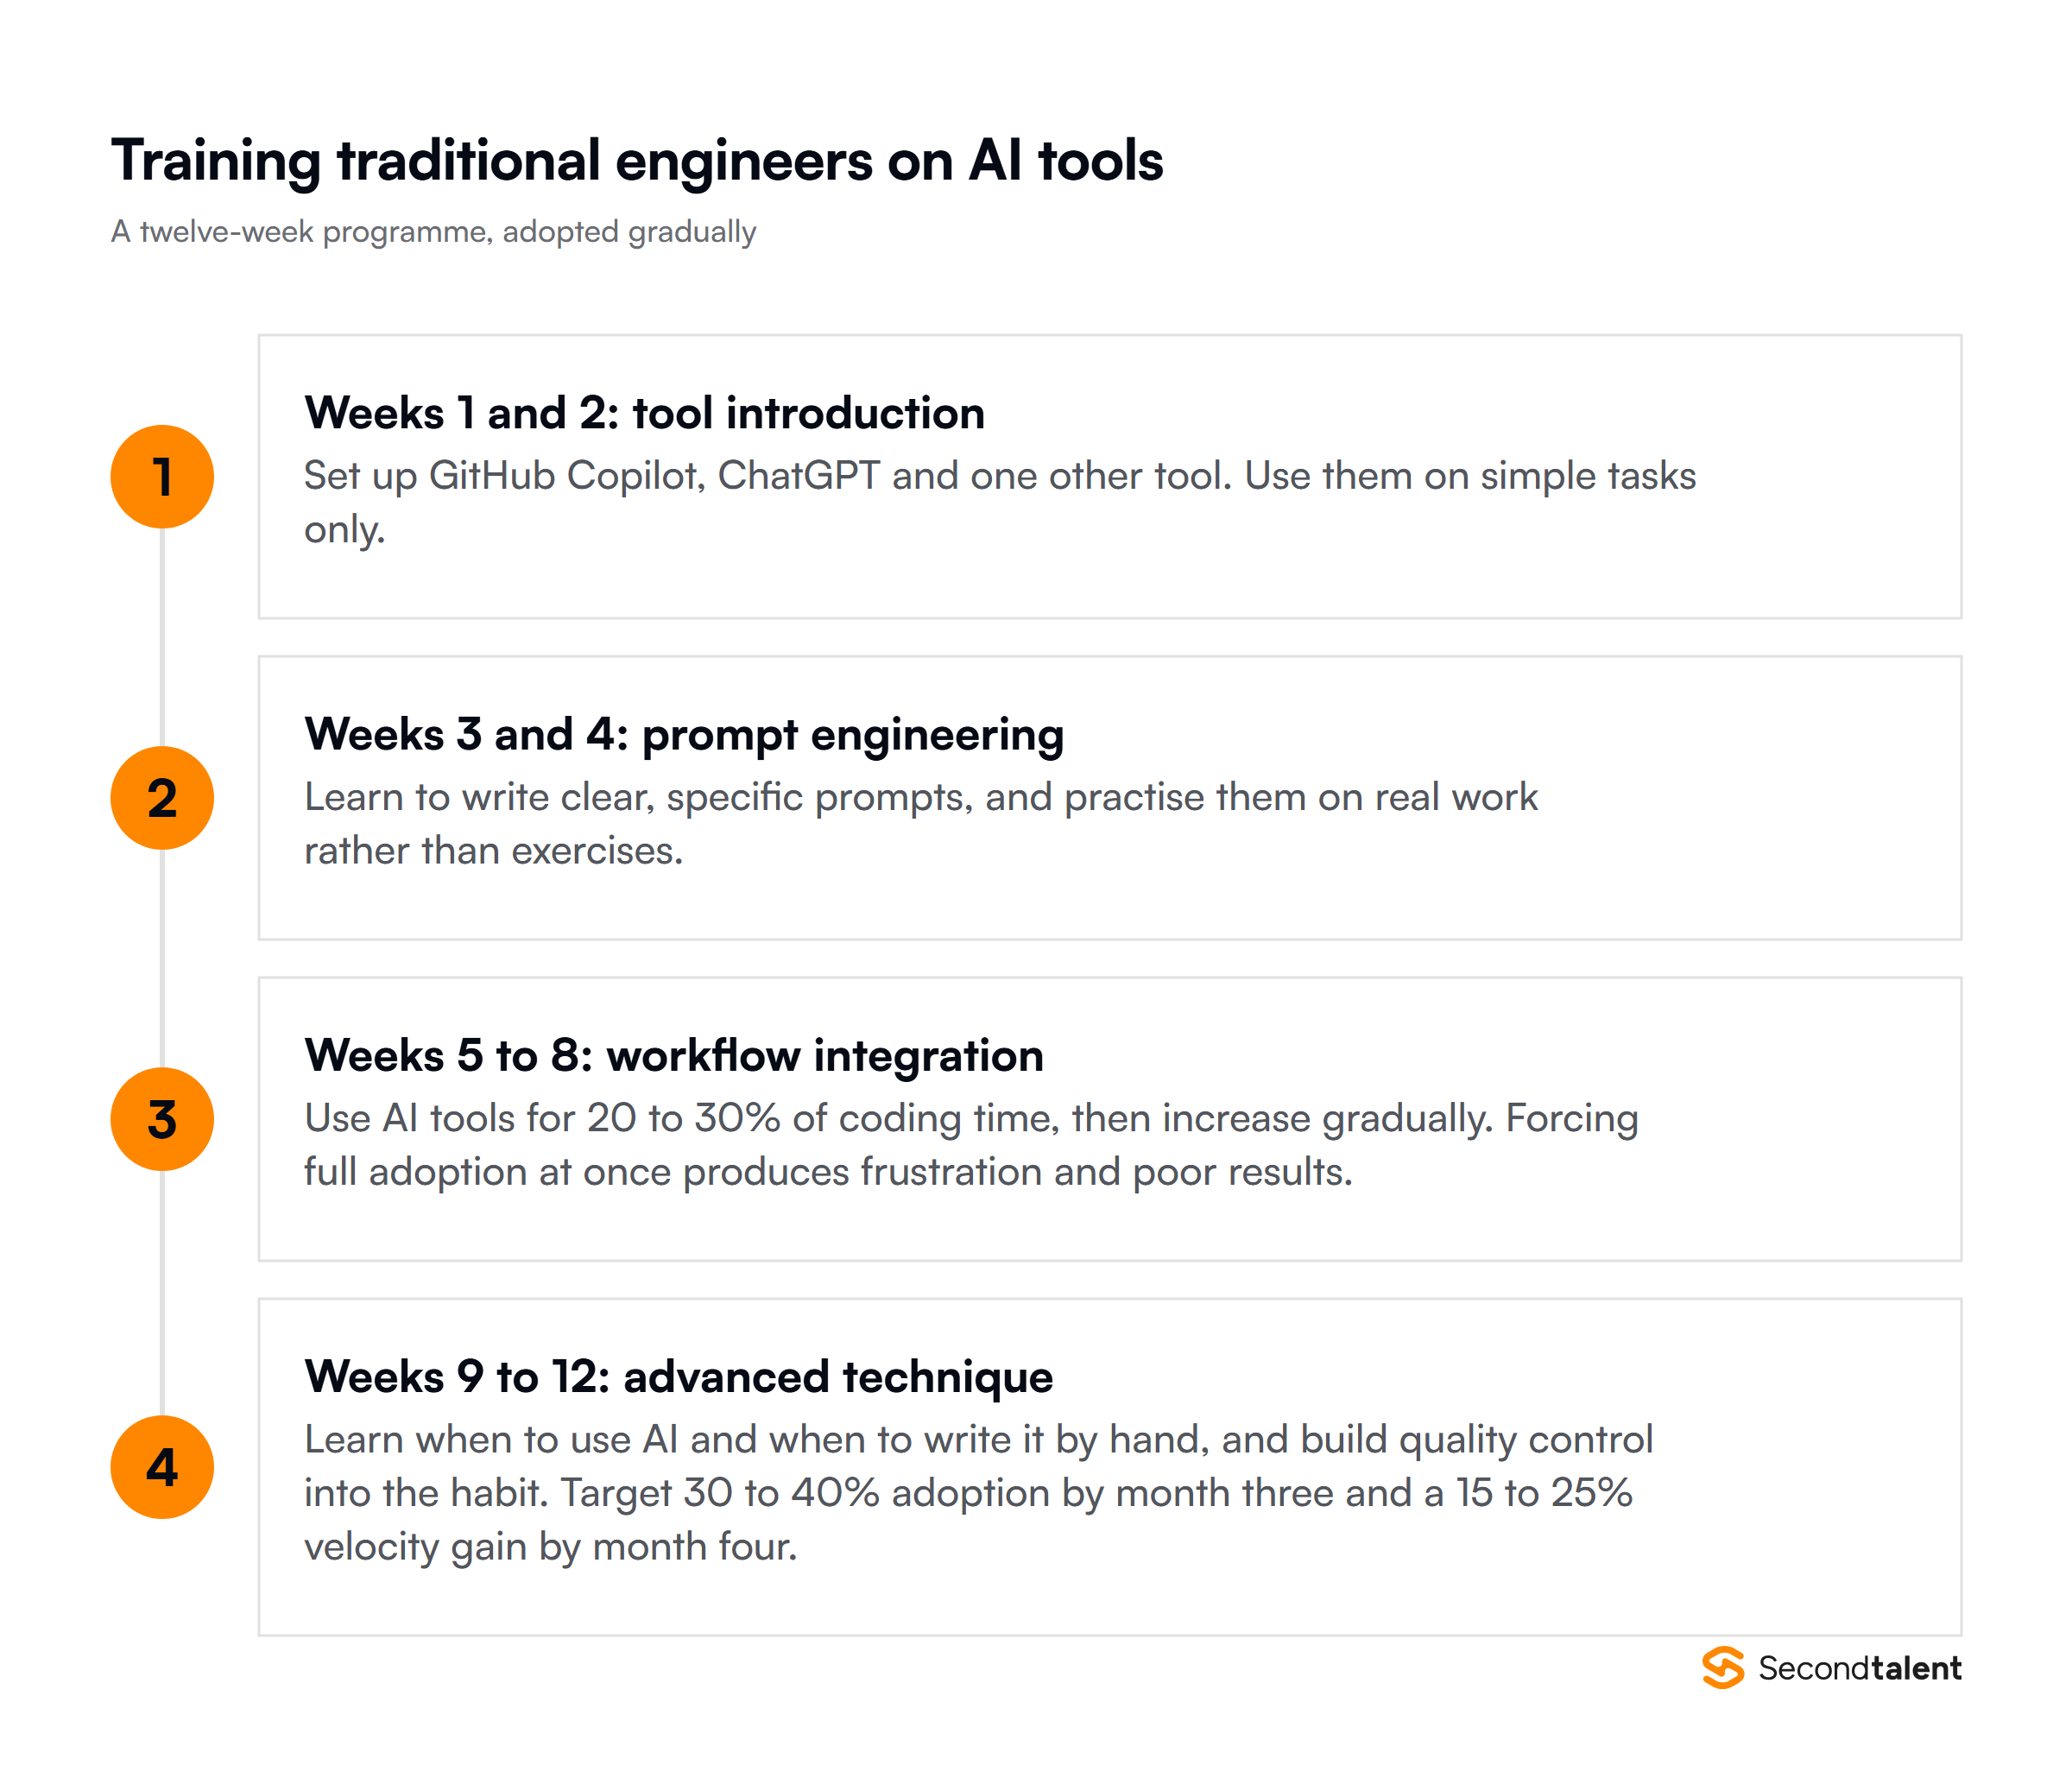
The adoption and velocity targets in the chart are the ones we set with client teams, not survey results. We move one step earlier than the chart shows: the failing test before generation goes in during weeks 5 to 8, before usage scales. Skip it and the team produces more of the code that fails Veracode's checks. Our guide on how to become an AI-native engineer covers the same ground from the engineer's side.
When to hire an AI-native engineer, a traditional engineer, or both
Choose on the cost of a production failure. If a bad deploy means an apology, hire for generation. If it means a breach notification or a regulator, hire for verification and pay for it.
If you are unsure, hire one of each and measure for two quarters. Track throughput, change failure rate and how much reviewer time each hire consumes. The third number decides whether the first was worth anything.
Customer-facing AI work raises a related choice between building and owning the rollout. Our deployment strategist vs forward deployed engineer comparison covers that pair.
Hire AI-native engineers from Asia
We screen engineers in a live session with an AI coding agent, scored on the rubric above, and match you with vetted AI engineers in 24 hours at 50-70% below US cost. We employ them through our own EOR in 9 Asian markets, including Vietnam, the Philippines and Indonesia, with a 90-day, one-time replacement guarantee.
Our Second Talent Monthly plan is $4,999 a month, all-inclusive, for a senior engineer, with the first month at $2,999. Tell us what you are building and we will send a shortlist.
Frequently Asked Questions
Do AI-native engineers work faster?
On some tasks. GitHub measured 55% faster on one scripted task in 2022. METR found experienced maintainers 19% slower in early 2025, then estimated an 18% saving in early 2026 on evidence it calls "only very weak".
Should candidates use AI in a coding interview?
Yes. Banning it means you grade a workflow the hire will drop on day one. Enable the tools, plant a flaw in the generated code and score what the candidate does next.
Can a traditional engineer become AI-native?
Yes, and senior engineers often make the strongest ones, because they know when the agent is wrong. The shift takes a few months of daily use with a verification step in place from the start.