TL;DR: Hire a pre-vetted RLHF specialist from across Asia for $1,200–$4,500/mo. Someone who ranks model outputs, writes preference data, and applies your guidelines the same way on the thousandth task as on the first. Shortlist in 24 hours, $0 upfront.
Why Hire an RLHF Specialist
Reinforcement learning from human feedback (RLHF) is how a capable base model becomes a helpful, safe assistant. Reviewers compare model responses, pick the better one, and explain why. Those judgements train a reward model, or feed preference methods such as DPO directly, and the model learns to prefer the answers your reviewers preferred.
The method is only as good as the judgements behind it. Vague guidelines, tired reviewers, and drifting standards all end up inside the model. An RLHF specialist is a reviewer who reads guidelines closely, flags the cases they do not cover, and holds a steady bar across long projects.
Through Second Talent you get dedicated specialists, not anonymous crowd workers. They work on your project only, you calibrate them directly, and you only pay when you make a hire.
What an RLHF Specialist Does
A strong RLHF specialist owns the human judgement layer of your training data:
- Preference ranking: comparing two or more model responses and choosing the better one against your rubric.
- Written rationales: explaining each judgement so you can audit it and train on the reasoning.
- Response rewriting: turning a weak answer into an ideal one for supervised fine-tuning.
- Rubric feedback: spotting gaps and contradictions in your guidelines and proposing clearer rules.
- Safety review: labelling harmful, biased, or policy-breaking output, and writing safe alternatives.
- Calibration: working through gold tasks and review sessions so the whole team scores the same way.
Where RLHF Specialists Fit in Your Pipeline
| Stage |
What the specialist produces |
Who else is involved |
| Guideline design |
Pilot judgements and edge-case notes |
Your research or product lead |
| Supervised fine-tuning |
Ideal responses, written fresh or rewritten |
Coding or domain expert trainers for specialist prompts |
| Preference data |
Ranked pairs with rationales |
Senior reviewers checking agreement |
| Evaluation |
Scored samples for regression checks |
AI Evaluation Specialists building the harness |
RLHF Specialist Rates
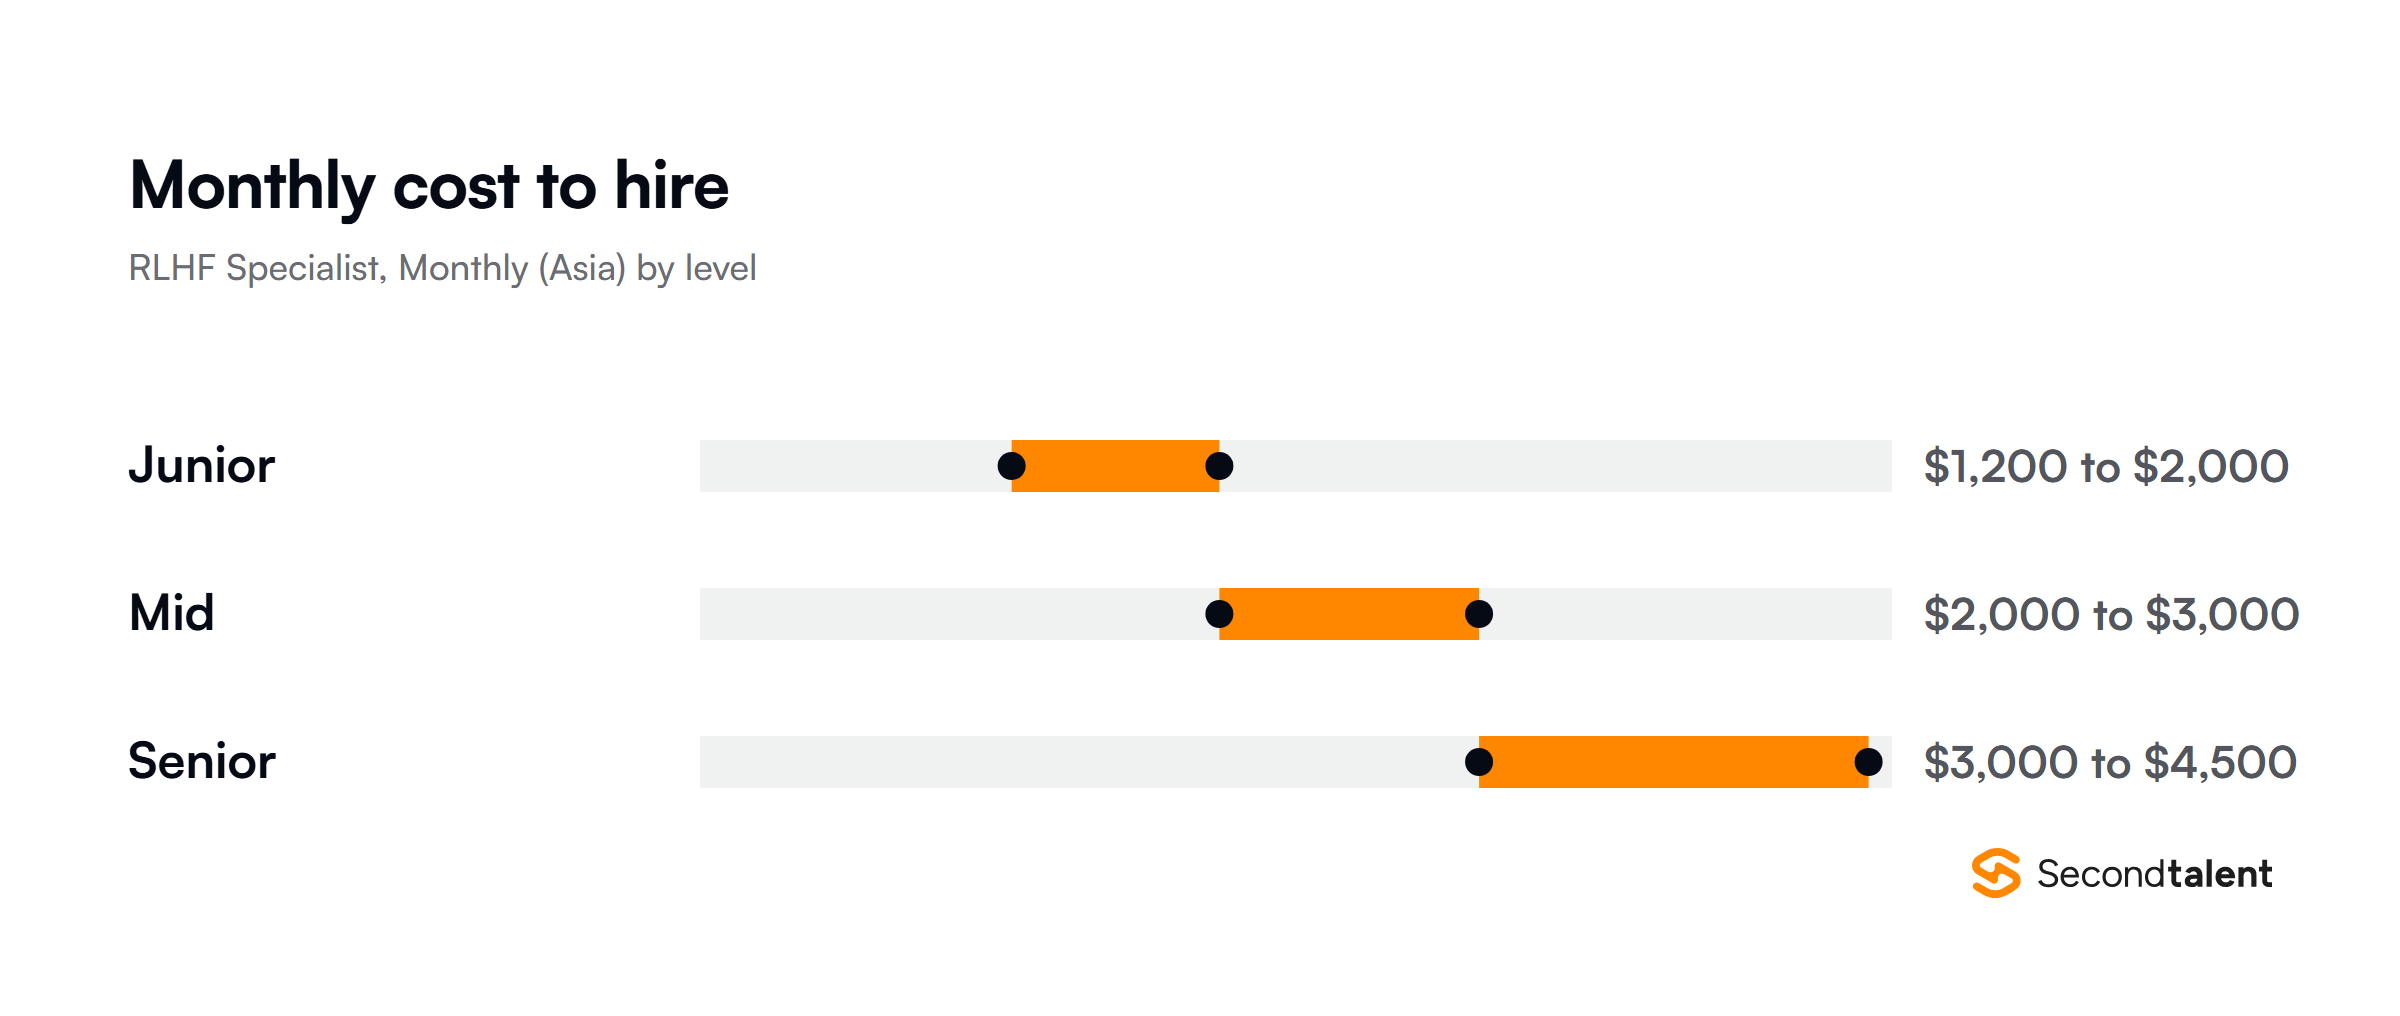
Monthly ranges for 2026, full-time and dedicated to your project:
| Level |
Monthly (Asia) |
Typical profile |
| Junior |
$1,200–$2,000 |
Strong writer, first preference-data project |
| Mid |
$2,000–$3,000 |
Has worked to a published rubric at volume |
| Senior |
$3,000–$4,500 |
Writes guidelines, runs calibration, reviews others |
| Lead |
$4,500+ |
Owns quality for a full workstream |
Rates vary by market and language. See the Asia Tech Salary Index for country-level context.
What We Vet For
Feedback work needs attention, judgement, and clear writing. Our process starts with a guideline test: the candidate applies a real rubric to a set of tasks with known answers. We score their agreement with the gold labels and read every rationale. A writing sample, an English communication check, and reference checks follow. Only the top few percent pass.
We look for specialists who notice when a rule does not fit a case and say so. That habit protects your data more than raw speed.
RLHF Specialists vs Data Annotators
Annotation labels data: boxes on images, tags on text, transcripts. It suits high volume and tasks with a clear right answer, and our data annotation specialists cover it. RLHF work asks for judgement on open-ended output, where two good answers can differ and the reviewer has to explain the choice.
Many teams use both. Annotators handle volume. RLHF specialists handle the tasks that shape how the model behaves.
How Hiring Works
Share your brief: the model, the task types, your guidelines, and the volume you expect. We send a shortlist of pre-vetted RLHF specialists within 24 hours. You interview the candidates you like and can set them your own sample task. We handle contracts, payroll, and compliance through our Employer of Record service, so there is no local entity to set up.
Most clients go from first call to a working specialist in under a week. If the fit is wrong, our 14-day replacement guarantee covers a re-match at no extra cost.
Get Started
Tell us what behavior you want your model to learn. We will deliver a pre-vetted shortlist within 24 hours. Book a free consultation to begin.