
Skip to content

GLM vs DeepSeek (Nov 2026): Tested on Code, Facts and Price

Elton Chan By Elton Chan, Co-Founder 15 min read
GLM vs DeepSeek, tested by Second Talent in November 2026.
TL;DR: DeepSeek won two of our three tests on 17 November 2026 and was the only one of the pair to get the World Cup fact-check right, while GLM-5.3-Flash, the free guest model on chat.z.ai, wrote the better bug diagnosis. The flagship APIs cost almost the same: GLM-5.3 at $1.40 input and $4.40 output per million tokens, DeepSeek-V4-Pro at $1.32 and $3.96 at peak. Pick DeepSeek for fast answers and web facts, and GLM for careful code reasoning you can try without an account.

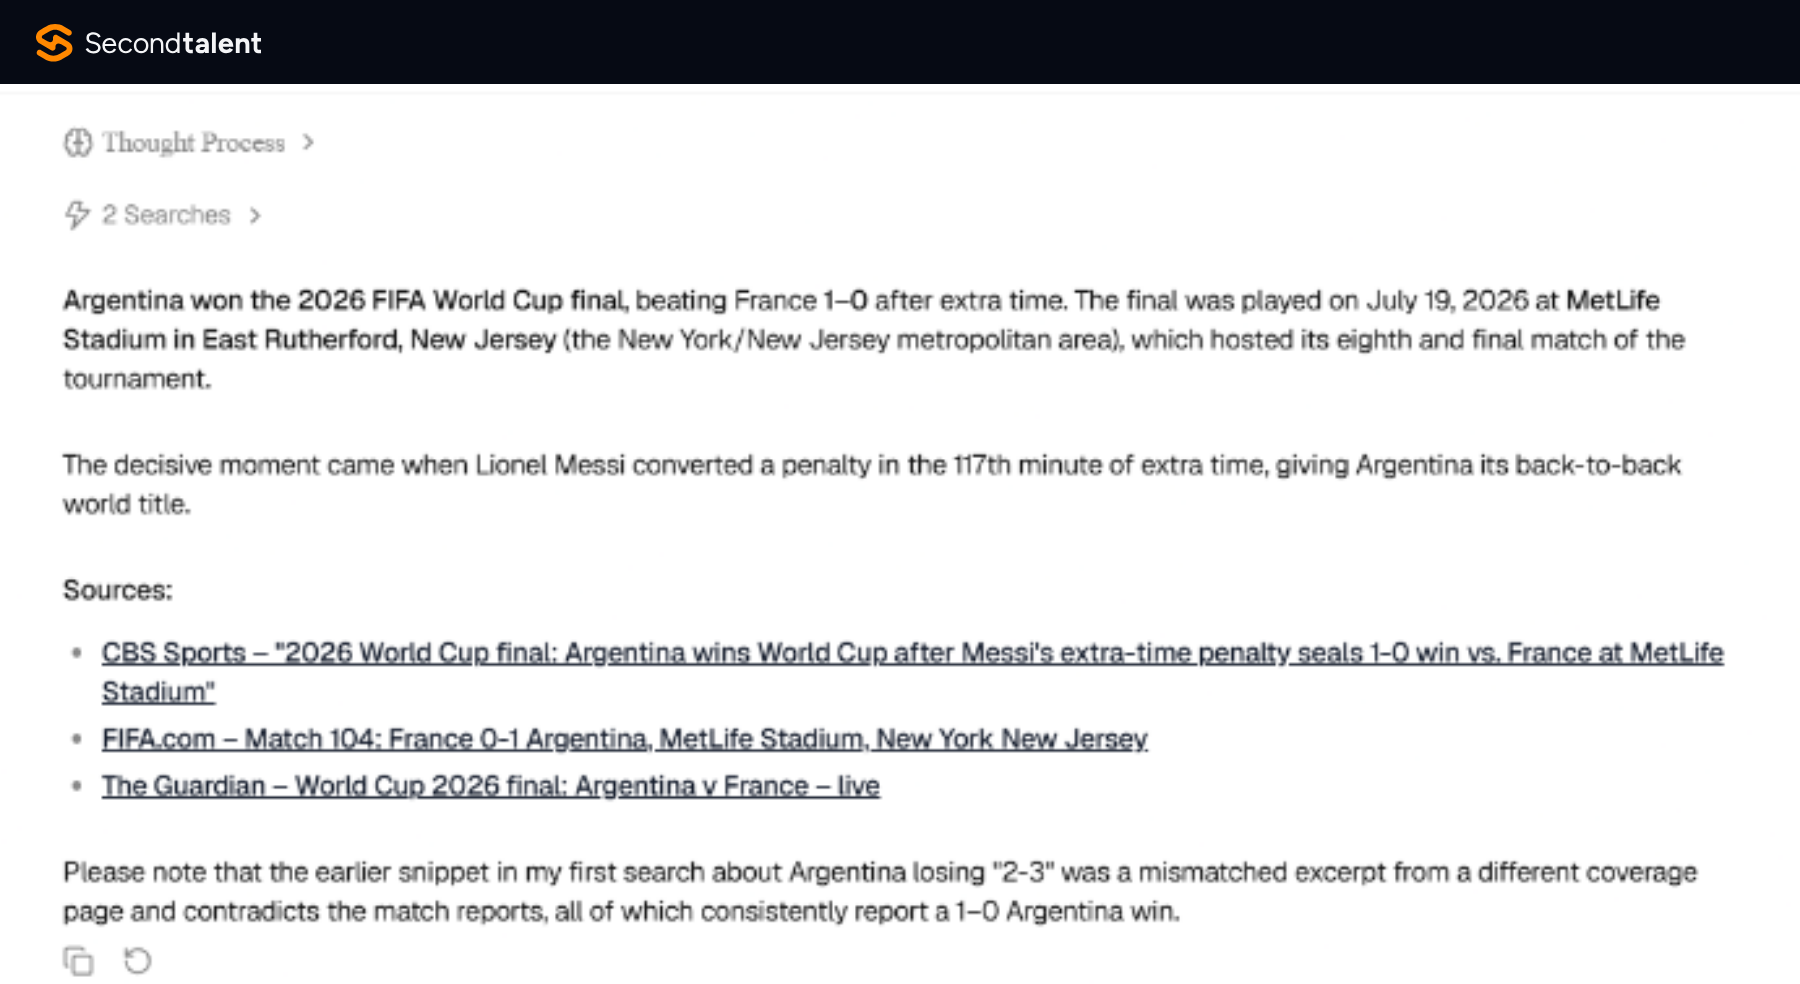
Asked who won the 2026 World Cup final, Z.ai's free GLM-5.3-Flash told us Argentina beat France 1-0 on a 117th-minute Messi penalty, and cited a Guardian live blog that returns a 404.

Spain won that final, and DeepSeek said so in about 15 seconds. Two prompts earlier, the same GLM model had written the sharpest explanation of a JavaScript sort bug we got from any Chinese chatbot that day.

Key takeaways
  1. 1chat.z.ai answers without an account, but only on GLM-5.3-Flash. DeepSeek has no guest chat at all.
  2. 2The cheap tiers flip the price order: GLM-5.3-Flash costs $0.15 in and $0.50 out, against $0.30 and $1.20 for deepseek-flash at peak.
  3. 3Both current DeepSeek models are MIT licensed. GLM-5.3 is not: its own licence adds a Z.ai security review for model-hosting firms with over $10 billion in revenue.
  4. 4DeepSeek's privacy policy stores chats in the People's Republic of China; chat.z.ai is run from Singapore.
GLM vs DeepSeek: who won our three tests

DeepSeek took two rounds and GLM took one, and the round GLM lost it lost badly. Both built a working password checker and both found the sort bug. Only DeepSeek got a basic sports fact right.

1. CodingDeepSeek
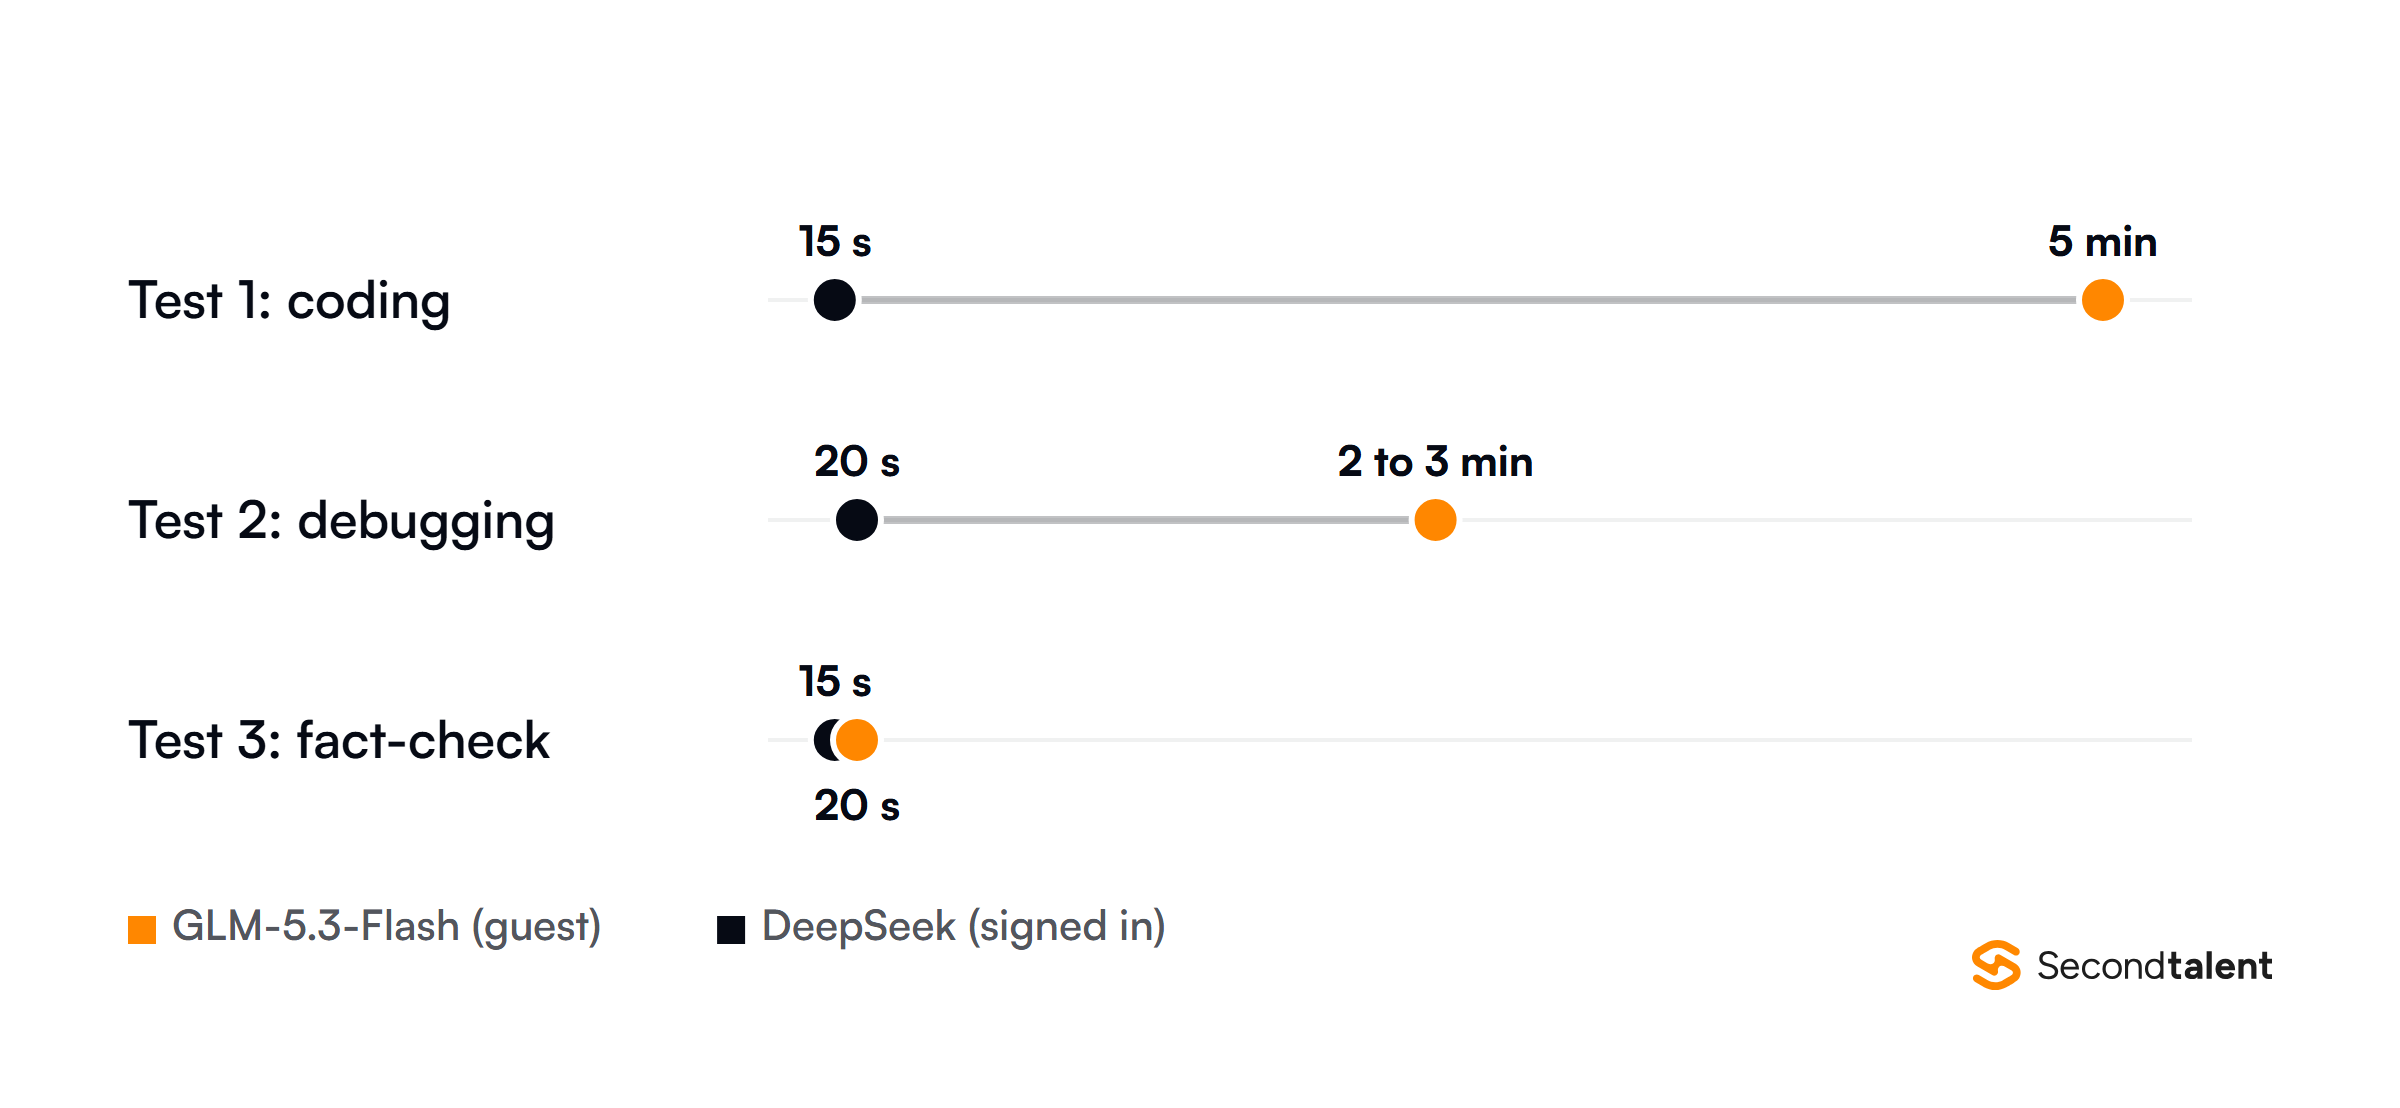
15 s vs 5 min
Both checkers worked and both rated Password123! as Strong. DeepSeek got there 20 times faster.
2. DebuggingGLM
Both correct
GLM added a repro, toSorted() and the pop() versus shift() trap.
3. Fact-checkDeepSeek
Right vs wrong
GLM named the wrong winner, the wrong opponent and the wrong scorer.

Speed separated them as much as quality. GLM ran at its default Max effort and thought out loud for minutes on the two coding prompts, while DeepSeek answered all three prompts in 20 seconds or less.

Dot plot of time to a finished answer in our 17 November 2026 tests: coding, GLM-5.3-Flash about 5 minutes against DeepSeek about 15 seconds; debugging, 2 to 3 minutes against about 20 seconds; fact-check, about 20 seconds against about 15 seconds.
GLM (Z.ai)DeepSeek
Chat appchat.z.ai, guest chat allowedchat.deepseek.com, login required
Model we testedGLM-5.3-Flash (guest), Effort MaxDefault chat model, DeepThink off
API flagshipGLM-5.3, $1.40 / $4.40DeepSeek-V4-Pro, $1.32 / $3.96 at peak
API budget modelGLM-5.3-Flash, $0.15 / $0.50deepseek-flash, $0.30 / $1.20 at peak
Context window1M tokens1M tokens
Max output128K tokens384K tokens
Open weightsGLM-5.3-Flash MIT, GLM-5.3 custom licenceMIT on V4-Pro and V4.1-Flash
Chat data held inSingapore, per Z.aiChina

API prices are per million tokens, input then output, from the Z.ai pricing page and the DeepSeek pricing page, both read on 17 November 2026.

How we tested

We ran the same three prompts on both chatbots on the evening of 17 November 2026, in Chrome on Windows 11, from Southeast Asia (UTC+7).

The prompts are the ones we used on Kimi and Claude that morning for our Kimi vs Claude test, and on six other chatbots for our Chinese AI chatbots round-up.

GLM, as we ran it
  • Guest on chat.z.ai, no account
  • GLM-5.3-Flash, the only model a guest can pick
  • Effort slider left at its default, Max
DeepSeek, as we ran it
  • Signed in on chat.deepseek.com, free account
  • Default chat model, DeepThink off
  • Search off for tests 1 and 2, on for test 3

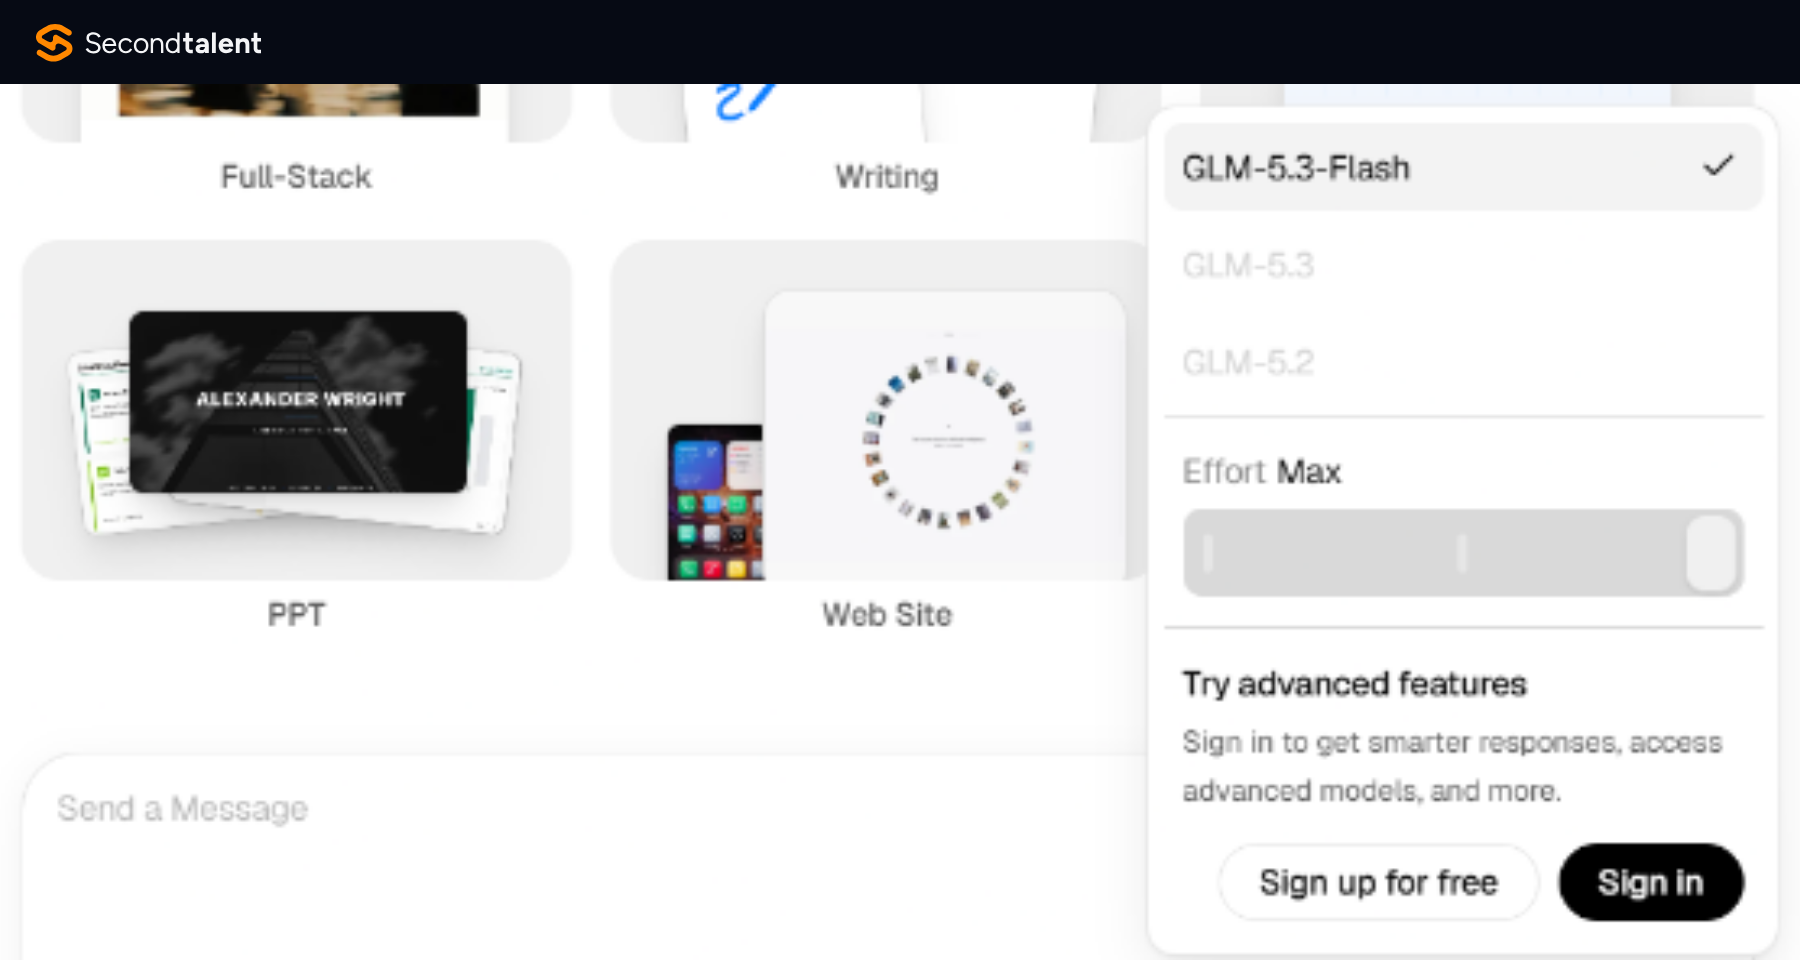
That is not a flagship-against-flagship test. The guest model menu on chat.z.ai greys out GLM-5.3 and GLM-5.2 with the line "Sign in to get smarter responses, access advanced models".

We did not sign in to Z.ai, so we did not test GLM-5.3, its strongest model. DeepSeek's chat window does not name its model either, but DeepSeek's change log says the web and app models moved to DeepSeek-V4.1-Flash-1017 on 17 October 2026.

The chat.z.ai guest model menu: GLM-5.3-Flash selected, GLM-5.3 and GLM-5.2 greyed out, Effort set to Max, and a prompt to sign in to access advanced models.

So the fairest reading is free budget model against free budget model, with one difference in GLM's favour: it asks for nothing before you start typing.

Test 1: build a password strength checker

GLM: about 5 min, side previewDeepSeek: about 15 s, Run buttonWinner: DeepSeek, on speed

GLM told us its checker would block breached passwords, then rated Password123! as Strong. We sent both chatbots this prompt, word for word:

"Create a responsive password strength checker using HTML, CSS, and JavaScript.

It should analyze passwords in real-time as the user types, showing strength levels (weak/medium/strong) with color indicators, display specific requirements (length, uppercase, lowercase, numbers, special chars), and update dynamically.

Include smooth transitions between strength levels."

Test prompt, sent to both chatbots on 17 November 2026

GLM spent about five minutes, most of it in visible thinking, then produced an index.html file card that opens a preview panel beside the chat.

The page is a dark card with a strength bar, five requirement chips, an estimated crack time and a note that the password stays in the browser.

GLM explained its rules. Strong needs all five requirements and 12 or more characters, Medium needs three points, and a small breach list forces passwords such as "password123" down to Weak.

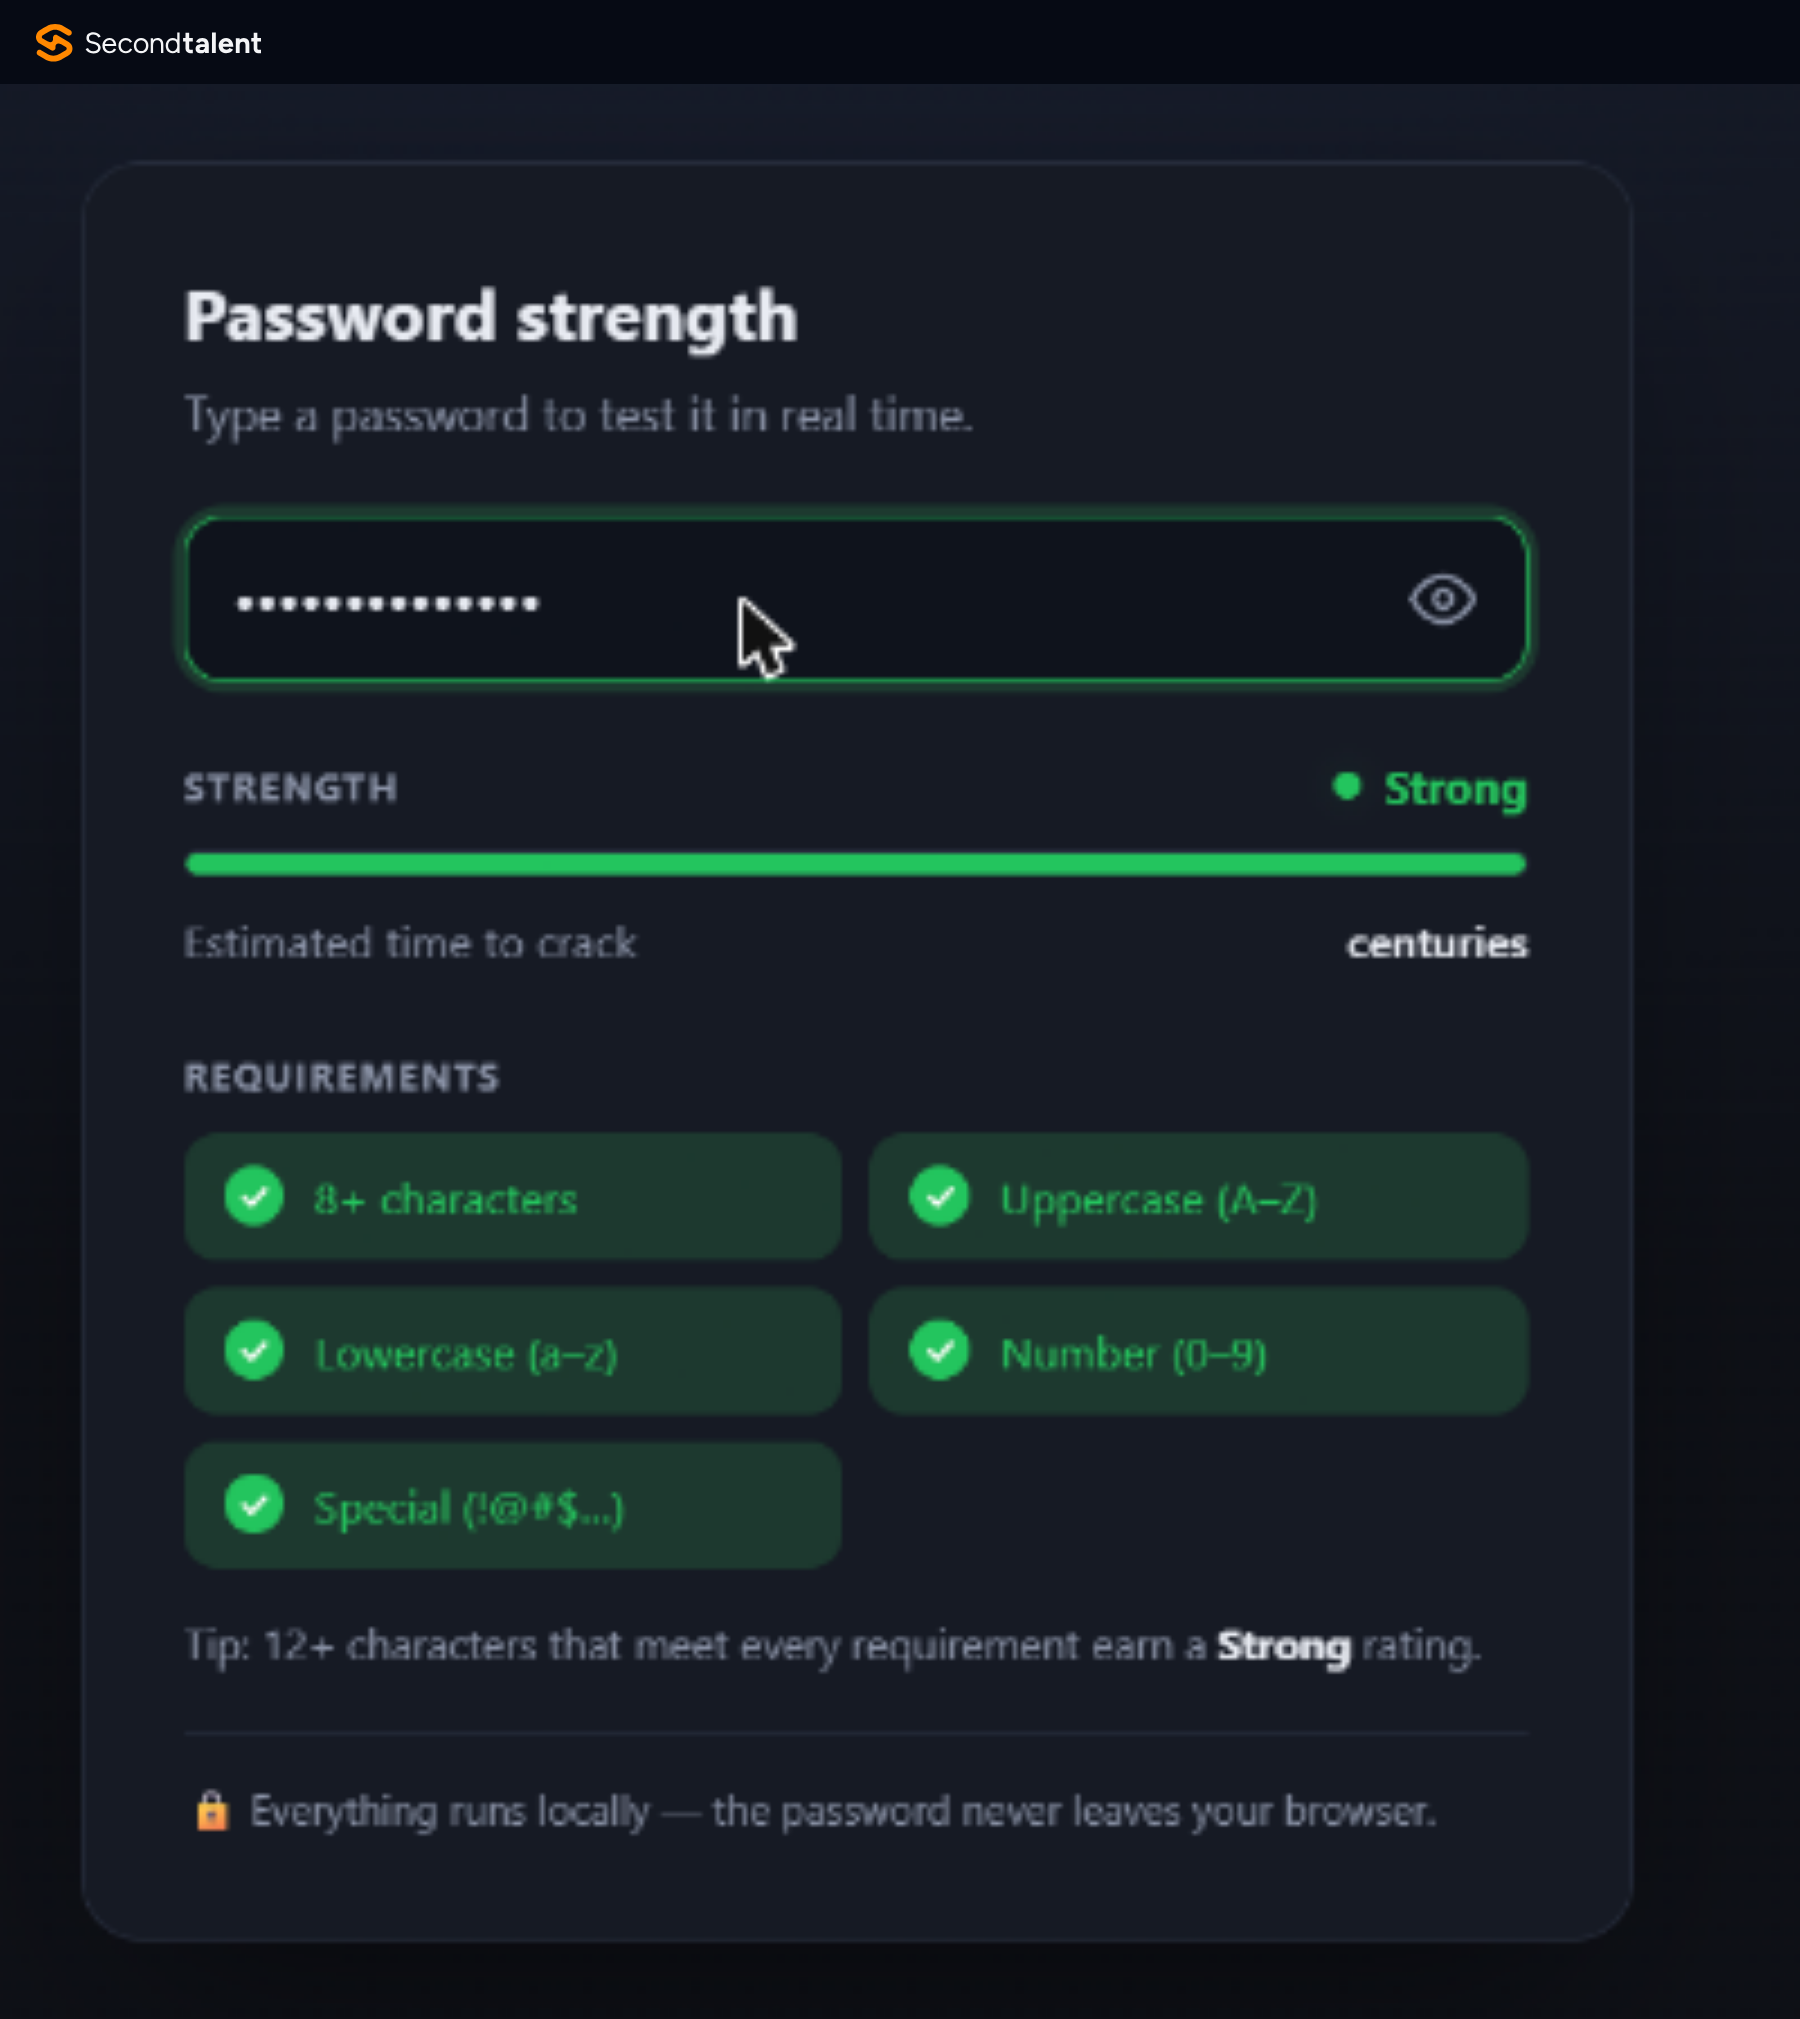
We typed four strings into each tool. GLM rated "abc" Weak with an instant crack time, "abcDef7" Medium at six minutes, and "abcDef7!xyzQ9k" Strong at centuries. Then we typed Password123!.

The breach list matches exact entries only, so a capital P and an exclamation mark were enough to earn Strong.

GLM-5.3-Flash's password strength checker rating a 14-character password Strong, with a full green bar, a crack time of centuries and all five requirement chips ticked.

DeepSeek returned one HTML file in a code block with Copy, Download and Run buttons, about 15 seconds after we pressed send.

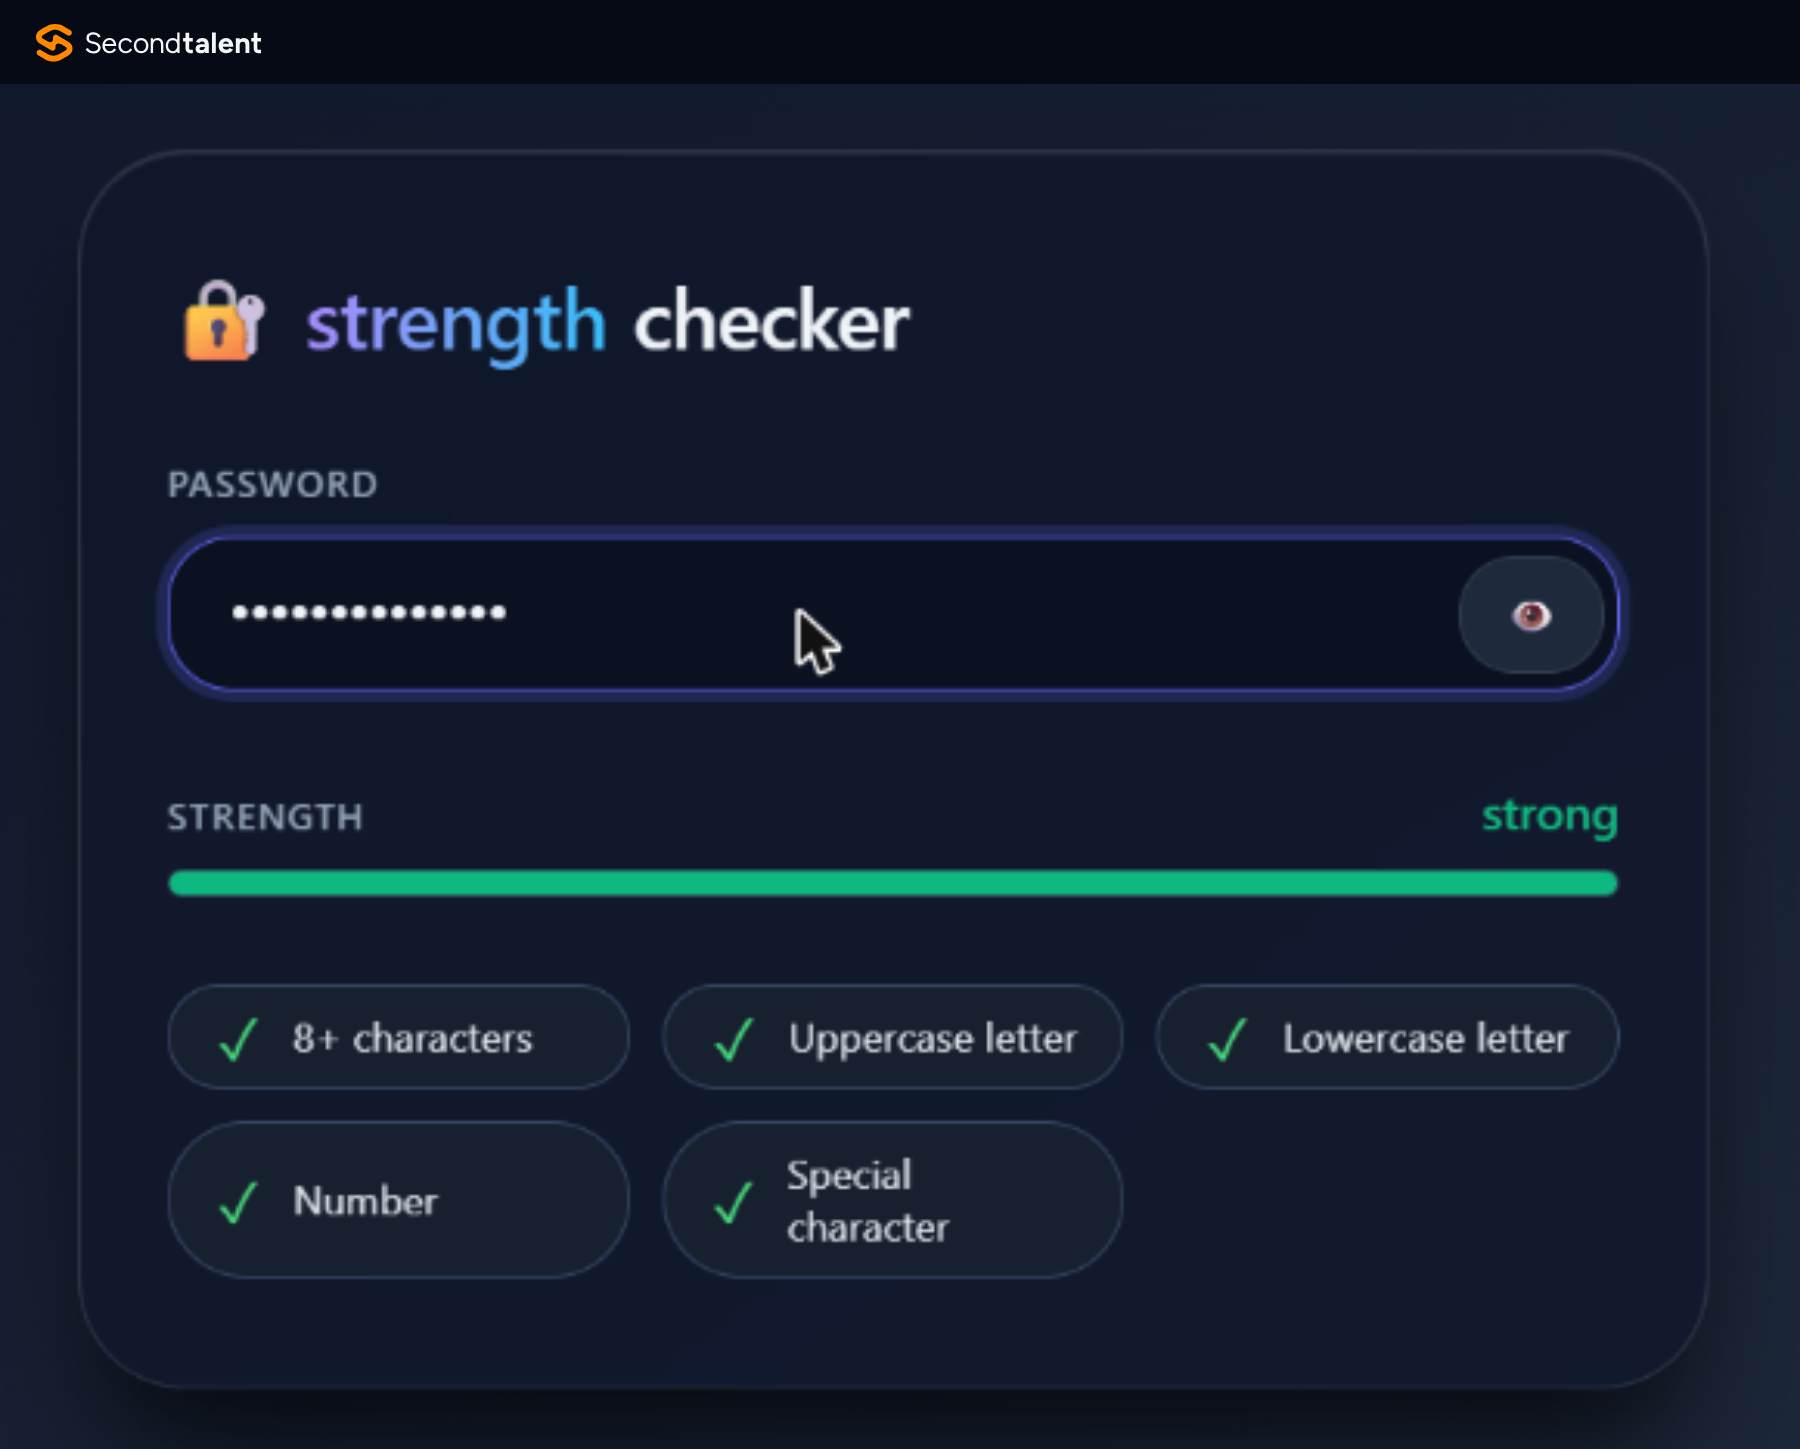
Run opened a side preview: a dark "strength checker" card with a single bar and five pill-shaped checks. "abc" showed a short red Weak bar, "abcDef7" a longer red bar with three of five checks, and the 14-character string a full green Strong bar.

DeepSeek's password strength checker in its Run preview, rating a 14-character password strong with a full green bar and five ticked requirement pills.

DeepSeek also rated Password123! as Strong, without claiming any breach check. Of the eight chatbots we gave this prompt that day, only Claude flagged it.

GLM's page has more in it, with the crack-time line and the 12-character rule, but a security feature that misses the most common pattern is worse than none, and it cost five minutes against fifteen seconds. We gave the round to DeepSeek.

Test 2: a sort bug that hits only some customers

GLM: 2 to 3 minDeepSeek: about 20 sWinner: GLM, on depth

Both found the bug, and GLM also warned about the mistake most people make when fixing it. The prompt: "This function should return the 3 most recent orders per customer, but in production some customers get their oldest orders instead.

Orders come from our API as parsed JSON. Find the bug and fix it." The function sorts with orders.sort((a, b) => a.date - b.date), pushes each order into a per-customer list, and calls shift() once a list passes three.

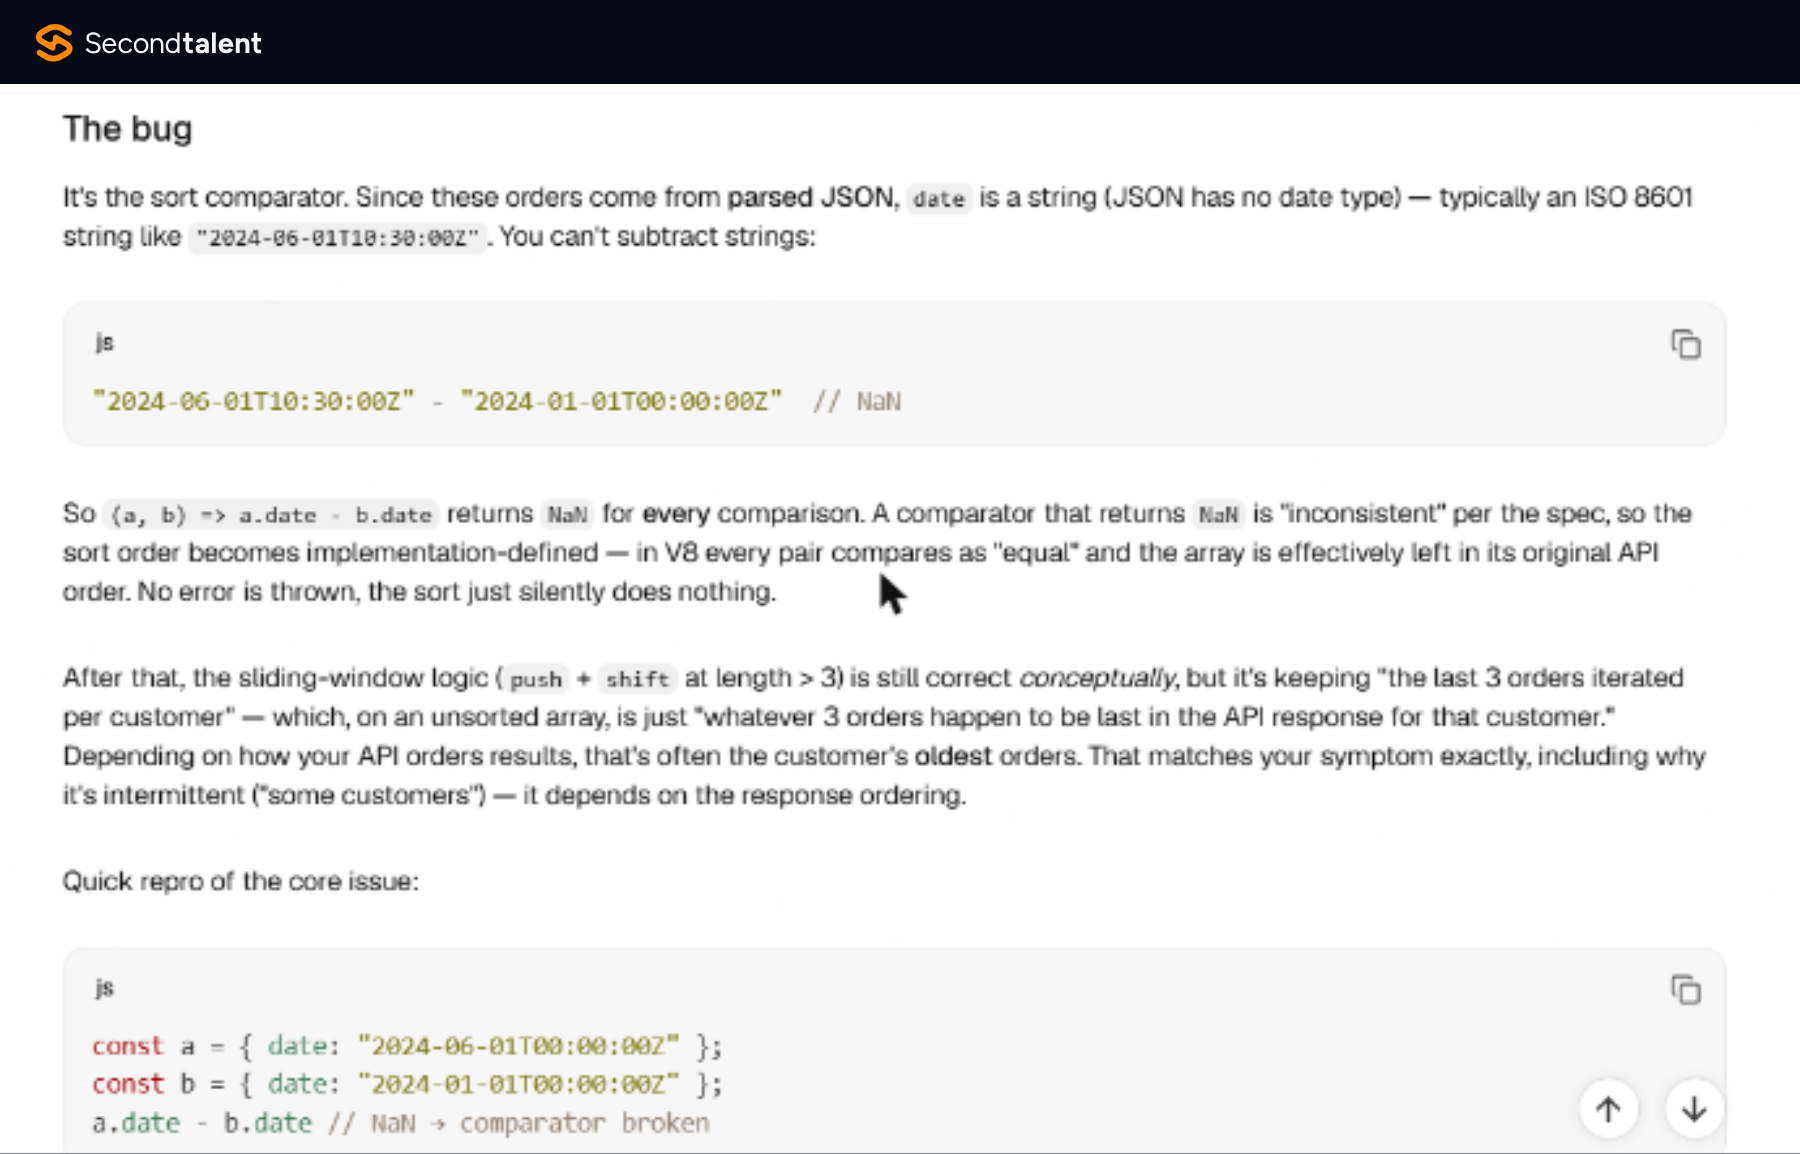
The cause: JSON has no date type, so each date arrives as an ISO string, and one string minus another is NaN. A comparator that returns NaN leaves the array in API order.

If the API sends newest first, the loop keeps each customer's three oldest orders.

GLM laid that out in order. It said a NaN comparator is "inconsistent" under the spec, that in V8 each pair then compares as equal, and that the bug shows up for only some customers because it depends on response order.

It added a three-line repro, a fix with Date.parse on a copy of the array, a mention of toSorted(), and one more warning: if you flip the sort to newest first, you must also switch shift() to pop().

Dola, ByteDance's chatbot, fell into that trap on the same prompt.

GLM-5.3-Flash's debugging answer explaining that JSON dates are strings, that subtracting them returns NaN, and that V8 then treats every pair as equal and leaves the orders in API order, with a short repro.

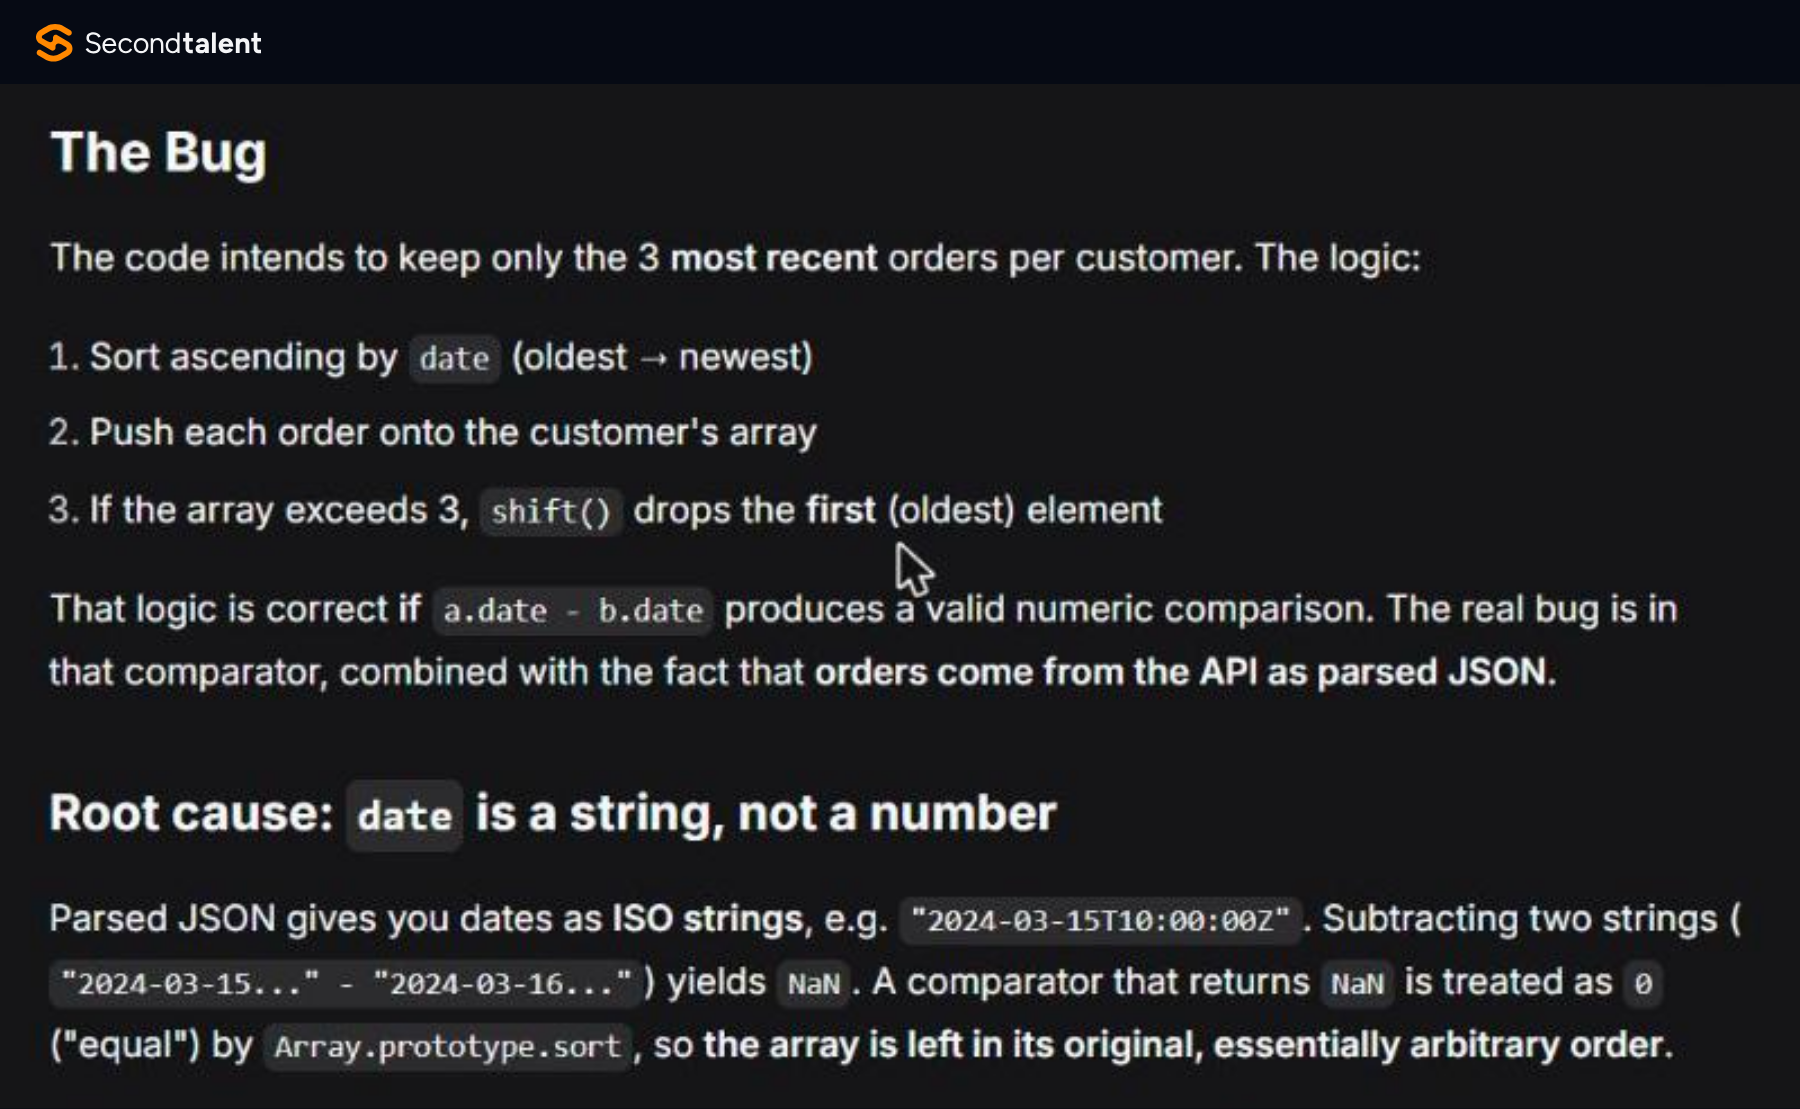
DeepSeek's answer was close behind and arrived in about 20 seconds. It named the same root cause, said a NaN result "is treated as 0" so the array stays in its original order, and tied the oldest-orders symptom to newest-first input.

It flagged that sort() mutates the caller's array and fixed it with Date.parse on a copy. Its bonus per-customer version claimed O(n), which is not true for code that still sorts inside the loop.

DeepSeek's debugging answer: the date field is an ISO string, string subtraction yields NaN, and a NaN comparator is treated as equal, so the array stays in its original order.

Of the seven chatbots we tested besides Claude, GLM's answer came closest to Claude Opus 5.5's. If your team asks a chatbot to explain broken code more than to write it, that is the result to weigh, and it came from GLM's free tier.

Test 3: fact-checking the 2026 World Cup final

GLM: 2 searches, wrongDeepSeek: 13 web pages, rightWinner: DeepSeek

GLM was the only one of the seven chatbots we fact-checked that day to get this wrong. We asked: "Who won the 2026 FIFA World Cup final, what was the score, and in which stadium was it played? Give your sources."

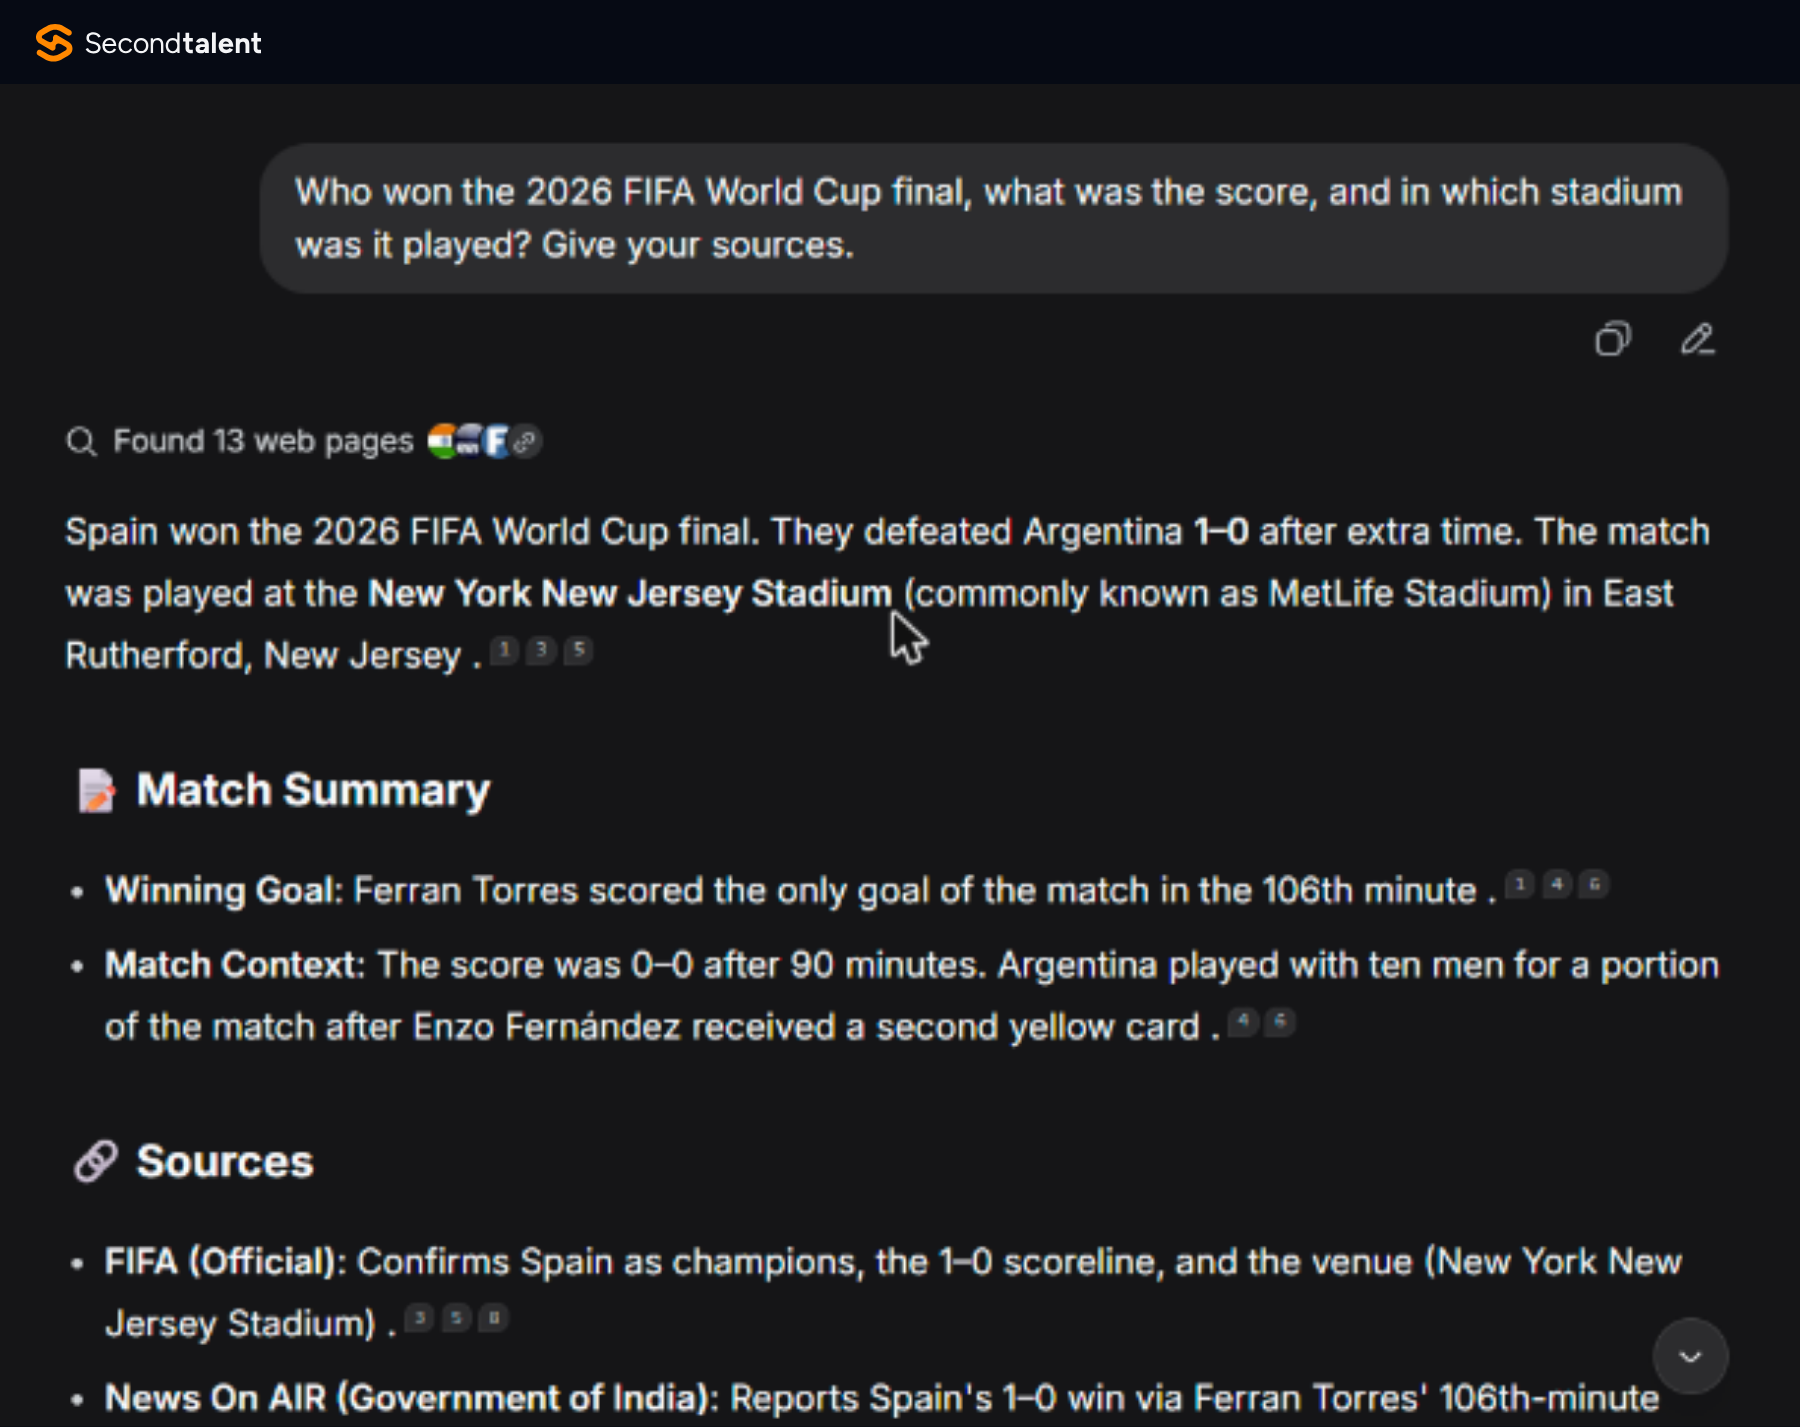
Spain beat Argentina 1-0 after extra time on 19 July 2026 at MetLife Stadium, with Ferran Torres scoring in the 106th minute, as NPR and ESPN reported.

GLM-5.3-Flash ran two searches in about 20 seconds and answered that Argentina beat France 1-0 after extra time, with Messi converting a 117th-minute penalty for a "back-to-back world title". It had the date and stadium right.

It cited three sources, all describing an Argentina v France final:

  • The Guardian live blog URL returned a 404 when we checked it the same day.
  • CBS Sports blocked our check (HTTP 406), so we could not confirm the headline GLM quoted.
  • FIFA.com linked to a generic match-centre page, not a report of the final.
GLM-5.3-Flash's wrong World Cup answer, claiming Argentina beat France 1-0 after a 117th-minute Messi penalty at MetLife Stadium, citing CBS Sports, FIFA.com and a Guardian live blog.

GLM's closing note worries me more than the wrong score. GLM's first search had turned up a snippet about Argentina losing, and the answer waved it away as "a mismatched excerpt from a different coverage page".

The model saw evidence against its answer and argued past it.

DeepSeek, with Search switched on, reported "Found 13 web pages" and answered in about 15 seconds: Spain 1-0 after extra time, Torres in the 106th minute, New York New Jersey Stadium (MetLife), and Argentina down to ten men after Enzo Fernández's second yellow card.

It cited FIFA, News On AIR, Algerian Radio and UBC with numbered chips on each claim.

DeepSeek with search on, after finding 13 web pages: Spain beat Argentina 1-0 after extra time at New York New Jersey Stadium, Ferran Torres scoring in the 106th minute.

One run on one free model does not prove GLM-5.3 would do the same. It does mean that if you use the guest chat for anything factual, check the links it gives you before you repeat the answer.

The companies and models behind each chatbot

Both labs ship a 1M-token flagship and a cheaper Flash model, and on Z.ai's own benchmark table the two flagships finish within a few points of each other. GLM comes from Zhipu AI, which sells it outside China under the Z.ai name.

DeepSeek has its headquarters in Hangzhou. Zhipu and several affiliates have been on the US Entity List since a Commerce Department rule of 16 January 2025, which matters for some US buyers.

ModelReleasedSize (total / active)Context / max outputInputs
GLM-5.318 Aug 2026Same base as GLM-5.21M / 128KText
GLM-5.3-Flash26 Aug 2026320B / 18B1M / 128KText, image, video, file
DeepSeek-V4-Pro13 Aug 2026 (GA)1.6T / 49B1M / 384KText
DeepSeek-V4.1-Flash10 Sep 2026, updated 17 Oct552B backbone / 8B to 16B1M / 384KText, image

Dates come from the Z.ai release notes and DeepSeek's change log, sizes from the Hugging Face model cards. Z.ai's GLM-5.3 guide says you cannot switch reasoning off; it offers low, high and max effort, with max as the default.

That default explains the five-minute wait in test 1. DeepSeek's two models run with thinking on by default too, but its chat app lets you switch DeepThink off, as we did.

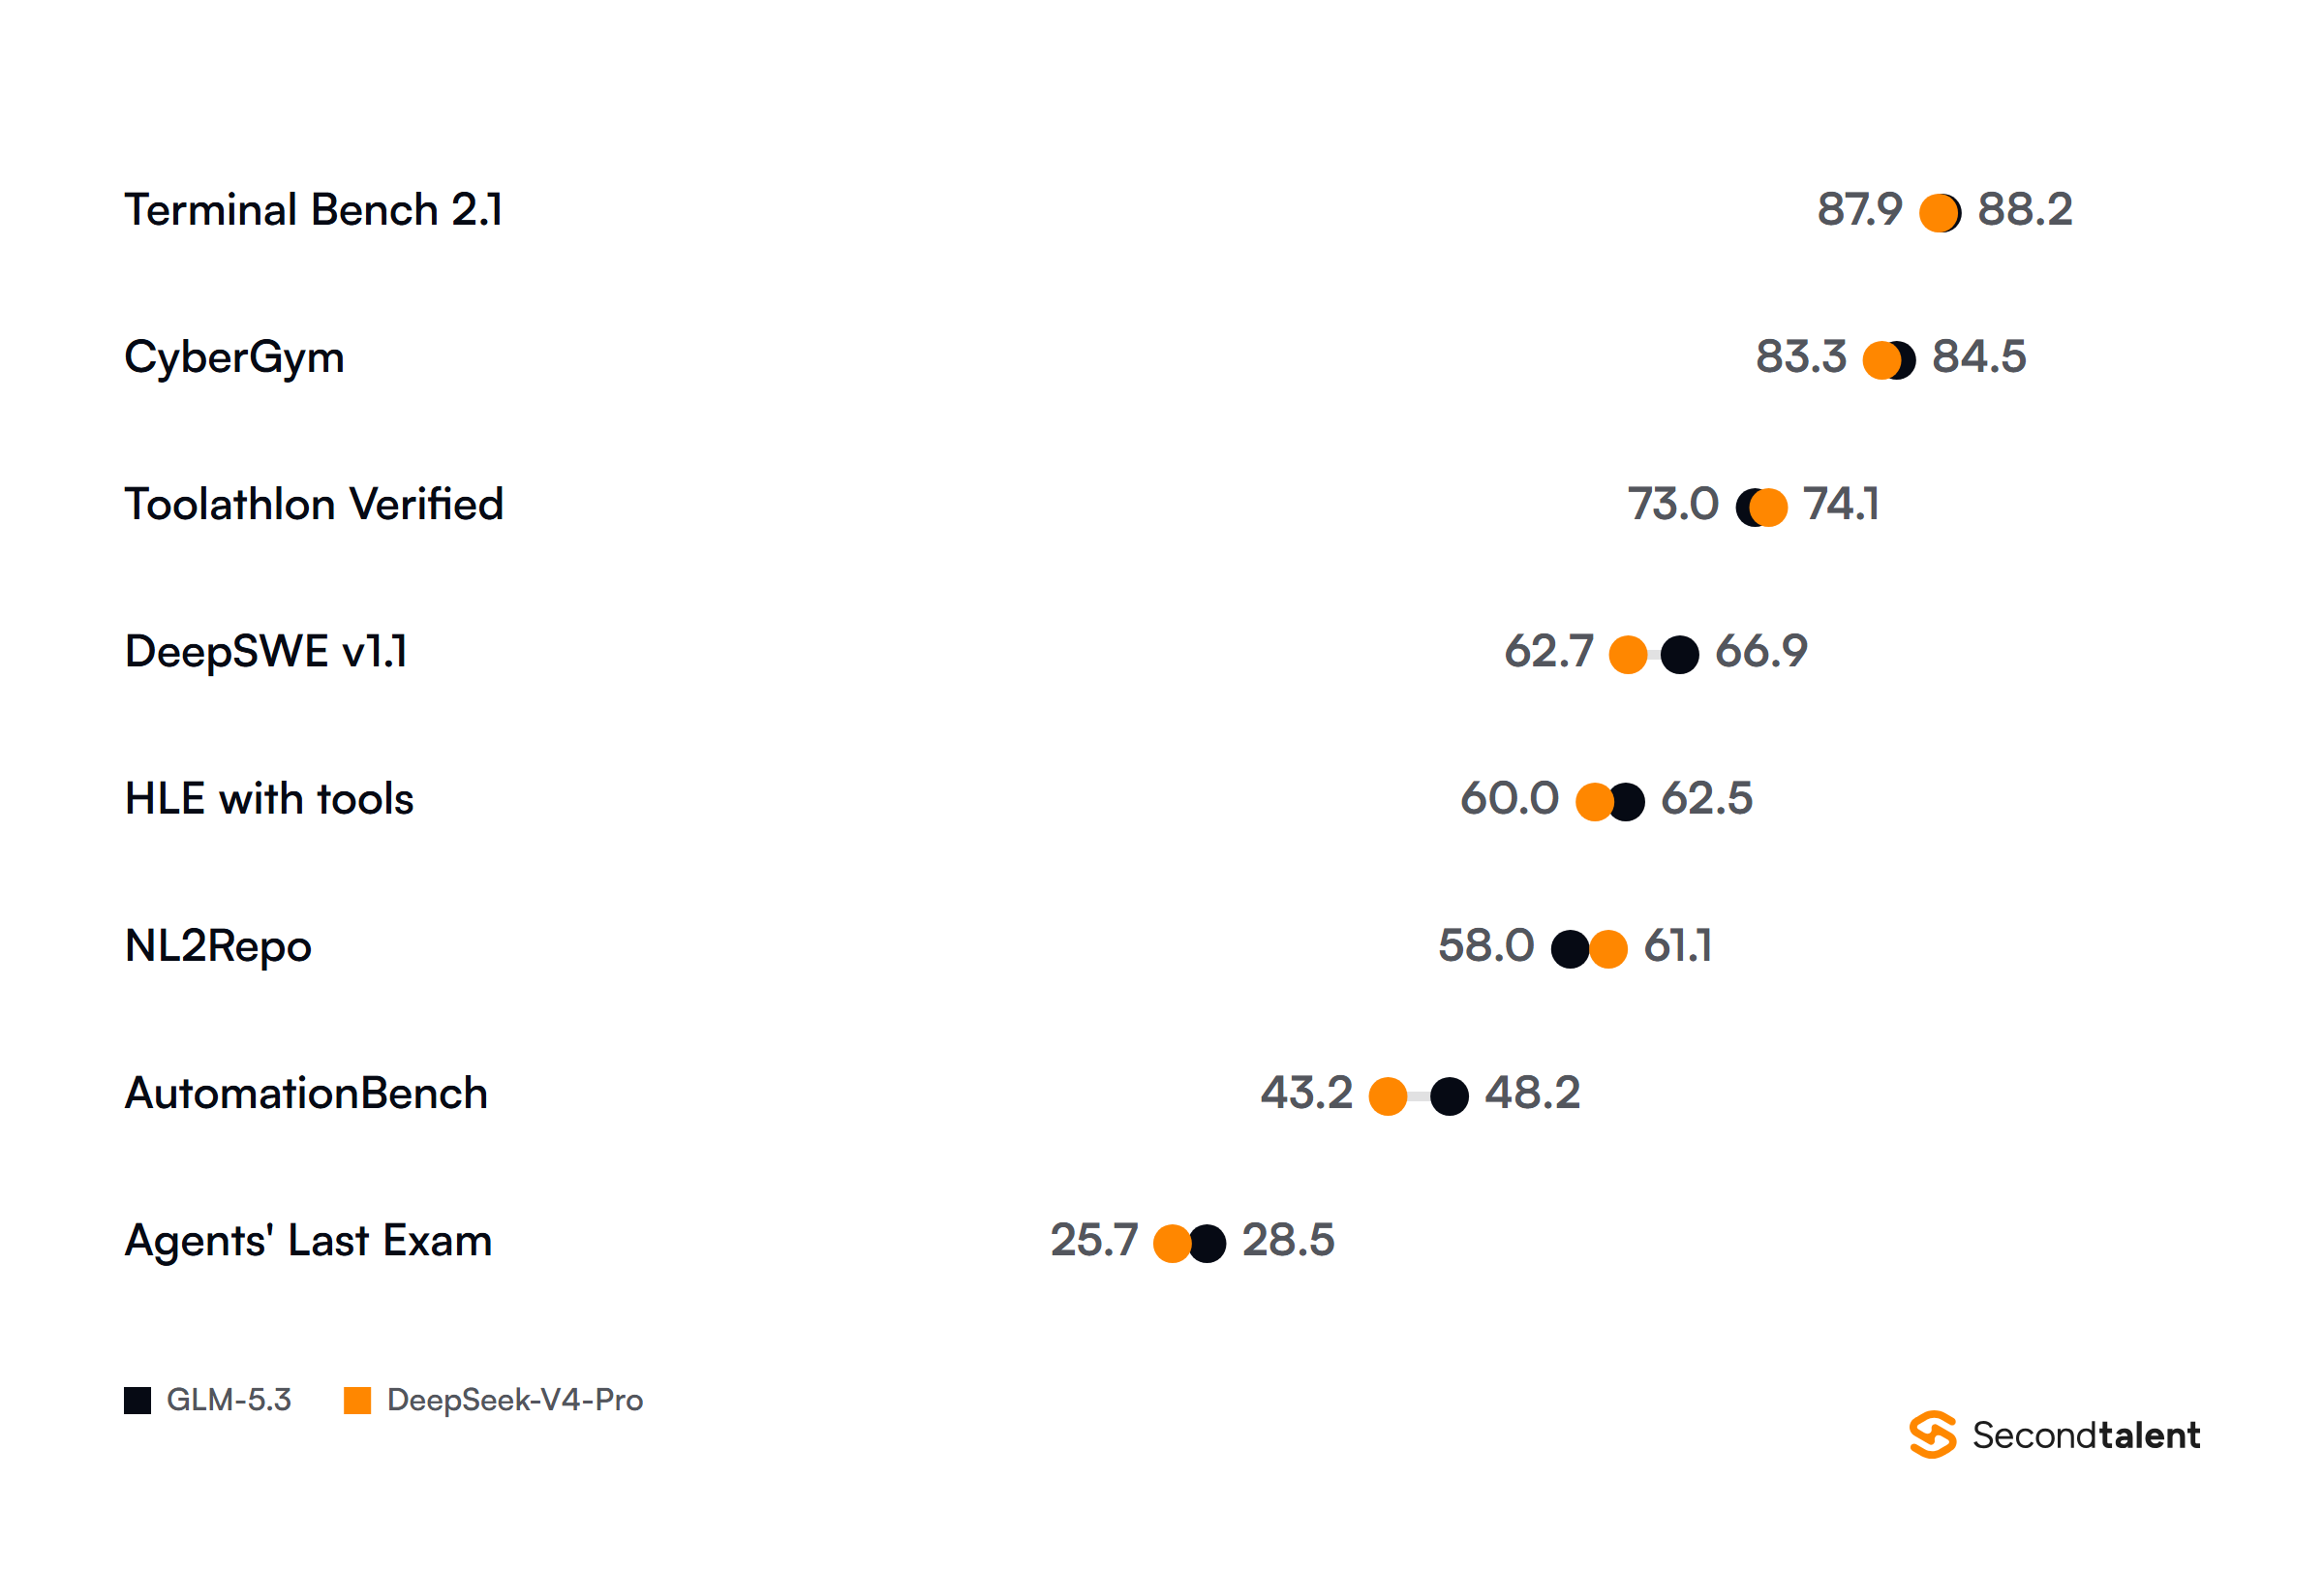
The GLM-5.3 model card includes DeepSeek-V4-Pro in its comparison table. GLM-5.3 leads on six of the eight tests below and trails on NL2Repo and Toolathlon. Z.ai chose the tests and ran the numbers, so read them as a vendor's claim.

Dumbbell chart of GLM-5.3 against DeepSeek-V4-Pro on Z.ai's benchmark table: Terminal Bench 2.1 88.2 vs 87.9, CyberGym 84.5 vs 83.3, Toolathlon Verified 73.0 vs 74.1, DeepSWE v1.1 66.9 vs 62.7, HLE with tools 62.5 vs 60.0, NL2Repo 58.0 vs 61.1, AutomationBench 48.2 vs 43.2, Agents' Last Exam 28.5 vs 25.7. Vendor-reported by Z.ai.

The Flash models tell the opposite story on their makers' own cards. DeepSeek reports 90.6 on Terminal-Bench 2.1 and 74.2 on DeepSWE v1.1 for V4.1-Flash; Z.ai reports 84.3 and 63.4 for GLM-5.3-Flash.

Each vendor ran its own harness, so the gap is a hint, not a measurement. It matches what we saw: DeepSeek's chat model answered faster and got the fact right.

For the full lineups, including older and retired models, see our guides to every GLM model and every DeepSeek model.

API pricing per million tokens

DeepSeek charges by the clock and Z.ai does not. DeepSeek's peak hours are 01:00 to 04:00 and 06:00 to 10:00 UTC on weekdays, outside Chinese public holidays, and DeepSeek bills all other hours at half price.

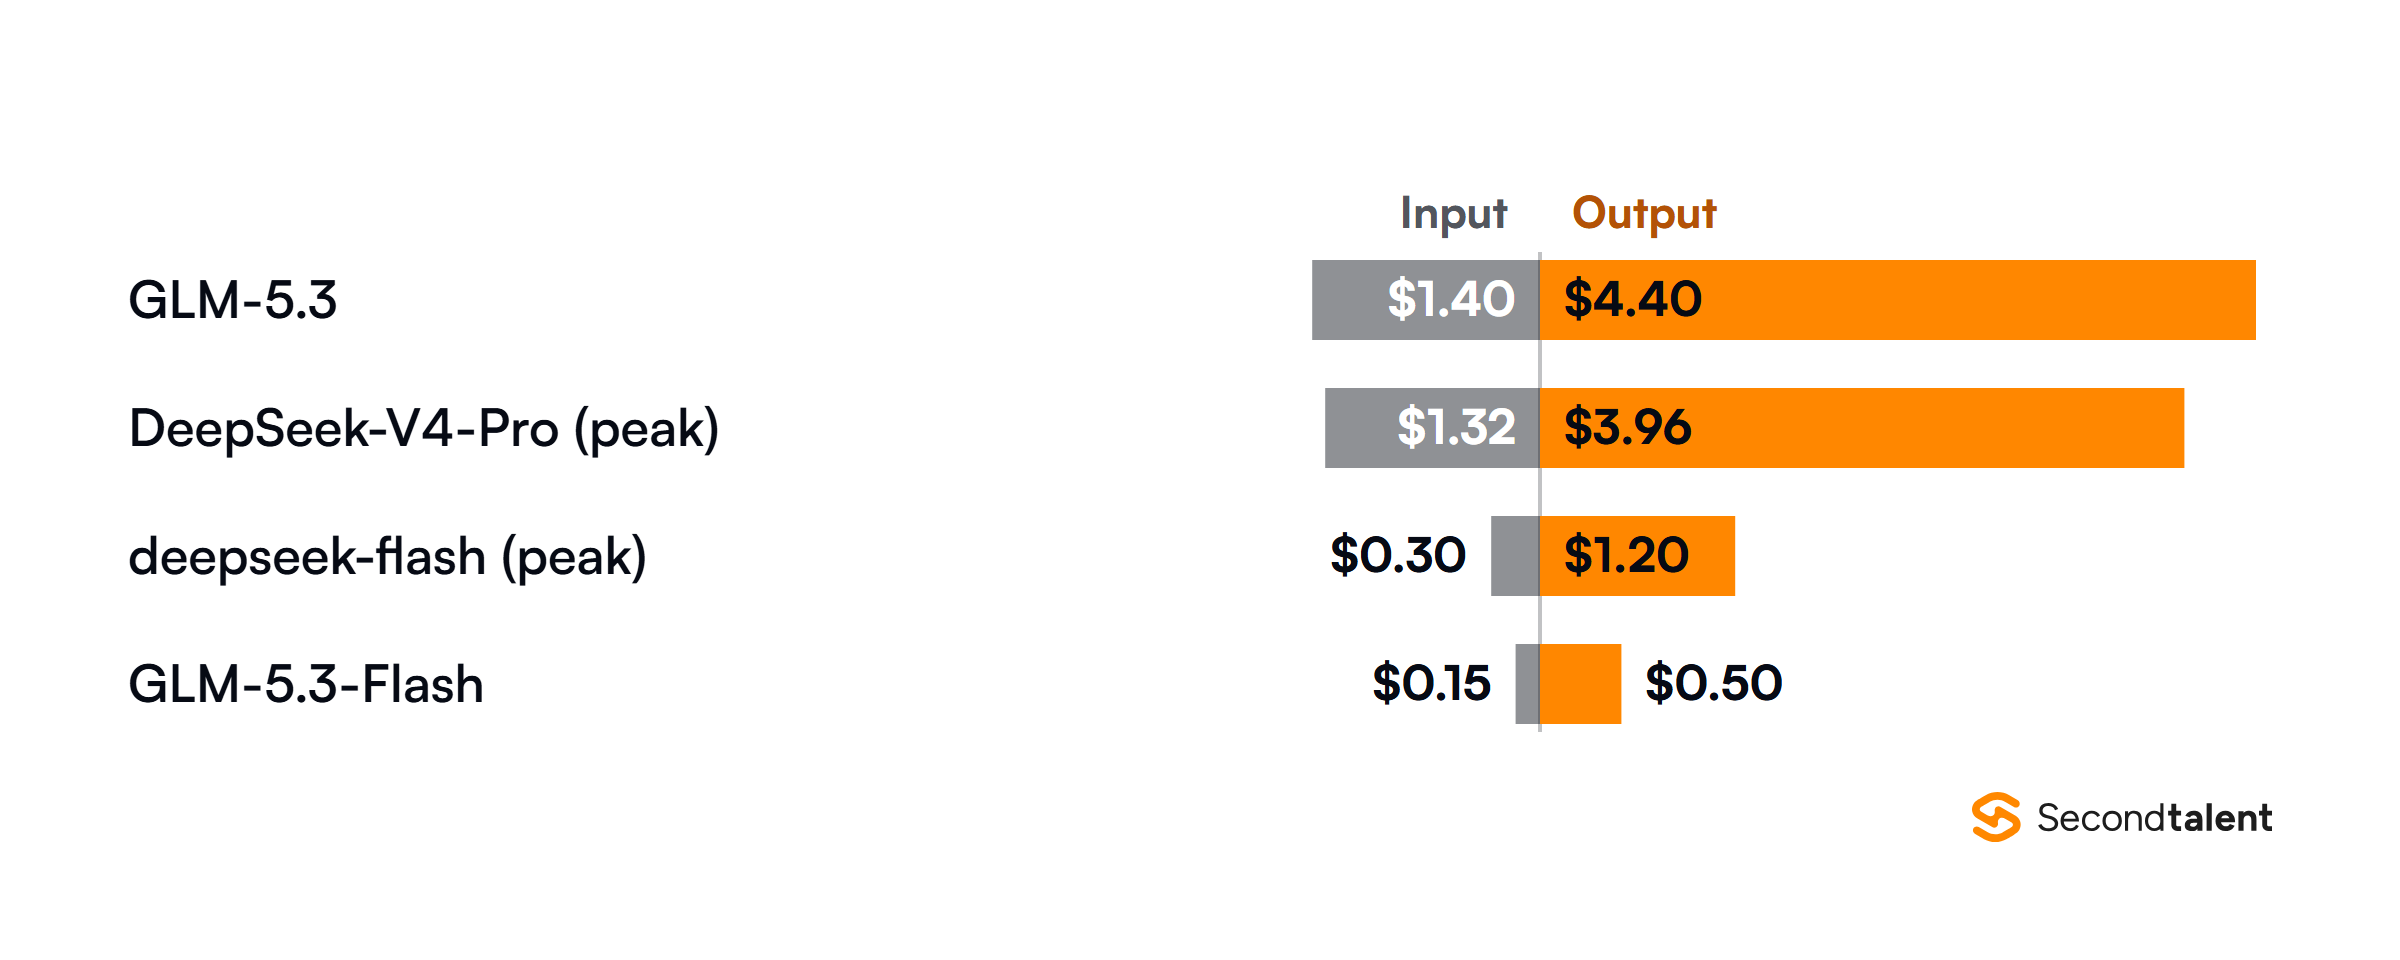
At peak, the flagships sit within 50 cents of each other, and GLM-5.3-Flash costs half as much as deepseek-flash on input and less than half on output.

Split bar chart of API prices per million tokens, input against output: GLM-5.3 $1.40 and $4.40, DeepSeek-V4-Pro at peak $1.32 and $3.96, deepseek-flash at peak $0.30 and $1.20, GLM-5.3-Flash $0.15 and $0.50, from the Z.ai and DeepSeek pricing pages on 17 November 2026.

Off-peak, deepseek-flash drops to $0.15 input and $0.60 output, level with GLM-5.3-Flash on input and 10 cents dearer on output. Cached input is where DeepSeek pulls ahead:

$0.006
deepseek-flash cache hit at peak, $0.003 off-peak
$0.03
GLM-5.3-Flash cached input
$0.044
DeepSeek-V4-Pro cache hit at peak
$0.26
GLM-5.3 cached input
USD per million cached input tokens. Source: Z.ai and DeepSeek API pricing pages, 17 November 2026.

An agent that resends a long system prompt with each call pays about six times more for cached tokens on GLM-5.3 than on DeepSeek-V4-Pro at peak. Z.ai has two offsets.

GLM-4.7-Flash and GLM-4.5-Flash cost nothing on its API, and the GLM Coding Plan starts at $18 a month for GLM-5.3 inside coding tools, with off-peak use counted at half the credit rate.

Both chat apps were free to use in our tests. DeepSeek needed an account; Z.ai needed one only for its stronger models.

Open weights and licences

DeepSeek is the simpler choice to self-host. The model cards for DeepSeek-V4-Pro and V4.1-Flash both state that the weights are under the MIT License, with no conditions beyond keeping the notice.

Z.ai splits its line: GLM-5.3-Flash uses the MIT License, while GLM-5.3 ships under its own GLM-5.3 licence, which grants MIT-style rights with one exception: a company running a Model-as-a-Service business must pass "Z.AI's security review" before commercial use if it and its affiliates earn more than $10 billion over any 12 months.

The licence sets no user cap and no territory limits, and a product that only embeds the model in its own features is outside the definition.

Size decides the hardware. GLM-5.3-Flash activates 18B parameters per token and DeepSeek-V4-Pro 49B, out of 320B and 1.6T in total. All of those experts have to sit in GPU memory, so even the Flash models need a multi-GPU server.

Access, sign-up and privacy

Z.ai is the easier one to try from outside China: chat.z.ai opened straight into a guest chat for us, with Full-Stack, Writing, Data Insight, PPT and Web Site tiles on the home screen. chat.deepseek.com sent us straight to a login page offering phone or email, Google and Apple.

The privacy terms differ more than the sign-up flow:

  • DeepSeek: the privacy policy (updated 10 February 2026) names Hangzhou DeepSeek Artificial Intelligence Co., Ltd. as the operator, says it collects, processes and stores data in the People's Republic of China, and lists model training as a use. You can opt out of training by emailing privacy@deepseek.com.
  • Z.ai: the chat privacy policy names a Singapore company, Jingsheng Hengxing Technology Pte. Ltd., and says data is "generally processed in Singapore". It lists model training as a legitimate interest that can cover message content, with a right to object. Z.ai's API data processing terms say customer content is not saved on its servers.

Neither policy is a reason to paste client data into a free chat window. For anything sensitive, the API terms or self-hosted open weights are the safer route on both sides.

I would also check whether your customers have rules about Chinese AI vendors before you build on either.

GLM or DeepSeek: which should you use

For most people, DeepSeek. It was faster on all three prompts, got the only factual question right, and its MIT weights carry no strings.

GLM is the pick when the job is reading and fixing code, or when you want to try a strong Chinese model without signing up.

JobPickWhy
Questions about current eventsDeepSeek, Search onRight answer from 13 sources; GLM invented a final
Explaining a bugGLMClosest answer to Claude's of seven chatbots in our test
Quick code you will review anywayDeepSeek15 seconds against 5 minutes for the same result
Trying a Chinese model with no accountGLMGuest chat on GLM-5.3-Flash
Cheapest API at peak hoursGLM-5.3-Flash$0.15 / $0.50 per million tokens
Agents with long cached promptsDeepSeek$0.006 cached input on Flash at peak
Self-hosting with no licence conditionsDeepSeek or GLM-5.3-FlashBoth MIT
Long single outputsDeepSeek384K max output against 128K

Our earlier hands-on reviews of GLM 4.6 for coding, GLM against Claude Sonnet and DeepSeek for coding cover the older models in more depth.

Hire engineers who build on GLM and DeepSeek

Our tests show why model choice is the easy part: GLM's checker shipped a breach list that did not work, and its fact-check cited a dead link with confidence. Catching that takes engineers who test model output before it reaches users.

We match companies with pre-vetted AI engineers across Asia in about 24 hours.

FAQ

Is GLM better than DeepSeek for coding?

For explaining and fixing code, GLM-5.3-Flash did better in our debugging test. For writing code fast, DeepSeek did: it built the same working checker in 15 seconds that took GLM five minutes.

On Z.ai's own table, GLM-5.3 edges DeepSeek-V4-Pro on most coding benchmarks.

Can I use GLM-5.3 for free?

Not as a guest. chat.z.ai only offers GLM-5.3-Flash without an account and shows GLM-5.3 as "Sign in to get smarter responses". On the API, GLM-4.7-Flash and GLM-4.5-Flash are the free models.

How does DeepSeek compare with other Chinese chatbots?

DeepSeek passed all three of our prompts, as did Kimi, Qwen and Ernie. See our Doubao vs DeepSeek comparison for ByteDance's side.

Get developers who ship with AI agents. Starts at $25/Hour.

Start Hiring $0 cost until you hire
Elton Chan

Written by

Elton Chan is the Co-Founder of Second Talent, a solution that connects global tech leaders with top-tier tech talent across Asia. He specializes in talent solutions and has led Second Talent’s rapid growth since 2024, helping scale its network to over 100,000 pre-vetted developers and earning industry recognition as the #1 in the Global Hiring category on G2. A long-time entrepreneur with deep roots in digital transformation, Elton previously co-founded Branch8, a Y Combinator–backed e-commerce technology firm, and served as the Founding Chairman of HKEBA, a leading Asia-focused business association driving innovation, digital education, and cross-border collaboration. His work bridges technology, talent, and business strategy to shape how companies scale in an increasingly remote and digital world.

More posts by Elton Chan →