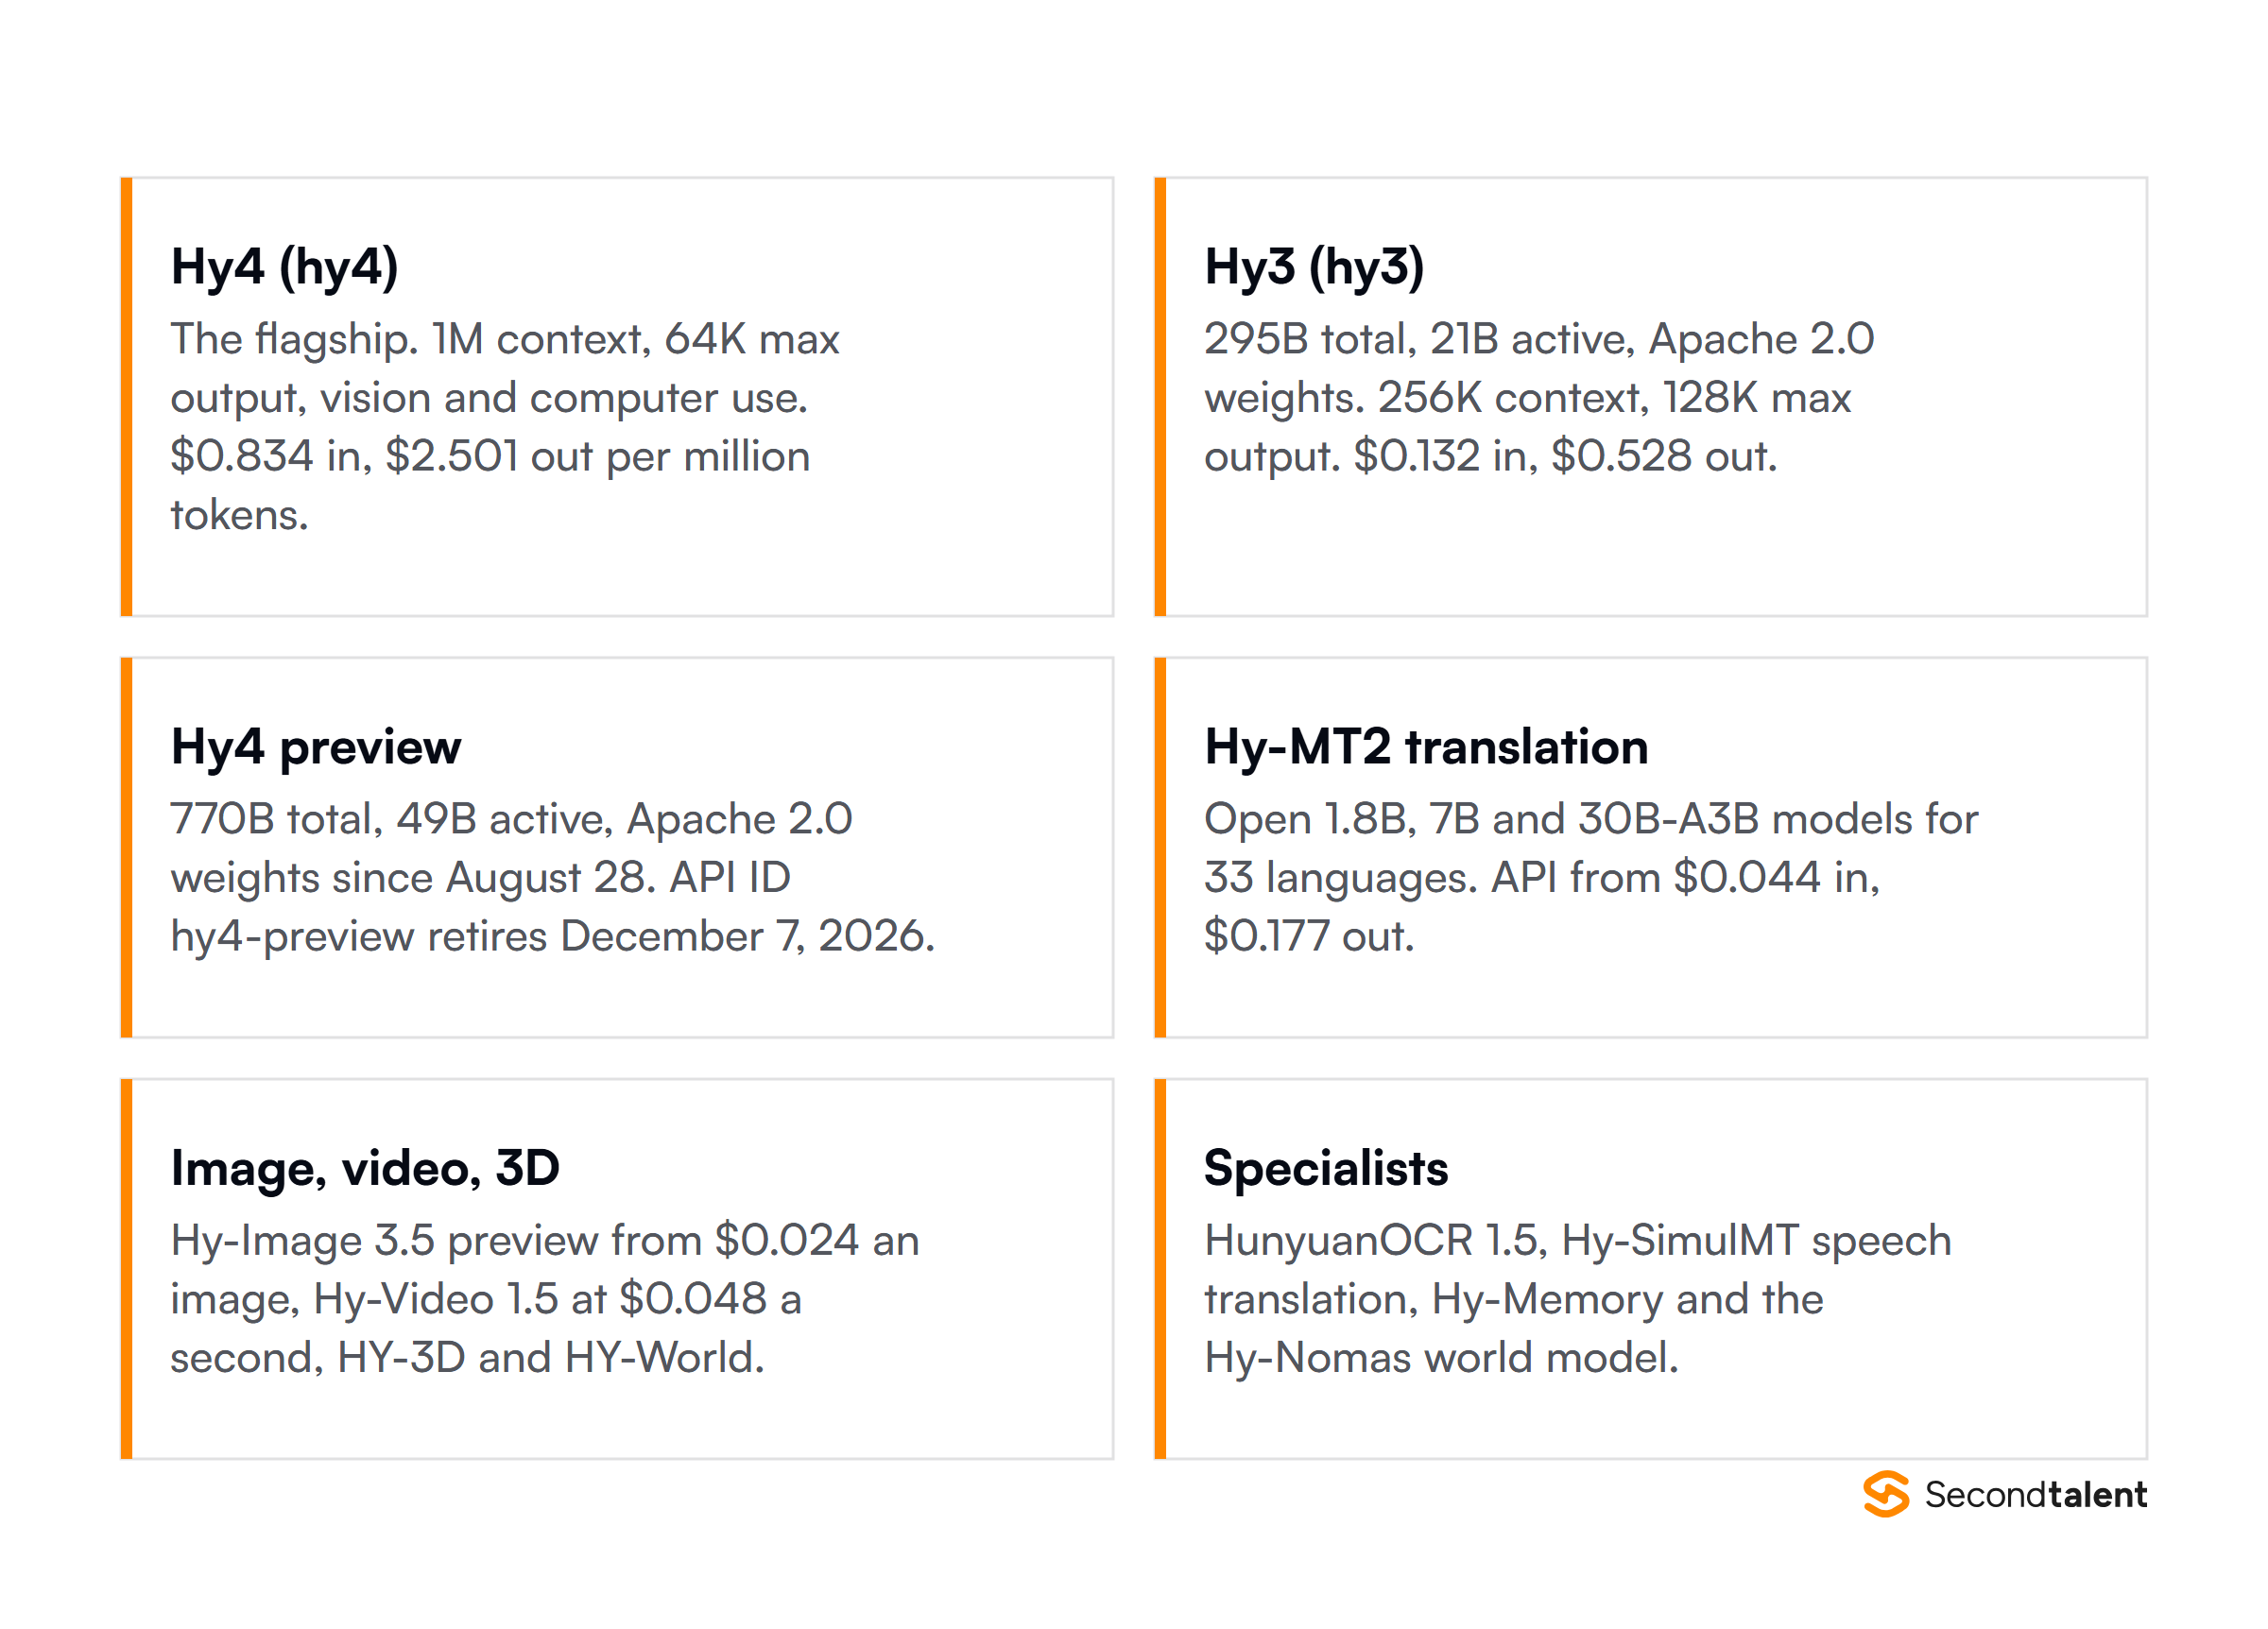
TL;DR: Tencent's current Hunyuan flagship is Hy4, priced at $0.834 input and $2.501 output per million tokens with a 1M token context window. Hy3 is the cheaper workhorse at $0.132 input and $0.528 output, and its weights are free under Apache 2.0. The largest open Hunyuan model is Hy4 preview, with 770B total and 49B active parameters.
Tencent shut its original Hunyuan API outside China on September 30, 2026. The Hunyuan text models you can call there today run on a newer platform called TokenHub, under shorter IDs: hy4, hy3 and hy-mt2. The rename tracks a rebuild.
Hy3 preview, released on April 23, 2026, was the first model trained on Tencent's rebuilt infrastructure, and three more flagship releases followed it by November 4.
Key takeaways
1Hunyuan licenses split in two. Hy3, Hy4 preview and Hy-MT2 are Apache 2.0; Hy3 preview, HunyuanImage 3.0 and HunyuanVideo 1.5 use a community license that does not apply in the EU, UK or South Korea.
2The hy4-preview API ID stops answering on December 7, 2026. Move code to hy4 before then.
3Hy3 can write a longer single reply than Hy4: 128K tokens of max output against 64K.
4Tencent bills Hy4 at half its list price until December 31, 2026, on both the China and international sites.
The current Hunyuan models at a glance
These are the Hunyuan language and translation models on Tencent Cloud TokenHub as of November 12, 2026, with the model ID your engineers pass to the API.
Tencent still calls the program Hunyuan, but new models ship as "Hy": Hy3, Hy4, Hy-MT2. The family has two halves that most write-ups blur.
One half is the hosted API on TokenHub. The other is a set of open-weight checkpoints on Hugging Face, ModelScope and GitCode, and the two halves do not line up one to one.
Hy4 is on the API but its weights are not public yet, while Hy-SimulMT and Hy-Memory are open releases with no API row.
Around the text models sit image, video, 3D and world models, several of them older Hunyuan-branded releases that still matter.
Hy4
ID: hy4Launched: November 4, 2026Weights: not published yet
Hy4 adds two things no earlier Hy flagship had: image understanding and computer use.
TokenHub describes it as the official release that improves on Hy4 preview for agent and long-running work, and adds visual understanding and computer-use agent abilities. Caixin reported the launch on November 4, 2026.
The API takes up to 960K tokens of input inside its 1M window and returns up to 64K. It supports deep reasoning with preserved thinking, structured output, function calling, caching and image input.
As of November 12, Tencent had not posted Hy4 weights on Hugging Face, so the open checkpoint for this generation is still Hy4 preview.
Tencent ran a blind test before shipping Hy4 preview: 163 of its own experts rated outputs on 203 engineering tasks. Hy4 preview averaged 2.99 against 2.92 for GLM 5.3 and 2.94 for Kimi K3, according to the Hy4 preview model card.
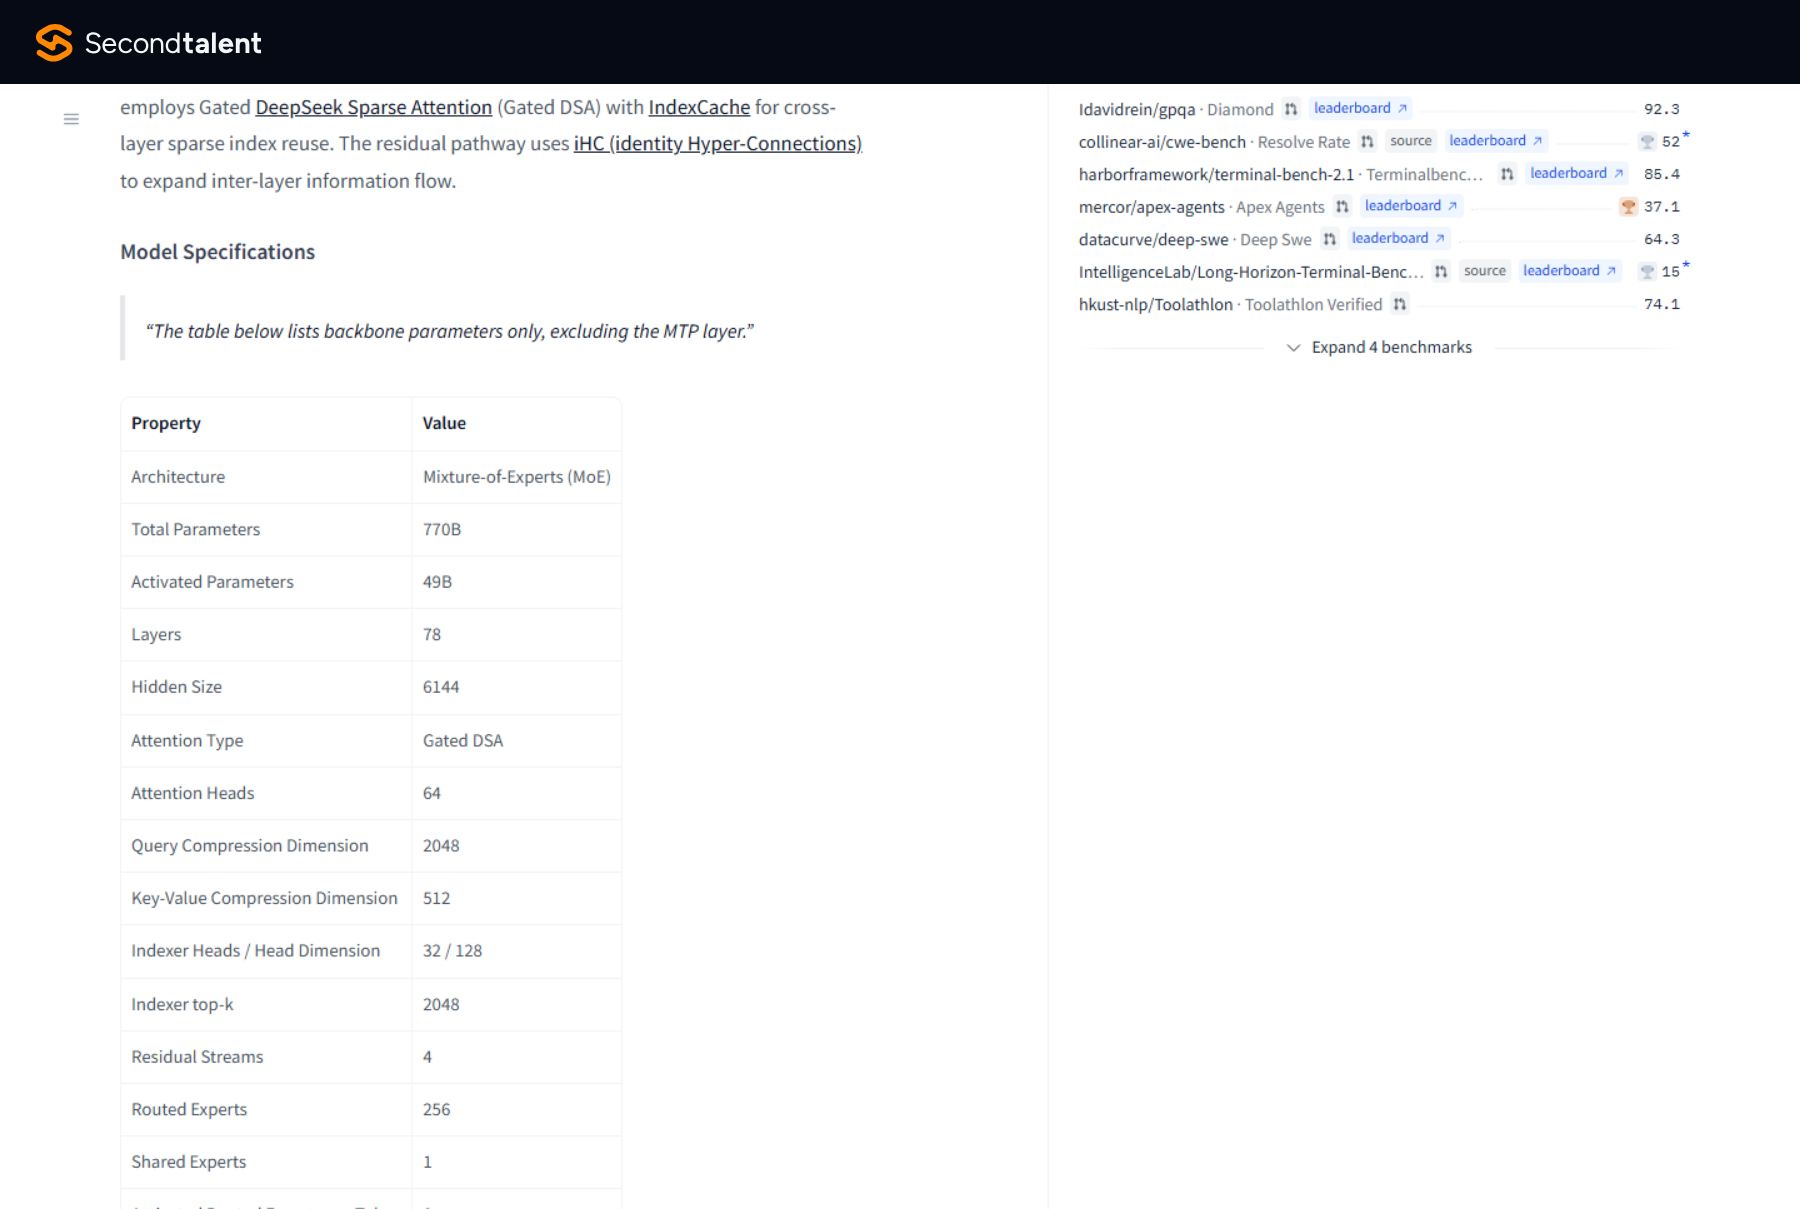
It is a Mixture-of-Experts model with 770B total parameters, 49B active per token, 256 routed experts and a 1M token context, and it borrows its sparse attention from DeepSeek.
The weights arrived on August 28, 2026 under Apache 2.0, with a ready vLLM image that serves the FP8 version across 8 GPUs.
Tencent lists two known problems: it reasons for longer than it needs to and it over-checks its own work.
If you compare it with the open models in our GLM model guide or Kimi model guide, keep in mind that the scores above are Tencent's own.
Hy3
Size: 295B total, 21B activeLicense: Apache 2.0Released: July 6, 2026
The headline change in Hy3 is fewer made-up answers. On Tencent's internal tests its hallucination rate fell from 12.5% to 5.4%, and its multi-turn issue rate from 17.4% to 7.9%, according to the Hy3 model card.
Tencent gathered feedback from more than 50 of its own products after the April preview, then scaled up post-training.
In a blind test with 270 experts, Hy3 scored 2.67 out of 4 against 2.51 for GLM-5.1. The architecture is the same as the preview: 295B total parameters, 21B active, 192 experts with 8 active per token, and a 256K context.
Tencent recommends 8 GPUs with large memory, such as H20-3e, to serve it. The Beijing News reported the July 6 launch and that Hy3 already runs inside WorkBuddy, CodeBuddy, Yuanbao and ima.
Hy-MT2 translation models
Hy-MT2 is Tencent's translation line, and its smallest model squeezes into 440 MB. Tencent open-sourced three sizes on May 21, 2026: 1.8B, 7B and a 30B-A3B MoE, all covering 33 languages under Apache 2.0, per the Hy-MT2 model card.
The 440 MB figure is the 1.8B model after 1.25-bit quantization, built for on-device use. On the API, Hy-MT2 comes in Lite, Plus and Pro tiers with an 8K context and 4K output. Tencent cut the Plus price on August 10, 2026.
Specialist models
Three smaller open releases fill narrow jobs. HunyuanOCR 1.5, about 1.1B parameters, parses documents, spots text in images and translates text inside pictures, with 4K image input and a 128K context.
Hy-SimulMT-30B-A3B, released October 26, 2026, interprets live speech between Chinese and English and clones the speaker's voice.
Hy-Memory-30B-A3B, with about 3B active parameters, replaces the general LLM inside memory frameworks such as Mem0 and MemOS and decides what an agent should remember. Hy-SimulMT and Hy-Memory are Apache 2.0.
HunyuanOCR uses the Tencent Hunyuan Community License.
The open-weight models
Tencent's two most recent text flagships went out under Apache 2.0, which is a change from its own past. Hunyuan-A13B, Hy3 preview and most image, video and 3D releases use Tencent's community licenses instead.
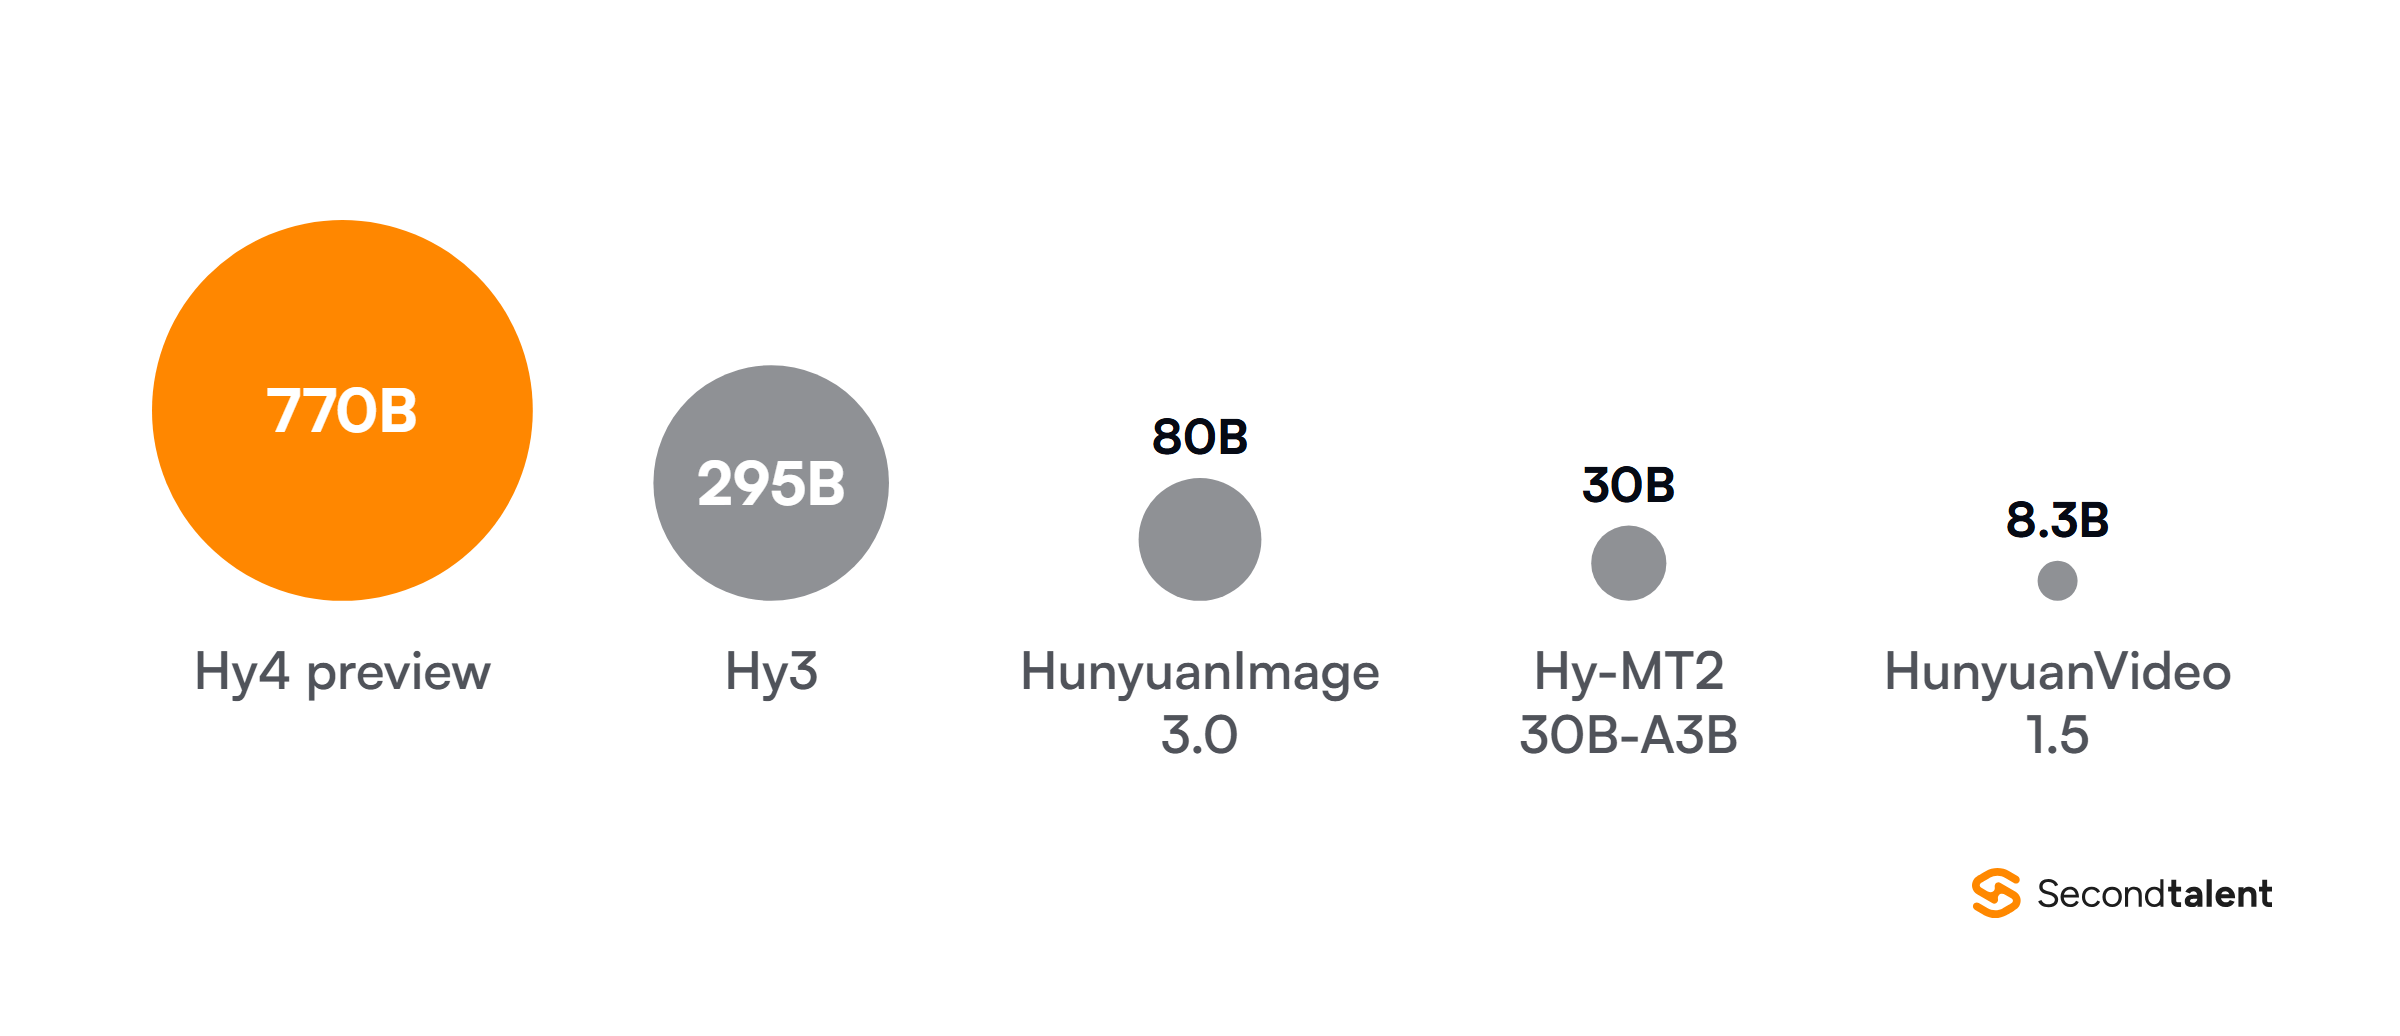
Size varies by two orders of magnitude across the family. Hy4 preview carries about 93 times the parameters of HunyuanVideo 1.5, and the gap is why one Hunyuan model needs a rack of data center GPUs and another runs on a gaming card.
Check the license before you deploy. The Tencent Hy Community License and the Hunyuan Community License both state that they do not apply in the European Union, the United Kingdom or South Korea. They also require a separate license from Tencent if your products had more than 100 million monthly active users in the month before the model's release date.
That territory clause is the first thing I would check for any team with users or staff in Europe. Hy3 and Hy4 preview avoid it, which makes them the safe open picks for a global product.
Teams comparing open families often look at Qwen's open-weight models next, since most of those are also Apache 2.0.
Image, video, 3D and world models
Tencent calls HunyuanImage 3.0 the largest open-source image generation MoE model to date, with 64 experts, 80B total parameters and 13B active, according to its model card.
It generates images inside an autoregressive language model rather than a diffusion transformer, and the Instruct version added in January 2026 handles image editing and prompt rewriting.
On the API the image line has moved on. The hy-image-v3 endpoint goes offline on November 12, 2026, and Hy-Image 3.5 preview costs $0.024 an image at 1K or 2K and $0.032 at 4K.
HunyuanVideo 1.5 has 8.3B parameters, and its step-distilled 480p image-to-video model can render a clip within 75 seconds on a single RTX 4090. The hosted Hy-Video 1.5 costs $0.048 per second of 720p output.
The newest open video release, Hy-Nomas, builds a world one clip at a time from text prompts and camera moves, at 720 by 1280 and 24 frames per second, under Apache 2.0.
For 3D, HY-World 2.0 turns text, images or video into 3D meshes and Gaussian splats, first released in April 2026 under its own community license. The API runs HY-World 2.1 at $0.77 per panorama and $12.30 per walkable scene.
HY-3D asset models bill in credits at $0.02 each, and a HY-3D 3.0 or 3.1 request takes 15 to 60 credits, or $0.30 to $1.20.
Pricing compared across the lineup
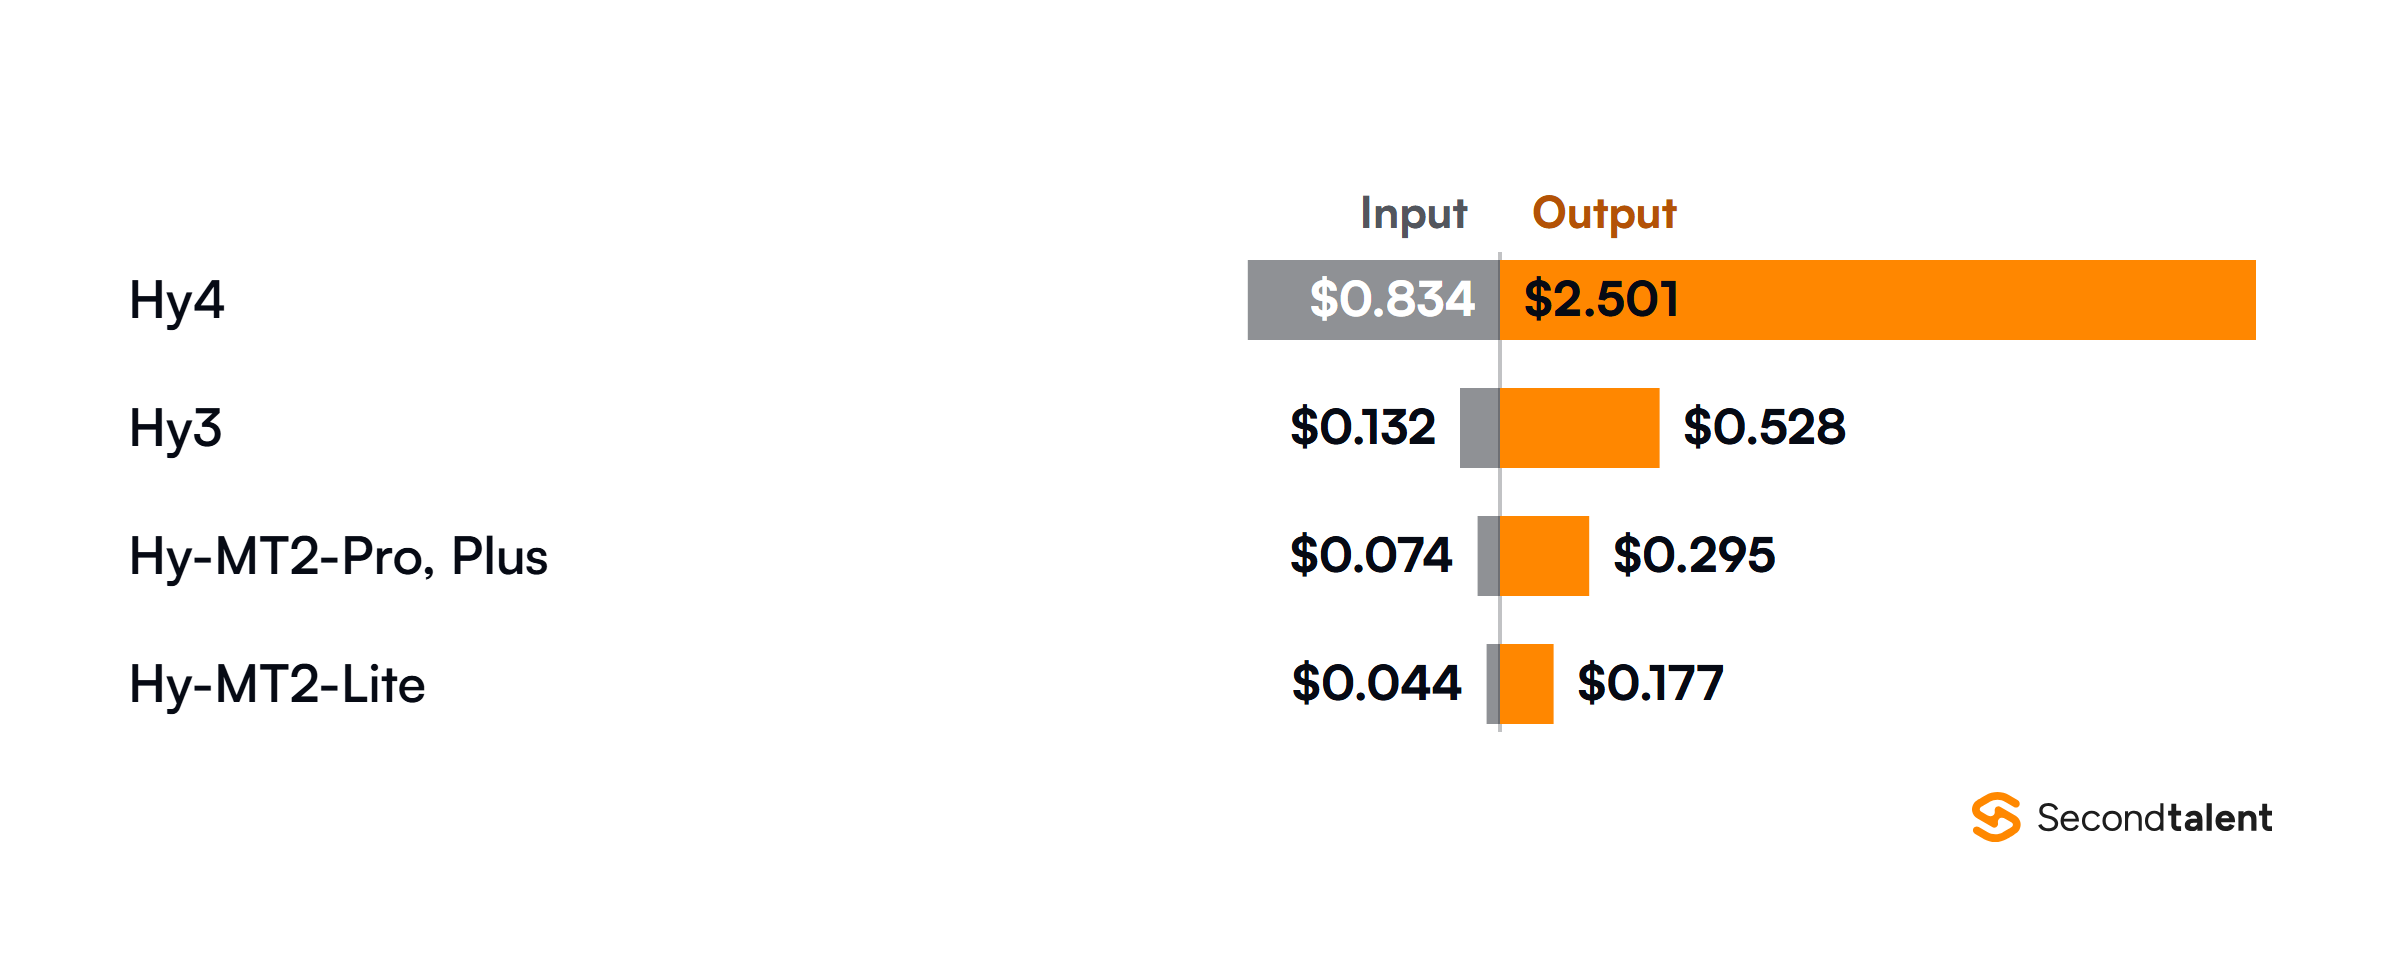
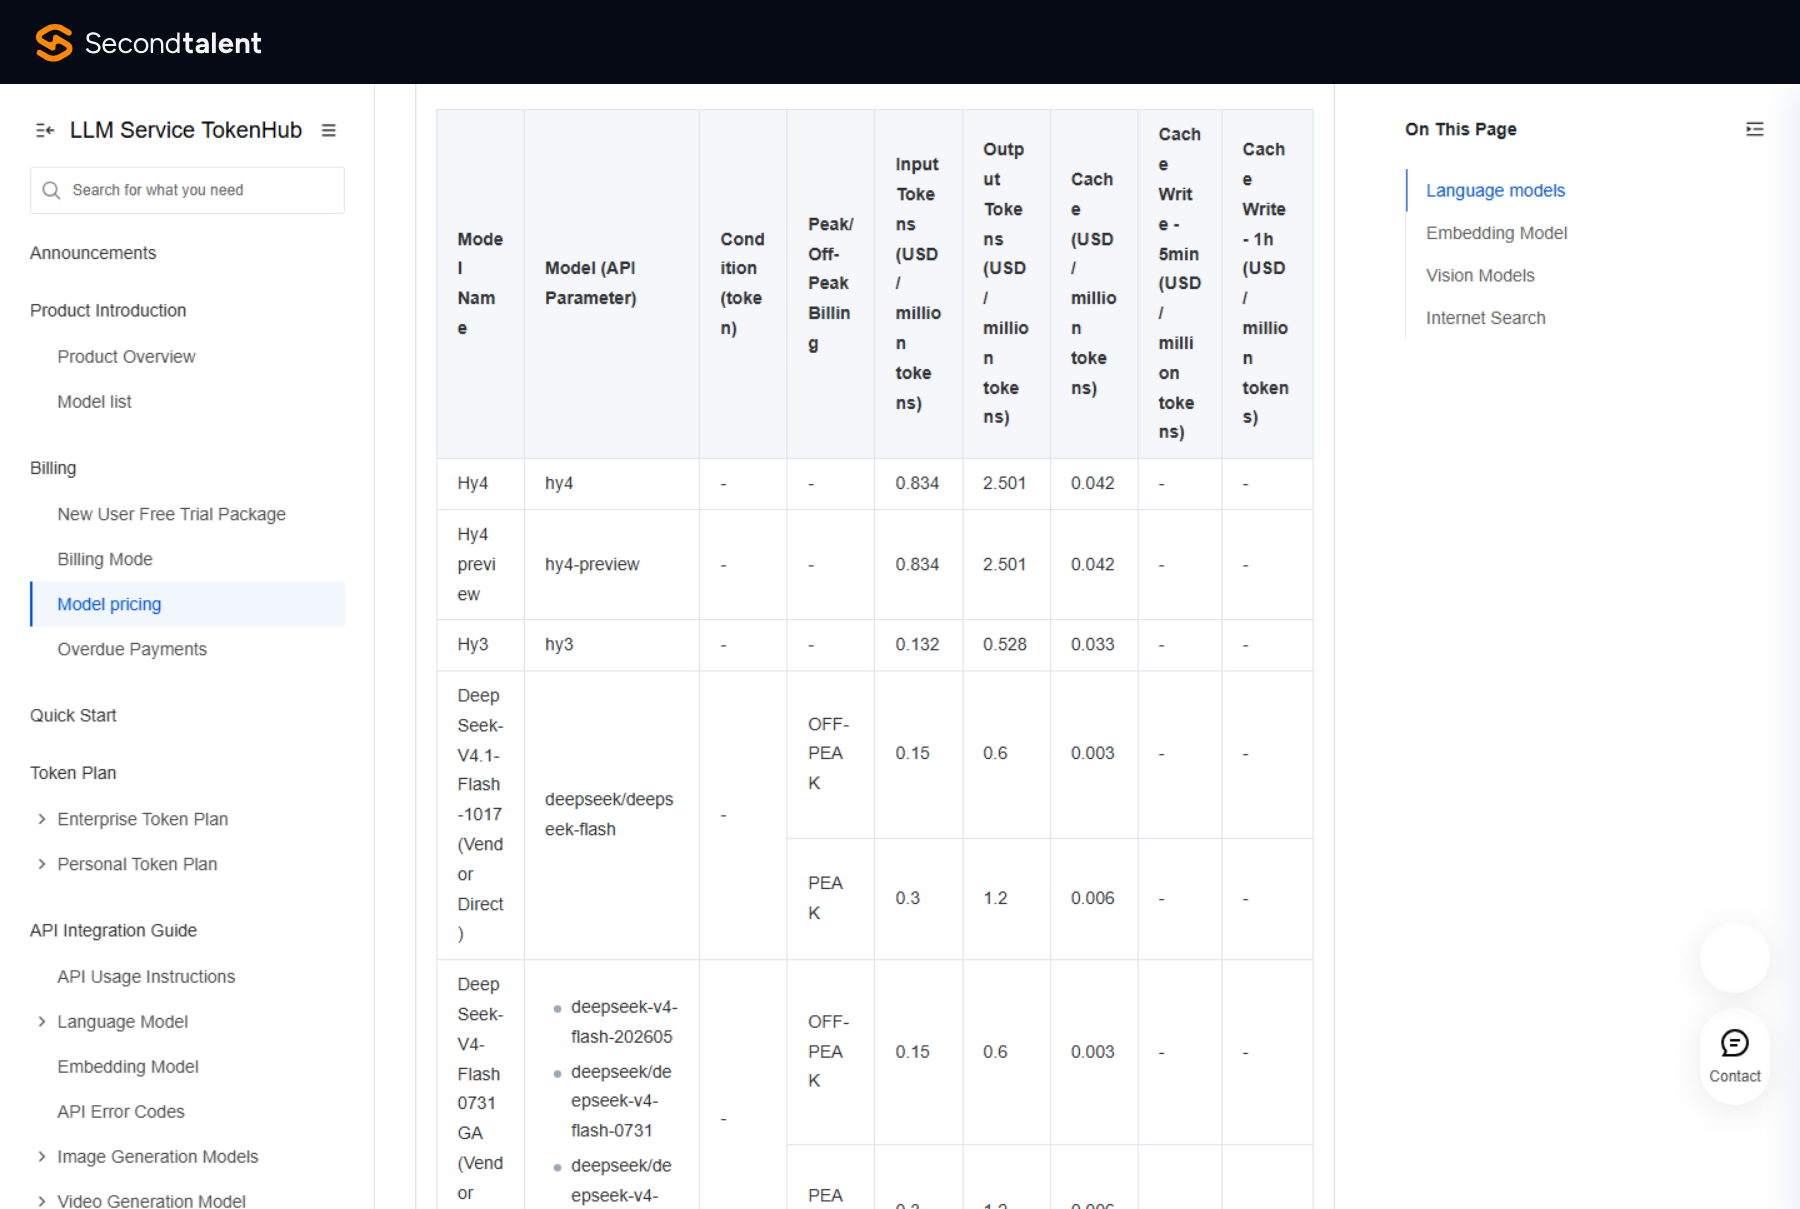
Hy4 output costs about 4.7 times Hy3 output, $2.501 against $0.528 per million tokens. That is the gap that decides most routing. Tencent lists these prices in US dollars on its international site, so this page converts no currency.
Three things move the bill below list price. Cache hits cost $0.042 per million on Hy4 and $0.033 on Hy3. The Hy4 promotion halves the bill on usage until 23:59:59 Beijing time on December 31, 2026.
And the China site, which prices in yuan on the TokenHub China pricing page, lists batch inference at half the online rate:
¥6 / ¥18
Hy4 online, input / output per million tokens
¥3 / ¥9
Hy4 batch inference
¥1 / ¥4
Hy3 online
¥0.5 / ¥2
Hy3 batch inference
CNY list prices per million tokens. Source: Tencent Cloud TokenHub model pricing (China), updated November 9, 2026.
The China page also lists vision models the international page does not, such as HY-Vision-2.0-Instruct at ¥7.5 input and ¥17.5 output per million tokens.
Context windows and output limits
Hy4 reads about four times as much as Hy3 but writes half as much in one reply. Its 1M token window allows up to 960K tokens of input and 64K of output.
Hy3's 256K window allows 192K of input and 128K of output, which suits long code generation or a full report in a single call.
The Hy-MT2 tiers stop at 8K, with 4K in and 4K out, so long documents need to be split before translation.
The open checkpoints match the API. The Hy4 preview card lists a 1M context length and the Hy3 card lists 256K. Serving the full window yourself costs GPU memory, which is where most self-hosting budgets go wrong.
Thinking and reasoning modes
Hy3 and Hy4 preview ship with opposite defaults. On a self-hosted Hy3, the reasoning_effort setting defaults to no_think and you raise it to low or high for math, code and planning.
Hy4 preview defaults to high, deep chain of thought, and you pass no_think to get a direct answer. Tencent recommends a temperature of 0.9 and top_p of 1.0 for both.
On TokenHub, Hy4, Hy4 preview and Hy3 all list deep reasoning with preserved thinking, plus structured output, function calling and caching.
A reasoning answer is longer than a direct one, so a Hy4 call left at high effort produces more output tokens. Given Tencent's own note that Hy4 preview over-reasons, set the effort per route instead of leaving the default.
Which model should you use
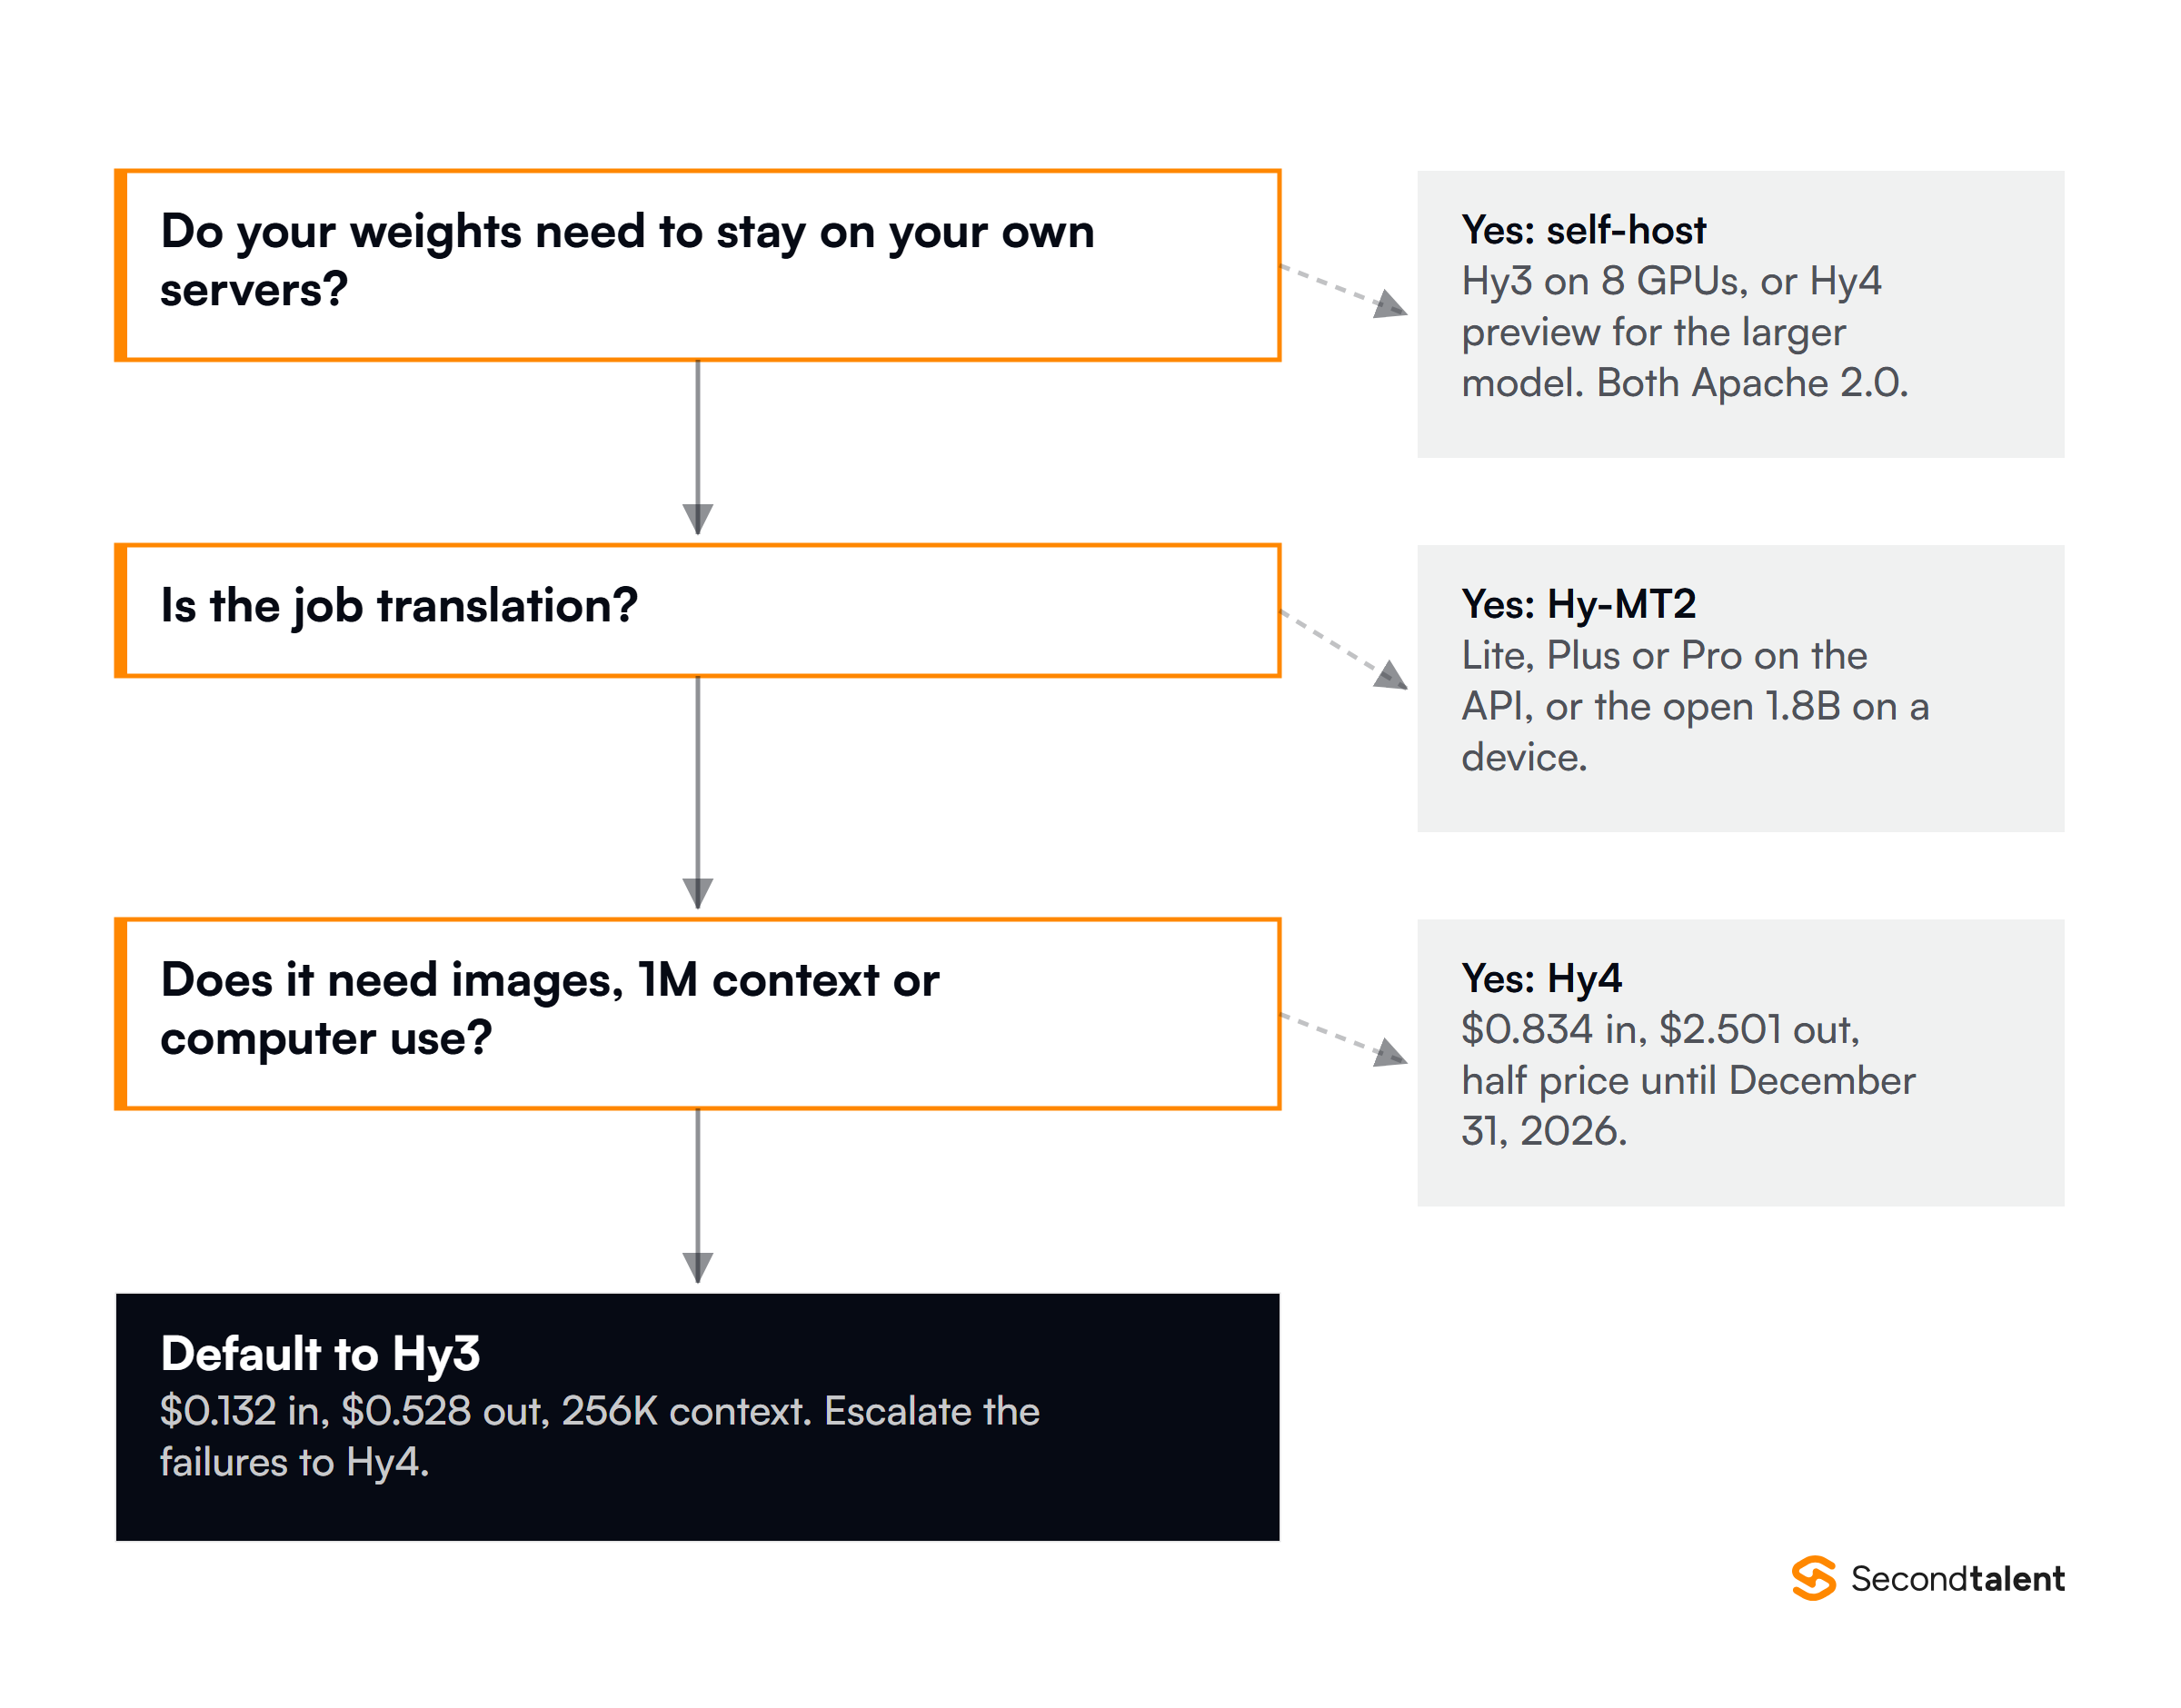
If I were starting a new build on Hunyuan today, I would put Hy3 first. It costs a fifth of Hy4 on output, writes longer replies, and has open weights you can move in-house later.
Send work up to Hy4 when a task needs images, more than 192K tokens of input or computer use.
Job
Recommended model
Why
Support chat, tagging, extraction
Hy3, thinking off
$0.528 output per million, fast with no_think
Daily coding and code review
Hy3
Beat GLM-5.1 in Tencent's blind expert test, 128K output
Long contracts or a whole codebase
Hy4
Up to 960K tokens of input
Screenshots, charts, browser agents
Hy4
Image input and computer use on the API
Translation at volume
Hy-MT2-Lite or Plus
From $0.177 output, 33 languages
Private data, EU users, self-hosting
Hy3 open weights
Apache 2.0, no territory clause
Product images
Hy-Image 3.5 preview
$0.024 an image at 1K or 2K
Measure before you escalate. Run a sample of real requests on Hy3, check the answers, and send only the failures to Hy4. While the Hy4 promotion lasts the gap is smaller, so test both now and plan your budget on the January list prices.
Legacy and retired models
Tencent moved Hunyuan off its first cloud platform this year.
The international notice stopped sales of the old Tencent HY Large Model service on June 30, 2026 and shut its console and API on September 30, 2026, with TokenHub as the replacement.
The China legacy price page still lists models such as hunyuan-a13b at ¥0.5 input and ¥2 output, but says new model work happens on TokenHub.
The next date to watch is hy4-preview, which the decommission notice retires at 00:00 Beijing time on December 7, 2026.
Tencent switches pay-as-you-go users to hy4 only if they already have pay-as-you-go billing on Hy4, and Token Plan users only when they call with a Token Plan key. Other callers get errors.
Older model
Status
Move to
hy4-preview (API)
Retires December 7, 2026
hy4
Hy3 preview
Weights still downloadable, superseded
Hy3
hy-image-v3 (API)
Offline November 12, 2026
hy-image-v3.5-preview
Legacy Tencent HY Large Model API (international)
Shut September 30, 2026
TokenHub: hy3, hy4
Hunyuan-A13B (80B total, 13B active)
Open weights, community license, superseded
Hy3
Hunyuan-Large, Hunyuan 0.5B to 7B dense
Open weights, superseded
Hy3, Hy-MT2-1.8B for small devices
Hunyuan-MT-7B, HY-MT1.5
Open weights, superseded
Hy-MT2
Most moves are a model ID change. The two that bite are the default thinking mode, which is off on the open Hy3 checkpoint and high on Hy4 preview, and the max output cap, which halves from Hy3 to Hy4.
Re-test any route that produces long replies before you switch it.
What this means for hiring
With Hunyuan, the engineering work sits in three places: routing between Hy3 and Hy4, setting reasoning effort per route, and serving a 295B MoE model on your own GPUs if data has to stay in-house.
Senior AI engineers who can do that cost $12,000 to $18,000 a month, all in, in the United States. Pre-vetted engineers in Vietnam or the Philippines with the same skills often cost $3,000 to $6,000.
Hunyuan gives you a cheap hosted workhorse in Hy3, a multimodal flagship in Hy4, and Apache 2.0 weights for Hy3 and Hy4 preview. Picking the model is quick. The routing, serving and evaluation around it is engineering work.
We match you with pre-vetted senior engineers across Asia in about 24 hours, with no upfront cost and payroll handled.
Elton Chan is the Co-Founder of Second Talent, a solution that connects global tech leaders with top-tier tech talent across Asia. He specializes in talent solutions and has led Second Talent’s rapid growth since 2024, helping scale its network to over 100,000 pre-vetted developers and earning industry recognition as the #1 in the Global Hiring category on G2.
A long-time entrepreneur with deep roots in digital transformation, Elton previously co-founded Branch8, a Y Combinator–backed e-commerce technology firm, and served as the Founding Chairman of HKEBA, a leading Asia-focused business association driving innovation, digital education, and cross-border collaboration.
His work bridges technology, talent, and business strategy to shape how companies scale in an increasingly remote and digital world.