TL;DR: The best Chinese AI models cost about a tenth as much as the best US models: GLM-5.3 lists at $4.40 per million output tokens, while Claude Fable 5.1 and GPT-6 Astra list at $50. They trail on capability, scoring 44.9 on the Artificial Analysis Intelligence Index against 53.4 for the top US model. At the budget end there is no price gap left, because OpenAI's GPT-5.6 Luna charges the same $1.20 as DeepSeek's peak rate.
The most used model on OpenRouter in the week to September 14, 2026 was American: OpenAI’s GPT-5.6 Luna, with 18.2 trillion tokens. The next five were all Chinese.
Second place went to Tencent’s Hy4 preview, a model Tencent had released as open weights at the end of August.
- 1Chinese does not always mean cheaper: Kimi K3 costs $15 per million output tokens, more than Claude Sonnet 5 at $10.
- 2NIST’s CAISI put DeepSeek V4 Pro about 8 months behind the US frontier, close to the 7-month average lag Epoch AI measured for Chinese models since 2023.
- 3Among the Chinese flagships, only DeepSeek (MIT) and Tencent’s Hy4 preview (Apache 2.0) ship under plain open licenses. GLM-5.3, Kimi K3, Qwen3.8-Max and MiniMax-M3 carry revenue or attribution clauses.
- 4Since the FY2026 NDAA, Pentagon contractors may not use DeepSeek while working on a Defense Department contract.
What US and Chinese AI Models Cost per Token
US flagships list at $5 to $10 per million input tokens and $25 to $50 per million output tokens. Chinese flagships list at $1.32 to $3 input and $3.96 to $15 output.
Below the flagships, both sides now sell models at $0.20 to $0.30 input and $1.20 output.
| Model | Lab | Input ($/1M) | Output ($/1M) | Weights |
|---|---|---|---|---|
| GPT-6 Astra | OpenAI (US) | $10.00 | $50.00 | Closed |
| Claude Fable 5.1 | Anthropic (US) | $10.00 | $50.00 | Closed |
| Claude Opus 5 | Anthropic (US) | $5.00 | $25.00 | Closed |
| GPT-5.6 Sol | OpenAI (US) | $4.00 | $20.00 | Closed |
| Kimi K3 | Moonshot AI (China) | $3.00 | $15.00 | Open, Kimi K3 License |
| Claude Sonnet 5 | Anthropic (US) | $2.00 | $10.00 | Closed |
| Qwen3.8-Max | Alibaba (China) | $2.00 | $6.00 | Open, custom license |
| Grok 4.6 | xAI (US) | $2.00 | $6.00 | Closed |
| GLM-5.3 | Z.ai (China) | $1.40 | $4.40 | Open, custom license |
| DeepSeek V4-Pro | DeepSeek (China) | $1.32 | $3.96 | Open, MIT |
| Gemini 3.8 Flash | Google (US) | $0.75 | $3.75 | Closed |
| Hy4 preview | Tencent (China) | $0.83 | $2.50 | Open, Apache 2.0 |
| DeepSeek V4.1 Flash | DeepSeek (China) | $0.30 | $1.20 | Open, MIT |
| MiniMax-M3 | MiniMax (China) | $0.30 | $1.20 | Open, community license |
| GPT-5.6 Luna | OpenAI (US) | $0.20 | $1.20 | Closed |
Prices come from each lab’s own page, read on September 15, 2026: OpenAI, Anthropic, Google, xAI, DeepSeek, Alibaba Cloud, Moonshot, Z.ai and MiniMax. Tencent’s figure is from its Hy4 launch release.
Two rows break the “China is cheap” rule. Kimi K3 costs more than Claude Sonnet 5 on both input and output. GPT-5.6 Luna undercuts DeepSeek V4.1 Flash on input, at $0.20 against $0.30, after OpenAI cut Luna’s price by 80% on July 30.
For the full lineups behind these rows, see our guides to every DeepSeek model, every Qwen model and every OpenAI model.
What the Price Gap Means on a Monthly Bill
Take a support or document pipeline that reads 100 million tokens and writes 20 million tokens a month. At list price, with no caching, that workload costs $2,000 on GPT-6 Astra and $54 on DeepSeek V4.1 Flash at peak rate.
Run the same job off-peak and the DeepSeek bill falls to $27.
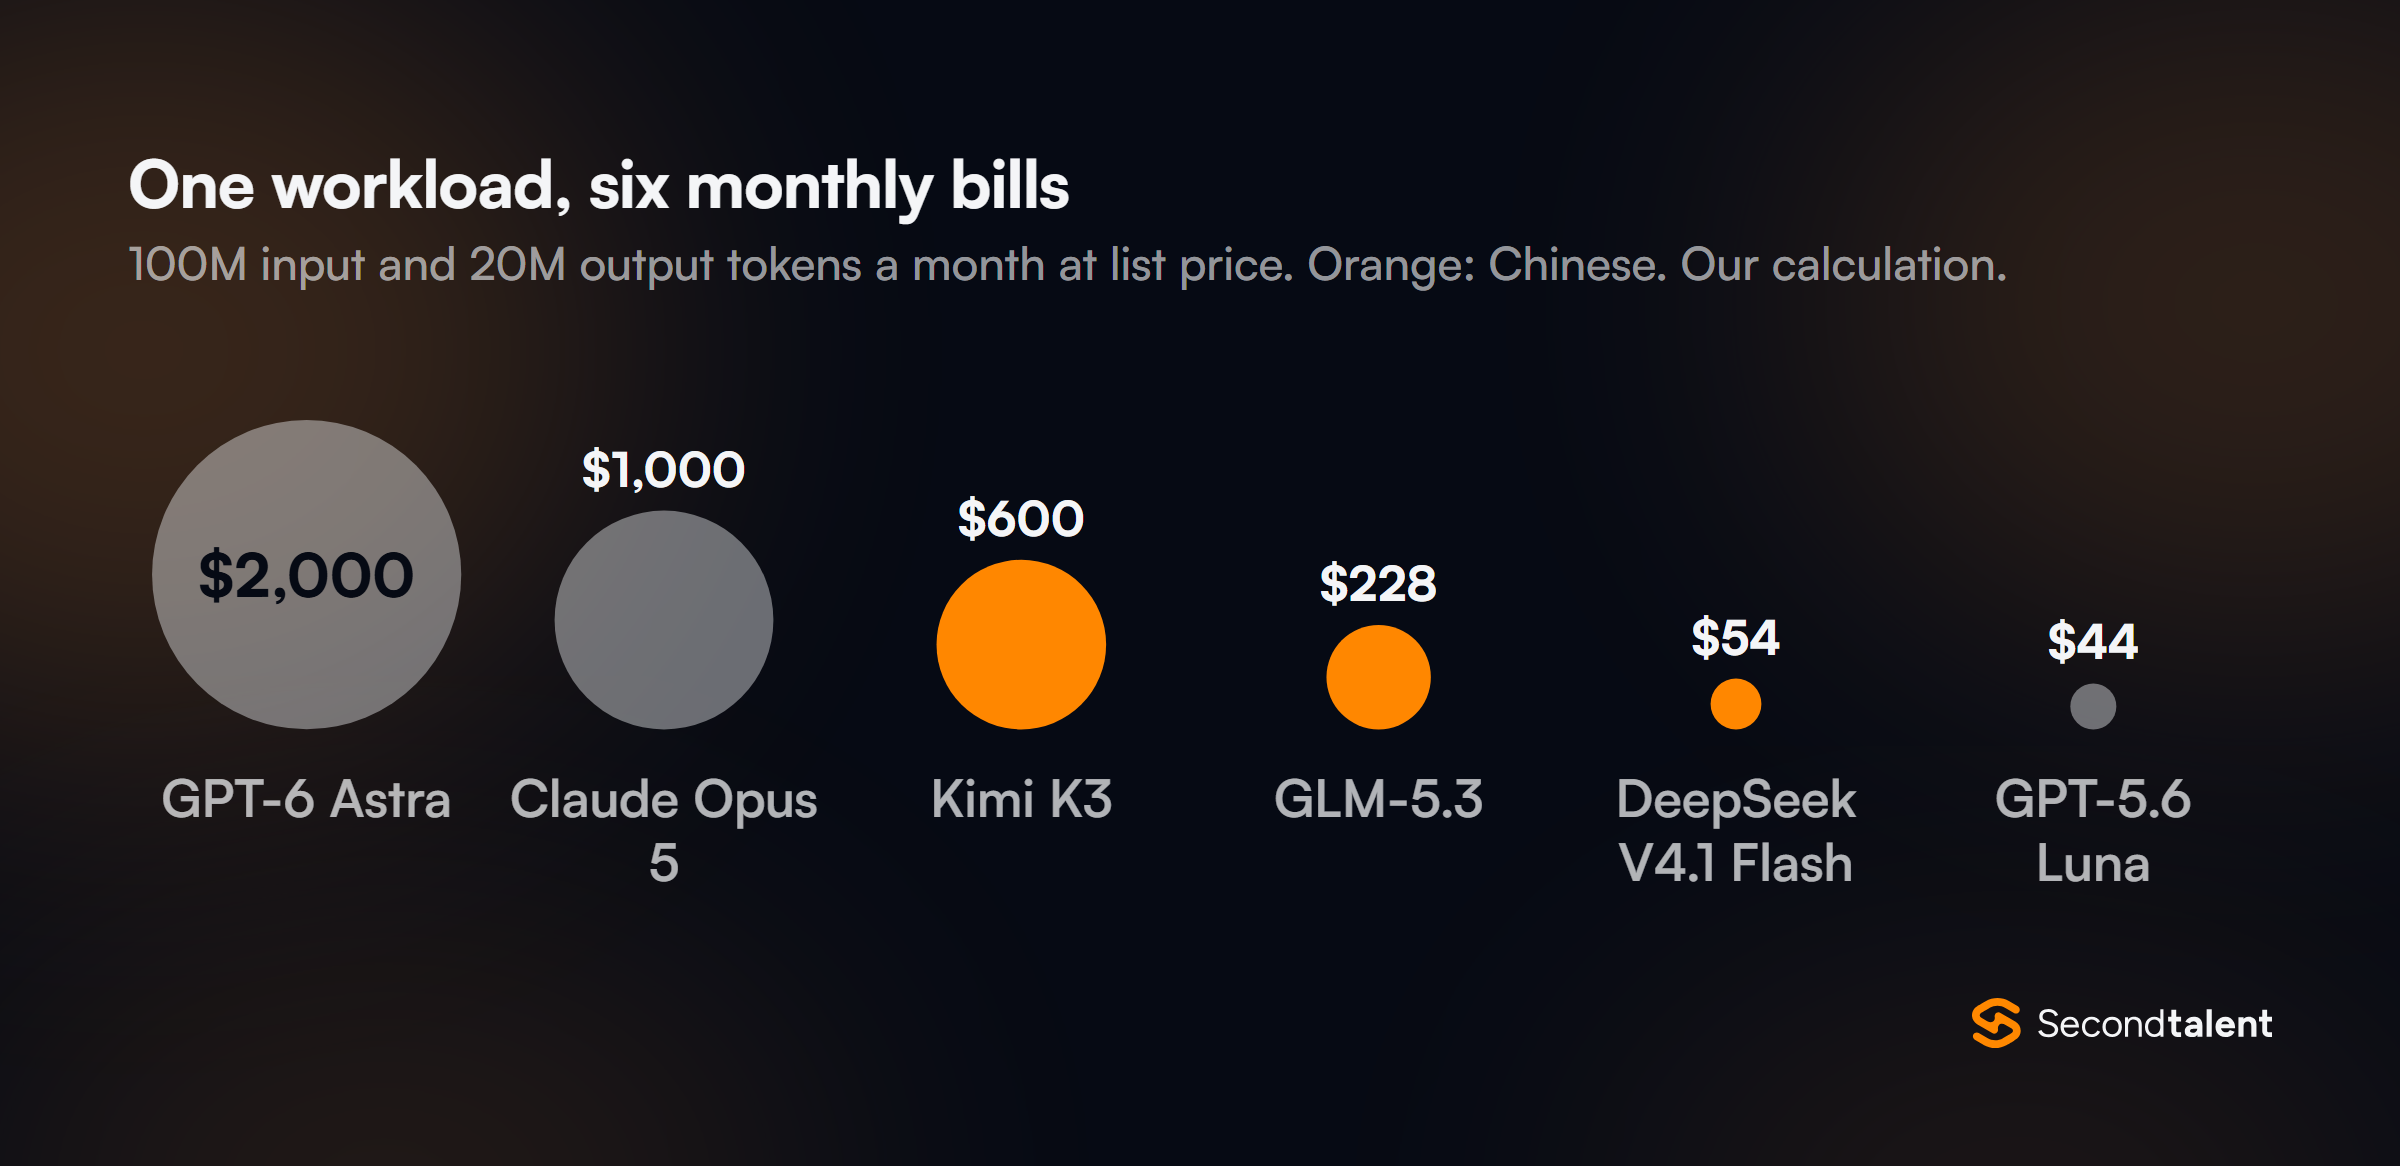
The chart shows where the real saving sits. Moving from a US flagship to a Chinese flagship takes the bill from $1,000 to $2,000 down to $228 to $600.
Moving from GPT-5.6 Luna to DeepSeek V4.1 Flash saves nothing: Luna comes in $10 cheaper, because its input price is lower.
Discounts narrow the gap. OpenAI and Anthropic both take 50% off for batch jobs that can wait, which puts GPT-6 Astra at $1,000 for this workload.
Cached input is cheap on both sides: DeepSeek V4.1 Flash charges $0.006 per million tokens on a cache hit, and Claude Fable 5.1 charges $0.25. A pipeline that resends the same long system prompt pays the cache rate on the repeated part.
Token price is also not cost per task. A model that thinks longer, or needs three attempts, spends more tokens per answer. NIST’s CAISI found that DeepSeek V4 Pro cost less than GPT-5.4 mini on 5 of 7 benchmarks.
Per task, it ranged from 53% cheaper to 41% more expensive.
How Far Behind Are Chinese AI Models?
Chinese models trail the US frontier by between 1% and 16% on today’s leaderboards, or by 7 to 8 months in time. The size depends on who is measuring and how.
Human preference votes show the smallest gap. On the Arena text leaderboard, formerly LMArena, the best Chinese entry is Kimi K3 in 17th place, 21 points behind Claude Fable 5. GLM-5.3 sits 19th and Qwen3.8-Max 22nd.
DeepSeek’s best model, V4 Pro, is 50th.
That gap has moved in both directions. Stanford HAI’s AI Index 2026 tracked the same leaderboard: DeepSeek-R1 trailed OpenAI’s o1 by 5 points in February 2025. By March 2026, Claude Opus 4.6 led ByteDance’s Dola-Seed-2.0 Preview by 39.
Graded tests show a wider gap. Artificial Analysis runs ten evaluations into one index. Claude Fable 5.1 leads at 53.4, GPT-6 Astra scores 52.8 and Claude Opus 5 50.7.
The best Chinese model, GLM-5.3, scores 44.9, followed by Kimi K3 at 43.8 and DeepSeek V4.1 Flash at 39.5.
Measured in time, the lag is steady. Epoch AI found that each model at the frontier of its capabilities index since 2023 came from the US. Chinese models trailed by 7 months on average, with a minimum of 4 and a maximum of 14.
Value: Capability per Dollar
GLM-5.3 delivers 84% of Claude Fable 5.1’s index score for about a tenth of its blended price. That makes it the strongest value case among today’s models, on our reading of the Artificial Analysis scores and list prices.
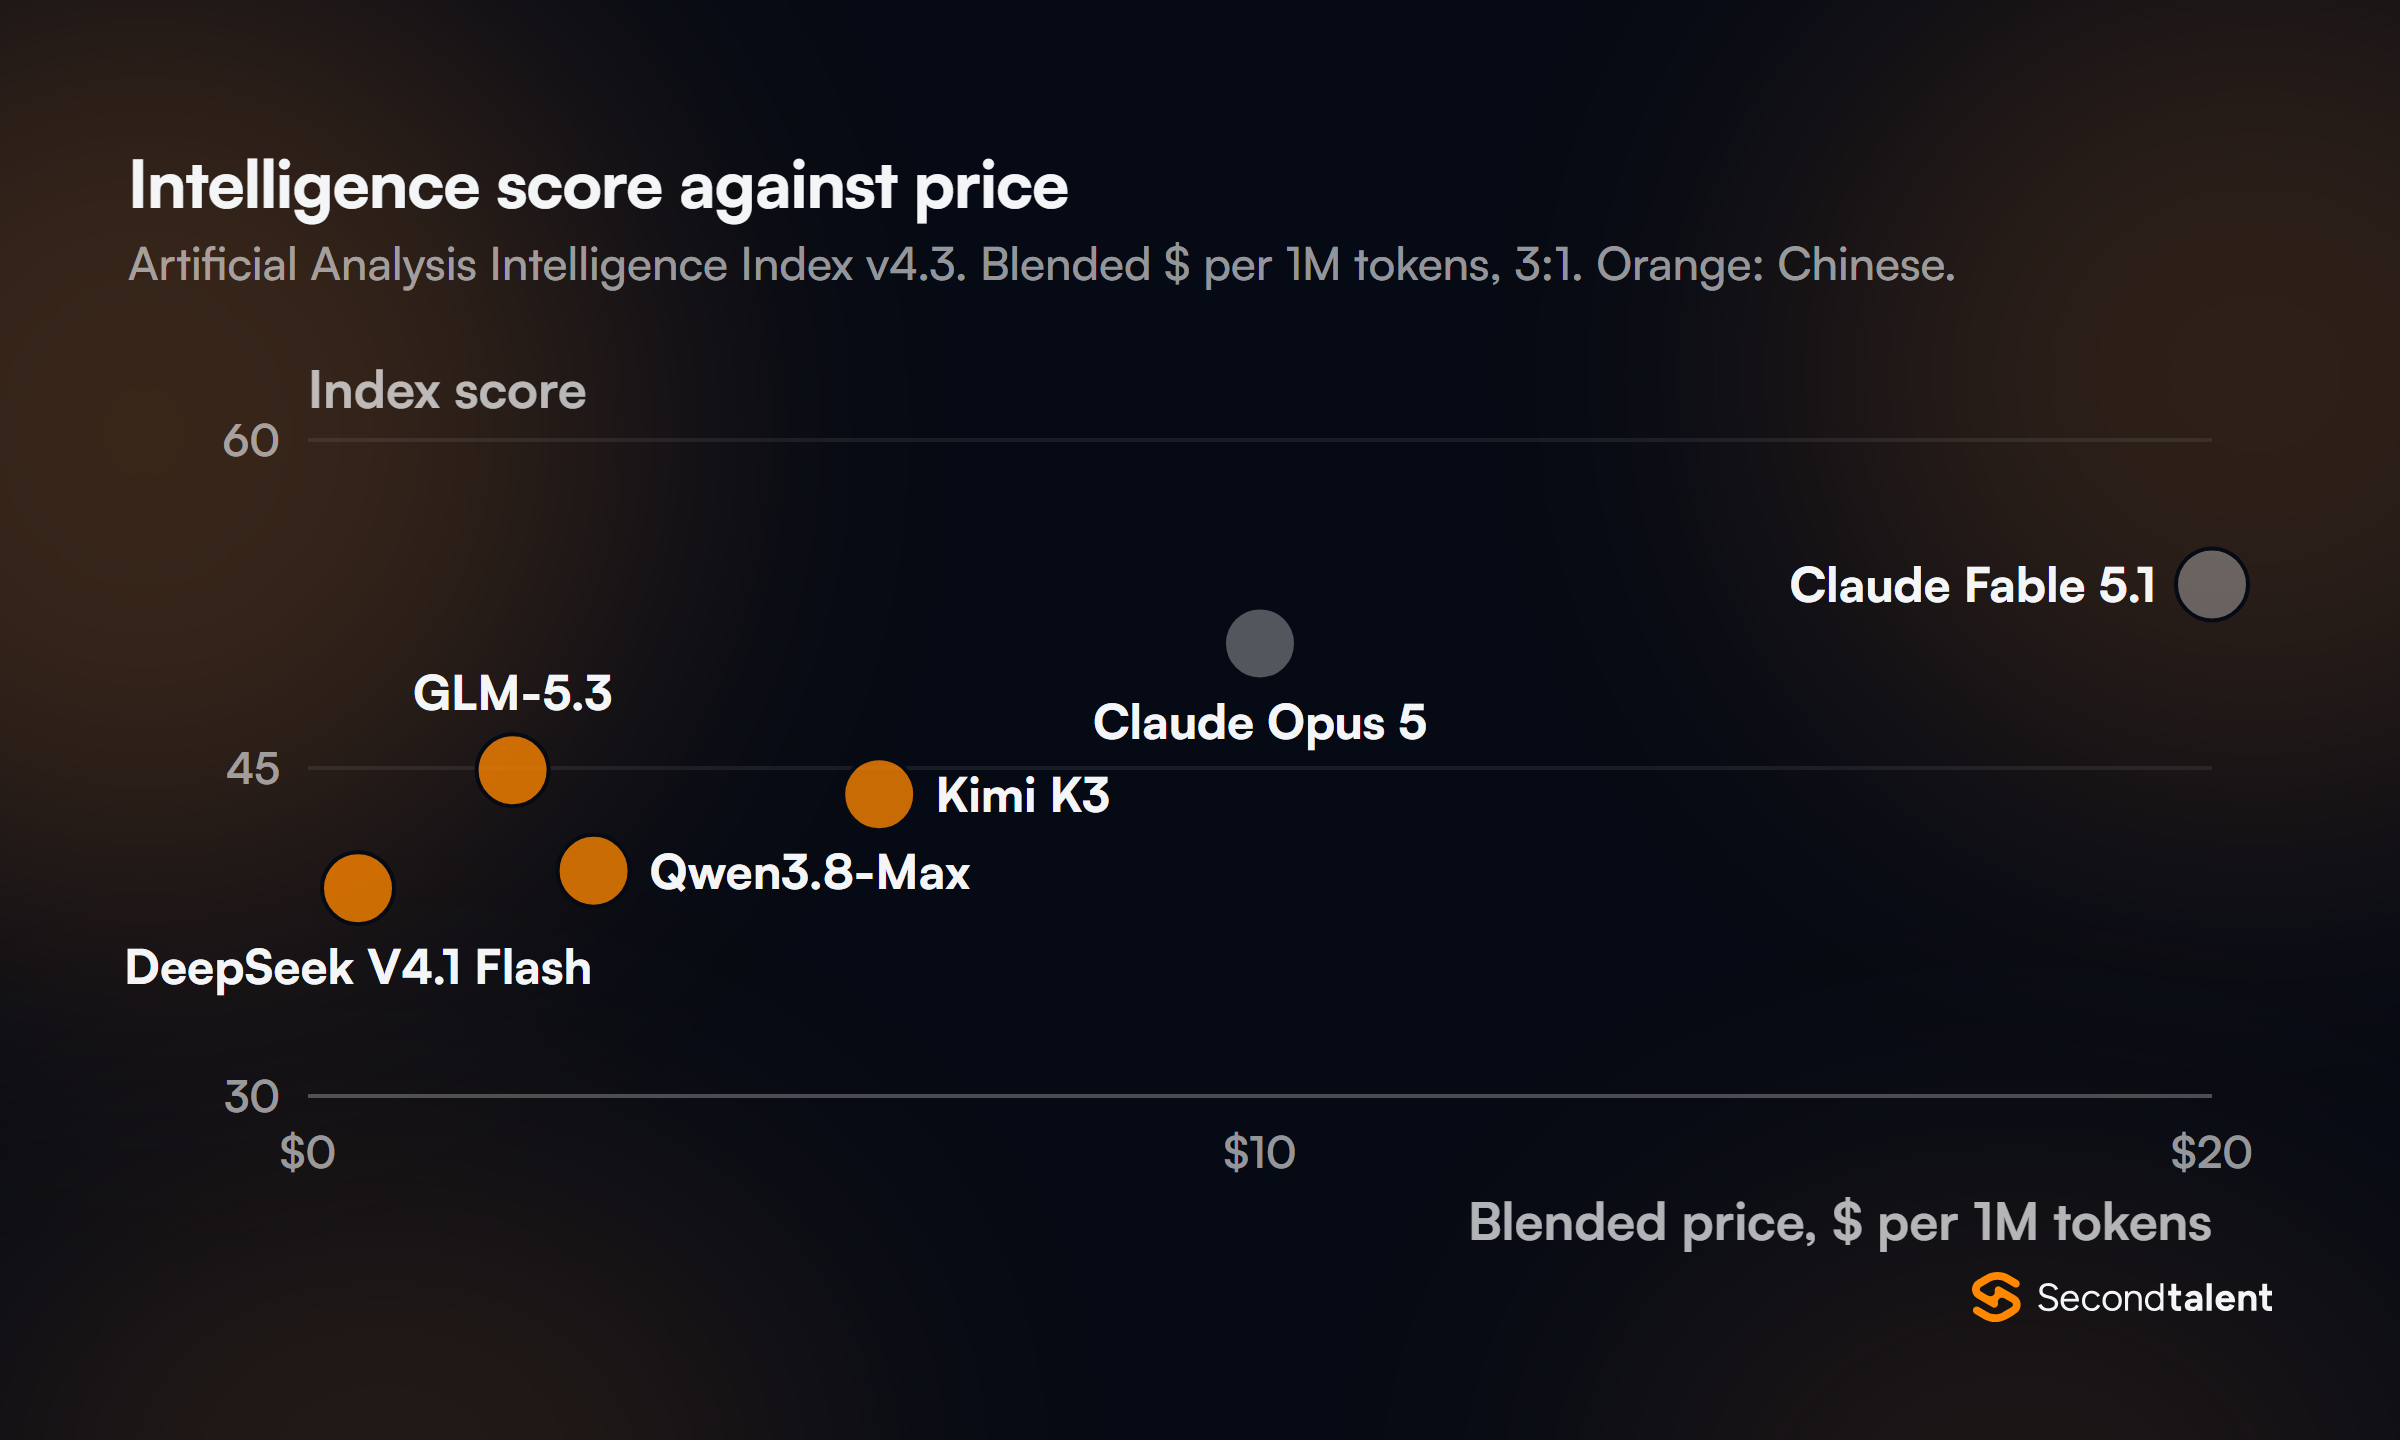
The blended price weights input and output 3 to 1, the ratio Artificial Analysis uses for its own price comparisons. On that basis Claude Fable 5.1 costs $20 per million tokens and GLM-5.3 costs $2.15.
DeepSeek V4.1 Flash scores 74% of Fable’s mark at $0.53, under 3% of the price.
The spread inside each country is as large as the gap between them. Kimi K3 is poor value next to GLM-5.3, and Claude Opus 5 gives up less than 3 points to Fable 5.1 for half the price.
A buyer choosing by flag skips both of those comparisons. Our list of the top Chinese AI companies profiles the labs behind these models.
Where US Models Still Earn the Premium
The US lead is widest on long, multi-step technical work. On one CAISI test, DeepSeek V4 Pro solved 32% of expert capture-the-flag security tasks. OpenAI’s GPT-5.5 solved 71% of the same set.
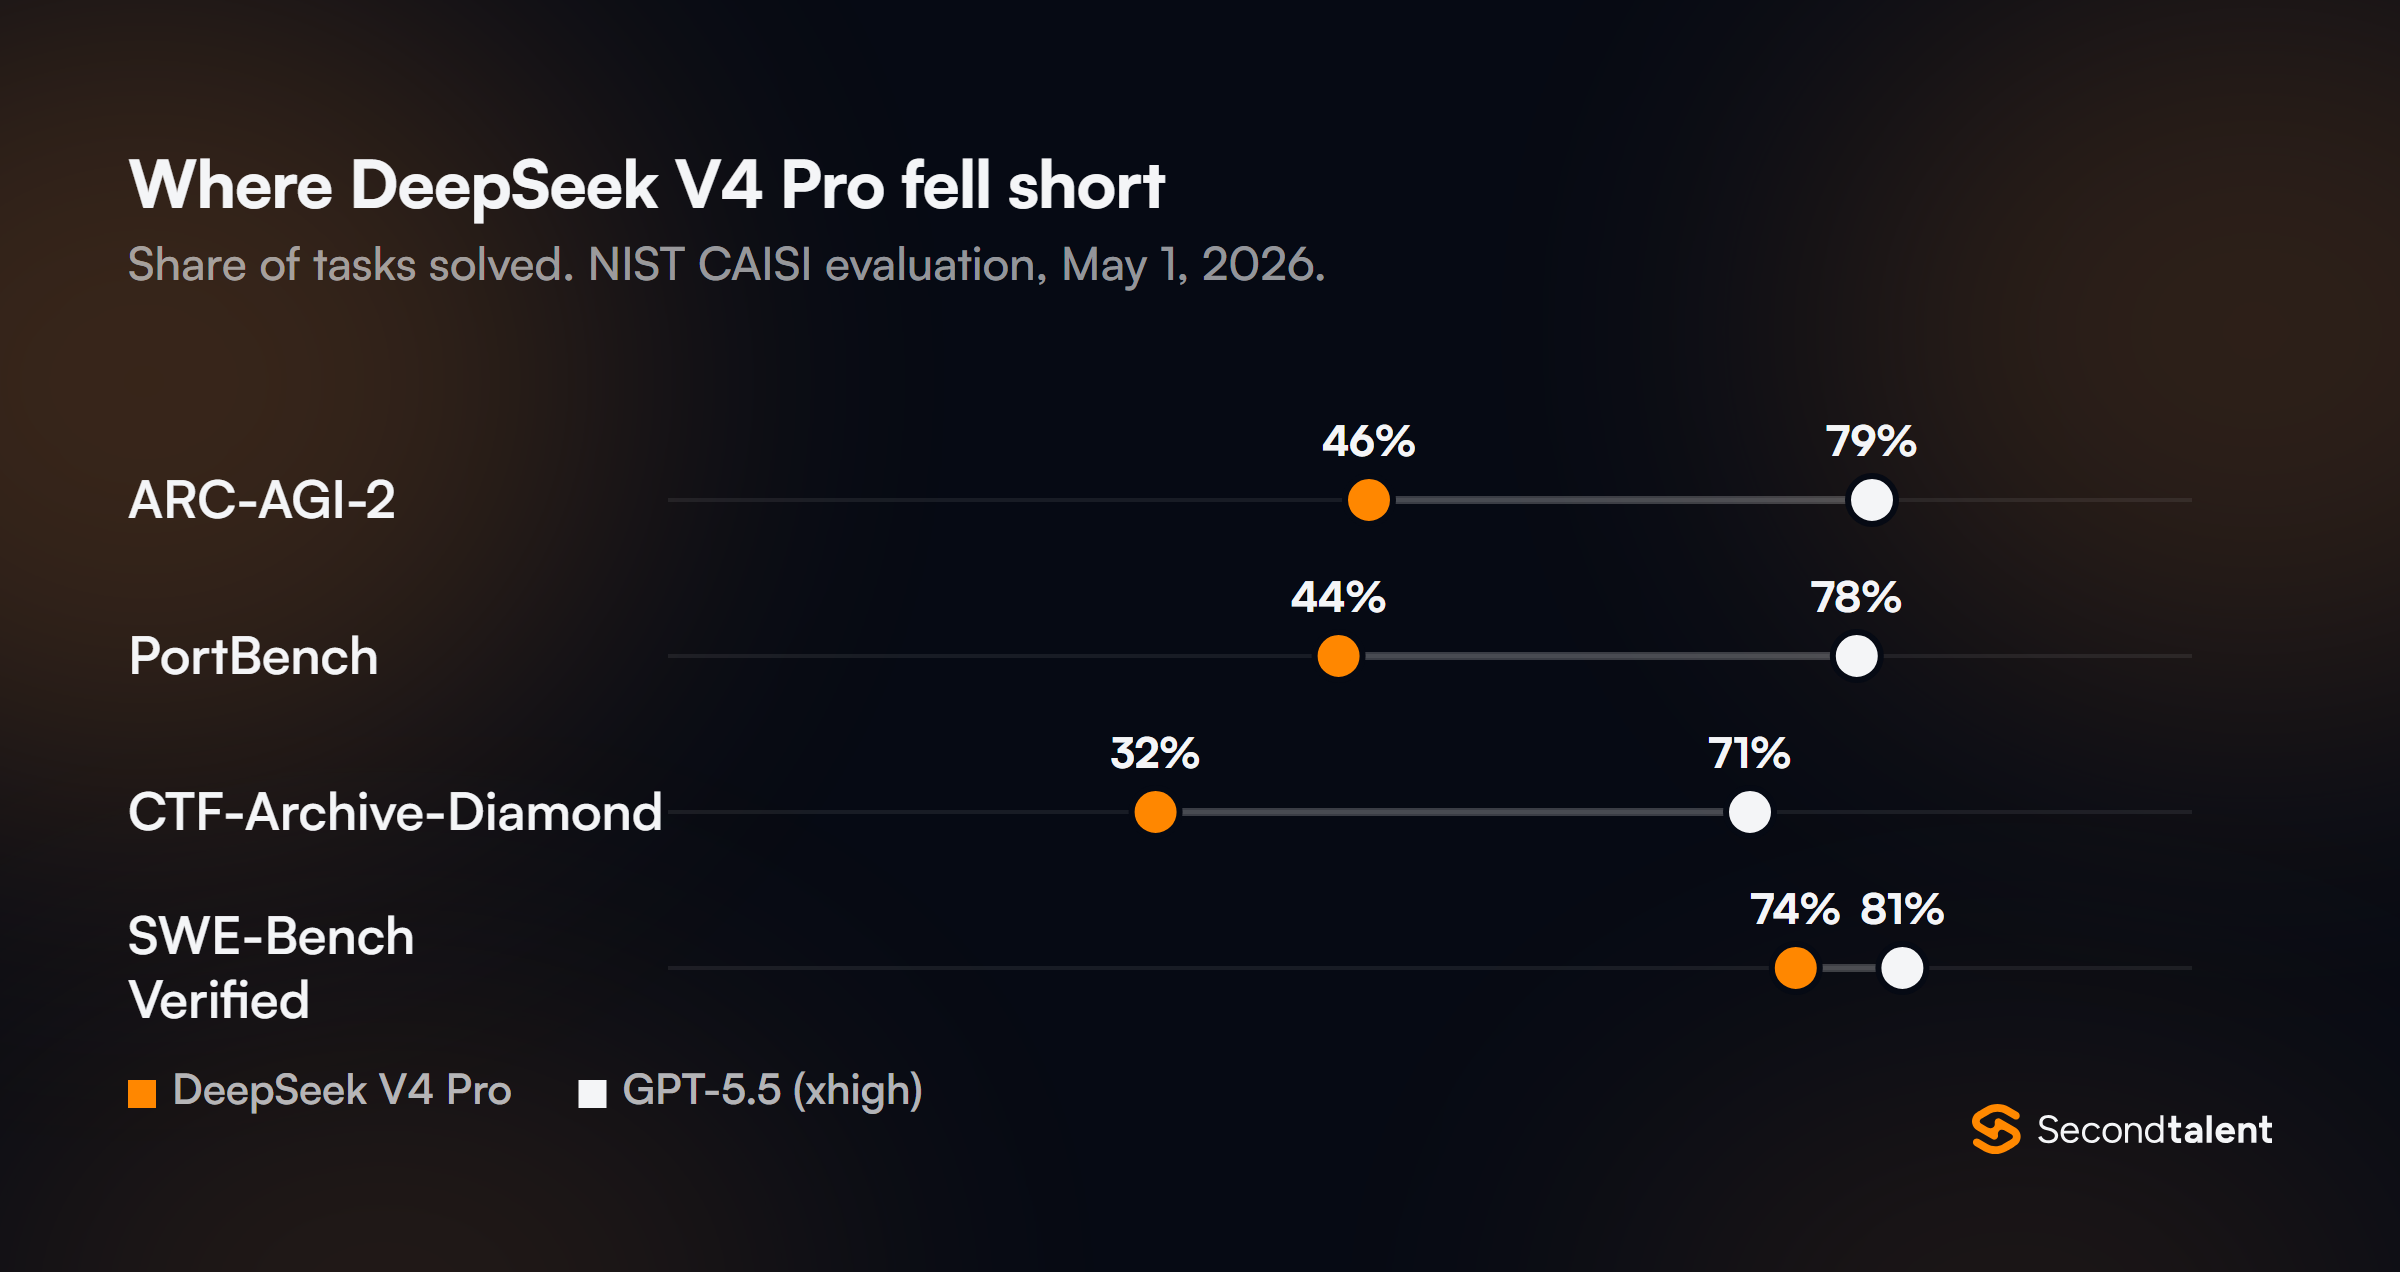
The CAISI evaluation of DeepSeek V4 Pro ran it on CAISI’s own benchmark suite rather than the tests DeepSeek chose. DeepSeek’s own launch data had claimed parity with Claude Opus 4.6 and GPT-5.4.
CAISI instead placed it near GPT-5, about 8 months behind. The closest result was on SWE-Bench Verified, a coding test, at 74% against 81%.
Newer Chinese models show the same pattern on agentic work. In a joint test by the UK AI Security Institute and CAISI, Kimi K3 reached step 17 of a 32-step simulated attack. The most capable US models reached 28.5 steps on average.
CAISI rated Z.ai’s GLM-5.2 as similar overall to GPT-5.2, a model OpenAI released in December 2025.
For work that fails without an error message, such as an agent editing a codebase for an hour, that gap decides the bill more than the token price.
Our comparison of Claude Fable, Opus and Sonnet covers where each US tier stops paying for itself.
Open Weights and What the Licenses Allow
China leads open weights by a wide margin. On the Artificial Analysis index, the best US open-weights model, Thinking Machines’ Inkling Small, scores 26.1. Four Chinese open-weights models score 39.5 or higher.
Downloads tell the same story. Hugging Face’s summer 2026 report on open models counts 151,448 models on its Hub derived from Qwen, 2.6 times Meta’s total.
On the US side, OpenAI’s gpt-oss models (August 2025), Google’s Gemma 4 and Meta’s 30B Muse Glimmer all use Apache 2.0. None of them is a frontier model.
“Open” no longer means “no strings” for the Chinese flagships. The license files on Hugging Face split them into two groups:
- DeepSeek V4.1 Flash and V4-Pro: MIT
- Tencent Hy4 preview: Apache 2.0
- GLM-5.3-Flash and Qwen3.8-27B: MIT and Apache 2.0, the smaller siblings
- Kimi K3: separate agreement for model-as-a-service revenue above $20M in 12 months
- Qwen3.8-Max: separate license for AI service businesses above $50M a year
- GLM-5.3: Z.ai security review for services above $10B in revenue
- MiniMax-M3: non-commercial grant; commercial use needs attribution, and written approval above $20M a year
For most companies using a model inside their own product, only the MiniMax terms bite. The revenue clauses target firms that resell the model as a hosted service. Our roundup of Chinese open-source LLMs covers the smaller releases.
Who Has Switched, and the Scrutiny That Followed
Chinese labs’ models took 68% of the tokens across OpenRouter’s 20 busiest models in the week to September 14. Twelve of the 20 came from Chinese labs, seven of them from DeepSeek and Z.ai.
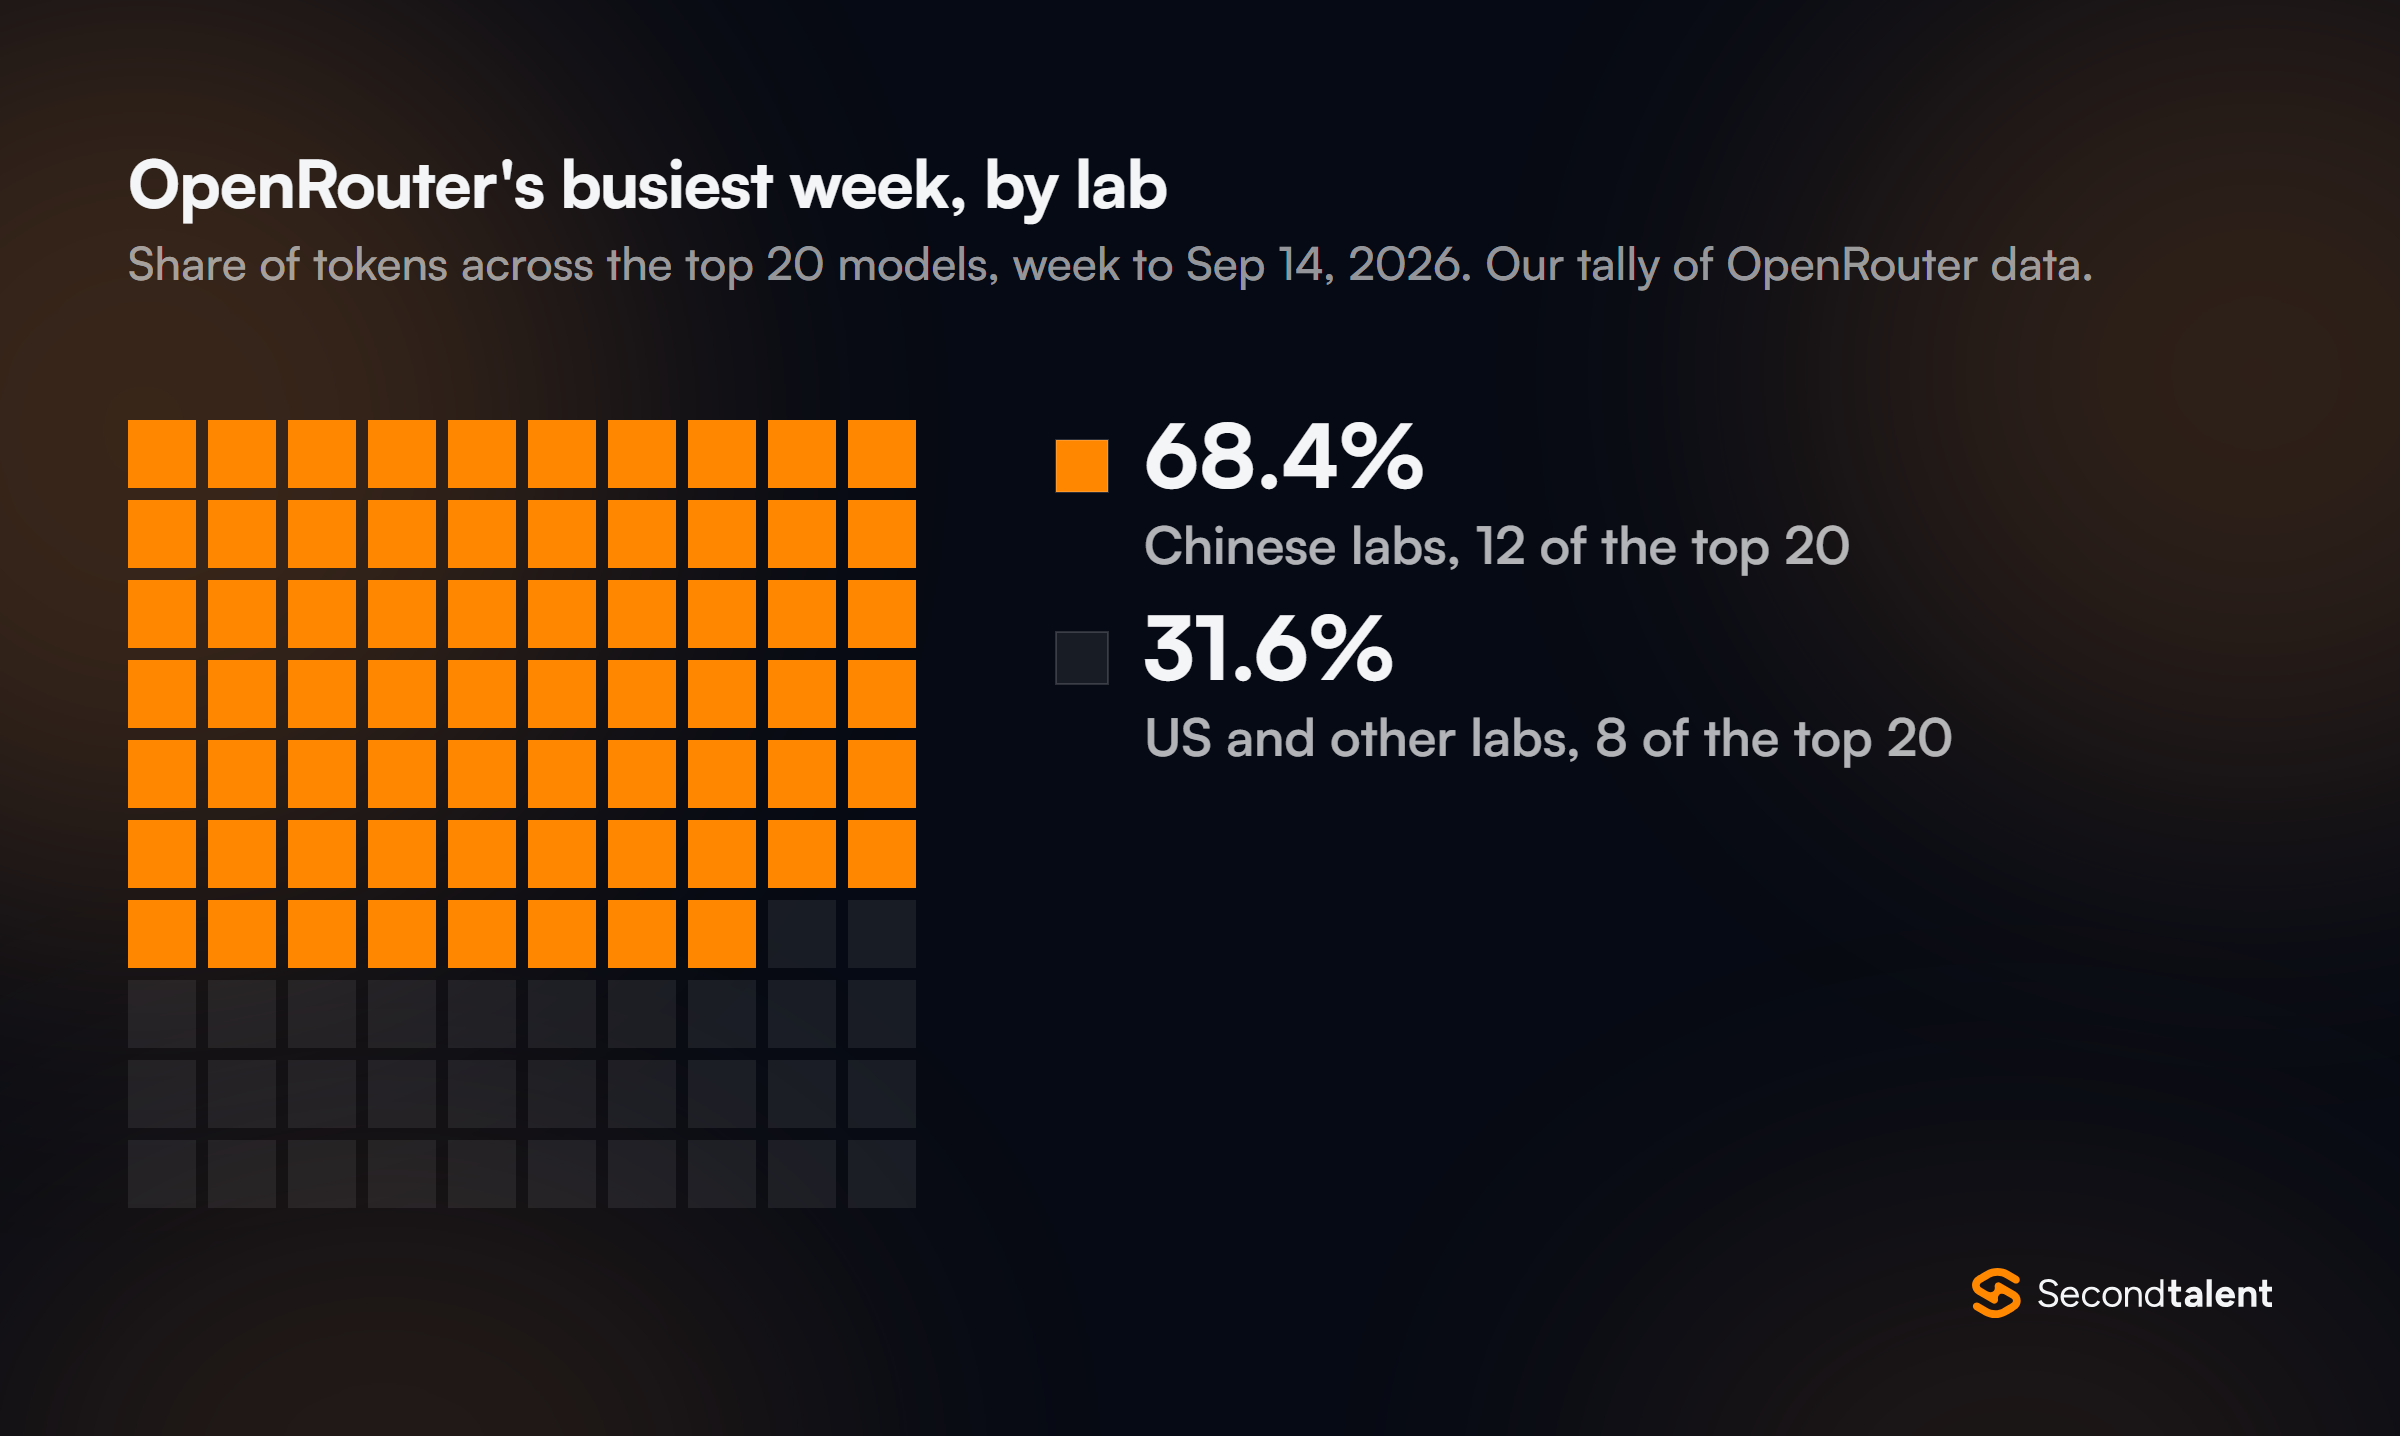
The share is our tally of OpenRouter’s weekly rankings, and it describes one marketplace. OpenRouter users can change models without signing a new vendor contract, so its rankings likely react to price faster than enterprise spending does.
Its own State of AI study with a16z put Chinese open models at 13% of weekly tokens on average through 2025.
Two well-known US companies built on Chinese models in public, and both drew a congressional inquiry.
Airbnb. In October 2025, chief executive Brian Chesky said Airbnb “relies heavily” on Alibaba’s Qwen for its customer service agent, calling it “fast and cheap”, SCMP reported. After the House inquiry, he gave a different account:
“We’re primarily using a variety of open-source models, including U.S. open-source models.”
Brian Chesky, via Bloomberg News, May 20, 2026
Cursor. Anysphere’s Composer 2 coding model started from Moonshot’s open Kimi K2.5.
The launch post did not name the base, and co-founder Aman Sanger later said “It was a miss to not mention the Kimi base in our blog from the start”, TechCrunch reported.
On April 29, 2026, two House committees opened a joint investigation into both companies.
The committees’ release said Chinese models reportedly ran about 1% of global AI workloads in late 2024 and about 30% by the end of 2025, without naming a source.
Legal and Security Risks of Chinese AI Models
Using a Chinese lab’s API and running its open weights carry different risks. An API call sends your data to the lab.
DeepSeek’s privacy policy says it will “directly collect, process and store your Personal Data in People’s Republic of China.”
Self-hosted weights keep the data on your own servers, but the model behaves the same wherever it runs.
In CAISI’s 2025 evaluation, DeepSeek R1-0528 answered 94% of overtly malicious requests under a common jailbreak, against 8% for US reference models.
The DeepSeek models also repeated four times as many misleading Chinese Communist Party narratives.
The main restrictions so far, in order:
The NDAA section is the one that reaches private companies. Section 1532 of the FY2026 act bars Defense Department contractors from using DeepSeek while they perform a DoD contract, with waivers case by case.
The FY2027 version would add “any derivative AI models”, Covington’s government contracts team notes. That wording would catch a fine-tune built on Qwen or Kimi.
The state bans cover government devices and agencies. Texas’s list applies to state agencies and state-issued devices.
Australia’s government direction against DeepSeek goes further in one detail: it exempts open-source models deployed locally on a government system. That line separates the lab’s service from its weights.
How to Split Work Between US and Chinese Models
Two questions settle most routing decisions: can the data leave your network, and what does a wrong answer cost? The answers put each workload in one of four boxes.
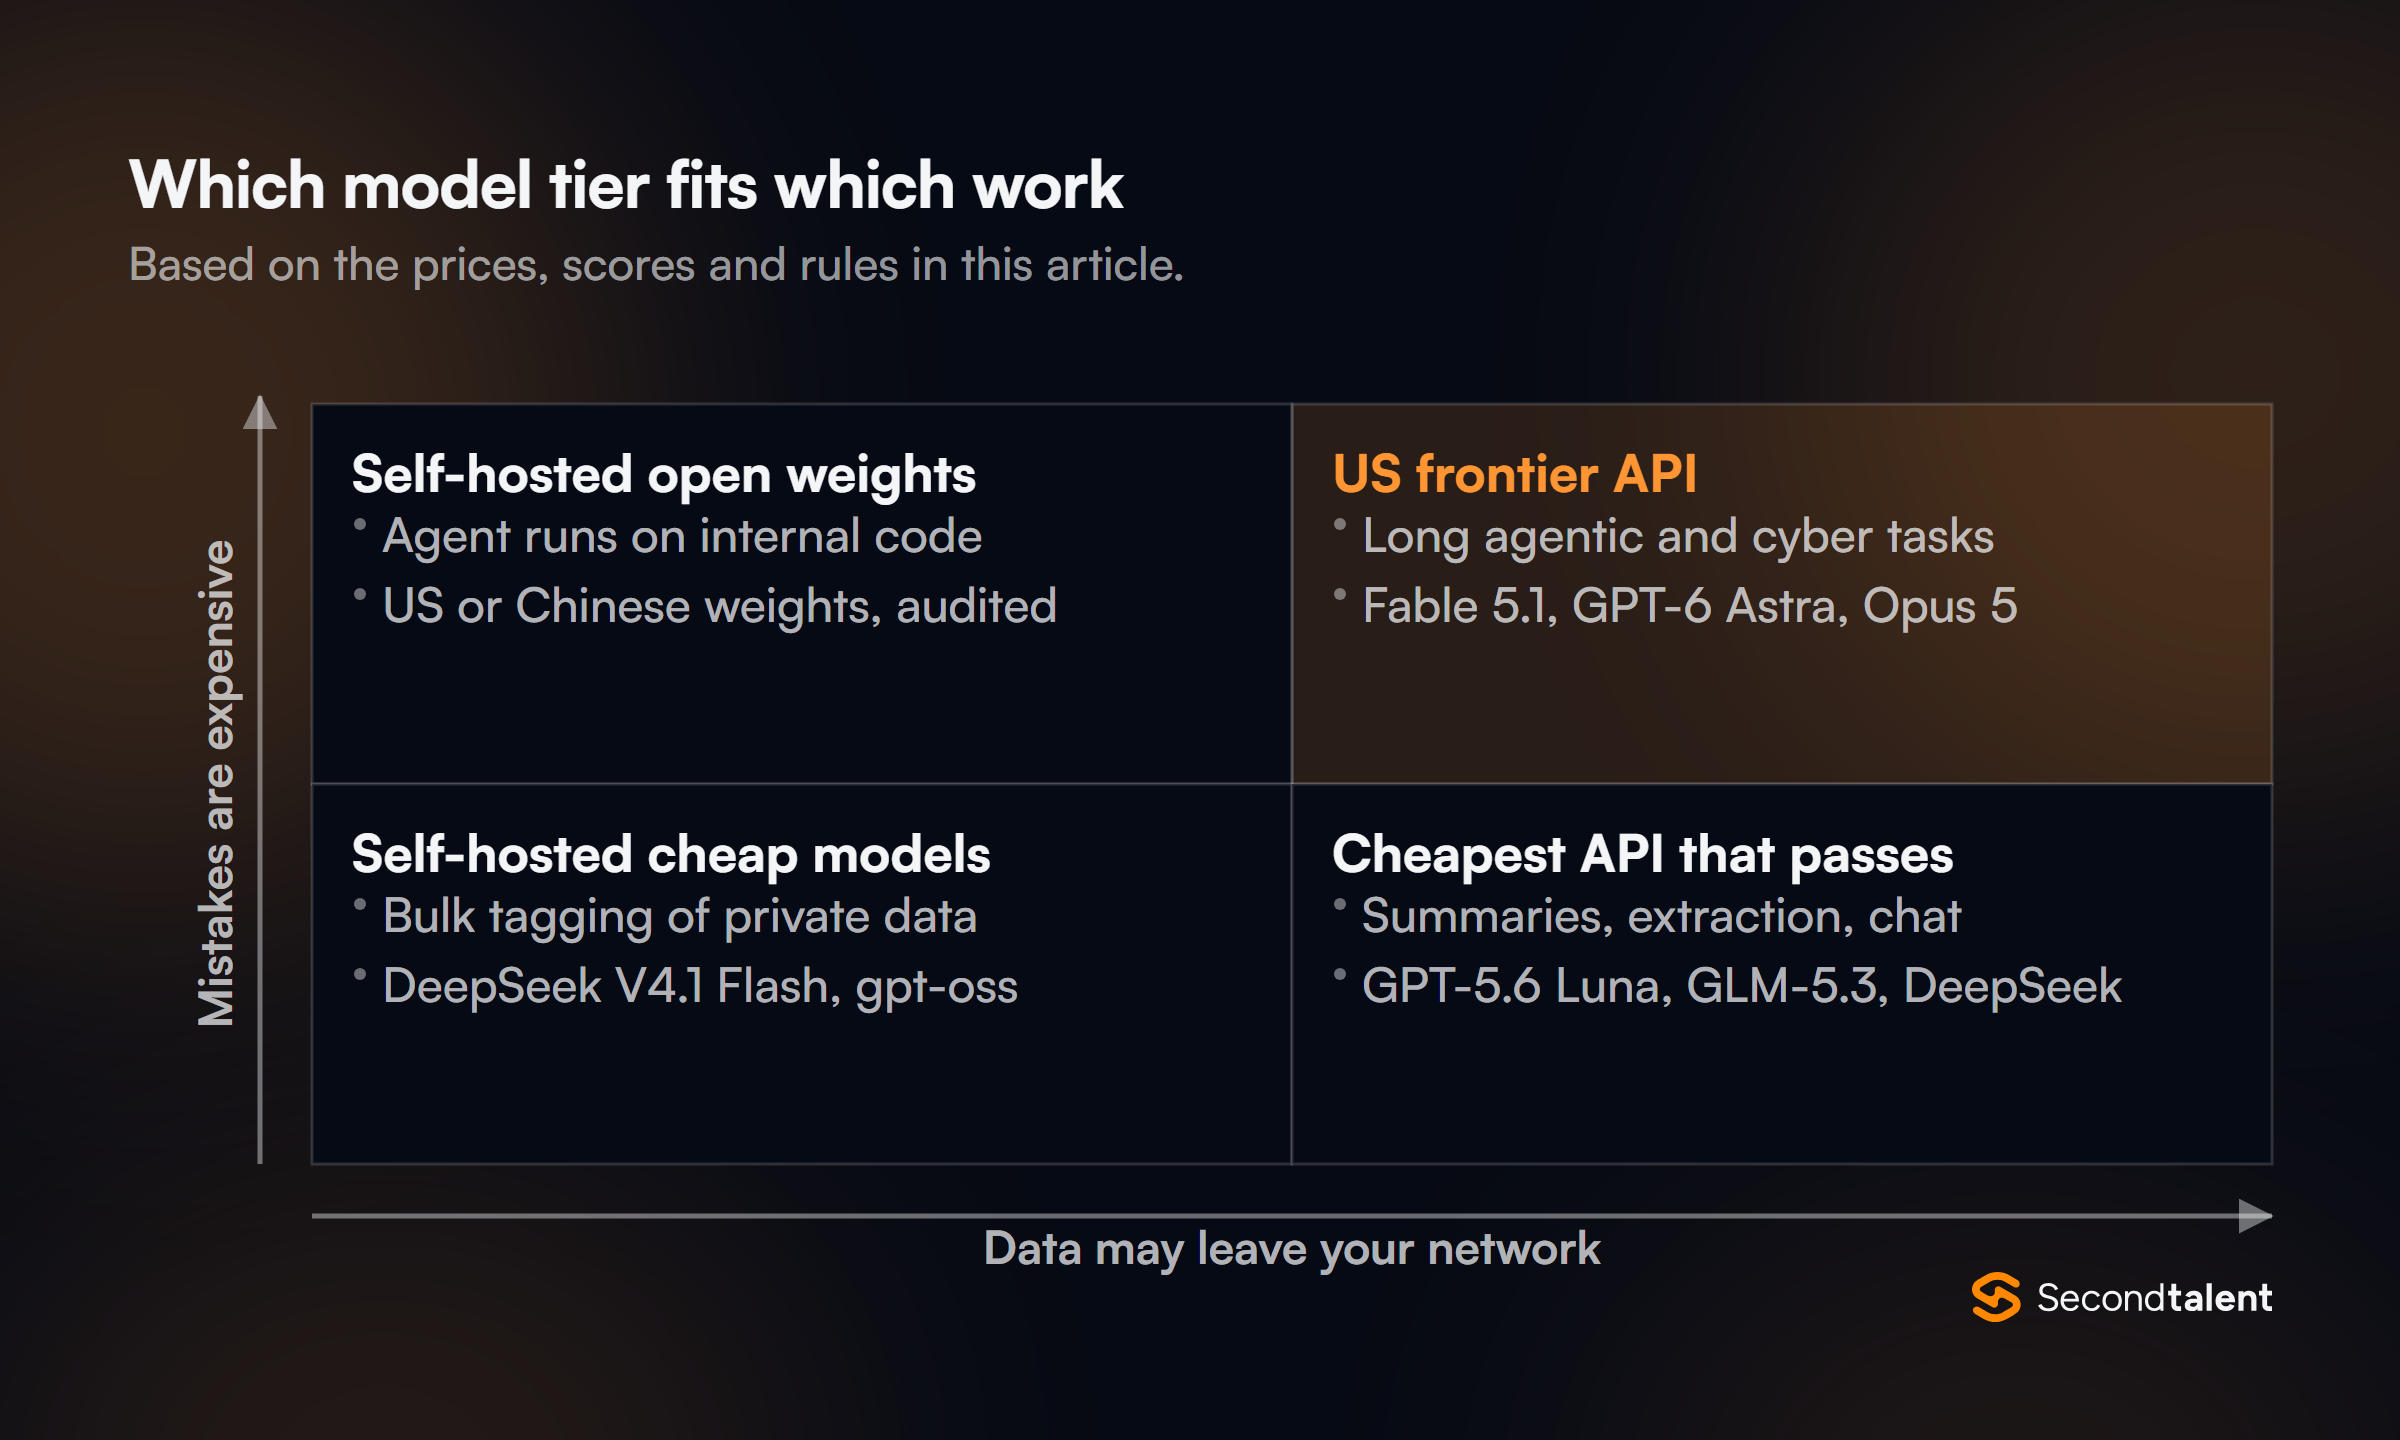
- Check contracts first. A DoD contract rules out DeepSeek today, and a pending bill may rule out derived models. Government customers in Texas and other states have their own lists.
- Price the workload, not the token. Run 200 real prompts through two or three candidates and record tokens used per correct answer.
- Start at the cheap end. GPT-5.6 Luna, DeepSeek V4.1 Flash and GLM-5.3 cost $1.20 to $4.40 per million output tokens. Move up only where they fail your test set.
- Keep the frontier for long agent runs. Claude Opus 5 at $25 output is half the price of Fable 5.1 and scores within 3 points.
- Self-host where the data is sensitive. MIT and Apache 2.0 weights avoid both the data transfer and the license clauses.
Since late July, OpenAI cut Luna’s price by 80%, DeepSeek added peak pricing and Anthropic canceled a planned Sonnet 5 increase. Gemini 3.8 Flash doubles in January.
A routing layer that lets you switch models without a rewrite is worth more than any one pick. More ways companies are cutting AI spend are in our corporate AI cost-cutting trends, and the country-level picture is in USA vs China in AI.
Engineers Who Can Run a Mixed-Model Stack
Routing between a US API and self-hosted Chinese weights is an engineering job: evaluation sets, inference serving, caching and a license review. Second Talent matches companies with vetted engineers from Asia who build this.
You can hire LLM engineers or machine learning engineers to set up serving and routing. AI model training specialists can build the evaluation set.
Tell us the role you need to fill and get a shortlist within 24 hours.
Frequently Asked Questions
Which Chinese AI model is the best in 2026?
It depends on the test. Z.ai’s GLM-5.3 has the highest Artificial Analysis index score of any Chinese model, at 44.9. Moonshot’s Kimi K3 ranks highest on Arena’s human-preference leaderboard, in 17th place overall.
Is DeepSeek cheaper than OpenAI?
Against OpenAI’s flagship, yes: DeepSeek V4.1 Flash output costs $1.20 per million tokens at peak, against $50 for GPT-6 Astra. Against OpenAI’s budget model, no. GPT-5.6 Luna matches that output price and charges less for input.
Can a US company use Chinese AI models?
For most private companies, yes. Defense Department contractors may not use DeepSeek on DoD work, and several states ban Chinese AI on government devices. The broader federal bills, such as the No Adversarial AI Act, have not passed.
Check your customer contracts as well as the law.
Does self-hosting a Chinese model remove the risk?
It removes the data transfer, not the model’s behavior. CAISI found weaker jailbreak resistance in DeepSeek models and censorship in Kimi K2 Thinking’s Chinese-language answers.
Test a self-hosted model on your own prompts before it touches production.