TL;DR: Claude is still the better coding model in October 2026: Sonnet 5.5 scores 70.6% and Opus 5.5 66.4% on Terminal-Bench 4.0, against 57.4% for Google's new Gemini 4 Argon. Gemini 3.8 Flash, the Gemini most developers can call today, costs $0.75 in and $3.75 out per million tokens and runs about twice as fast as any Claude model. Pick Claude for hard agentic work and Gemini Flash for cheap, fast, high-volume calls.
Google's own launch table for Gemini 4 Argon shows it beating Claude Opus 5.5 on two agentic coding benchmarks and losing on the other two, and Argon is only open to a group of cyber defenders for now.
Five frontier models shipped between September 1 and September 30, so comparisons written over the summer, including the first version of this one, now name the wrong models.
I rebuilt it from the launch posts, the price sheets and Artificial Analysis's independent runs.
- 1Gemini 4 Argon is not on the public API yet; Google is rolling it out to trusted cyber defenders first.
- 2Gemini 3.8 Flash's price doubles on January 1, 2027, to $1.50 in and $7.50 out.
- 3Per finished task, Opus 5.5 costs about five times what Gemini 3.8 Flash costs, for a 17-point higher score on the Artificial Analysis index.
- 4Every Claude model except Haiku writes up to 128K tokens in one reply; Gemini 3.8 Flash stops at 65,536.
Which Writes Better Code in October 2026?
Claude, for work where an agent has to plan, run commands and land a working change.
Anthropic's two newest models hold the top two Terminal-Bench 4.0 scores that any lab has published, and Claude Opus 5.5 leads the Artificial Analysis leaderboard at 58, five points ahead of Gemini 4 Argon.
Gemini wins on price and speed. Gemini 3.8 Flash costs less than a fifth of Opus 5.5 per input token, reads video and audio, and is the model Google itself recommends for "long-horizon software engineering" on its developer docs.
| Model | Price per 1M tokens (in / out) | Context / max output | Terminal-Bench 4.0 | Can you use it today? |
|---|---|---|---|---|
| Claude Opus 5.5 | $4 / $20 | 1M / 128K | 66.4% | Yes, all platforms |
| Claude Sonnet 5.5 | $2 / $10 | 1M / 128K | 70.6% | Yes |
| Claude Fable 5.1 | $10 / $50 | 1M / 128K | 55.8% | Yes |
| Gemini 4 Argon | $2 / $10 intro, then $4 / $20 | 1M / not published | 57.4% | Limited preview |
| Gemini 3.8 Flash | $0.75 / $3.75 to Dec 31, then $1.50 / $7.50 | 1M / 65,536 | 19.1% | Yes |
Scores are each lab's own figures; the next section explains why they are not directly comparable.
Coding Benchmarks: What Each Lab Reports
SWE-bench Verified, the benchmark the first version of this post leaned on, has dropped out of the launch tables.
Anthropic and Google now both report Terminal-Bench 4.0, which grades an agent on long, multi-step tasks run inside a real terminal.
Terminal-Bench 4.0
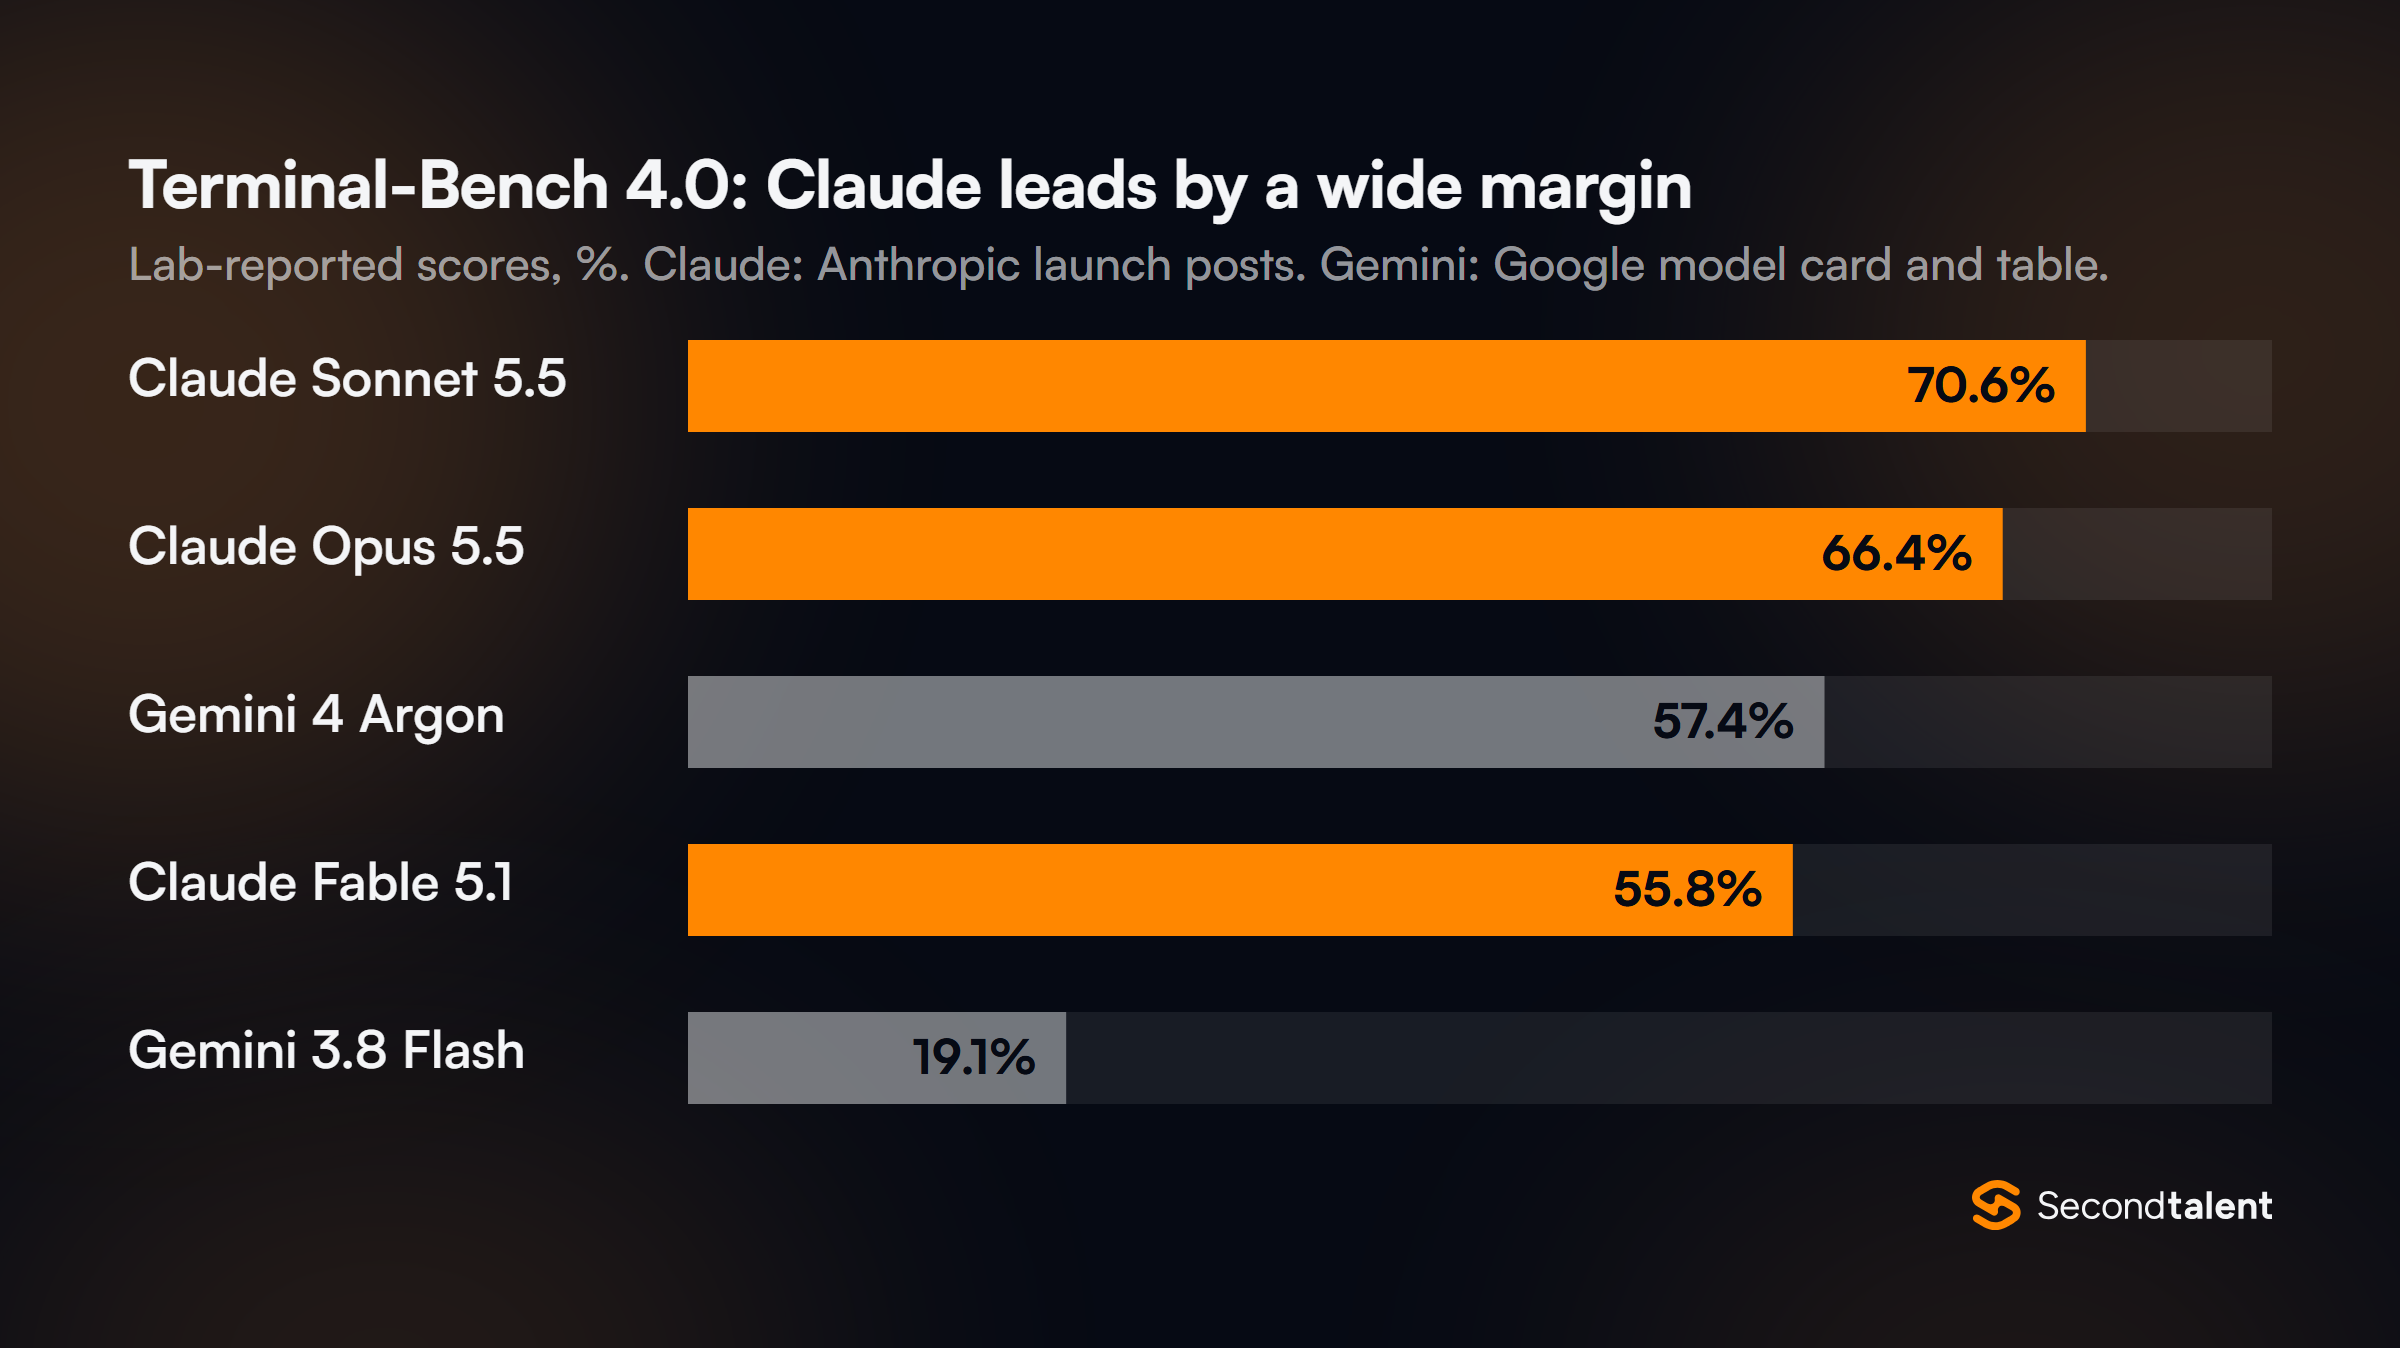
The surprise is Sonnet 5.5 beating Opus 5.5. Anthropic's Sonnet 5.5 launch post puts it at 70.6%, up from 10.3% for Sonnet 5, at half of Opus's price.
Opus 5.5 still leads Sonnet on FrontierCode (54.4% to 46.2%) and CursorBench 4.0 (57.8% to 55.5%), so the gap depends on the benchmark you trust.
Gemini 3.8 Flash's 19.1% comes from Google's own model card, which prints Claude Opus 5 at 51.8% in the same table. On the older Terminal-bench 2.1, the same card has 3.8 Flash at 89.4%, slightly ahead of Opus 5.
The newer test is the one built around long, messy tasks, and that is where the Flash model falls away.
Google's table: Argon against Opus 5.5
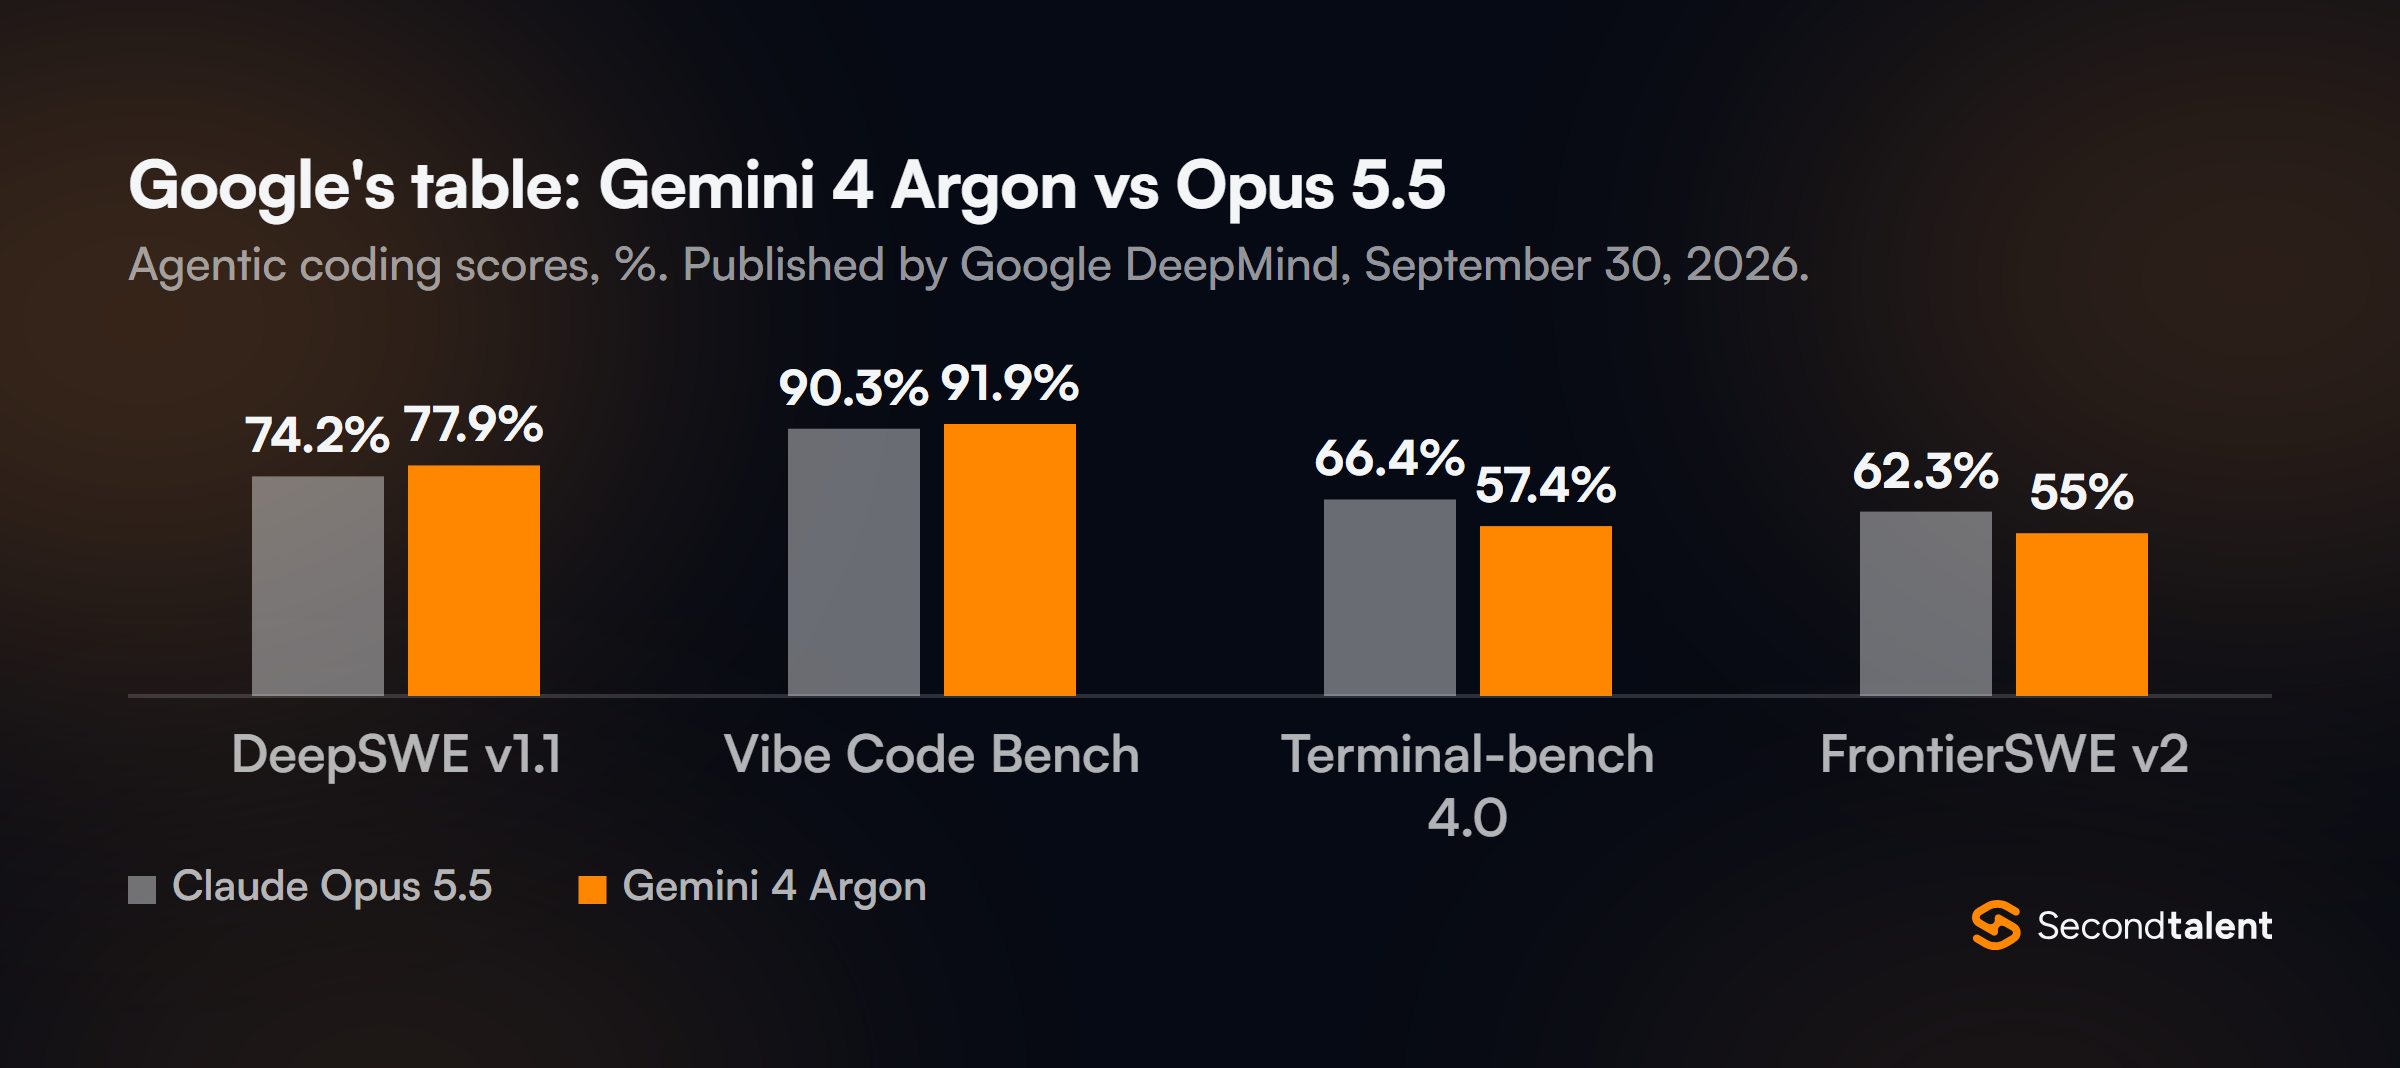
On the Gemini page Google published with Argon, Argon wins DeepSWE and Vibe Code Bench by under four points and loses Terminal-bench 4.0 and FrontierSWE v2 by seven to nine.
A tie on the tasks that look like writing a feature, and a clear Claude lead on the long agentic ones.
Model Lineups and Prices
All five of these models launched inside one month. The July version of this post compared Opus 4.8 with Gemini 3.1 Pro; neither is its family's best coding model now.
Claude's coding models
- Claude Opus 5.5 (
claude-opus-5-5): $4 / $20, 1M context, 128K output. Anthropic says it performs at Fable 5.1's level on most work and costs 40% less to run than Opus 5. A fast mode doubles the price to $8 / $40. - Claude Sonnet 5.5 (
claude-sonnet-5-5): $2 / $10, 1M context, 128K output. The best price-to-score ratio in the Claude line for agentic coding. - Claude Fable 5.1 (
claude-fable-5-1): $10 / $50, Anthropic's most capable model for long research and reasoning runs. For day-to-day coding, Opus 5.5 now matches or beats it. - Claude Haiku 4.5 (
claude-haiku-4-5): $1 / $5, 200K context. The cheap tier, still on the previous generation.
Gemini's coding models
- Gemini 3.8 Flash (
gemini-3.8-flash): 1,048,576 input tokens, 65,536 output, text, image, video, audio and PDF in. Google's developer docs call it the pick for "long-horizon software engineering, autonomous agents". - Gemini 4 Argon: Google's new frontier model, 1M context, for now open only to the Fairwind program. Google says paid API customers and AI Ultra subscribers come next, with no date given.
- Gemini 3.1 Pro: still labeled Preview, $2 / $12 up to 200K tokens of prompt and $4 / $18 above that.
- Gemini 3.5 Flash-Lite: $0.30 / $2.50, the budget option for simple calls.
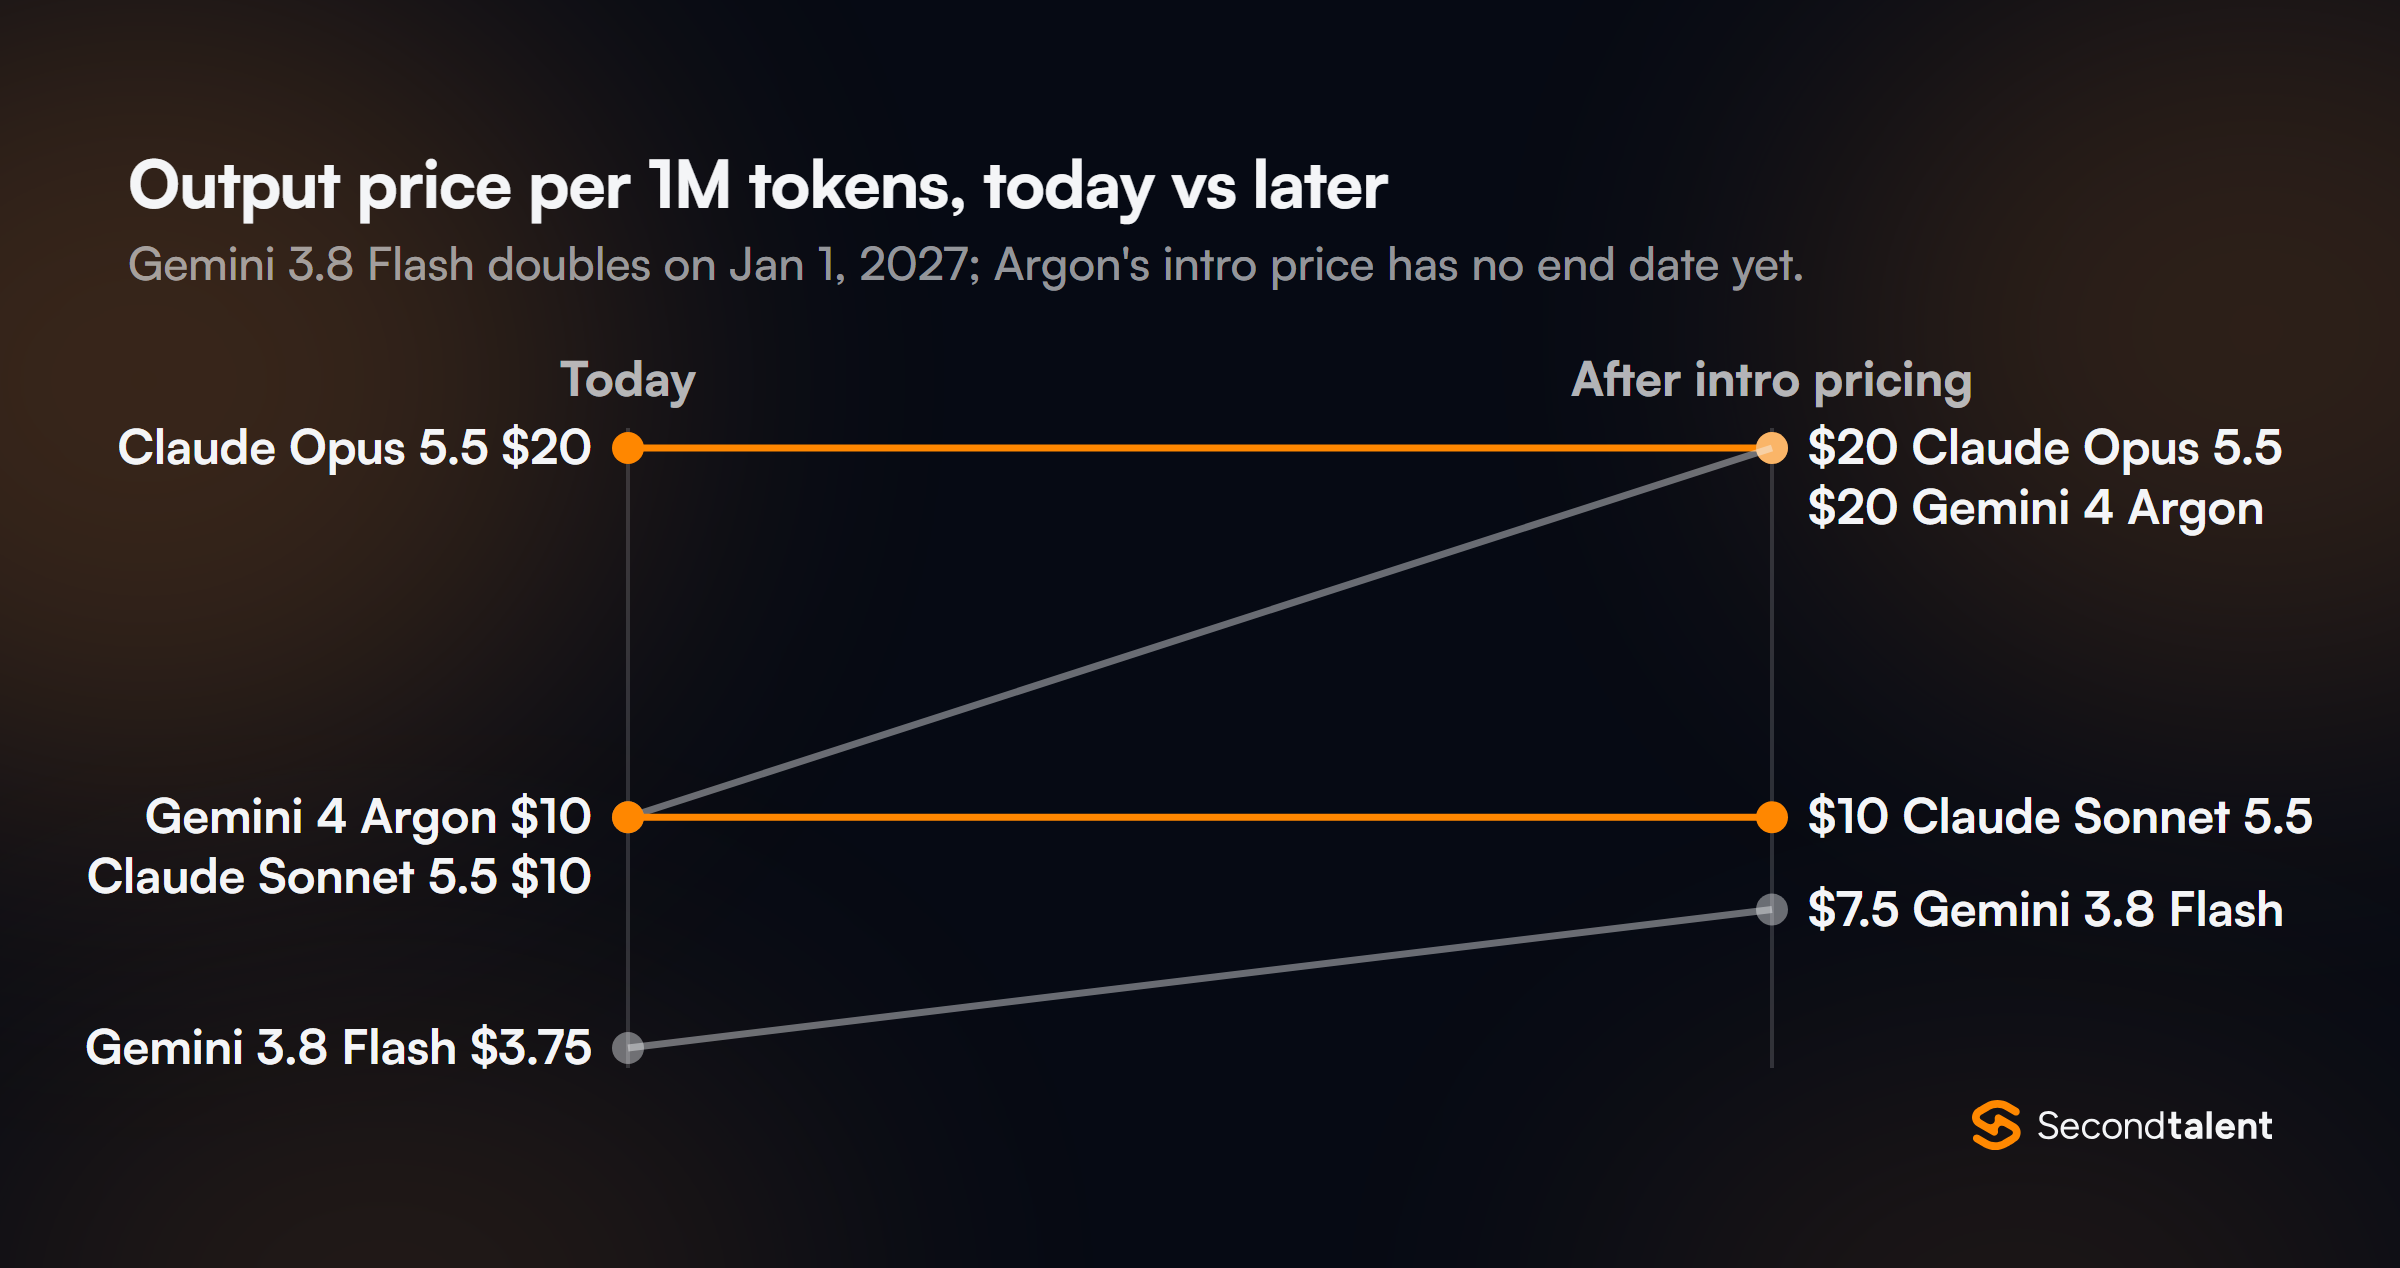
Both Gemini prices are introductory. Google's pricing page doubles 3.8 Flash on January 1, 2027, and the Argon announcement sets a later rate of $4 / $20, the same as Opus 5.5. Claude's prices on the Claude pricing page carry no end date.
If you are budgeting for 2027, use the second column.
Cost Per Task, Not Per Token
Token price misleads in both directions. A model that thinks longer, retries more or writes longer answers can cost more per job even at a lower rate per token.
Artificial Analysis publishes what each model spent to run its full test suite, which is the closest public number to a real cost per task.
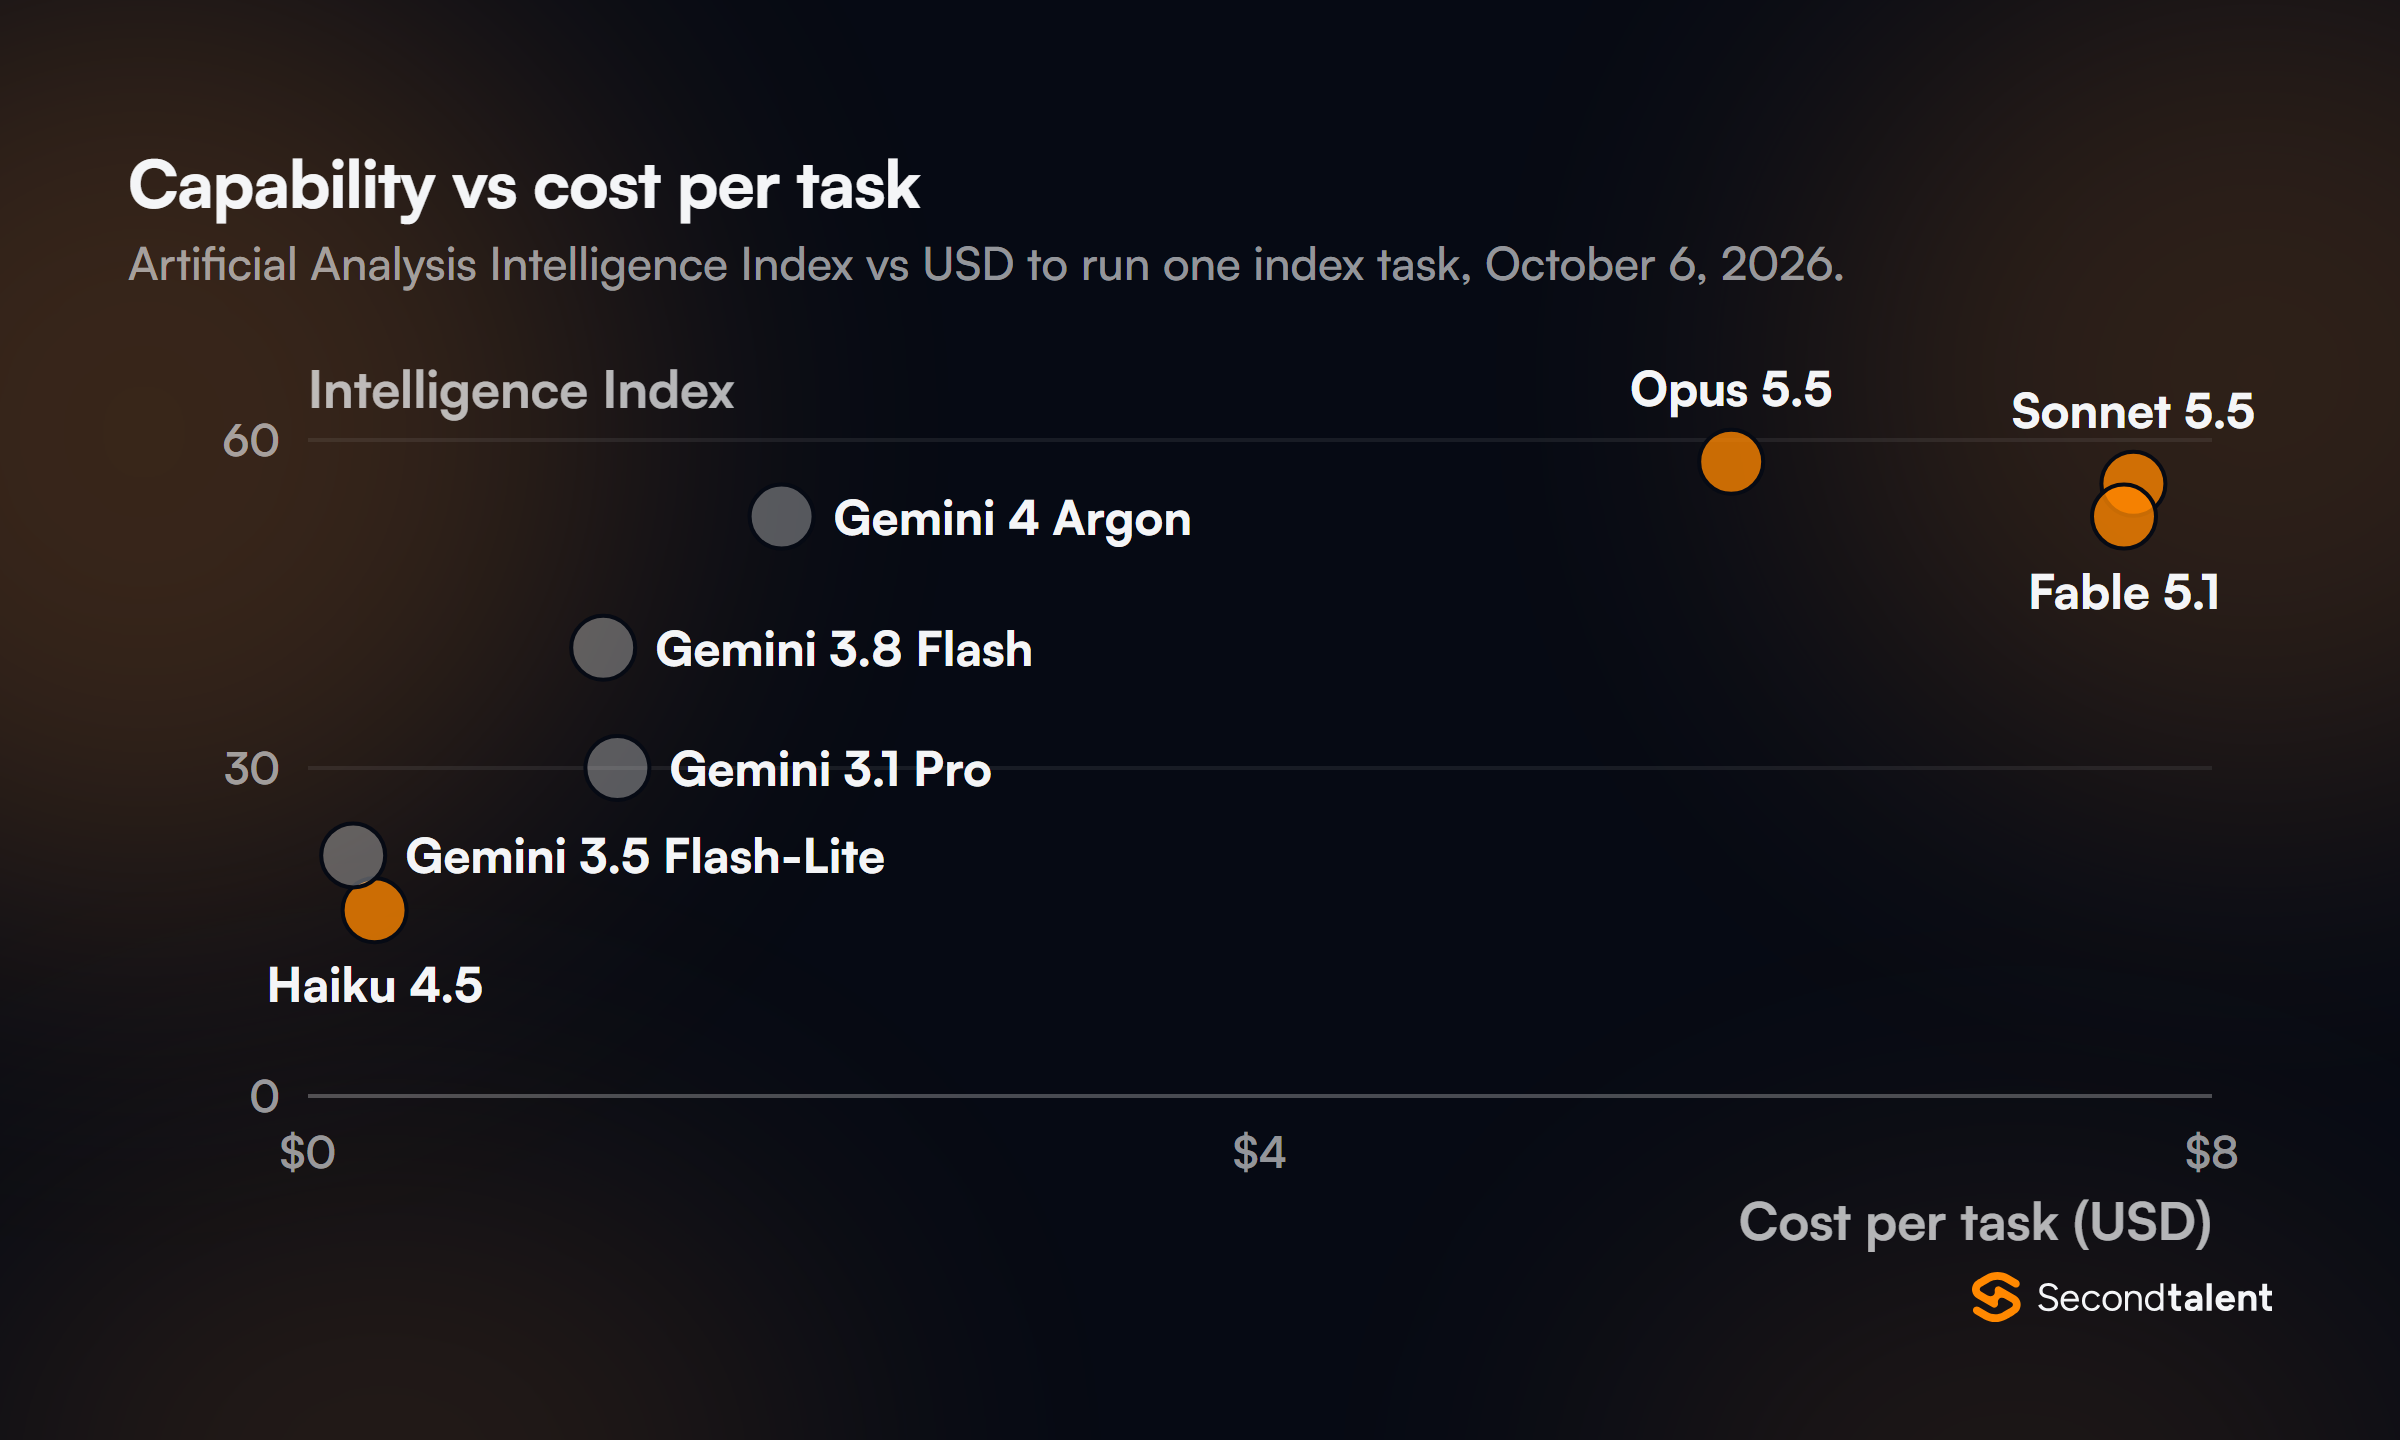
Sonnet 5.5 has half Opus's token price but costs more per task, $7.67 against $5.98, which means it spent well over twice as many tokens on the same tests.
Argon is the striking one: the same index score as Fable 5.1 at roughly a quarter of the cost, on its introductory price.
For a team, the useful question is what a wrong answer costs. The API bill is rarely the expensive part; an engineer spending an afternoon unpicking a change that compiled but broke something two modules away is.
On those jobs Opus or Sonnet earns its premium. On high-volume, well-specified work such as test generation, docstrings or migration boilerplate, 3.8 Flash at a fifth of the cost is the better trade.
Speed, Context and Multimodal Input
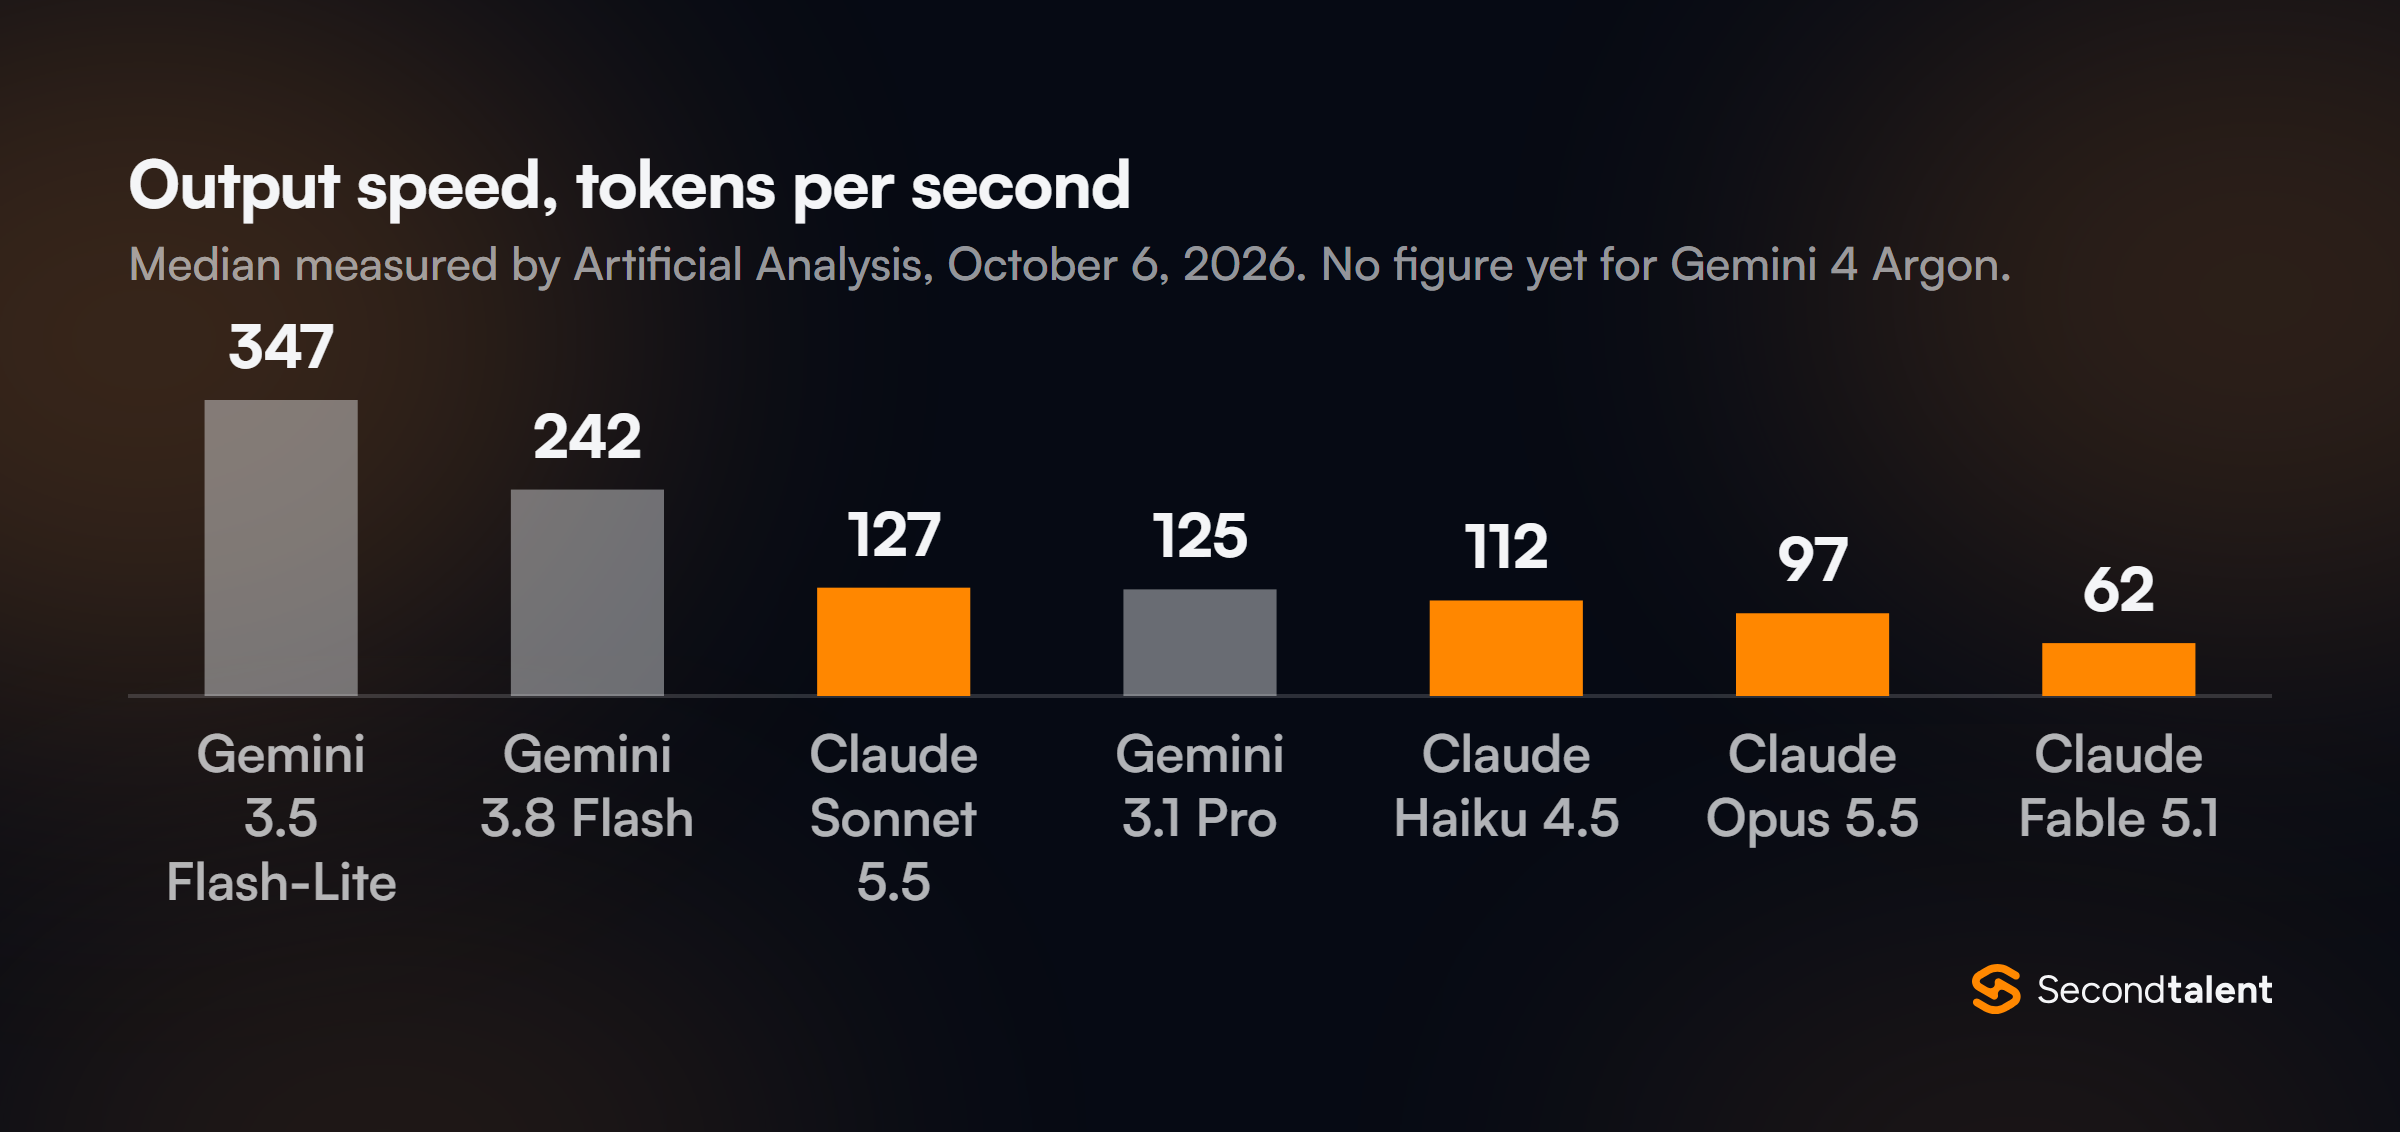
Gemini 3.8 Flash streams 242 tokens a second, almost twice Sonnet 5.5's 127 and two and a half times Opus 5.5's 97. In an editor, that is the difference between a suggestion that appears as you pause and one you wait for.
In CI, it shortens every agent step.
Context is a tie at 1M tokens for every model here except Haiku 4.5.
Output is not: Claude's 5.x models can write 128K tokens in one reply, nearly double Gemini 3.8 Flash's 65,536, which matters when an agent rewrites a large file in one pass.
Input types still favor Google. Gemini 3.8 Flash takes video and audio natively, so a screen recording of a bug or a spoken spec can go straight into the prompt.
Claude reads text, images and PDFs, which covers screenshots and design files but not a recording.
Developer Experience: Claude Code vs Antigravity
The agent around the model shapes the day as much as the model does.
- Runs in the terminal, with desktop, web and VS Code / JetBrains versions
- Hooks, skills, subagents and MCP for custom workflows
- Works next to the editor you already use
- A full agent-first IDE, with Gemini 3.8 Flash built in
- An Antigravity Agent model in preview on the Gemini API
- The same Gemini 3.8 Flash also runs in AI Studio and Android Studio
Claude Code suits developers who want an agent that fits into their existing setup and can be scripted. Antigravity suits teams that want one editor with agents built in, and our guide to installing the Antigravity IDE covers the setup.
For a wider look at the editors around Claude, see our list of Claude Code editors.
When to Choose Each
Choose Claude for:
- Long agent runs that edit many files and run tests, where Terminal-Bench 4.0 shows the widest gap
- Debugging and AI code review where a missed bug is expensive
- Large single-pass rewrites that need up to 128K tokens of output
- Budgets for 2027 that cannot absorb a price that doubles
Choose Gemini for:
- High-volume, well-specified work where 3.8 Flash costs a fifth as much per task
- Latency-sensitive autocomplete and CI steps, at 242 tokens a second
- Bug reports and specs that arrive as video or audio
- Teams already on Google Cloud and Antigravity
Many teams route between the two: Flash for first drafts and bulk jobs, Sonnet or Opus 5.5 for the hard changes and final review.
If Argon reaches the public API at $2 / $10, that split will need a fresh look; until then it is a preview most developers cannot call.
Our Fable vs Opus vs Sonnet comparison and Gemini Flash-Lite vs Flash vs Pro guide go deeper within each family, and GPT-6 vs Claude vs Gemini adds OpenAI's models.
For teams building AI applications around governed enterprise data, Databricks provides a unified Data + AI Platform for data, analytics, agents and apps.
Its governance layer keeps models, data, and agent workflows managed in one place, complementing, rather than replacing, the choice of coding model.
Hire Engineers Who Build With Both
Choosing a model takes an afternoon; wiring a router, evals and cost tracking around it takes engineers who have done it before. We place vetted AI engineers and LLM developers from Asia who build on Claude and Gemini every day.
Tell us what you are building to get a shortlist.
Frequently Asked Questions
Can I use Gemini 4 Argon for coding today?
Not unless your organization is in Google's Fairwind cyber-defense program. Google says paid API customers and Google AI Ultra subscribers will get access next, without a date.
Is Gemini 3.1 Pro still worth using?
Rarely for coding. It is still a Preview model, scores 30 on the Artificial Analysis index against 41 for 3.8 Flash, and costs more per token.
Are older models like Claude Opus 4.8 and Sonnet 5 still available?
Yes. Anthropic still serves Opus 5, Opus 4.8 and Sonnet 5 at their old prices, but Opus 5.5 and Sonnet 5.5 cost the same or less, so there is little reason to stay on them for new work.