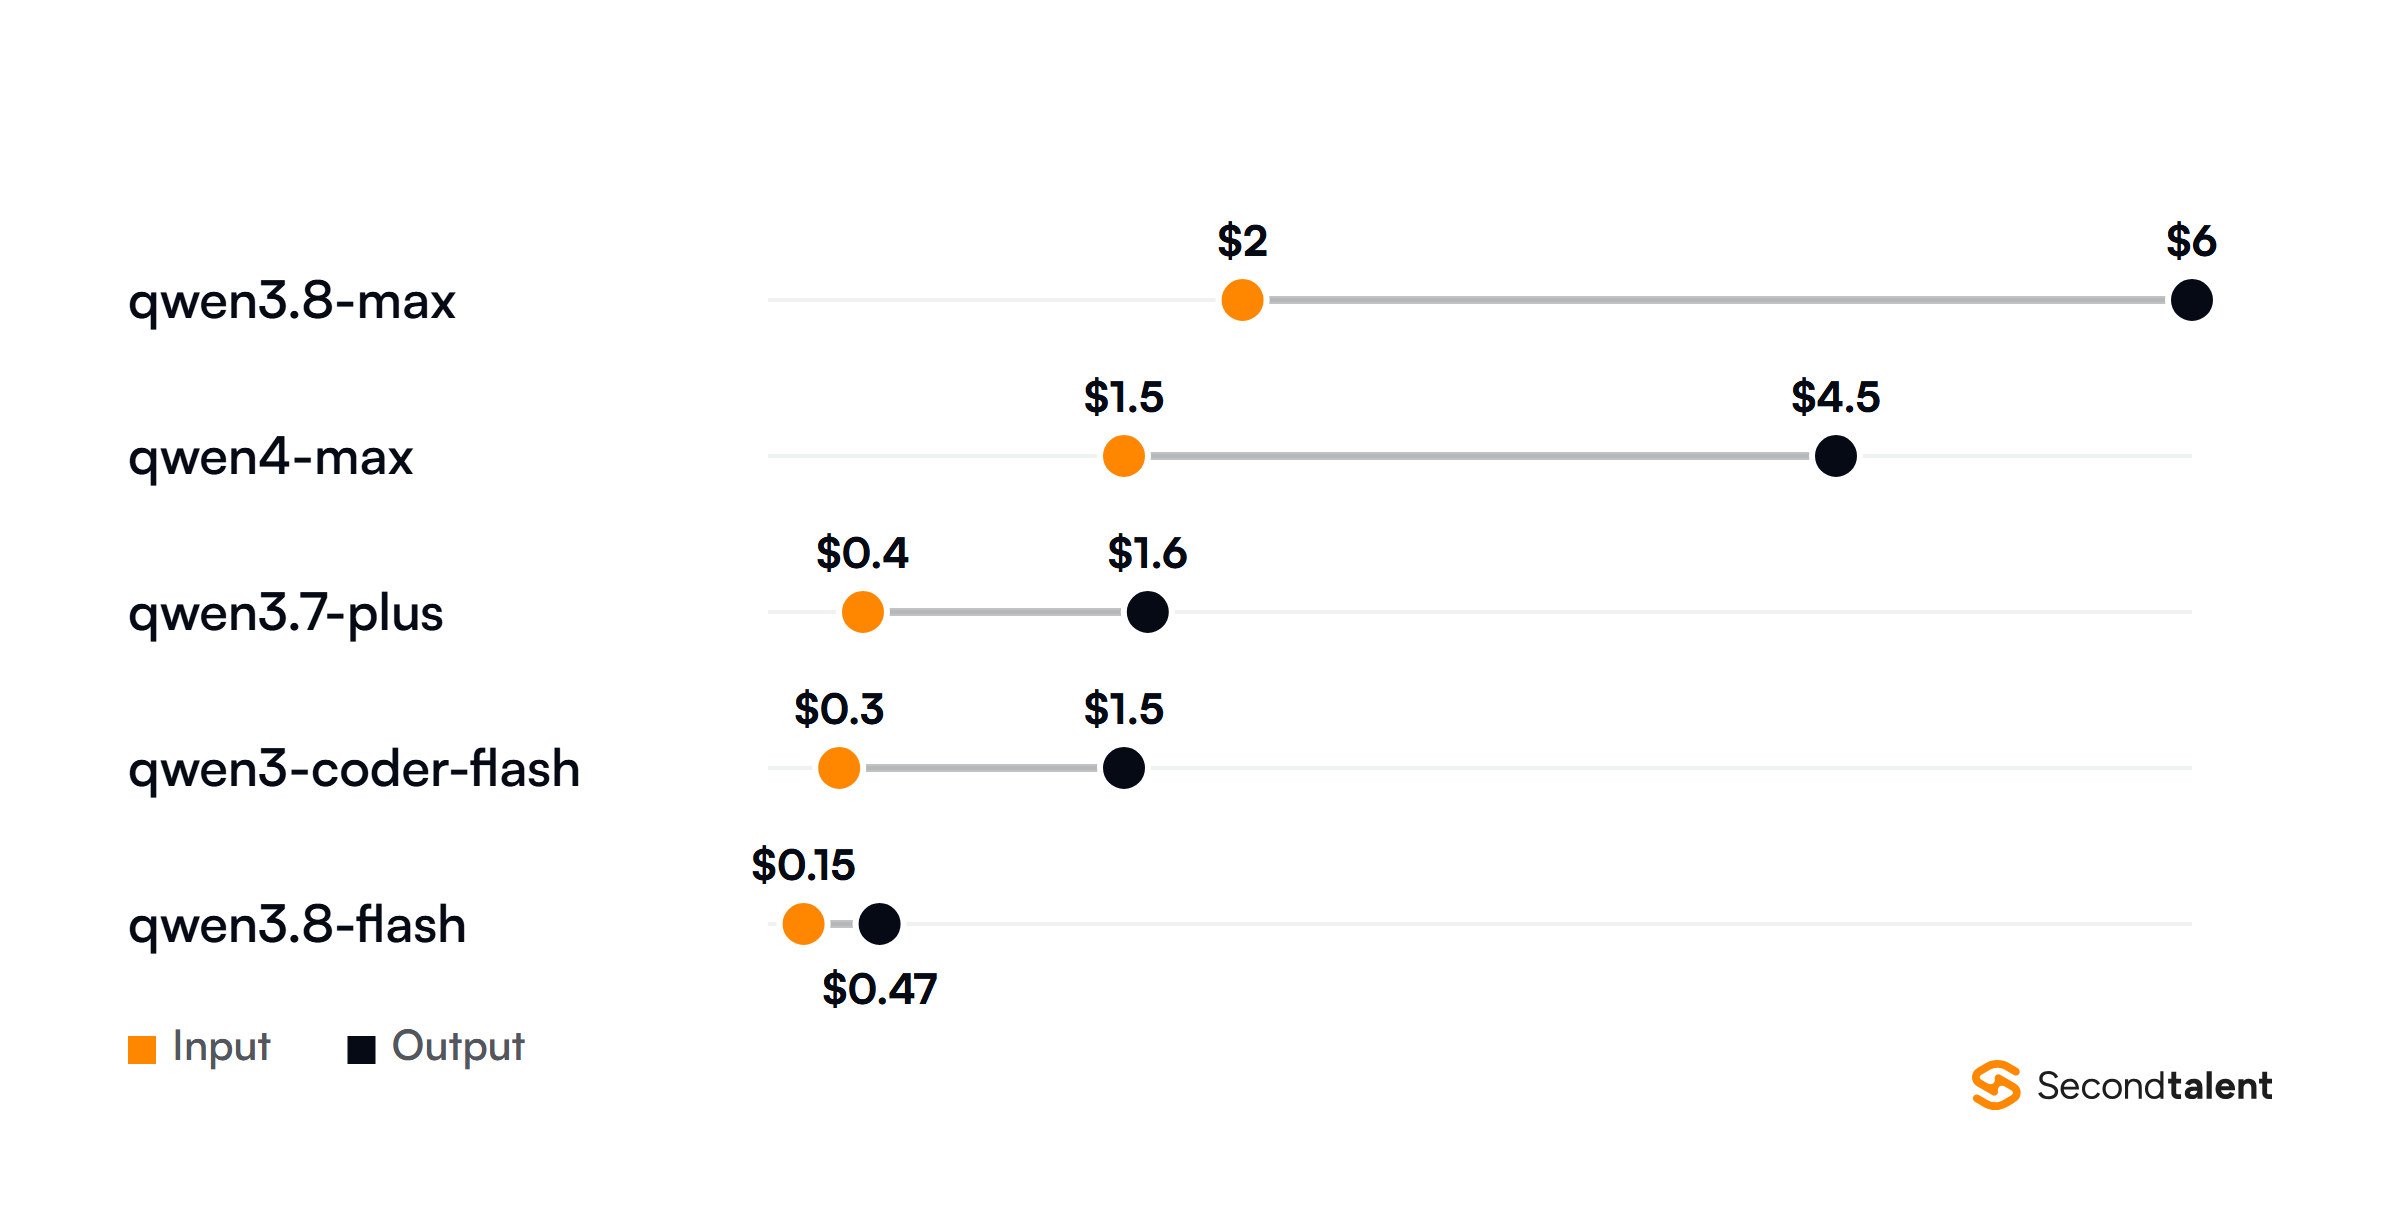

TL;DR: For coding in November 2026, use Qwen3.8-Max in chat or over the API ($2 in, $6 out per million tokens), or run the open Qwen3.8-27B on your own machine; it scores 61.7 on SWE-bench Pro under an Apache 2.0 licence. In our 17 November test against seven other chatbots, Qwen3.8-Max built the most complete password checker and found the root cause of our date-sorting bug, but the checker took about six minutes. Qwen Code, Alibaba's terminal agent, is free and open source, though its free hosted tier closed on 15 April 2026.
Alibaba Cloud switched off qwen3-coder-plus on 10 October 2026 and told its users to move to a general model, qwen3.7-plus. The dedicated Qwen coder line now has one hosted model left, qwen3-coder-flash.
The coding gains ship inside Qwen3.6, Qwen3.8 and the new qwen4-max.
We gave Qwen and seven rival chatbots the same three prompts on 17 November 2026 to see how that plays out on real code.
Key takeaways
1You can try Qwen3.8-Max at chat.qwen.ai with no account: guests answer one birth-year question and get Qwen3.7-Plus and Qwen3.8-Max.
2On Qwen's own table, Qwen3.8-Max sits 1.5 points behind Claude Opus 4.8 on SWE-bench Pro and ahead of it on Terminal Bench 2.1.
3Qwen's checker rated Password123! as strong, and so did six of the other seven tools. Only Claude caught it.
4Alibaba's Coding Plan Pro costs $50 a month for up to 90,000 requests and works with Qwen Code, Claude Code and Cursor.
Which Qwen model to use for coding in November 2026
Pick Qwen3.8-Max for the hardest work, Qwen3.7-Plus for everyday agent runs, and Qwen3.8-27B if the code cannot leave your machines.
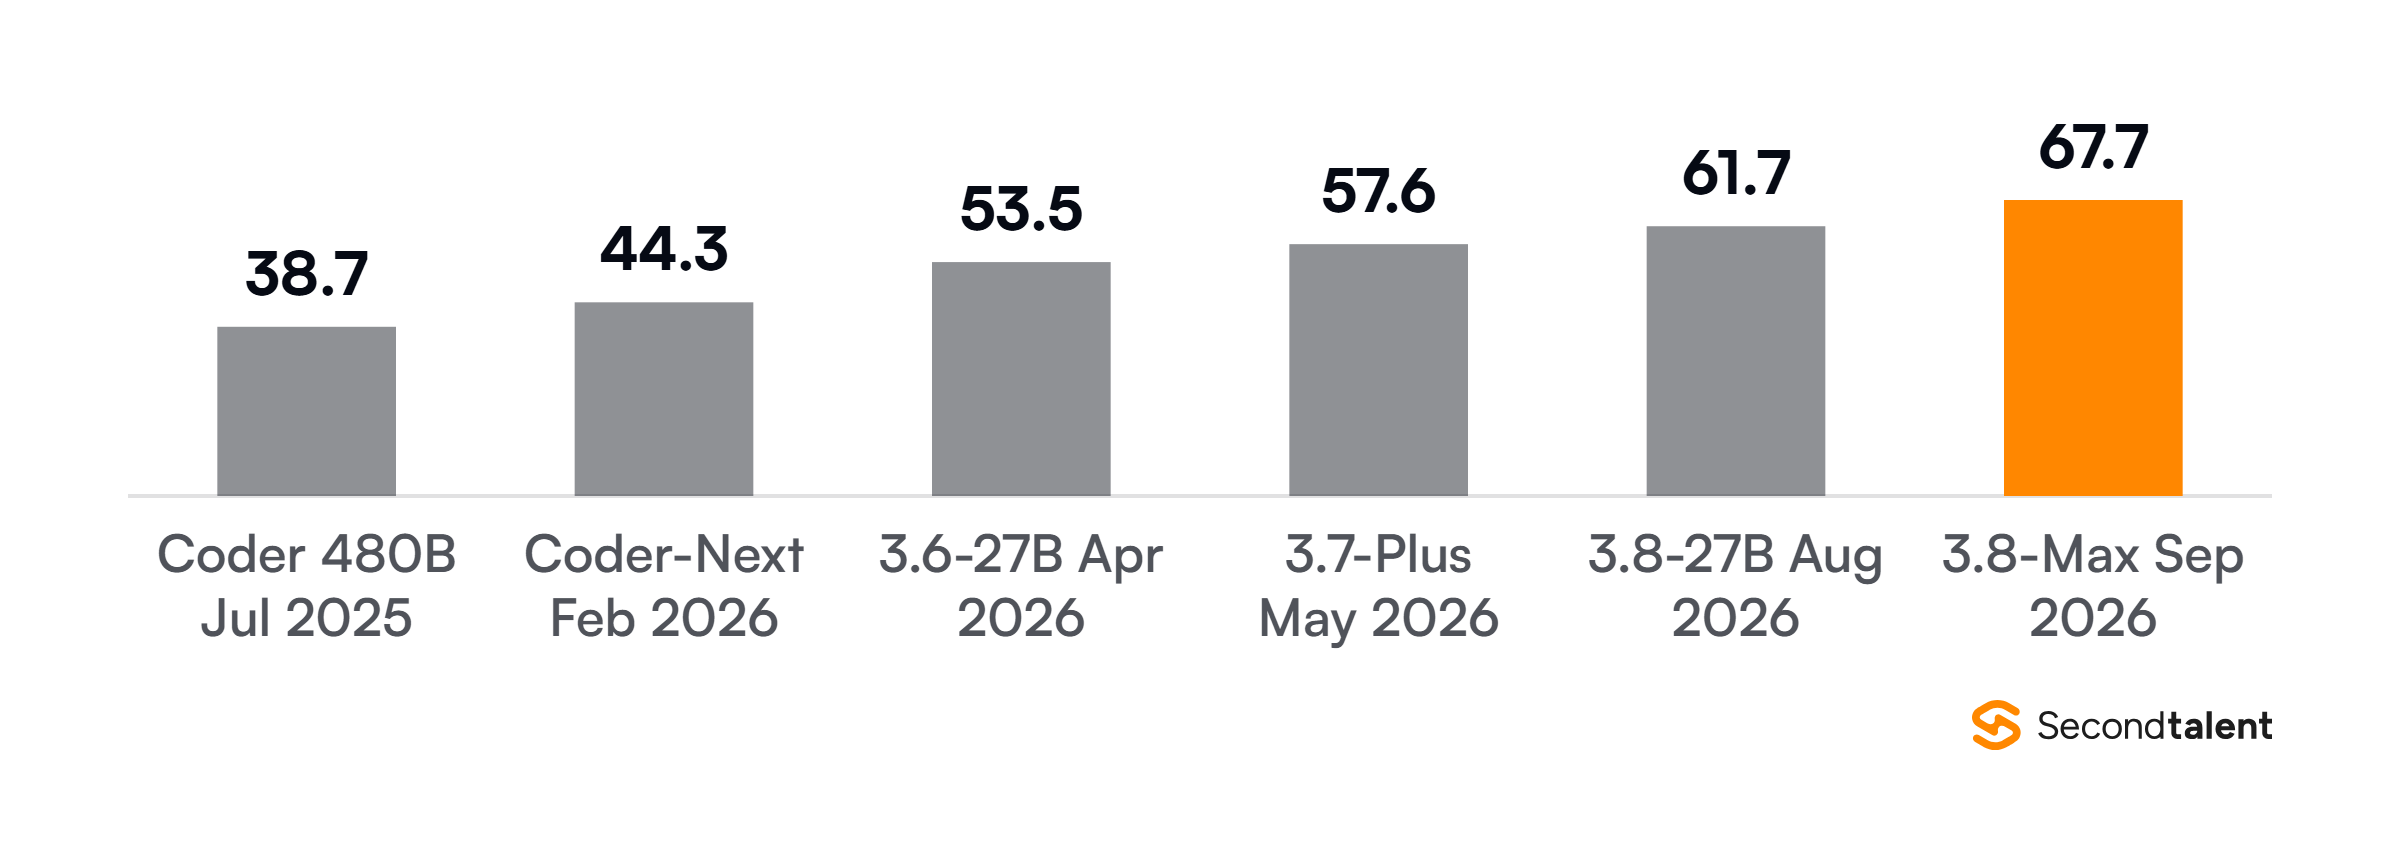
The model called "Qwen Coder" is no longer the best Qwen for code: the last dedicated release, Qwen3-Coder-Next in February 2026, scores 44.3 on SWE-bench Pro, 17 points under the general Qwen3.8-27B.
Qwen3.8-MaxAPI, chat
67.7
SWE-bench Pro. 2.4T parameters, 95B active, 1M context by default
Qwen3.7-PlusAPI, chat, Coding Plan
$0.40 / $1.60
Alibaba's named replacement for qwen3-coder-plus
Qwen3.8-27BOpen weights
18 GB
Ollama download, Apache 2.0, 256K context
Qwen3-Coder-NextOpen weights
3B active
80B total, 70.6 on SWE-bench Verified
Source: Qwen model cards on Hugging Face, Alibaba Cloud Model Studio pricing and the Ollama library, checked 17 November 2026.
The hosted coder models went in one sweep.
Alibaba Cloud's deprecation table lists qwen3-coder-plus, its two dated snapshots, qwen3-coder-next, qwen3-coder-30b-a3b-instruct and qwen3-coder-480b-a35b-instruct as retired on 10 October 2026, each with qwen3.7-plus as the replacement.
API calls to a retired model fail, so any script still pinned to qwen3-coder-plus has been broken for five weeks.
The open weights stay on Hugging Face, so you can still run Qwen3-Coder yourself. Our guide to every Qwen model covers the non-coding side of the family.
How Qwen did in our hands-on coding test
Qwen3.8-Max wrote the best-looking app of the day and took the longest to do it. We ran three prompts at chat.qwen.ai on 17 November 2026 as a guest, without logging in.
The guest model menu offered two models, Qwen3.7-Plus (the default) and Qwen3.8-Max, and the first message triggered an age check asking for a birth year.
Test 1: build a password strength checker
Model Qwen3.8-Max~6 min to finished codeResult works
The prompt: "Create a responsive password strength checker using HTML, CSS, and JavaScript.
It should analyze passwords in real-time as the user types, showing strength levels (weak/medium/strong) with color indicators, display specific requirements (length, uppercase, lowercase, numbers, special chars), and update dynamically.
Include smooth transitions between strength levels."
Qwen3.8-Max thought out loud for five to six minutes before it finished the code. Guests get Copy and Download buttons on the code block but no preview, so we saved the file and opened it in Chrome.
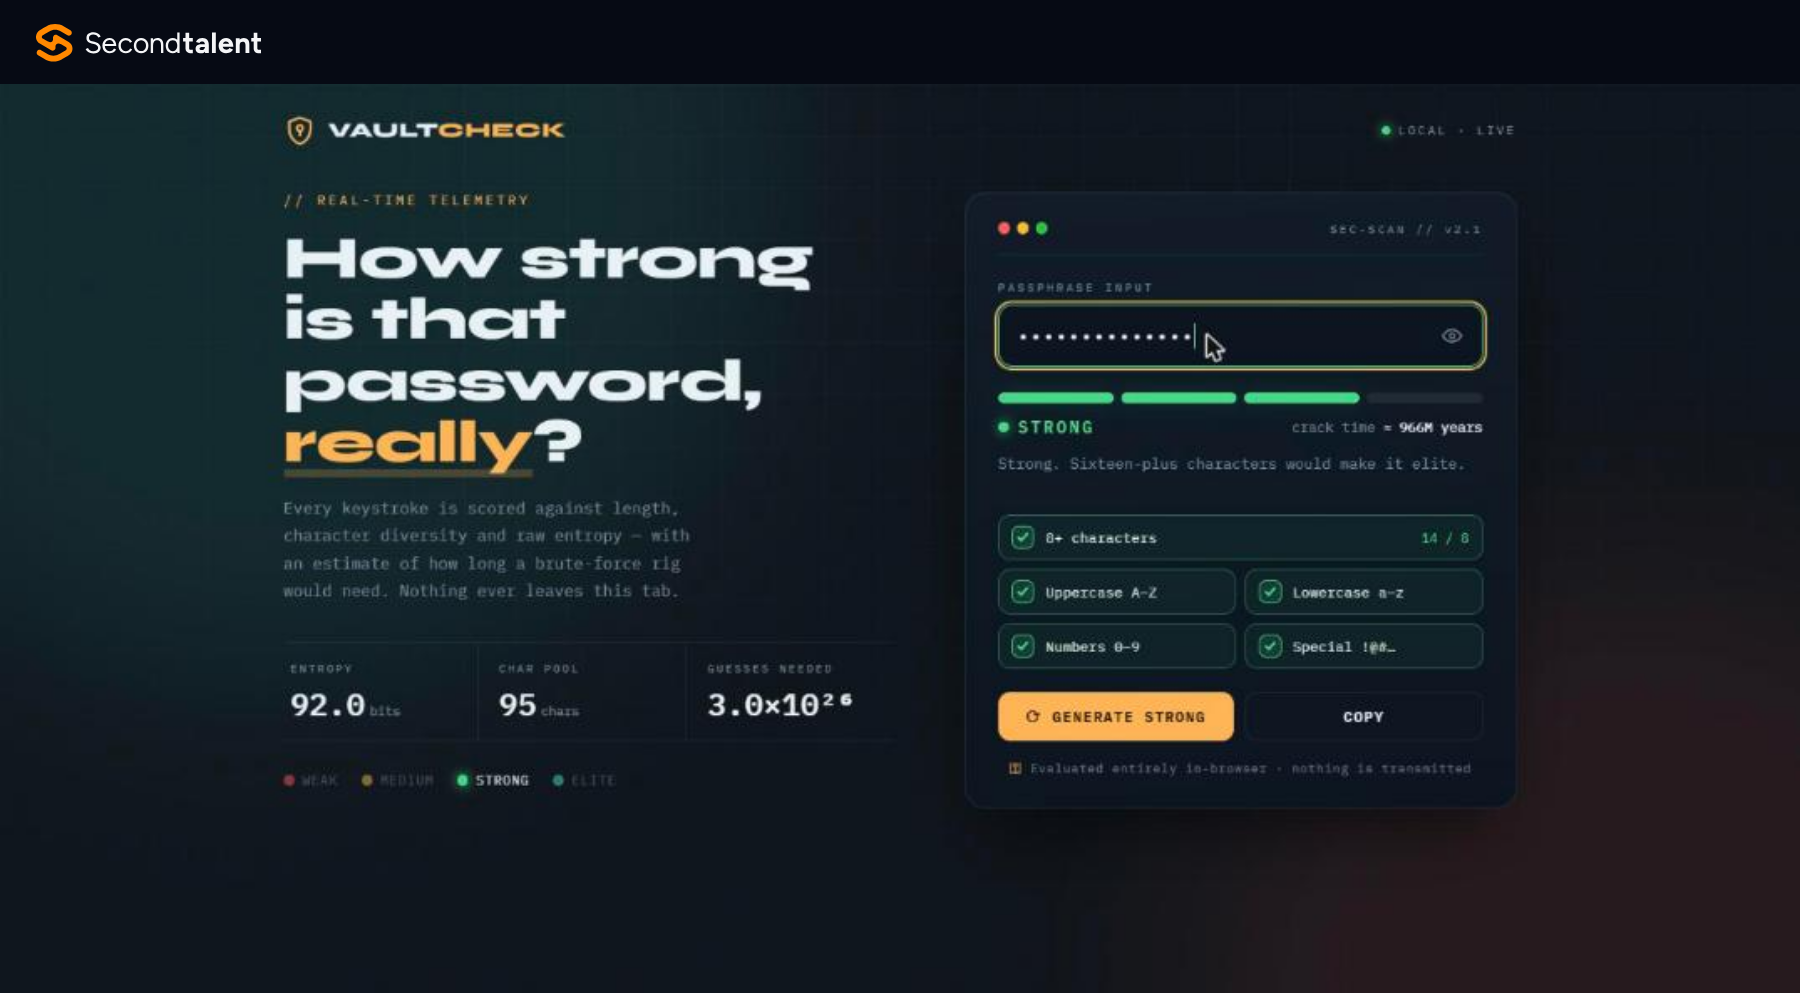
It had named its app "VaultCheck": a landing-page hero, a four-segment strength bar, entropy in bits, character pool, guesses needed, a crack-time estimate and a "Generate strong" button.
We typed the same four strings into all eight tools' output. Qwen's scores held together:
abc: weak, 14.1 bits, crack time "instantly"
abcDef7: weak, 41.7 bits, about 23 seconds
abcDef7!xyzQ9k: strong, 92.0 bits, about 966 million years
Password123!: strong, 78.8 bits, because nothing checks for common passwords
Two details matter if you ship this. The page loads Google Fonts, so its "nothing leaves this tab" footer overstates its privacy.
The last result counts most: a checker that calls Password123! strong will pass a password found on public breach lists.
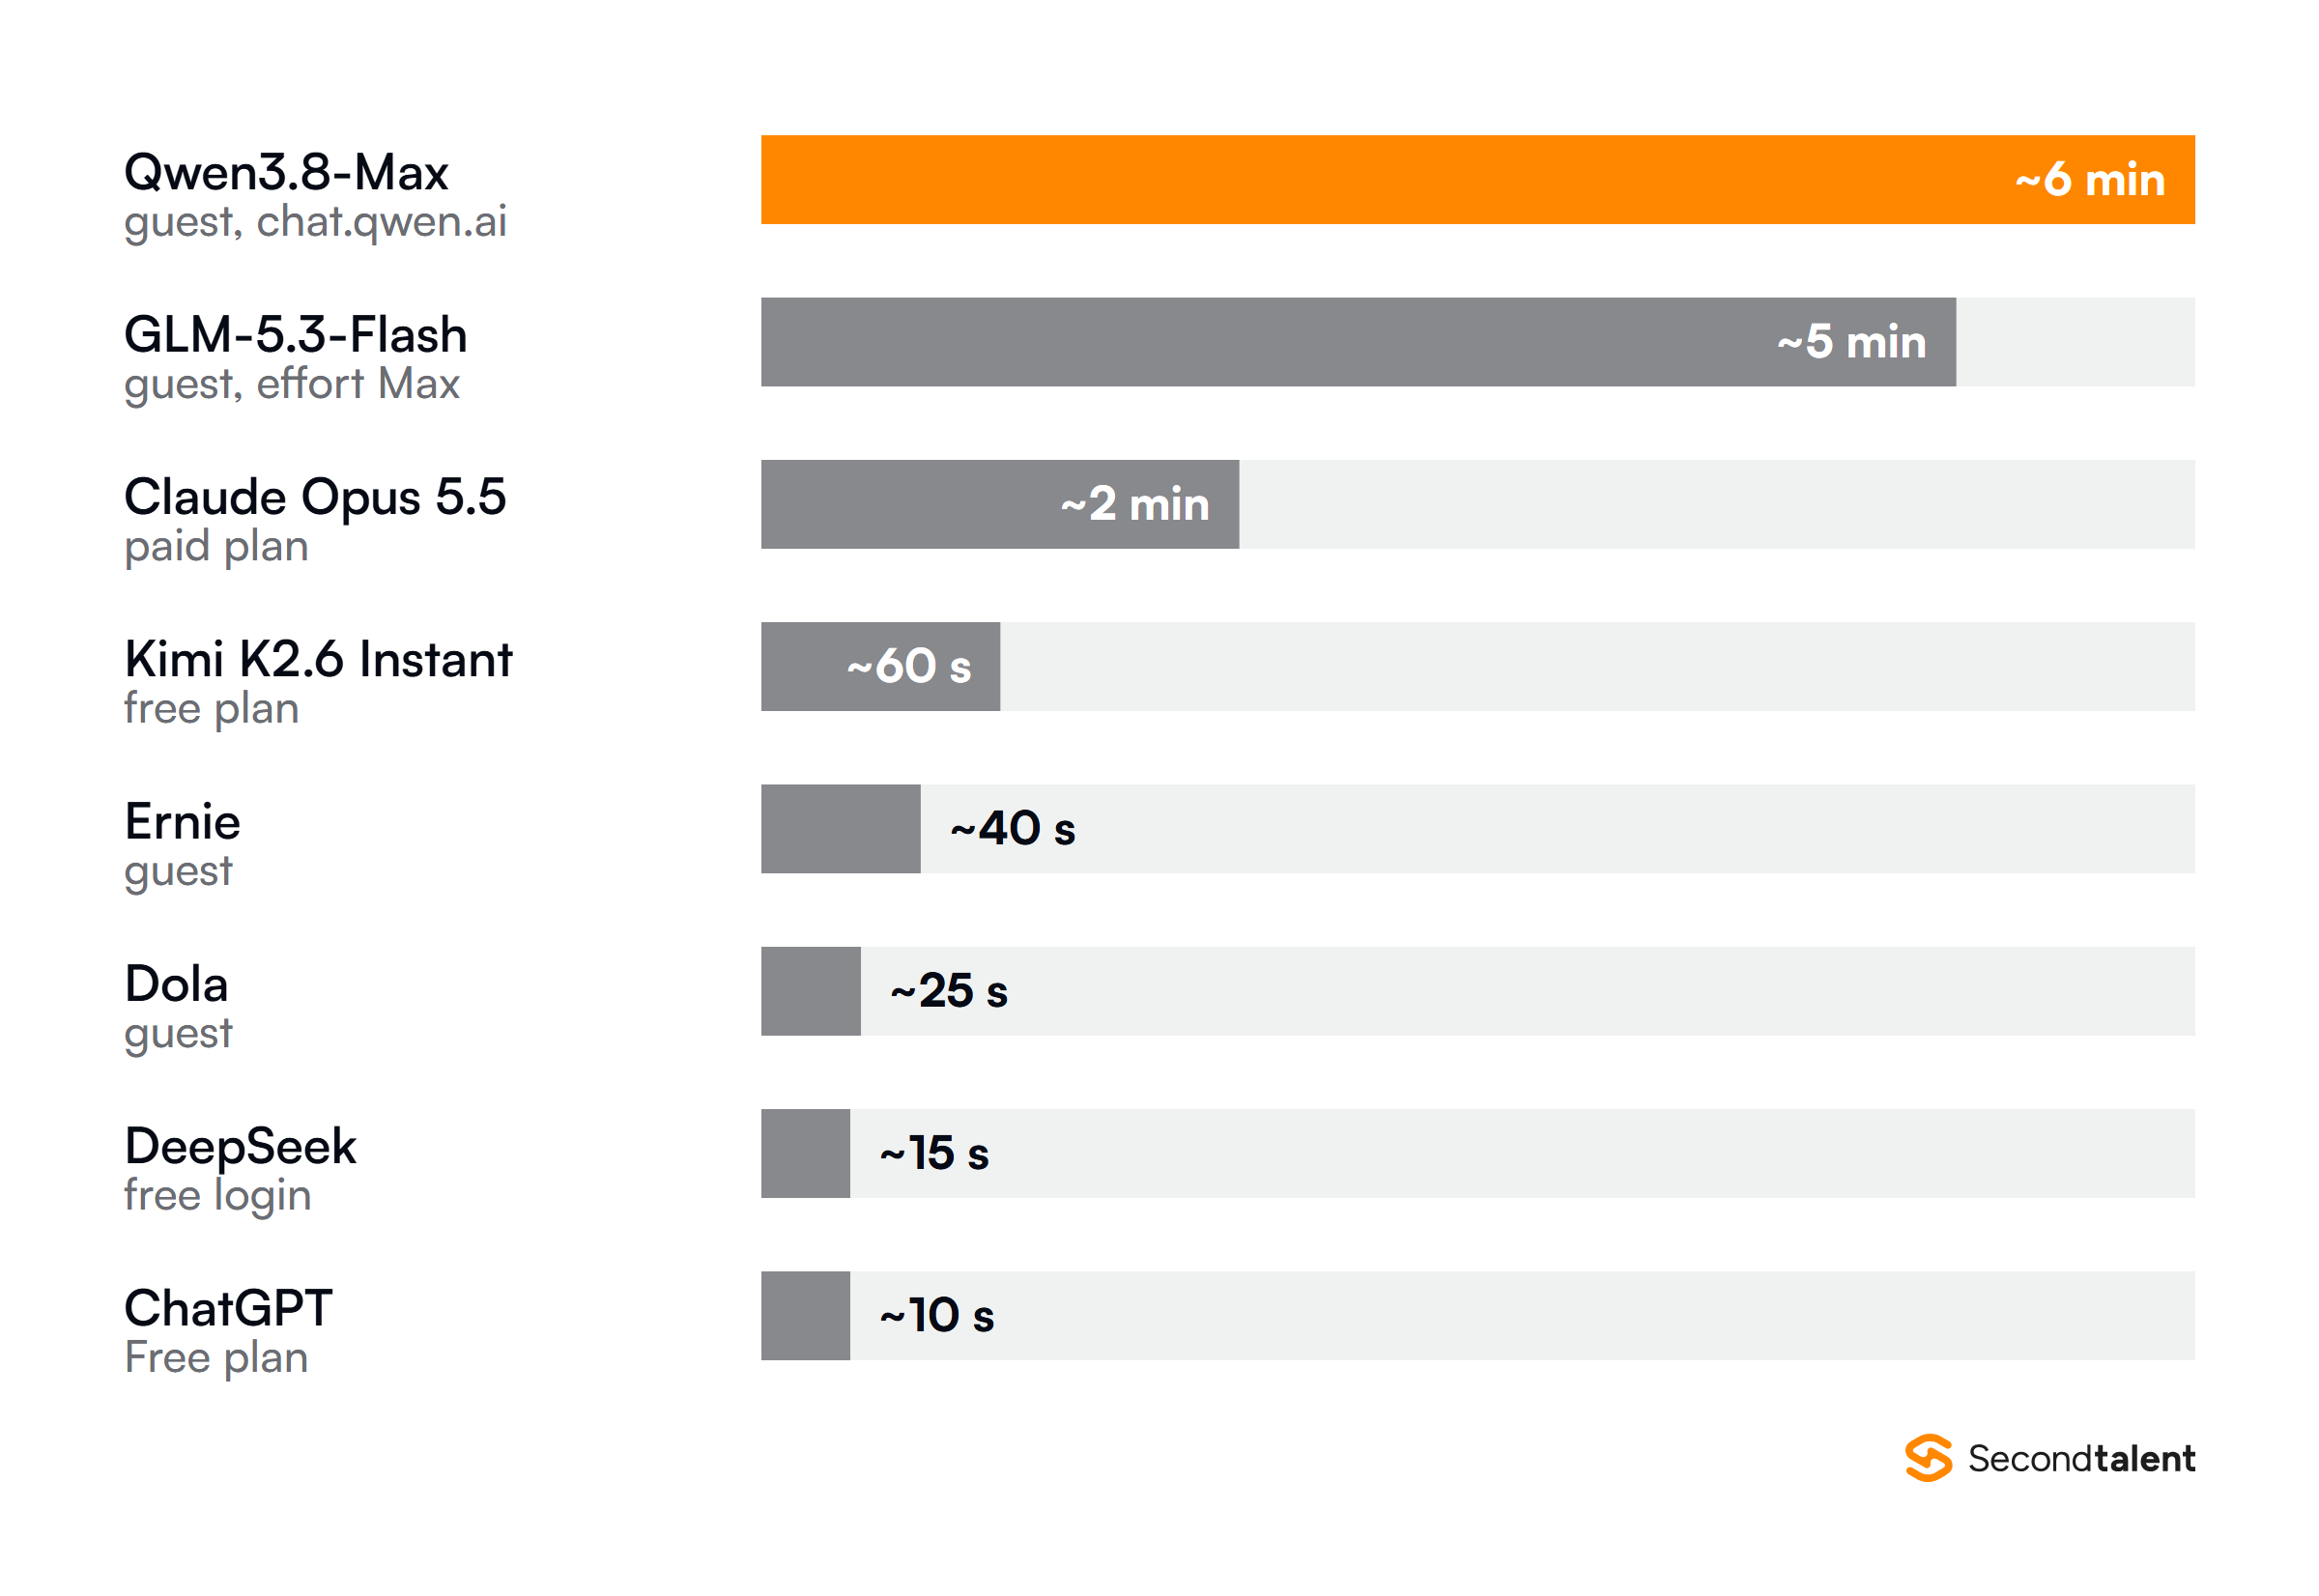
Time was the cost. The other seven tools all finished faster, and three of them finished in under 30 seconds:
Test 2: find a production bug
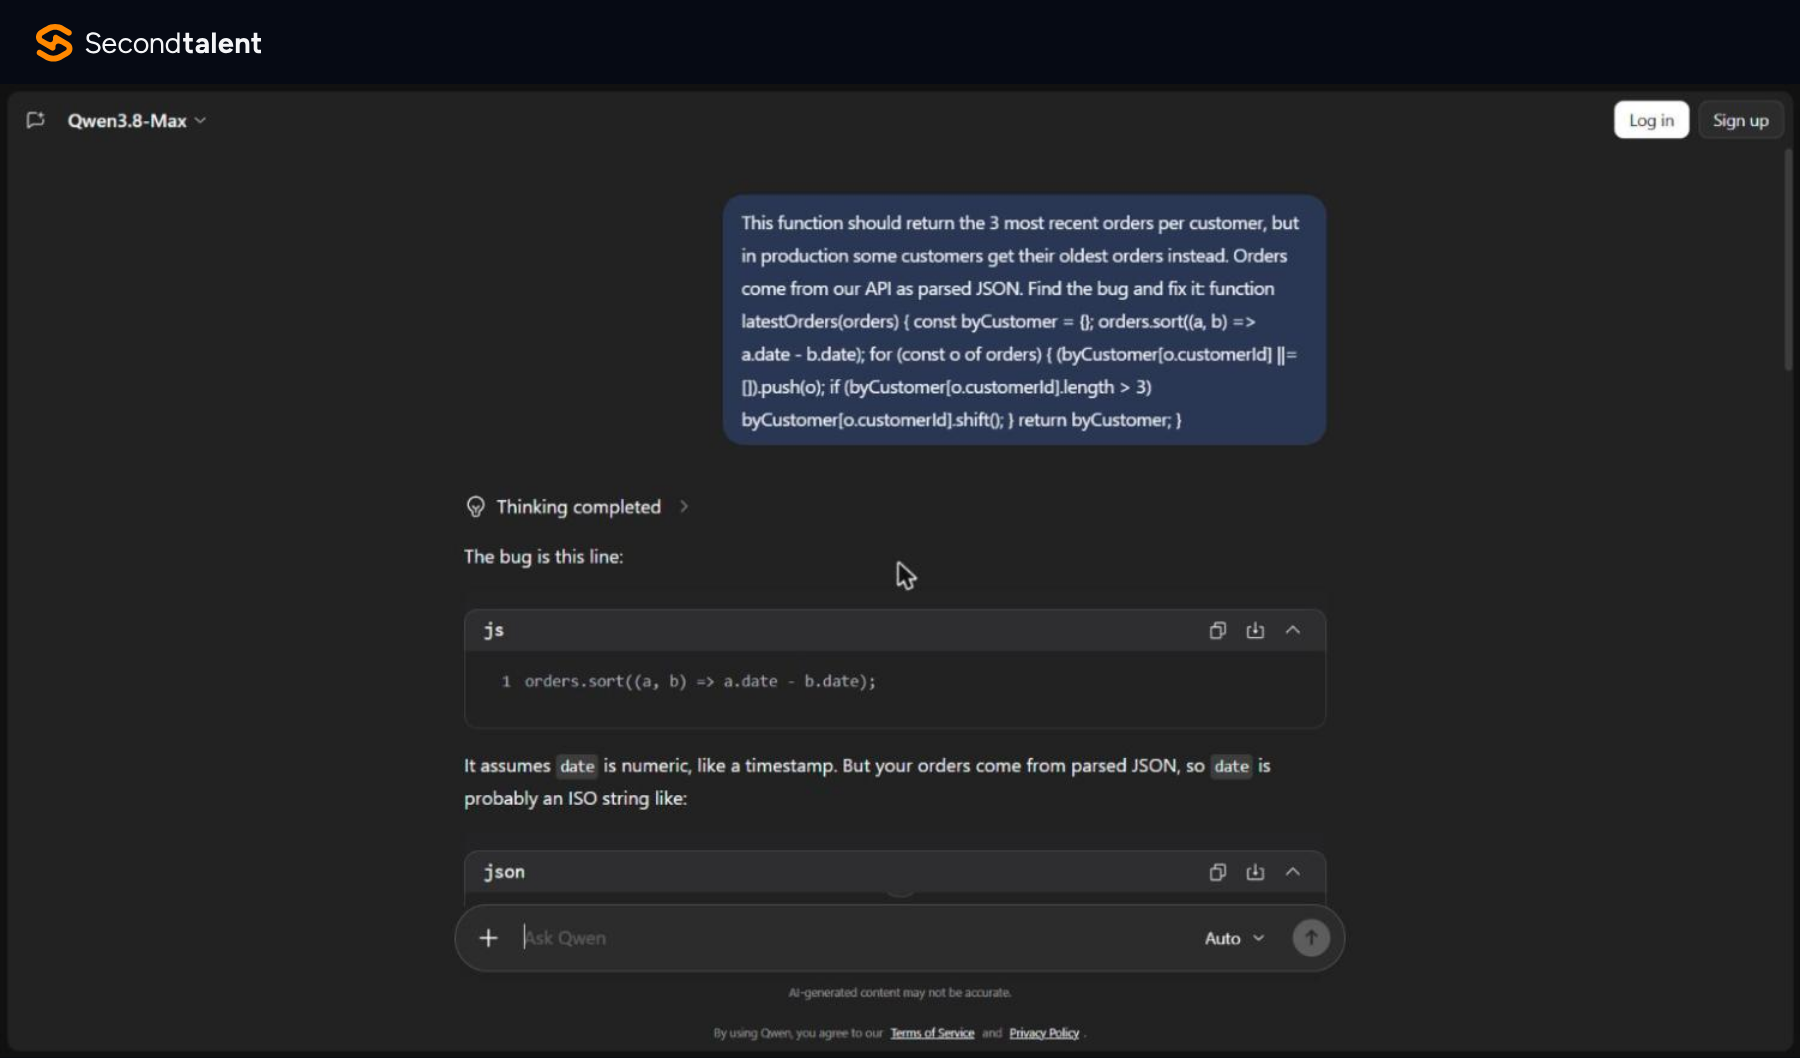
The bug hides in one line. We asked: "This function should return the 3 most recent orders per customer, but in production some customers get their oldest orders instead. Orders come from our API as parsed JSON.
Find the bug and fix it", followed by a function that sorts with orders.sort((a, b) => a.date - b.date) and keeps the last three per customer.
Parsed JSON has no date type, so date is an ISO string, string minus string is NaN, and the sort leaves the array in API order. If the API sends newest first, the loop keeps the three oldest.
Qwen3.8-Max found this in one to two minutes: it named the line, explained that the dates arrive as strings, and gave a fix that parses timestamps and sorts a copy newest-first before keeping the first three.
Claude's answer went one step further, explaining that a NaN comparator counts as "equal", which is why only some customers were hit. Qwen's fix was still correct and ready to paste.
Test 3: answer with sources
Coding work also means looking things up, so the third prompt checked whether Qwen searches before it answers.
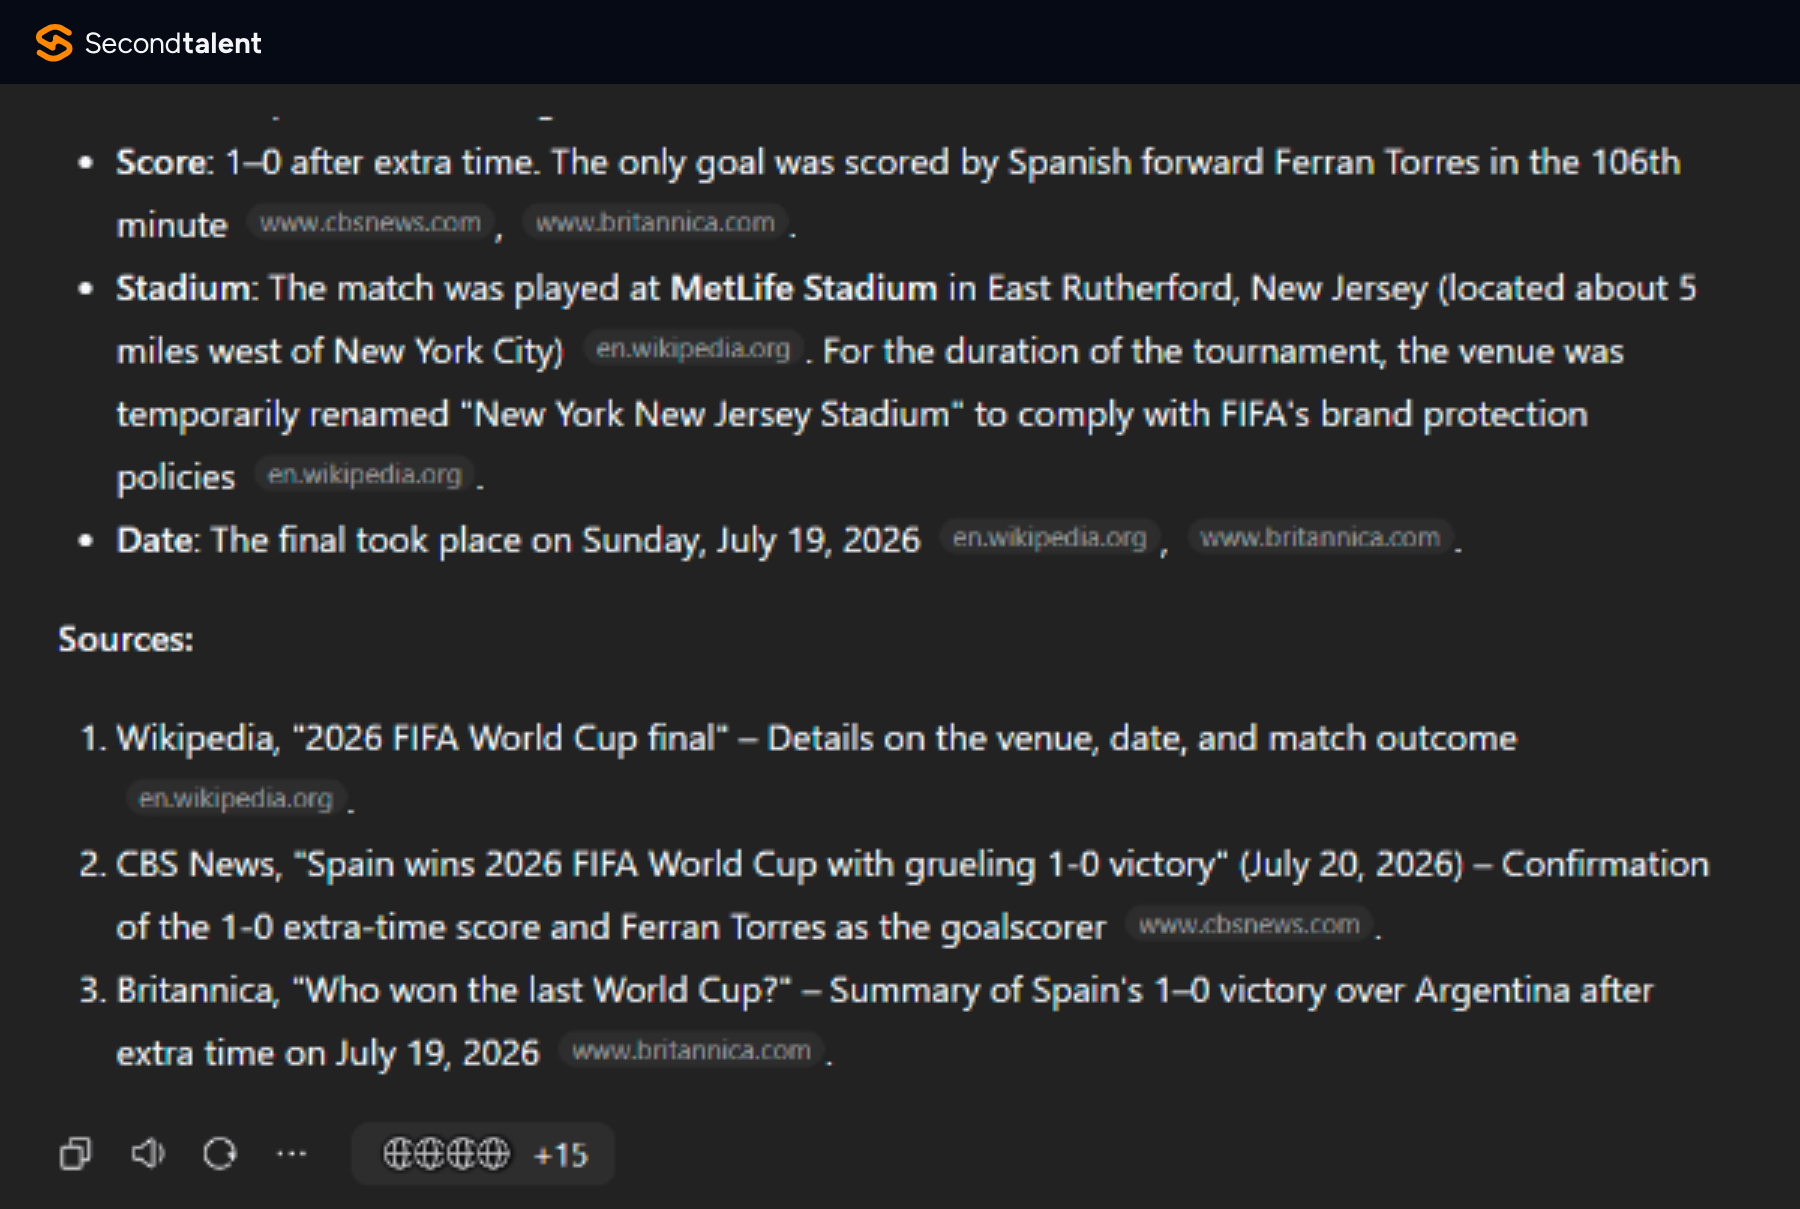
We asked: "Who won the 2026 FIFA World Cup final, what was the score, and in which stadium was it played? Give your sources."
On the default Qwen3.7-Plus, the status line read "Searching the web", then "Reading sources", and about 20 seconds later it had the right answer.
Spain beat Argentina 1-0 after extra time on 19 July 2026, with Ferran Torres scoring in the 106th minute at MetLife Stadium.
Qwen added that FIFA renamed the venue "New York New Jersey Stadium" for the tournament, and cited Wikipedia, CBS News and Britannica plus 15 more pages.
Qwen against Claude, DeepSeek, Kimi, GLM and three others
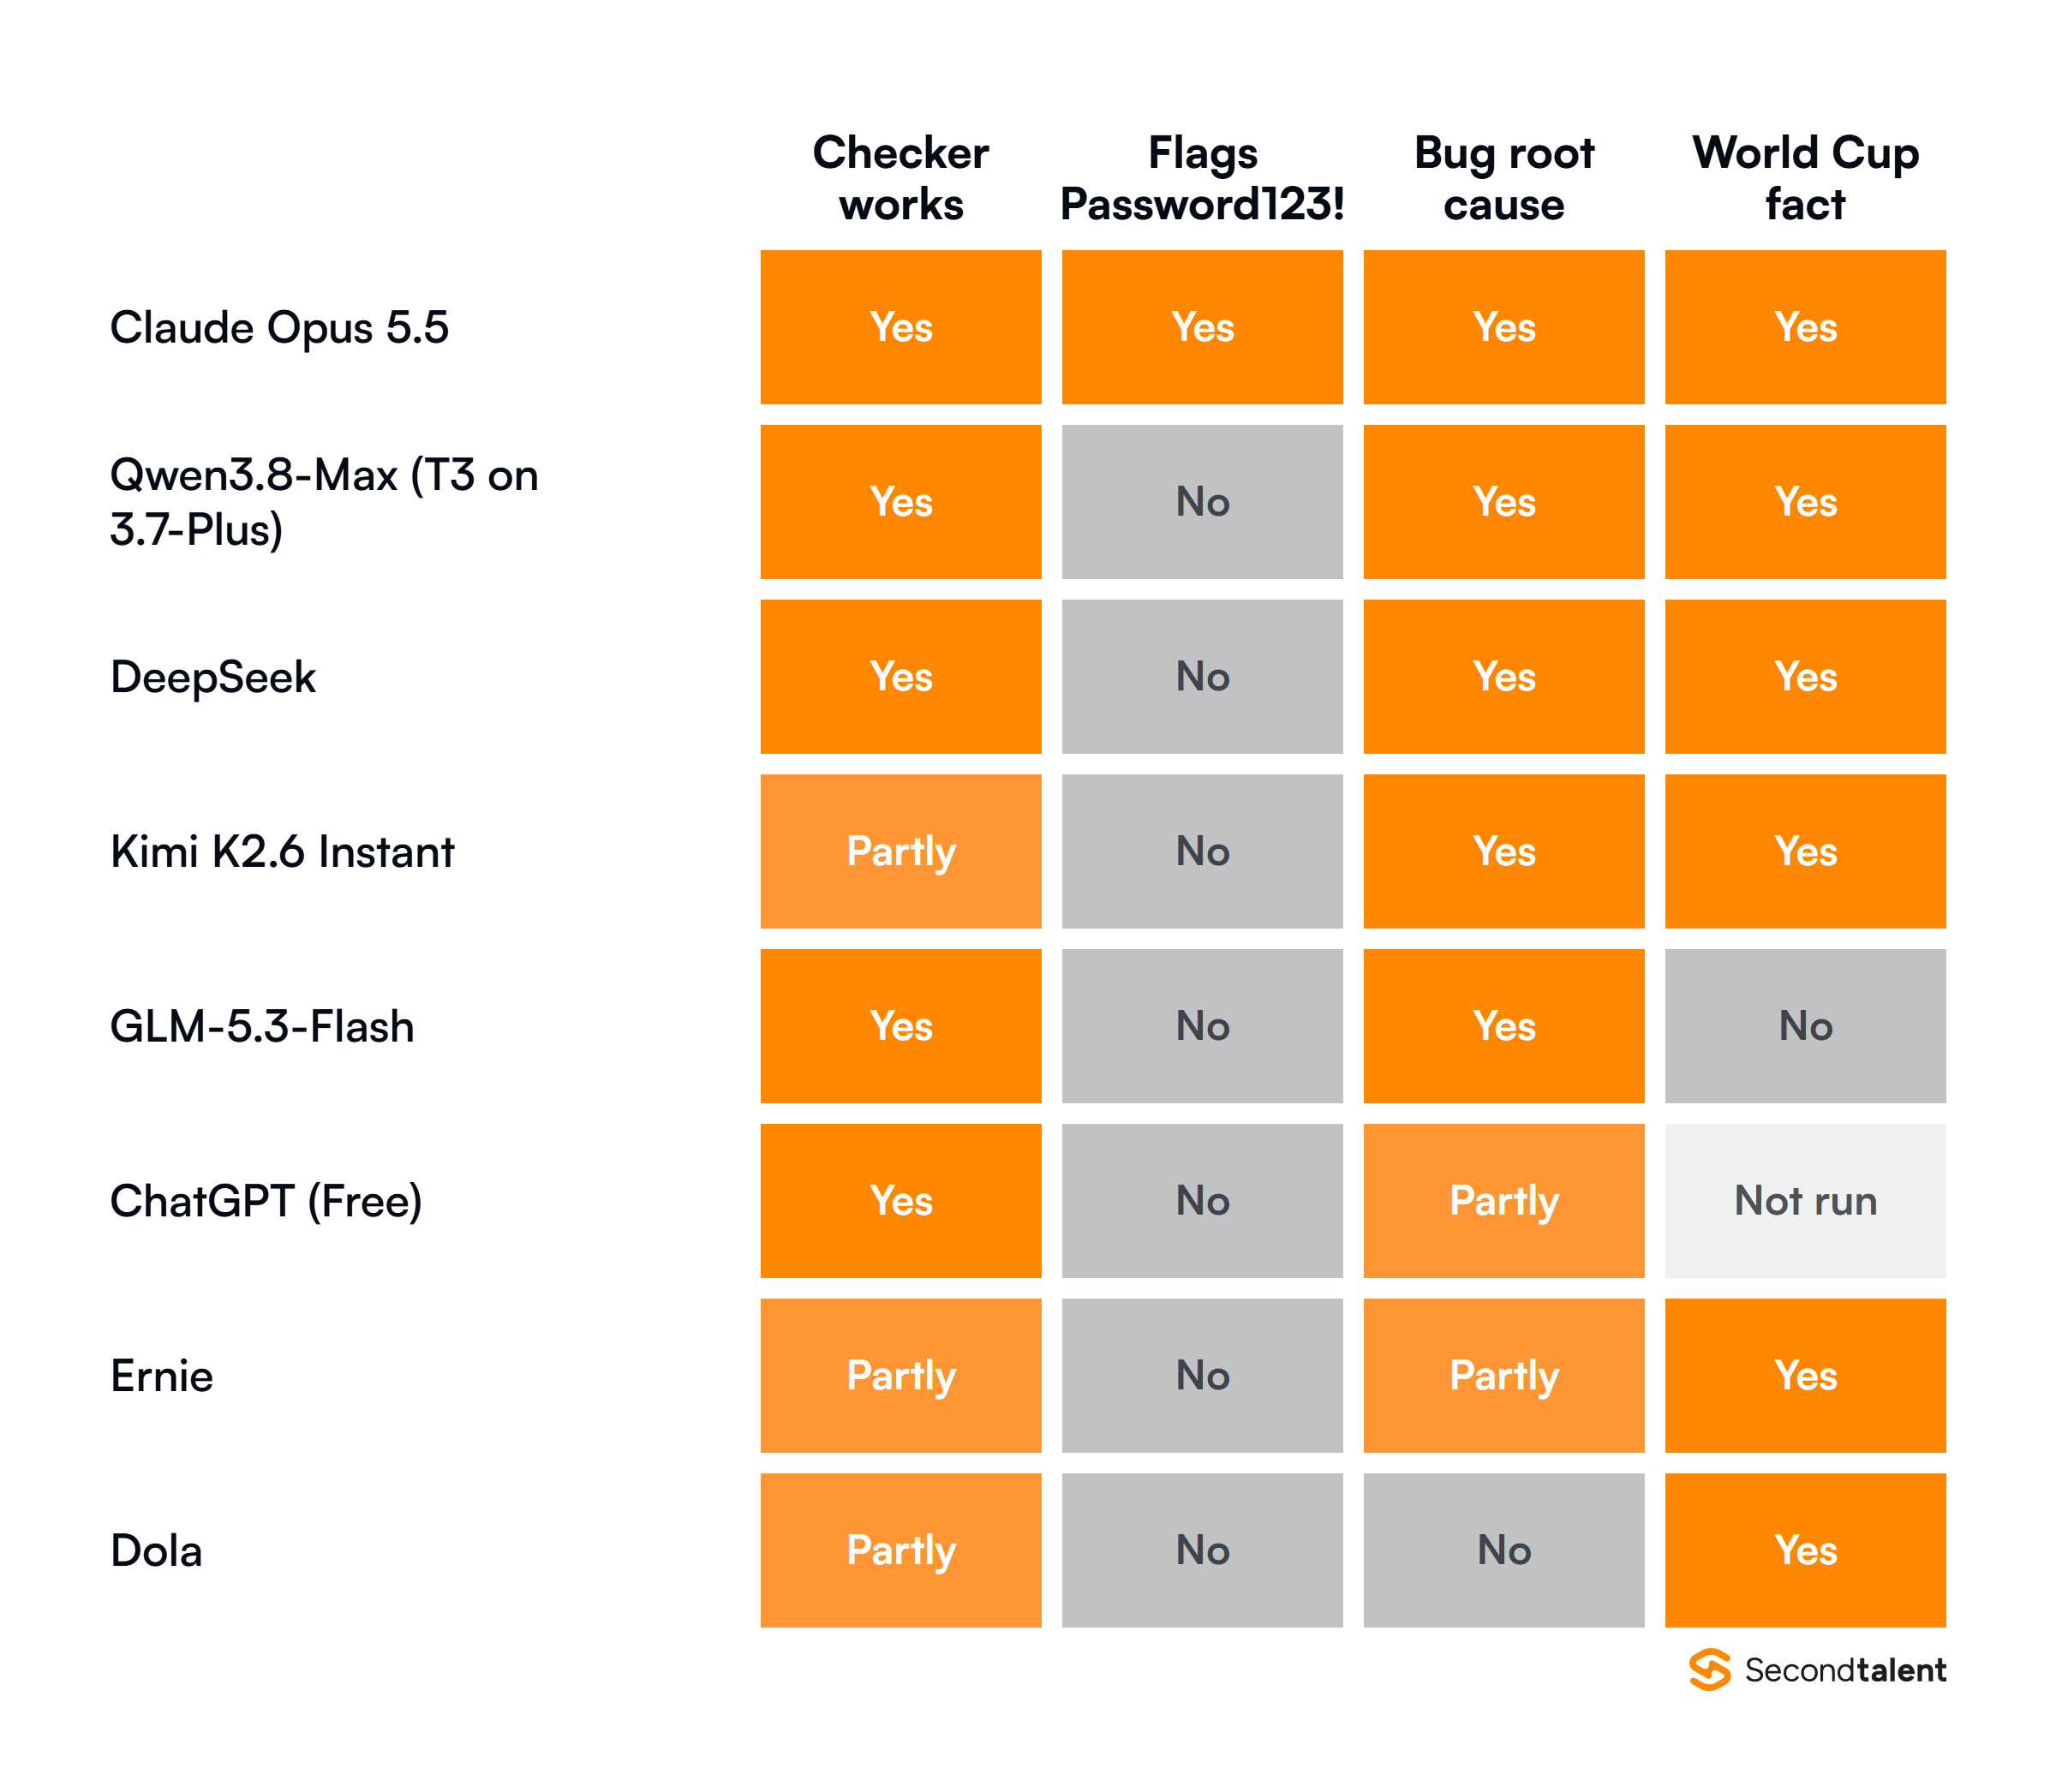
Qwen finished with three passes out of four, level with DeepSeek and behind only Claude Opus 5.5, the one paid model in the test. All eight tools built a checker that worked.
The split came on the bug and the fact check: Dola blamed the sort direction and returned a "fix" that still subtracts strings, and GLM-5.3-Flash said Argentina beat France.
Claude Opus 5.5, same checker prompt
~2 min, live preview in the chat
Flags Password123! as weak (common-password and pattern checks)
abcDef7!xyzQ9k: 78 bits, strong
Qwen3.8-Max, guest
~6 min, Copy and Download only, no preview
Rates Password123! strong at 78.8 bits
abcDef7!xyzQ9k: 92.0 bits, strong, plus a password generator
Source: Second Talent hands-on test, 17 November 2026.
Three things set Qwen apart from the other Chinese chatbots we tried. It answered in English throughout, while Ernie replied to our English prompts in Chinese. It needed no login, where DeepSeek and Kimi did.
And it was the slowest at code, about a minute slower than GLM's long "Max effort" thinking. Our Chinese AI chatbots roundup covers which of them work outside China.
Qwen's SWE-bench Pro score rose from 38.7 to 67.7 in fourteen months, and the biggest jumps came from general models, not the coder line.
SWE-bench Pro gives a model real repository issues to fix and checks the fix against the project's tests; it is harder than the older SWE-bench Verified, where scores in the 70s are now common.
Read across cards with care. Every figure above is self-reported on a Qwen model card, and the harnesses differ: the Qwen3.6 card used Qwen's internal agent scaffold, the Qwen3.8-27B card ran its rivals through the Claude Code harness, and the Qwen3-Coder cards name no scaffold.
The Qwen3.8 model card sets the flagship against Western models. Qwen3.8-Max is a 2.4-trillion-parameter mixture-of-experts model with 95 billion parameters active per token:
Benchmark
Qwen3.8-Max
Claude Opus 4.8
GPT 5.6 Sol (max)
Qwen3.7-Max
SWE-bench Pro
67.7
69.2
64.6
60.6
Terminal Bench 2.1
86.6
84.6
88.8
74.5
DeepSWE 1.1
56.6
59.0
73.0
21.6
The small model is the bigger surprise. The Qwen3.8-27B card reports 61.7 on SWE-bench Pro and 90.3 on LiveCodeBench v6, both above the 53.4 and 88.8 it lists for Claude Opus 4.6 Max.
On Terminal Bench 2.1, Opus 4.6 Max still leads, 78.2 to 73.0.
Qwen3-Coder-Next shows how far a tiny active footprint goes. Its model card lists 70.6 on SWE-bench Verified, 44.3 on SWE-bench Pro and 64.3 on SWE-bench Multilingual from 3 billion active parameters.
The older Qwen3-Coder-480B needs 35 billion active to score 38.7 on SWE-bench Pro.
One correction to figures still quoted around the web, including our own earlier version of this page: the 69.6 on SWE-bench Verified belongs to Qwen3-Max-Instruct, a general model from 2025, not to a Qwen Coder release.
Qwen Code CLI: install, models and the end of the free tier
Qwen Code is Alibaba's open-source answer to Claude Code: an agent that runs in your terminal, reads your repository, edits files and runs commands.
Version 0.28.0 shipped on the day of our test, and the GitHub repository has 30.7k stars under an Apache 2.0 licence.
Jul 22, 2025
Qwen Code launches with Qwen3-Coder, adapted from Gemini CLI
Mar 20, 2026
Coding Plan Lite closes to new subscribers
Apr 15, 2026
Free Qwen OAuth tier ends, after a cut to 100 requests a day
Oct 10, 2026
Hosted Qwen3-Coder models retired on Model Studio, replaced by qwen3.7-plus
Nov 17, 2026
Qwen Code v0.28.0 released
Sources: Qwen blog, Alibaba Cloud Model Studio docs, Decrypt, GitHub releases.
The free ride is over. Qwen Code shipped alongside Qwen3-Coder in July 2025 (Qwen's launch post), and until this spring a Qwen account came with free hosted requests.
Decrypt reported that Alibaba cut that quota from 1,000 requests to 100 a day and then ended the free tier on 15 April 2026. The CLI itself stays free; the inference behind it now costs money.
Install it with npm (Node.js 22 or newer) and start it inside a project:
npm install -g @qwen-code/qwen-code@latest
cd your-project
qwen
Inside the session, /auth offers five routes: a Qwen account with a Plus or Pro subscription, QwenCloud, Alibaba Model Studio, third-party providers and a custom provider.
The agent speaks the OpenAI, Anthropic, Gemini and Qwen APIs, so you can point it at a local Ollama or vLLM server instead. It ships plugins for VS Code, Zed and JetBrains, plus a desktop app.
A "1.0 Preview" branch merges in the agent harness from Qoder, Alibaba's AI editor.
What Qwen costs for coding
The newest flagship, qwen4-max, costs less than qwen3.8-max: $1.50 in and $4.50 out per million tokens, against $2 and $6, on Alibaba Cloud Model Studio's price list for the International (Singapore) region.
Alibaba has not published coding benchmarks for qwen4-max yet, so we have not ranked it.
Prices step up with prompt length. qwen3-coder-flash charges $0.30 / $1.50 up to 32K input tokens, then $0.50 / $2.50 to 128K, $0.80 / $4 to 256K and $1.60 / $9.60 to 1M, and the whole request bills at the tier its input lands in.
qwen3.7-plus jumps from $0.40 / $1.60 to $1.20 / $4.80 past 256K. Coding agents send whole files, so long-context tiers decide the bill more than the headline rate.
Heavy agent users can pay a flat rate instead. The Coding Plan Pro costs $50 a month for up to 6,000 requests per five-hour window, 45,000 a week and 90,000 a month.
The plan covers qwen3.7-plus, qwen3.6-plus and qwen3.5-plus alongside Kimi K2.5, GLM-5 and MiniMax M2.5, and it plugs into Qwen Code, Claude Code, Cursor, Cline and OpenCode.
Alibaba sells it "first-come, first-served" with limited availability.
Running Qwen coding models locally
Qwen3.8-27B is the local pick: Ollama's qwen3.8:27b is an 18 GB download with a 256K context window and image input. That is small enough for a single 24 GB graphics card or a 32 GB Mac.
ollama run qwen3.8:27b
Qwen3-Coder-Next is heavier on disk and lighter on compute. Ollama lists it at 52 GB in 4-bit and 85 GB in 8-bit, because all 80 billion parameters must sit in memory even though 3 billion run per token.
The 4-bit build needs more than 52 GB of free memory, so a 32 GB laptop cannot load it.
Check the num_ctx setting before you point an agent at a repository: a short context window makes the model lose the top of the file it is editing.
Moving a team off a retired model ID, wiring Qwen Code into CI, or serving Qwen3.8-27B on your own GPUs is work for an LLM engineer.
Our LLM developer cost guide puts mid-level contract rates at $119 to $185 an hour in the US, against $39 to $94 in Vietnam. We place vetted LLM developers from Asia, with a shortlist in about 24 hours.
Yes, in two ways. Guest chat at chat.qwen.ai costs nothing and includes Qwen3.8-Max, and the open-weight models run free on your own hardware. Since April 2026 you pay for hosted API calls, including the inference behind the Qwen Code CLI.
Is there a newer Qwen Coder model than Qwen3-Coder?
Qwen3-Coder-Next, released in February 2026, is the latest model with "Coder" in the name. Since then Qwen has put its coding gains into general models: Qwen3.6, Qwen3.8 and qwen4-max.
Is Qwen better than Claude for coding?
Not in our test. Claude Opus 5.5 passed all four checks, while Qwen missed the common-password check and took three times as long on the build task.
On Qwen's own benchmark table, Qwen3.8-Max trails Claude Opus 4.8 on SWE-bench Pro and DeepSWE but leads it on Terminal Bench 2.1, at a lower API price.
Get developers who ship with AI agents. Starts at $25/Hour.
Matt Li is a tech-driven entrepreneur with deep expertise in global talent strategy, digital experience optimization, e-commerce, and Web3 innovation.
He is the Co-Founder of Second Talent, a US-based company that connects businesses with top-tier tech professionals worldwide. Since launching the company in 2024, Matt has led its growth by leveraging technology to streamline remote hiring and scale distributed teams.
With a background spanning product, operations, and innovation, Matt brings a cross-disciplinary perspective to the evolving digital economy. His work sits at the intersection of global talent, emerging technology, and scalable digital transformation.