Skip to content

Top 30 Terraform Interview Questions and Answers [2026]

October 12, 2026 17 min read
Terraform interview guide by Second Talent
TL;DR: Terraform interviews in 2026 test state and locking, for_each versus count, module design, refactoring with moved, import and removed blocks, and a safe CI/CD workflow. Candidates should know that Terraform 1.16 is current, that S3 now locks state without DynamoDB, and that ephemeral values keep secrets out of state.

Terraform 1.14, released on November 19, 2025, added two blocks that do things Terraform never did before: action, which triggers an operation such as invoking a Lambda function outside the create, update and delete model, and list, which queries existing infrastructure so it can be imported.

The core of an interview has not moved, though. Most of the hard questions are still about state: who holds it, what is in it and how to change it without destroying production.

Key takeaways
  1. 1The current release is Terraform 1.16.4 (September 23, 2026); 1.16.0 shipped on August 26, 2026 with import blocks allowed inside modules.
  2. 2The AWS provider moved to major version 6 in June 2025 and the AzureRM provider to version 5 in July 2026.
  3. 3HashiCorp archived CDK for Terraform on December 10, 2025; cdktf synth --hcl is the exit path to plain HCL.
  4. 4OpenTofu, the open-source fork, is on 1.12 and added end-to-end state encryption back in version 1.7.

State and Workflow

1. What happens during terraform init, plan and apply?

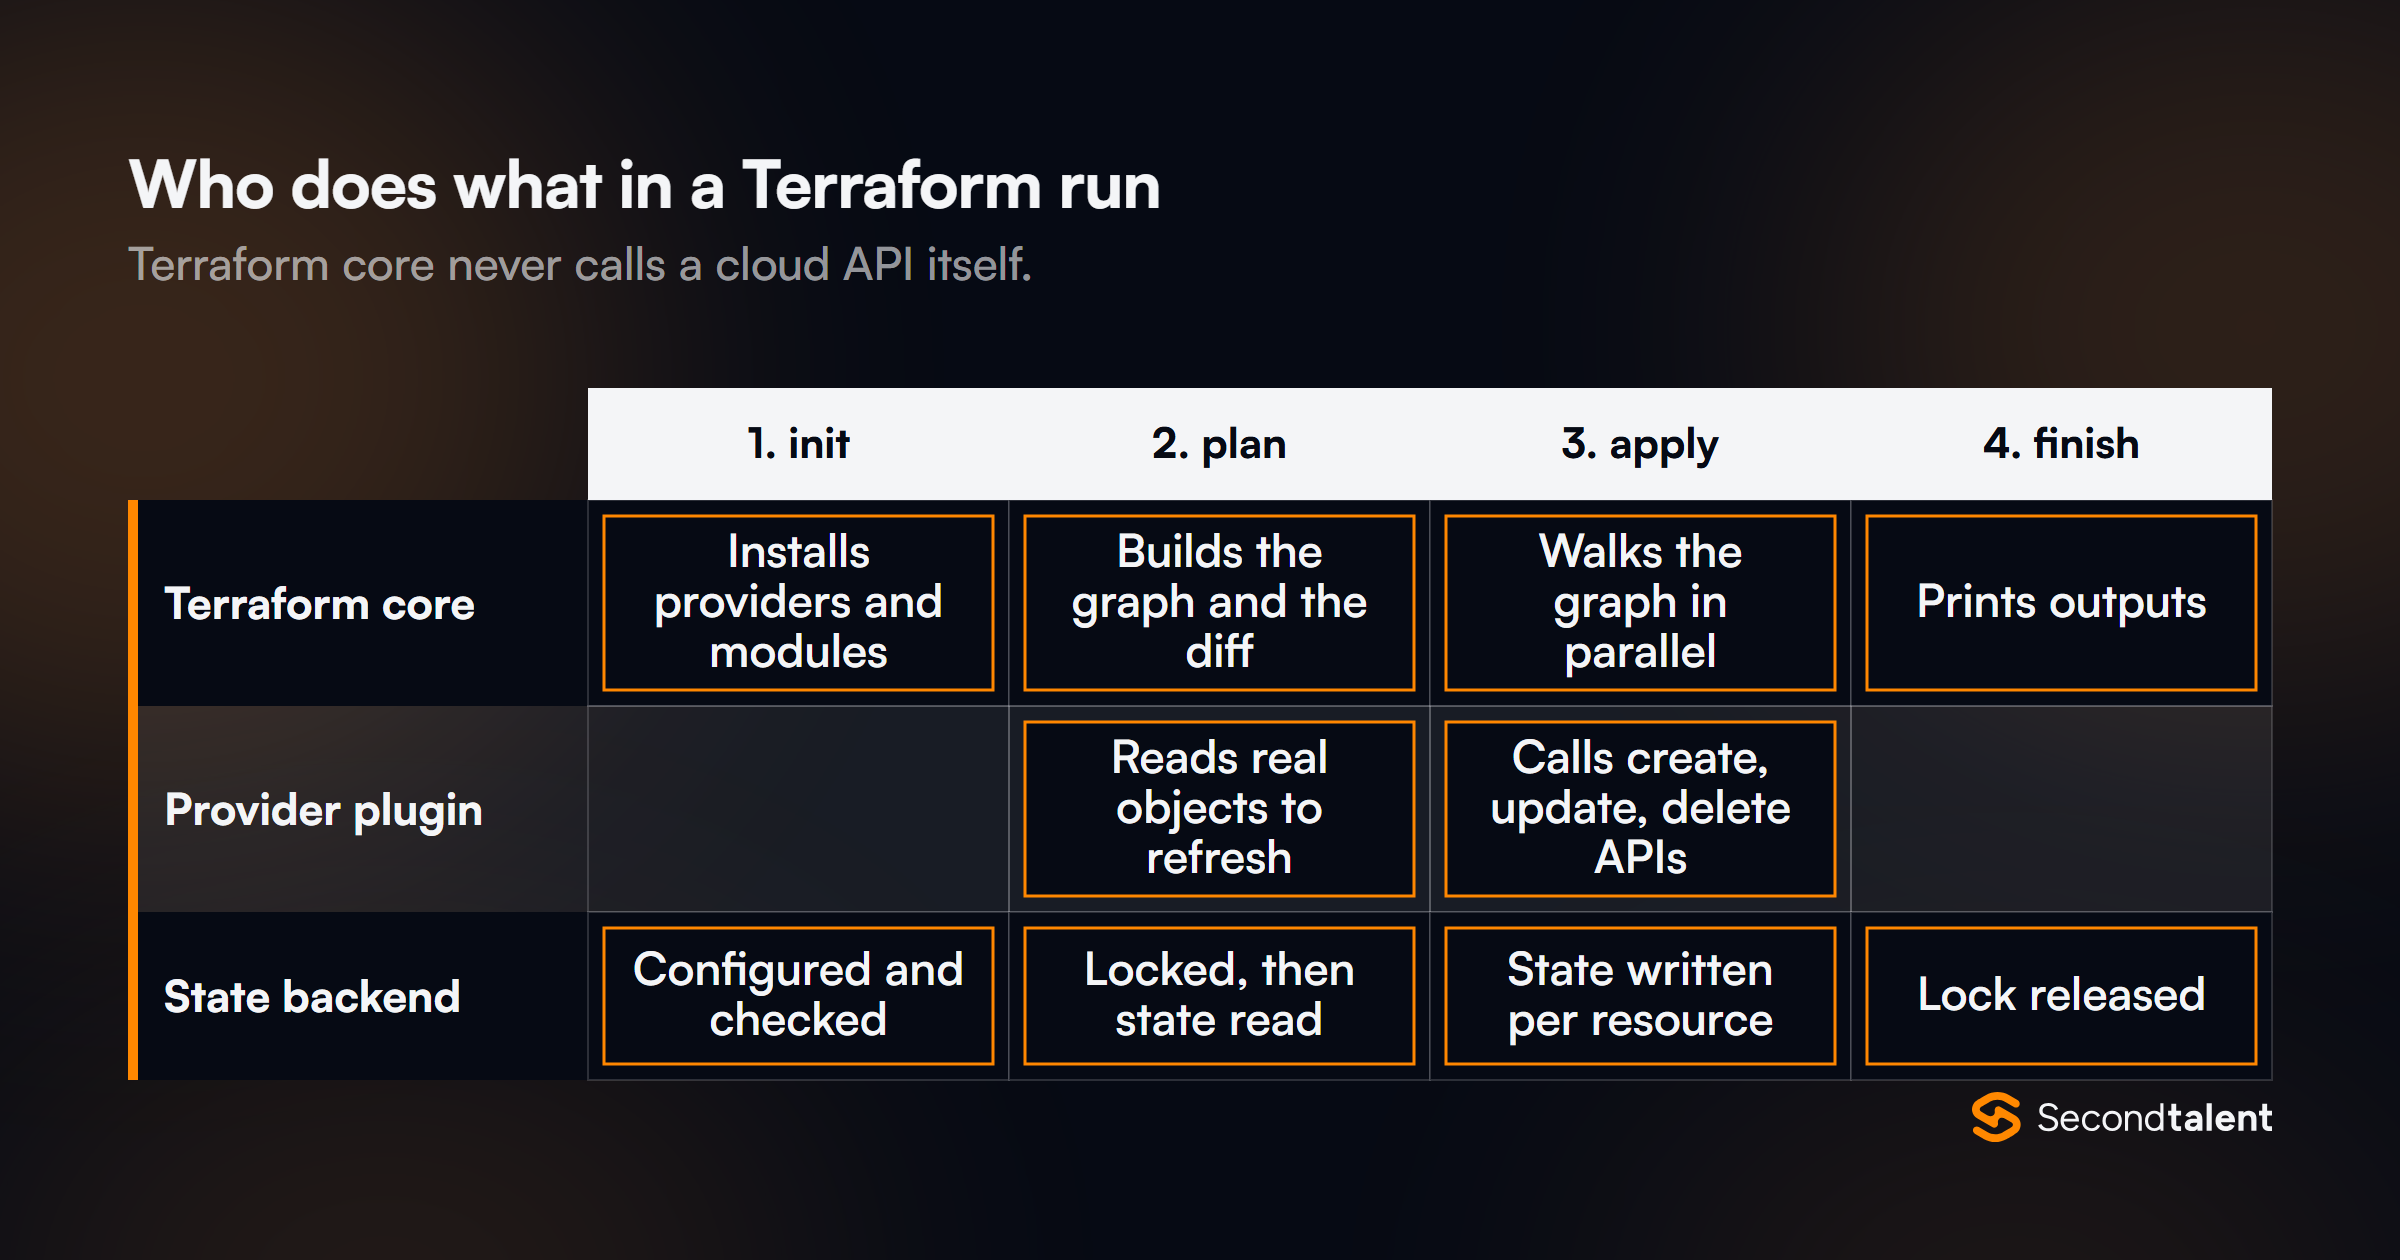
init configures the backend, downloads providers matching the version constraints and the dependency lock file, and downloads modules. plan refreshes state from the real infrastructure, compares it with the configuration and builds a dependency graph of proposed changes. apply executes that graph, running independent changes in parallel (10 at a time by default) and writing state as each resource finishes.

Swimlane of a Terraform run across Terraform core, the provider plugin and the state backend: init installs providers and configures the backend, plan locks and reads state while the provider refreshes real objects and core builds a diff, apply executes the graph through provider API calls, and state is written as each resource finishes before the lock is released.

Terraform core never calls a cloud API itself. Every read and write goes through a provider plugin over gRPC, which is why the same workflow manages AWS, Kubernetes, GitHub or Datadog.

In CI, save the plan with plan -out=tfplan and apply exactly that file, so what was reviewed is what runs.

2. What is Terraform state, and why is it sensitive?

State maps each resource address in the configuration to a real object ID and records its attributes.

Terraform needs it to know what it manages, to compute diffs without querying every attribute, and to track dependencies for destroy order.

sensitive is not encryption. State stores attribute values in plain text, including database passwords and private keys that providers return. Marking a variable sensitive only hides it from CLI output; the value is still in state.

So state belongs in an encrypted remote backend with tight access, never in Git. Ephemeral values and write-only attributes (question 26) are the fix for keeping secrets out of it.

3. How does state locking work, and what changed for S3?

Before any operation that can write state, Terraform takes a lock in the backend, so two people or pipelines cannot apply at once and corrupt it.

If a run crashes, the lock stays until someone runs terraform force-unlock with the lock ID, after confirming no other run is active.

For the S3 backend, use_lockfile = true now locks with a lock object in the bucket itself, using S3 conditional writes.

It was added in Terraform 1.10 and became generally available in 1.11, and the S3 backend docs mark DynamoDB-based locking as deprecated. Both can run together during a migration.

terraform {
  backend "s3" {
    bucket       = "acme-tf-state"
    key          = "prod/network.tfstate"
    region       = "us-east-1"
    encrypt      = true
    use_lockfile = true
  }
}

4. How do you detect and handle drift?

Drift is a difference between state and real infrastructure, usually from a change made in the console. terraform plan detects it during refresh and proposes to put things back. terraform plan -refresh-only shows only what changed outside Terraform, and apply -refresh-only accepts those changes into state without touching the infrastructure.

The old terraform refresh command is deprecated, because it updated state with no review step.

Then decide per change: revert it by applying, adopt it by updating the code, or add ignore_changes for attributes another system owns, such as an autoscaling group's desired count.

Scheduled plan-only runs in CI catch drift before it surprises the next deploy.

5. What is the dependency lock file, and how should version constraints be set?

.terraform.lock.hcl records the exact provider versions and their checksums selected by init. Commit it, so every machine and pipeline uses the same provider builds; terraform init -upgrade moves to newer versions within the constraints.

In root modules, pin providers with a pessimistic constraint such as ~> 6.0 (any 6.x) and pin required_version for Terraform itself.

In reusable modules, set only a minimum (>= 5.0), because a tight upper bound in a shared module blocks every caller from upgrading.

HCL and Resources

6. When do you use for_each instead of count?

Use for_each whenever instances have an identity. count addresses instances by index, so removing the first element of a list shifts every index, and Terraform plans to destroy and recreate everything after it. for_each addresses instances by key, so removing one key affects only that instance.

variable "buckets" {
  type    = set(string)
  default = ["logs", "assets"]
}

resource "aws_s3_bucket" "this" {
  for_each = var.buckets
  bucket   = "acme-${each.key}"
}
# addresses: aws_s3_bucket.this["logs"], aws_s3_bucket.this["assets"]

count still suits "zero or one" conditionals (count = var.enabled ? 1 : 0) and truly identical copies. The keys of a for_each must be known at plan time, so they cannot come from attributes of resources that do not exist yet.

7. What problem do dynamic blocks solve, and when are they a smell?

A dynamic block generates repeated nested blocks, such as ingress rules on a security group, from a collection. It lets a module accept a list of rules instead of hard-coding them.

They become a smell when used for every nested block "for flexibility": the module becomes a thin, harder-to-read wrapper around the resource.

Many providers now model such rules as separate resources, for example aws_vpc_security_group_ingress_rule, which can be managed with for_each and avoid dynamic blocks entirely.

8. How do you validate input variables?

With validation blocks on the variable: a condition and an error message, checked before planning. Since Terraform 1.9, conditions can refer to other variables and objects in the module, not only the variable being validated.

variable "environment" {
  type = string
  validation {
    condition     = contains(["dev", "staging", "prod"], var.environment)
    error_message = "environment must be dev, staging or prod."
  }
}

Add precise types too: object({ name = string, size = optional(number, 20) }) catches mistakes that any or map(string) let through.

Terraform 1.15 added a deprecated argument on variables and outputs, which warns callers still using an input you plan to remove.

9. How does Terraform order operations, and when do you need depends_on?

Terraform builds a graph from references: if a subnet references aws_vpc.main.id, the VPC is created first and destroyed last. Most ordering is implicit and needs nothing extra.

depends_on is for dependencies Terraform cannot see, such as an IAM policy that must exist before an EC2 instance's startup script calls an API.

Use it sparingly: on a module or data source, it can make values unknown until apply and turn small plans into wide ones.

A data source reads existing infrastructure; if it reads something the same configuration creates, reference the resource directly instead.

10. Explain the lifecycle meta-arguments.

  • create_before_destroy: when a change forces replacement, create the new object first, then destroy the old one. Needed for anything in use, such as a launch template or a certificate.
  • prevent_destroy: any plan that would destroy the resource fails. A guard for databases and state buckets, though removing the resource block removes the guard too.
  • ignore_changes: ignore differences in listed attributes, for values another system manages.
  • replace_triggered_by: replace this resource when a referenced resource or attribute changes.

Preconditions and postconditions also live in lifecycle: a precondition checks an assumption before Terraform acts on the resource, and a postcondition checks the result, such as an AMI's architecture.

11. What is a check block, and how does it differ from a postcondition?

A check block, added in Terraform 1.5, holds assertions about the infrastructure as a whole, optionally with its own scoped data source, and runs on every plan and apply.

A failed check produces a warning, not an error, so it never blocks a deploy.

check "api_health" {
  data "http" "health" {
    url = "https://api.example.com/health"
  }
  assert {
    condition     = data.http.health.status_code == 200
    error_message = "API health check did not return 200."
  }
}

A postcondition belongs to one resource and fails the run. Use postconditions for guarantees the rest of the configuration relies on, and checks for ongoing validation that should alert but not stop.

Modules and Environments

12. What makes a good Terraform module?

A clear purpose with a small interface: a module for "a private S3 bucket with our encryption and logging defaults" is useful; a module that wraps one resource and passes every argument through adds a layer and nothing else.

Inputs are typed and validated, outputs expose what callers need, and the module has a README with an example.

Consume modules by a fixed version: a Git tag (?ref=v3.2.0) or a registry version constraint, never a moving branch.

Terraform 1.15 now allows variables and locals in module source and version, but the version still has to be resolvable at init, and pinning is still the rule.

13. How should providers be configured for child modules?

Reusable modules declare the providers they need in required_providers but do not contain provider blocks. The root module configures providers and passes them in, which is the only way to deploy one module to two regions or accounts:

provider "aws" {
  alias  = "eu"
  region = "eu-west-1"
}

module "replica_bucket" {
  source    = "./modules/bucket"
  providers = { aws = aws.eu }
}

A module with its own provider block cannot use count or for_each, and removing it from the configuration leaves resources that Terraform can no longer destroy, because their provider configuration went with it.

14. Workspaces, separate directories or Terragrunt for environments?

CLI workspaces give one configuration several state files.

They fit identical, short-lived copies such as per-branch test stacks, but prod and dev share the same code and backend, so a mistake in terraform workspace select is a production incident.

CLI workspaces
  • One configuration, one backend, several states
  • Good for identical, short-lived copies
Directory per environment
  • Own backend and credentials per environment
  • Differences visible in code review

Separate root directories per environment, each with its own backend, calling shared versioned modules, make differences explicit and allow different credentials.

Terragrunt reduces the repetition in that layout: backend configuration, provider generation and dependencies between stacks.

HCP Terraform workspaces are a different thing again, closer to separate root modules with their own variables, runs and permissions.

15. How would you split state in a large organization?

By blast radius and rate of change. Networking changes rarely and breaks everything; application stacks change daily.

Separate states, typically network, shared data stores, and one per service per environment, keep plans fast, limit the damage from a bad apply and let teams own their stacks.

Stacks share data through outputs. terraform_remote_state works but grants read access to the whole other state, secrets included; reading published values from SSM Parameter Store, a data source on the real resource, or HCP Terraform's output sharing is safer.

The trade-off to name: more states mean more ordering between applies, which Terragrunt or HCP Terraform Stacks manage.

Refactoring and Import

16. How do you rename or move a resource without destroying it?

With a moved block, added in Terraform 1.1. It tells Terraform the object at the old address is now at the new one, and the plan shows a move instead of a destroy and create:

moved {
  from = aws_s3_bucket.logs
  to   = aws_s3_bucket.this["logs"]
}

It works for renames, moving into or out of modules, and switching from count to for_each. Unlike terraform state mv, it is code: it goes through review, runs in CI and applies to every workspace that uses the module.

Keep moved blocks in shared modules for a few releases so every caller migrates.

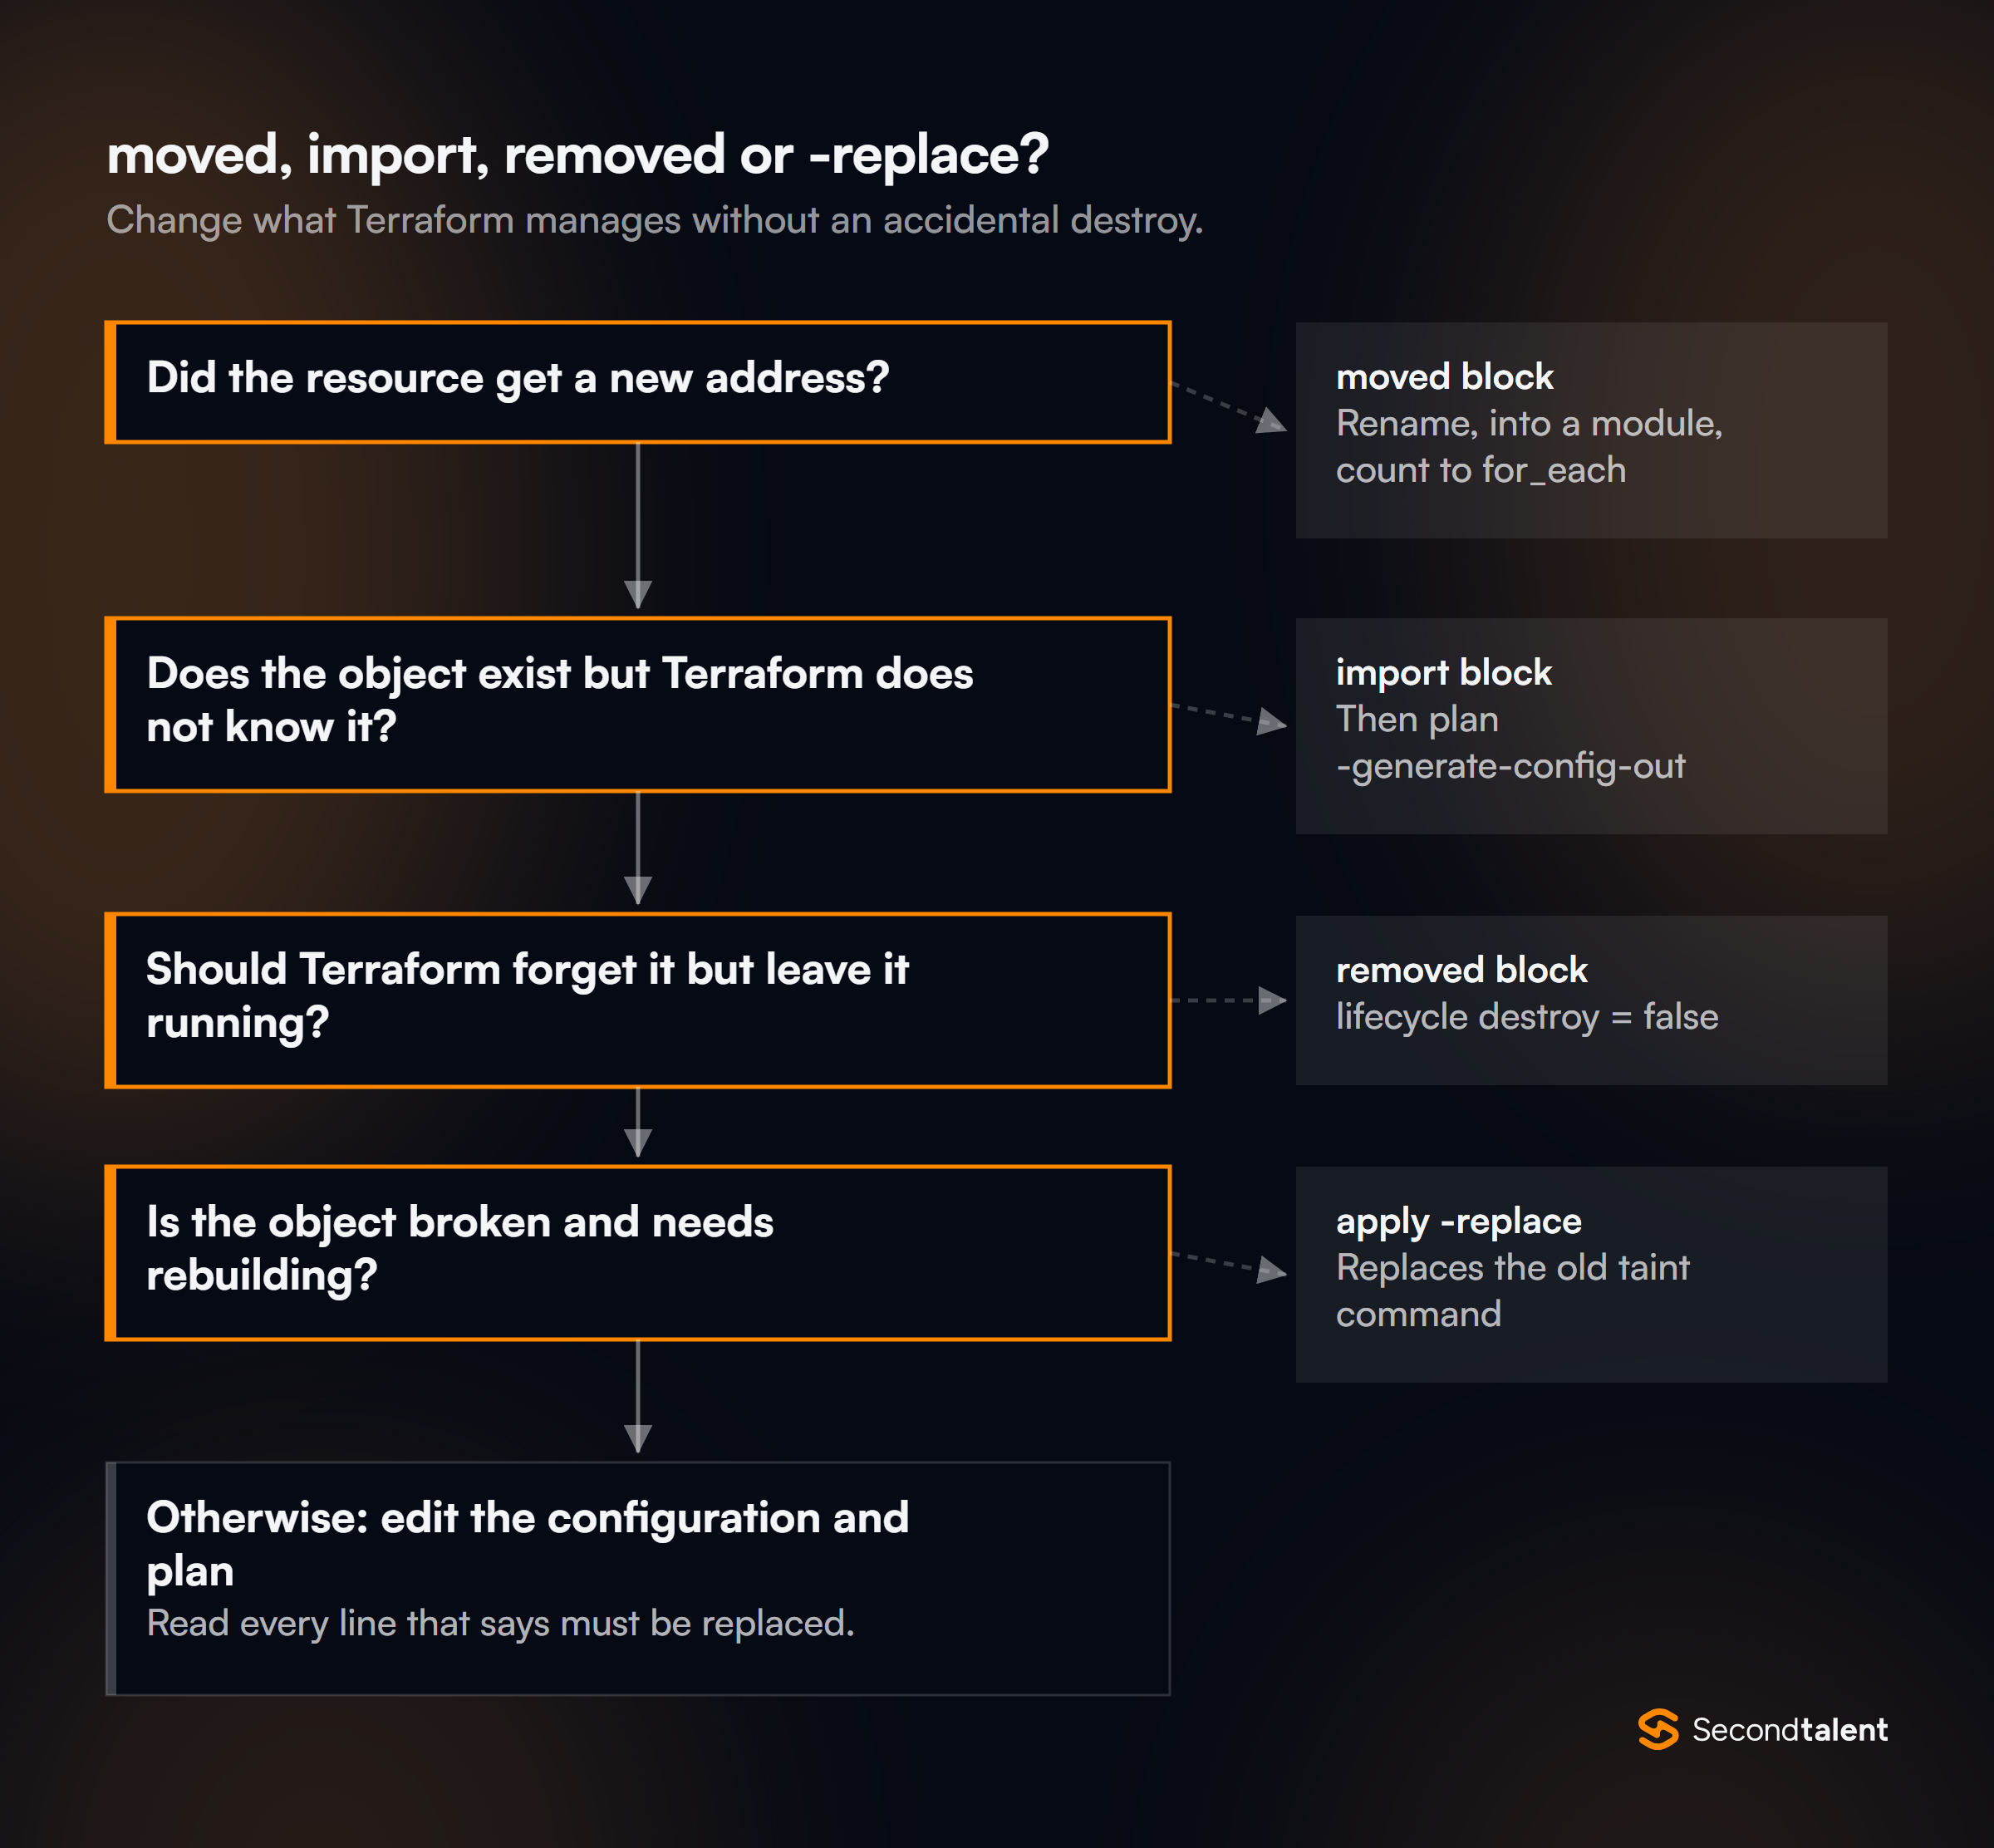
Decision flow for changing what Terraform manages: a renamed or moved resource needs a moved block, an existing object Terraform should adopt needs an import block, an object Terraform should forget but keep needs a removed block with destroy set to false, a damaged object needs apply with -replace, and otherwise edit the configuration and plan.

17. How do you bring existing infrastructure under Terraform?

With import blocks, added in Terraform 1.5. Import becomes part of a normal, reviewable plan instead of a one-off CLI command that writes straight to state:

import {
  to = aws_s3_bucket.legacy
  id = "acme-legacy-assets"
}

terraform plan -generate-config-out=generated.tf writes starter configuration for imported resources, which you then clean up.

Since 1.7, import blocks accept for_each to import many resources at once, and Terraform 1.16 allows them inside modules. For a whole account, the terraform query command from question 28 can list what exists and generate the import blocks.

18. How do you stop managing a resource without deleting it?

With a removed block, added in Terraform 1.7, and destroy = false:

removed {
  from = aws_s3_bucket.legacy
  lifecycle {
    destroy = false
  }
}

Terraform forgets the object and leaves it running, for example when another team's stack takes ownership.

The older way, terraform state rm, does the same from the CLI but leaves no record in code, and every workspace has to run it by hand. Deleting the resource block without either tells Terraform to destroy the object.

19. What do -replace and -target do, and why use them carefully?

terraform apply -replace=aws_instance.web forces one resource to be destroyed and recreated, for example a VM whose disk is corrupted. It replaced terraform taint, which is deprecated because it marked state before anyone saw a plan.

-target limits a plan to some resources and their dependencies.

It is an escape hatch for recovering from errors, not a workflow: the rest of the configuration is not checked, so state and code drift apart, and Terraform itself warns that the plan may be incomplete.

A team that uses -target routinely usually has a state that should be split.

Team Workflow

20. Describe a safe CI/CD workflow for Terraform.

  • On every pull request: fmt -check, validate, a linter such as TFLint, a security scan such as Checkov or Trivy, terraform test, and a plan posted to the PR for review.
  • After merge: apply the saved plan for that commit, with a manual approval for production.
  • Credentials: short-lived tokens through OIDC federation from GitHub Actions or GitLab to AWS, Azure or GCP, never long-lived keys in CI variables.
  • One apply at a time per state, enforced by the backend lock and by pipeline concurrency settings.

Our CI/CD interview guide covers the pipeline side, such as OIDC and pinned actions, in more depth.

21. How do you handle secrets in Terraform?

Keep them out of code, plan files and state. Read them at run time from a secret manager, mark variables sensitive to keep them out of output, and, on Terraform 1.10 and later, make them ephemeral so Terraform does not persist them at all.

The strongest answer is to have the cloud generate and own the secret: for example, let RDS manage the master password in Secrets Manager (manage_master_user_password = true) so Terraform never sees it.

Where Terraform must pass a secret to a resource, use a write-only attribute (question 26). And encrypt the state backend regardless, because older providers still store secrets there.

22. What is policy as code for Terraform?

Rules evaluated against the plan before apply: no public S3 buckets, only approved instance types, mandatory tags, a cost ceiling.

HCP Terraform and Terraform Enterprise run Sentinel or OPA policies as a step in each run, with advisory, soft-mandatory and hard-mandatory enforcement levels.

Outside HCP Terraform, teams run OPA with Conftest, or Checkov, against terraform show -json output in CI.

Policy on the plan catches what the code will do, including values that come from variables, which a static scan of .tf files can miss. A strong candidate mentions both layers: static scans for fast feedback, plan policies as the gate.

23. How do you test Terraform code?

With terraform test, generally available since 1.6. Tests live in .tftest.hcl files as run blocks that plan or apply the module and assert on the result:

run "creates_two_buckets" {
  command = plan
  assert {
    condition     = length(aws_s3_bucket.this) == 2
    error_message = "expected two buckets"
  }
}

command = plan tests are fast and need no real resources; apply tests create real infrastructure and destroy it afterwards. Since 1.7, mock_provider and overrides let apply-mode tests run without cloud credentials.

Terratest in Go remains the choice for end-to-end tests that call the deployed service.

24. How would you upgrade a major provider version across many stacks?

Read the provider's upgrade guide first. The AWS provider's 6.0 release in June 2025 and AzureRM's 5.0 in July 2026 both removed deprecated resources and arguments, and some changes force replacement.

Then upgrade one low-risk stack: bump the constraint, run init -upgrade, fix errors and deprecation warnings, and read the plan for anything that says "must be replaced".

Roll out stack by stack, oldest risk last, and commit the lock file with each. Fixing deprecation warnings on the old major version before the jump makes the upgrade itself small.

The same approach applies to Terraform versions: required_version keeps anyone on an older CLI from writing a newer state format.

25. Scenario: an apply failed halfway and the state lock is stuck. What do you do?

First, confirm no run is still active: check the CI job and the lock's owner and timestamp in the error message. Only then run terraform force-unlock <LOCK_ID>.

Next, run a plan. Terraform writes state as each resource completes, so resources created before the failure are usually already tracked, and the plan shows what remains.

If the state itself is damaged, restore an earlier version from the backend's versioning (S3 bucket versioning, or state versions in HCP Terraform) and reconcile with a -refresh-only plan and import blocks for anything created but not recorded.

Candidates who say "delete the state and start again" fail this question.

What Changed Recently

Nov 27, 2024
1.10: ephemeral values and resources, S3 native locking
Feb 27, 2025
1.11: write-only attributes; S3 locking GA, DynamoDB locking deprecated
Nov 19, 2025
1.14: action blocks, list resources and terraform query
Apr 29, 2026
1.15: variables in module sources, deprecated variables and outputs
Aug 26, 2026
1.16: import blocks in modules, terraform_data store block

26. What are ephemeral values and write-only attributes?

Terraform 1.10 added ephemeral input variables, outputs and resources: values that exist during a run but are never written to the plan file or state.

An ephemeral resource, such as a secret read from a secret manager, is fetched fresh in each phase.

Ephemeral values could not be stored in normal resource arguments, so Terraform 1.11 added write-only attributes: arguments a provider accepts but never saves, typically with a _wo suffix and a version argument that you bump to trigger an update.

Together they let Terraform set a database password without the password ever landing in state, per the 1.11 release notes.

27. What are Terraform actions?

Introduced in Terraform 1.14, an action block declares a provider-defined operation outside the create, read, update and delete model, such as invoking a Lambda function or creating a CloudFront invalidation.

Actions run when a resource's lifecycle action_trigger fires, for example after create or update, or on demand with terraform apply -invoke=action.aws_lambda_invoke.example.

They replace many local-exec provisioners and null_resource hacks with something the provider implements and the plan shows. Terraform 1.16 added before_destroy and after_destroy events and on_failure modes (halt, taint or continue).

Provisioners remain the last resort.

28. What does terraform query do?

Terraform 1.14 added list blocks, written in .tfquery.hcl files, and the terraform query command, per the 1.14 release notes.

A list block asks a provider for existing resources of a type, with filters, and terraform query prints the results and can generate configuration and import blocks for them.

It turns "import everything in this account" from a scripting project into a reviewable plan. It depends on providers implementing list resources, so coverage varies by resource type.

29. What did Terraform 1.15 and 1.16 change for module authors?

1.15 (April 29, 2026) allowed variables and locals in module source and version, added a deprecated attribute for variables and outputs, explicit type constraints on outputs, a convert function, and validation of the backend block in terraform validate.

It also added native Windows ARM64 builds.

1.16 (August 26, 2026) allowed import blocks inside modules, added a store block on terraform_data that holds ephemeral and sensitive values across plan and apply, -json output for state show and workspace list, and Mermaid output for terraform graph.

The 1.16 changelog lists the rest.

30. How do the license change, OpenTofu and the end of CDKTF affect tool choice?

HashiCorp moved Terraform from the MPL to the Business Source License from version 1.6 in 2023. Using Terraform to manage your own infrastructure is allowed; offering a competing hosted Terraform product is not.

OpenTofu, a community fork of the last MPL version, stays largely compatible, and has added features Terraform lacks, starting with state encryption in OpenTofu 1.7.

HashiCorp, now an IBM company, archived CDK for Terraform on December 10, 2025, saying it "did not find product-market fit at scale". Teams on CDKTF should export to HCL with cdktf synth --hcl or move to Pulumi.

A good answer compares the options on license, features the team needs and the registry and support it depends on, not on loyalty.

Signs of a Strong Answer

  • They treat state as production data: encrypted, locked, versioned and never edited by hand without a backup.
  • They use moved, import and removed blocks instead of state mv, import and state rm commands, and can say why.
  • They pick for_each by default and can predict what a plan does when a list element is removed under count.
  • They read a plan for "must be replaced" before approving it, and know which attribute forced it.
  • They keep secrets out of state with ephemeral values, write-only attributes or cloud-managed credentials.
  • They can argue Terraform versus OpenTofu on license and features rather than habit.

Hiring Terraform Engineers

Engineers who can refactor a live Terraform codebase without a destroy in the plan are rarer than those who can write a module.

Second Talent matches companies with pre-vetted DevOps engineers and cloud engineers from Asia, screened with questions like these.

Tell us the stack and we send a shortlist within 24 hours. Start hiring, or continue with our AWS and Kubernetes interview guides.

Ready to hire? Hire DevOps Engineers: vetted AI-native talent, with first profiles in 24 hours.

Get developers who ship with AI agents. Starts at $25/Hour.

Start Hiring $0 cost until you hire