TL;DR: CI/CD interviews in 2026 test how a candidate designs a pipeline that builds once and promotes the same artifact, picks a release strategy, and keeps the pipeline itself from becoming the attack path. Candidates should know DORA's current five delivery metrics and why pinning third-party actions to a commit SHA became standard after the March 2025 tj-actions compromise.
GitHub removed Node 20 from its Actions runners on September 23, 2026, so every JavaScript action now runs on Node 24. Workflows that still reference old action versions can break without a single line of their own changing.
That is a CI/CD lesson in miniature: the pipeline has dependencies too, and they need the same care as application code.
- 1The tj-actions/changed-files compromise hit over 23,000 repositories by moving existing version tags to a malicious commit.
- 2Since August 15, 2025, GitHub admins can fail any workflow that uses an action not pinned to a full commit SHA.
- 3Argo CD 3.0 (May 6, 2025) switched its default resource tracking from labels to annotations.
- 4v3 of
actions/upload-artifactanddownload-artifactstopped working on January 30, 2025.
Pipeline Basics
1. What is the difference between continuous integration, delivery and deployment?
Continuous integration merges small changes into the main branch often, with an automated build and tests on each one. Continuous delivery keeps every passing build ready to release, with the final push to production a business decision.
Continuous deployment removes that last manual step: every change that passes the pipeline goes live.
A strong candidate says which one their team practiced and why. Regulated products often stop at continuous delivery because a release needs a sign-off. That is a valid choice, not a failure of automation.
2. Compare trunk-based development with GitFlow.
Trunk-based development keeps one main branch that everyone merges into at least daily, through short-lived branches. GitFlow keeps long-lived develop, release and feature branches.
Trunk-based development suits continuous delivery. Merges stay small, conflicts stay rare, and the pipeline has one path to production. It depends on fast tests and on feature flags to hide unfinished work.
GitFlow fits software shipped as numbered versions with several supported releases, such as a desktop app or a library. For a web service, it mostly adds merge work and slows feedback. See trunkbaseddevelopment.com.
3. What does "pipeline as code" give you?
It puts the pipeline definition in the repository, as a .github/workflows/*.yml, .gitlab-ci.yml or Jenkinsfile. Changes to the pipeline then go through the same review, history and rollback as application code.
It also means a pull request can change its own pipeline. That is a security question: branch protection and required reviews must cover workflow files too, or a contributor can edit the pipeline to leak secrets.
4. Why should a pipeline build the artifact only once?
So the thing you tested is exactly the thing you release. If staging and production each rebuild from source, a changed base image or dependency can make the two builds differ.
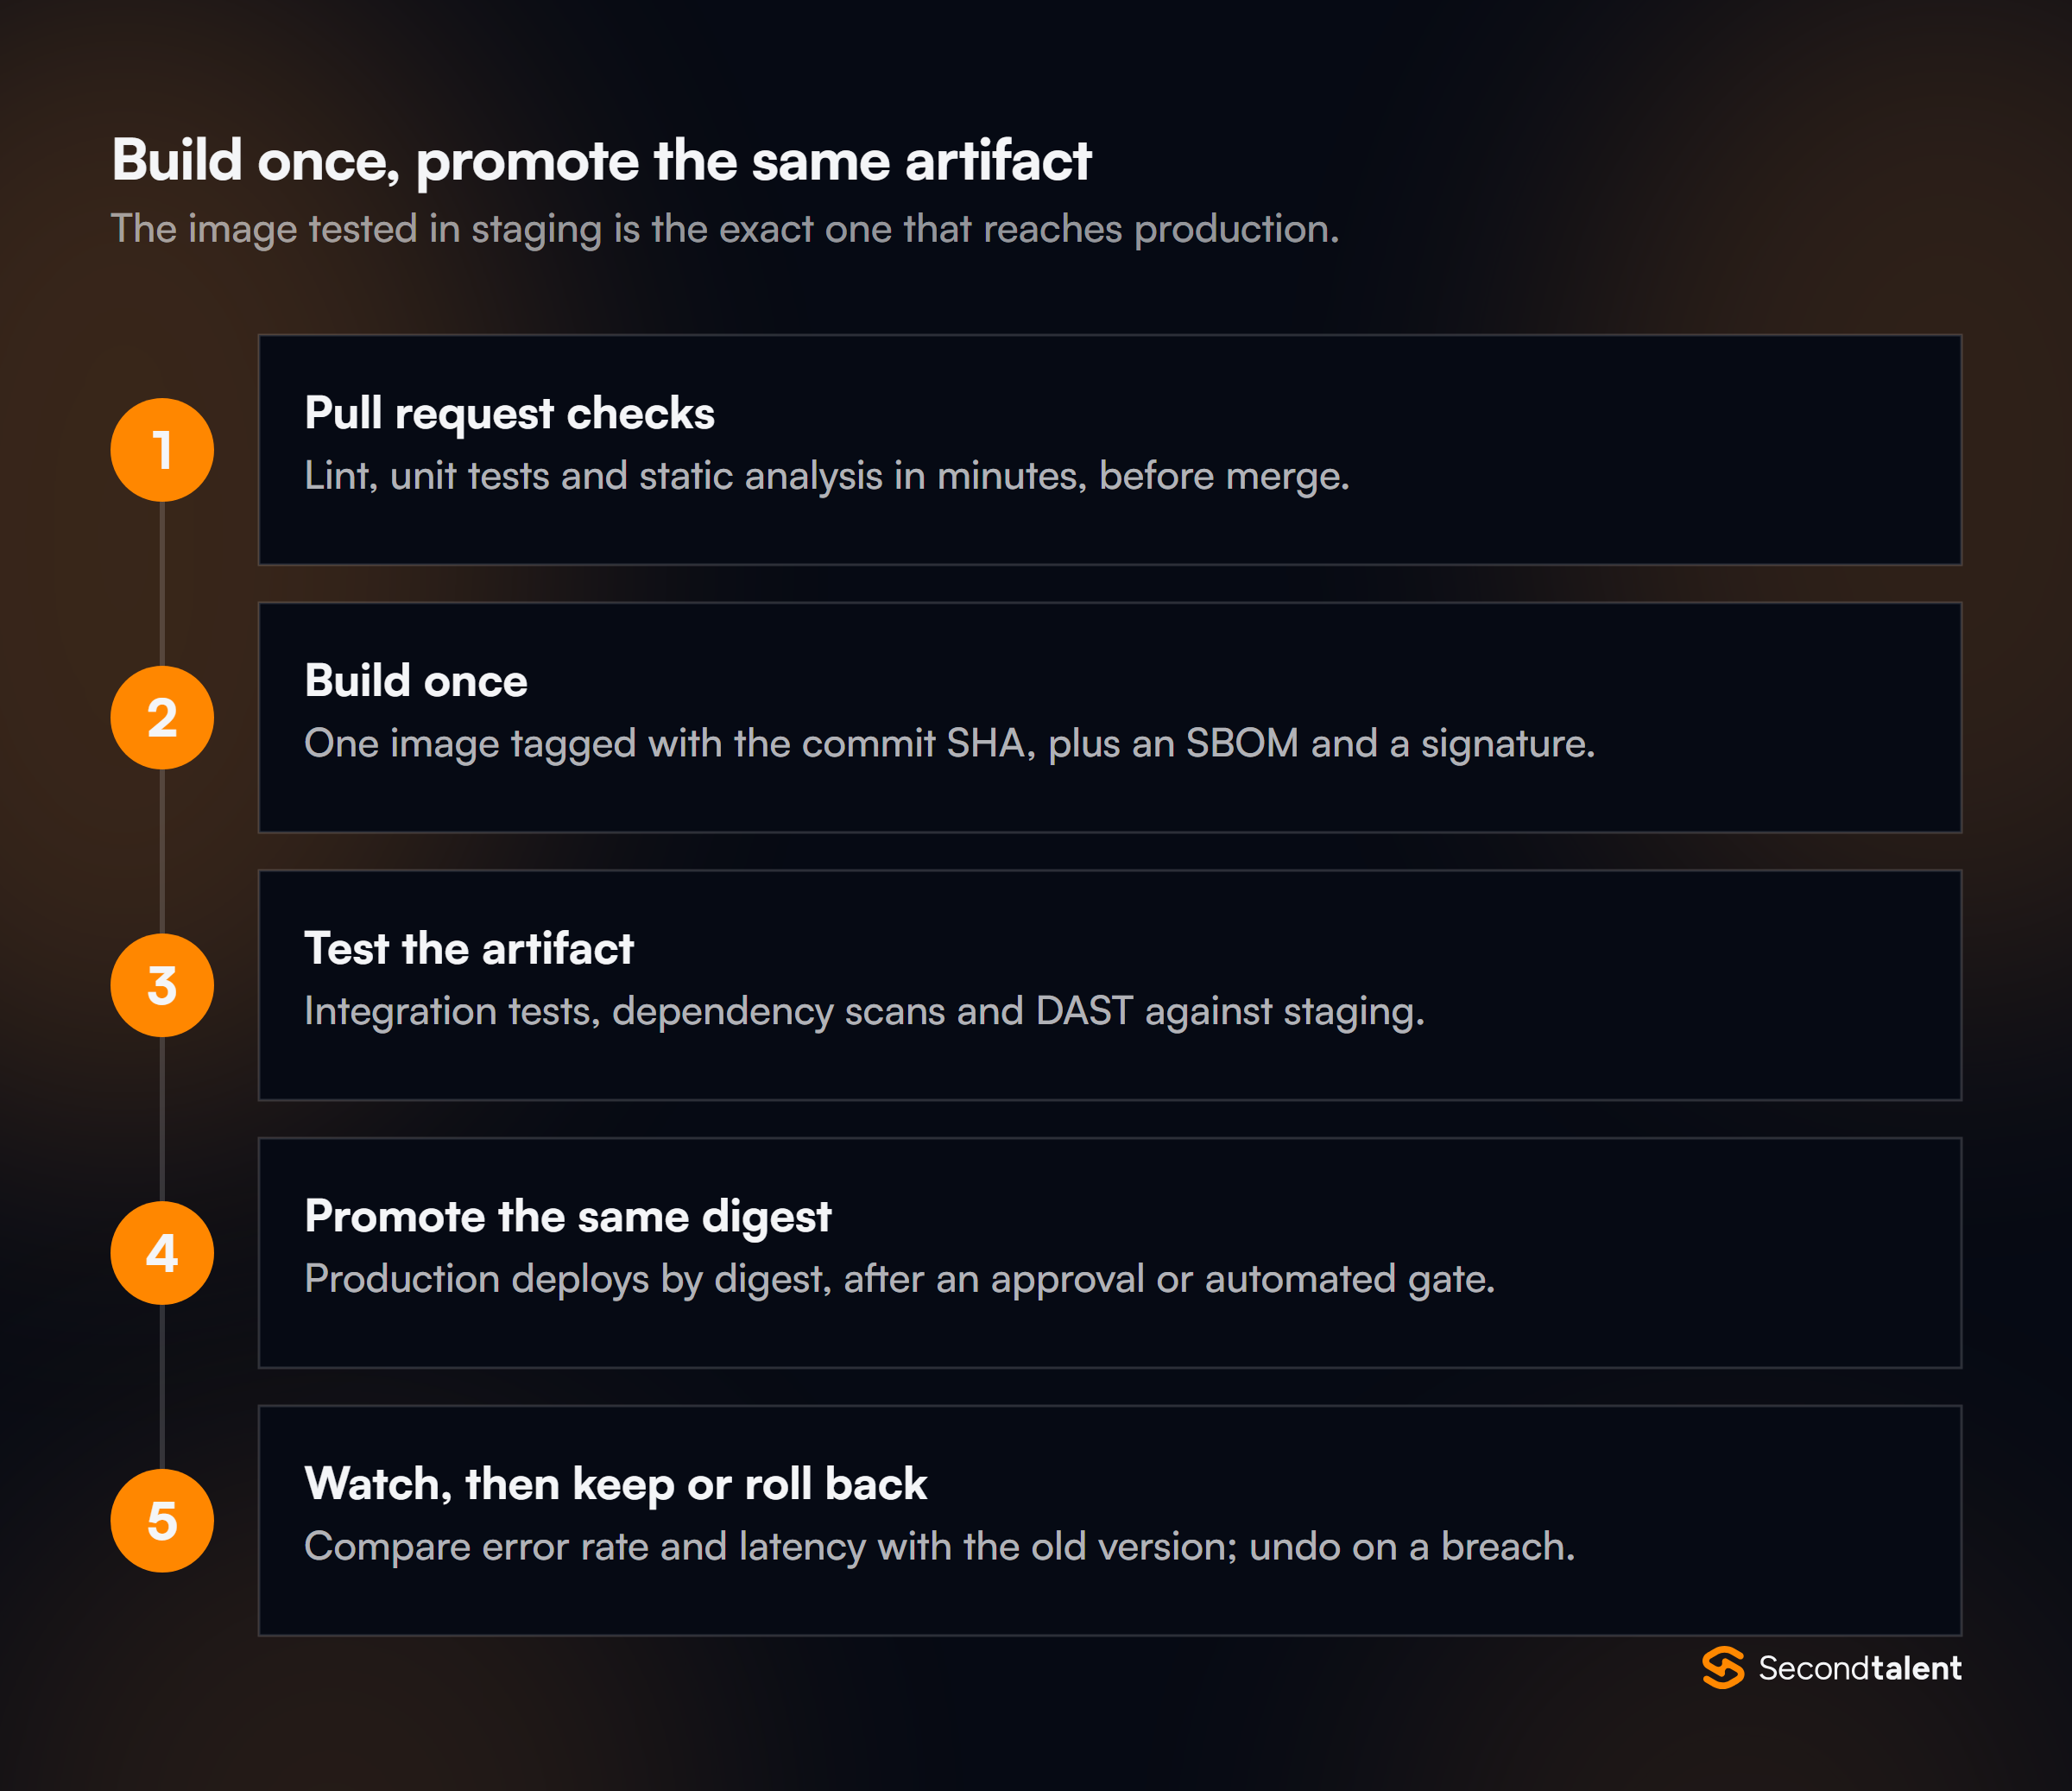
Build one image, tag it with the commit SHA, and deploy it everywhere by its digest. Configuration that differs per environment comes from environment variables or a config service, not from a rebuild.
Promotion then means pointing the next environment at the same digest.
5. What CI/CD problems does a monorepo create, and how do you solve them?
The main problem is building and testing only what changed. A naive pipeline runs every test for every commit, which gets slow and expensive as the repository grows.
The fixes are path filters that trigger only affected jobs, and build tools that know the dependency graph, such as Bazel, Nx or Turborepo, with remote caching.
Polyrepos have the opposite problem. Each repo is simple, but a change to a shared library must be versioned, published and then picked up by every consumer, often through automated dependency update pull requests.
6. How do you avoid copying the same pipeline into fifty repositories?
Put the shared steps in one place and call them with parameters. Each CI system has its own mechanism:
- GitHub Actions: reusable workflows for whole jobs, composite actions for groups of steps.
- GitLab CI:
includeof shared templates, and CI/CD components. - Jenkins: shared libraries.
jobs:
  deploy:
    uses: my-org/pipelines/.github/workflows/deploy.yml@v3
    with:
      service: orders-api
      environment: staging
    secrets: inherit
Version the shared templates like a library, so a change to them can be rolled out and rolled back in steps.
7. A pipeline takes 40 minutes. How do you speed it up?
Measure first: find which jobs sit on the critical path, then attack those. The usual fixes, roughly in order of payoff:
- Cache dependencies and Docker layers between runs.
- Run independent jobs in parallel, and split large test suites across runners.
- Run only the tests affected by the change on pull requests, and the full suite on main.
- Order Dockerfile steps so rarely changing layers come first.
- Use larger or closer runners for compile-heavy jobs.
A strong answer also names the goal. Teams usually aim for a pull request check that finishes in about ten minutes, because slower feedback makes people batch changes.
8. How do you deal with flaky tests?
Treat a flaky test as a bug, not as noise. A test that fails at random teaches the team to rerun until green, and then real failures get ignored too.
Track failure rates per test, quarantine repeat offenders into a non-blocking job with an owner and a deadline, and fix the cause.
Common causes are shared state between tests, fixed sleeps instead of waiting for a condition, reliance on test order, and real network calls. Automatic retries hide the problem and should be a short-term patch at most.
Release Strategies
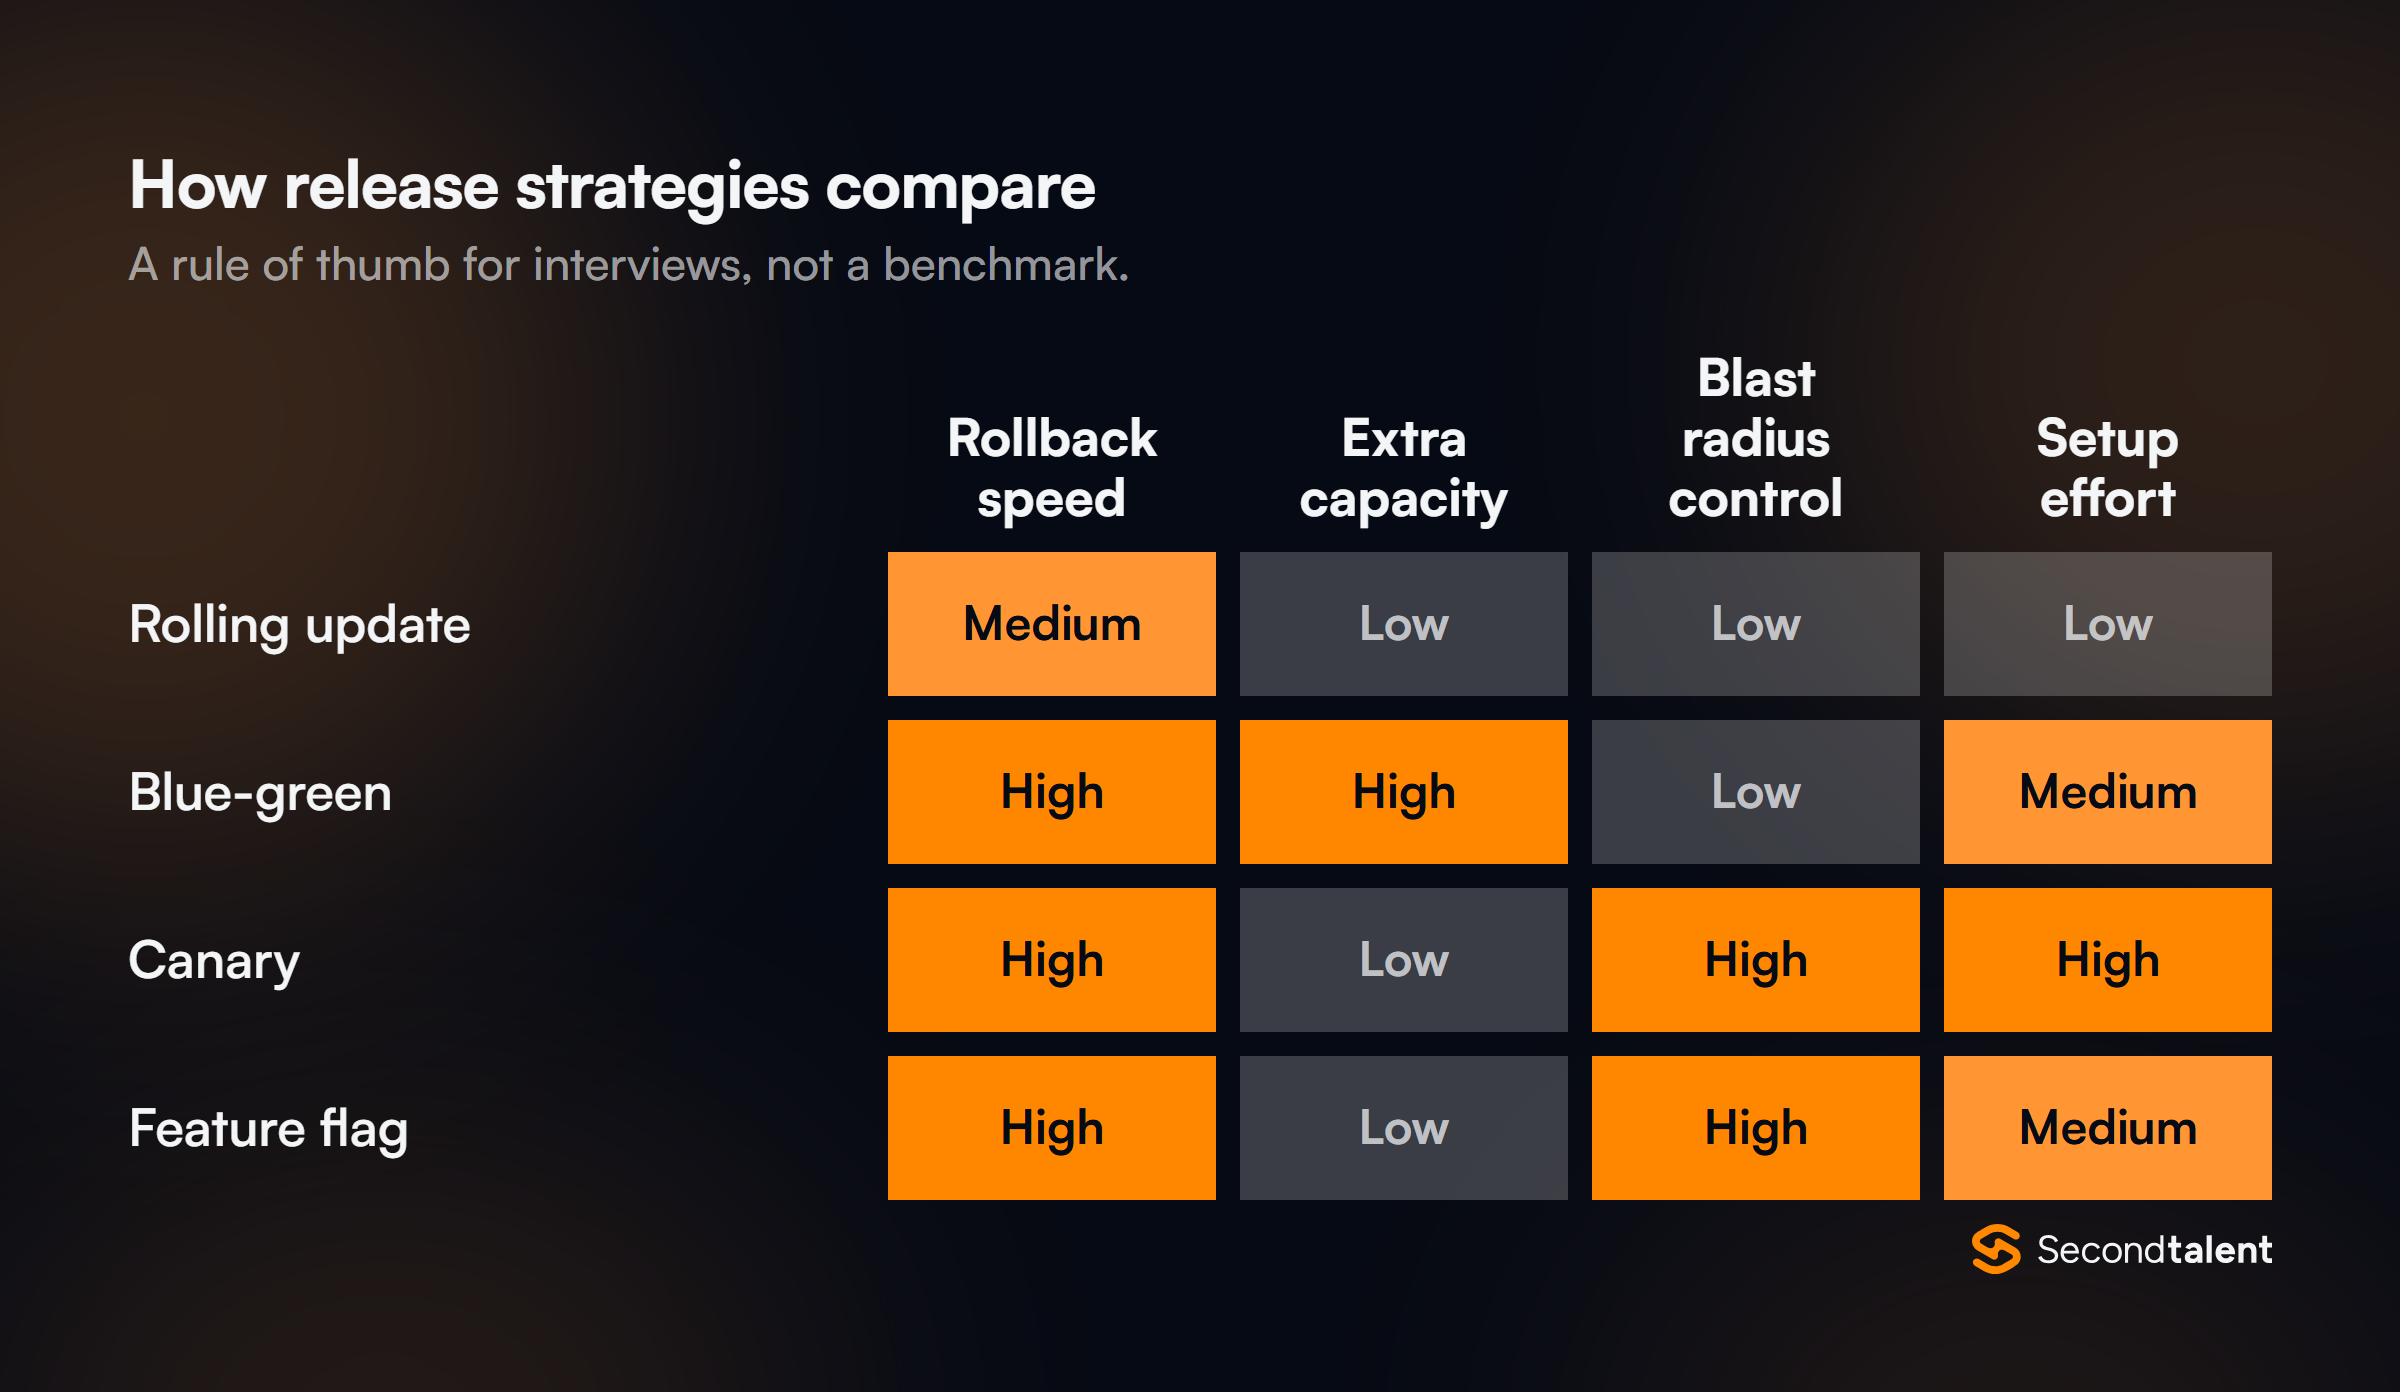
9. Compare rolling, blue-green and canary deployments.
They differ in how much traffic sees the new version at once and how fast you can undo it. A rolling update replaces instances a few at a time, so it needs little extra capacity, but a rollback is another rolling update.
Blue-green runs a full second environment and switches all traffic at once; switching back is instant, but you pay for double capacity during the release.
A canary sends a small share of traffic to the new version and grows it while metrics stay healthy. It gives the most control over blast radius but needs traffic splitting and good metrics. See Martin Fowler's note on canary releases.
10. How do feature flags change the release process?
They separate deploying code from releasing a feature. Code can ship to production switched off, then be turned on for staff, a beta group or a percentage of users, with no new deploy.
That supports trunk-based development and gives an instant kill switch. The cost is complexity: every flag is a branch in the code, so old flags must be removed. Keeping flags manageable is key.
Clear ownership, consistent naming, and safe rollouts are important feature flag best practices that help teams release safely without adding extra complexity.
Martin Fowler's feature toggles article separates release, experiment, ops and permission flags, which have very different lifespans.
11. How would you design an automated rollback?
Define the health signals before the deploy, watch them after it, and roll back automatically when they cross a threshold.
Typical signals are error rate, latency percentiles and a business metric such as checkouts per minute, compared against the previous version.
The rollback itself should be boring: redeploy the previous artifact digest, or shift canary traffic back. On Kubernetes, kubectl rollout undo deployment/api does it by hand, and tools such as Argo Rollouts or Flagger automate the analysis.
Rollback fails when a deploy also ran a database migration the old code cannot use, which leads to question 12.
12. How do you deploy database schema changes without downtime?
Use expand and contract, so old and new code both work at every step. First add the new column or table without removing anything. Then deploy code that writes to both and reads the new one, and backfill the data.
Remove the old column only in a later release.
Each step can be rolled back on its own. The rule a candidate should state: a migration in the same release as the code must be backward compatible with the previous code version. Renaming a column in one step is the classic outage.
13. What is GitOps?
GitOps keeps the desired state of the system in Git and uses an agent in the cluster to pull that state and apply it. The OpenGitOps principles describe the state as declarative, versioned, pulled automatically and continuously reconciled.
Argo CD and Flux are the common agents. The CI pipeline builds and pushes the image, then updates an image tag in a config repository. The agent sees the change and syncs the cluster.
The cluster needs no inbound credentials from CI, and every change has a commit to review and revert. Drift, such as a manual kubectl edit, gets detected and reverted.
14. How do you add approvals and gates between environments?
Model each target as an environment with its own rules, and let the pipeline pause until they pass. In GitHub Actions, deployment environments can require reviewers, a wait timer, or specific branches.
They also hold secrets that only jobs targeting that environment can read.
Keep manual approval for real decisions, such as a regulated release, and automate the rest with tests and metric checks. An approval that someone clicks without looking adds delay and no safety.
Pipeline Security
15. Where do SAST, SCA and DAST fit in a pipeline?
SAST and SCA run early on the code; DAST runs later against a running app. SAST scans source code for flaws such as injection, and it runs on every pull request.
SCA checks dependencies, including transitive ones, against known vulnerabilities. It runs on pull requests and on a schedule, because new CVEs appear for code that has not changed.
DAST attacks a deployed staging environment from outside, as a user would. Secret scanning belongs on every push.
A strong answer covers noise too: block the build only on high-severity findings with a fix available, or the team learns to ignore the scanner.
16. How should a pipeline get cloud credentials?
Through OpenID Connect, so no long-lived cloud key is stored in the CI system at all. The CI provider issues a short-lived signed token for the job. The cloud provider trusts that issuer and swaps the token for temporary credentials.
Per GitHub's OIDC docs, the trust policy can require claims such as the repository, branch or environment. A workflow on a fork or a feature branch then cannot assume the production role.
permissions:
  id-token: write
  contents: read
steps:
  - uses: aws-actions/configure-aws-credentials@<full-commit-sha>
    with:
      role-to-assume: arn:aws:iam::123456789012:role/deploy-prod
      aws-region: us-east-1
17. What are image signing, SBOMs and provenance for?
They let the deploy side check what an artifact is and where it came from before running it. A signature proves who built the image and that it has not changed. An SBOM lists the packages inside it.
A provenance attestation records which source commit and which build produced it.
Sigstore's cosign can sign keylessly, using the CI job's OIDC identity instead of a stored private key. A Kubernetes admission policy then rejects unsigned images or images from the wrong workflow.
The SLSA framework grades how far a build meets these supply chain goals.
18. How do you secure the pipeline itself?
Treat CI as production infrastructure with access to everything, because it has it. The main controls:
- Set the default
GITHUB_TOKENpermissions to read-only and raise them per job. - Never check out and run untrusted pull request code in a
pull_request_targetworkflow, which has secrets. - Pass untrusted inputs, such as issue titles, through environment variables, not straight into shell commands, to avoid script injection.
- Use ephemeral runners, one job per clean machine, especially for self-hosted runners.
- Protect workflow files with code owners and required reviews.
GitHub's secure use reference covers each of these.
19. Why pin third-party actions to a commit SHA?
Because a tag like v4 can be moved to different code at any time, and a full commit SHA cannot. Whoever controls the action's repository controls what your pipeline runs, with your secrets in reach.
- uses: actions/checkout@v7                      # tag: can be moved
- uses: actions/checkout@<40-character-sha>  # immutable
Pinning makes updates manual, so pair it with Dependabot or Renovate, which open pull requests with the new SHA and the release notes. Question 26 covers the attack that made this standard.
Infrastructure and Runners
20. How does infrastructure as code fit into CI/CD?
Infrastructure changes follow the same pull request flow as code. The pipeline runs terraform plan on the pull request and posts the output for review.
After merge, it runs terraform apply with the saved plan, so what was reviewed is what gets applied.
terraform plan -out=tfplan && terraform show -no-color tfplan > plan.txtState lives in a locked remote backend, never on a runner. Policy checks, such as Open Policy Agent or Checkov, can block risky plans, like a public bucket, before a person even reviews them.
21. Hosted or self-hosted runners?
Hosted runners are the default: clean machines per job, no upkeep, billed per minute. Self-hosted runners make sense when jobs need private network access, special hardware such as GPUs, or when build volume makes your own machines cheaper.
- A clean machine per job
- No patching or capacity planning
- No access to private networks by default
- Private network access, GPUs, custom images
- You own patching and isolation
- Must be ephemeral to be safe
The trade-off is security and upkeep. A long-lived self-hosted runner keeps files and credentials between jobs, so one malicious job can poison the next.
Run self-hosted runners as ephemeral containers or VMs, for example with Actions Runner Controller on Kubernetes. Never attach them to public repositories where anyone can open a pull request.
22. How do you stop two deploys from running at the same time?
Use a concurrency lock per environment. In GitHub Actions, a concurrency group allows one running job per group name.
concurrency:
  group: deploy-production
  cancel-in-progress: false
For deploys, keep cancel-in-progress false so a half-finished deploy is not killed. For pull request checks, set it to true so a new push cancels the outdated run and saves runner time.
23. What is the difference between a cache and an artifact?
A cache speeds up later runs and may be missing at any time; an artifact is an output you need to keep. Caches hold things like downloaded dependencies, keyed on a lockfile hash, and a job must still work on a cache miss.
Artifacts hold build outputs, test reports and coverage files, passed between jobs or kept for download. Container images belong in a registry, not in CI artifacts.
Mixing the two up leads to builds that pass only when a warm cache happens to exist.
Metrics and Feedback
24. What are the DORA metrics today?
DORA now lists five software delivery metrics, not four. The DORA metrics guide names them:
- Change lead time: from commit to running in production.
- Deployment frequency: how often you deploy.
- Failed deployment recovery time: how long it takes to recover from a deploy that needs immediate intervention.
- Change fail rate: the share of deploys that need immediate intervention.
- Deployment rework rate: the share of deploys that are unplanned and caused by a production incident.
Older material says "mean time to recovery" and stops at four. The rename narrows the metric to failures caused by deploys, not every outage.
25. How do you make the pipeline itself observable?
Track it like a service: duration per job, queue time, failure rate by cause, and flaky test counts, over time. A slow creep from 8 to 20 minutes goes unnoticed without a chart.
Most CI systems expose this through APIs or webhooks, and some emit OpenTelemetry traces with a span per job and step.
Tag failures by cause (test, infrastructure, dependency download) so the team fixes the biggest cause, not the most recent one.
What Changed Recently
26. What happened with tj-actions/changed-files, and what should teams learn from it?
Attackers moved the action's version tags to a malicious commit that dumped CI secrets into build logs. Per the GitHub advisory for CVE-2025-30066, versions through 45.0.7 were affected between March 14 and 15, 2025.
The attack hit over 23,000 repositories. The script read secrets from the runner's memory and printed them to the logs. In public repositories, those logs are public.
The lessons: pin actions to full commit SHAs, keep secrets scoped to the jobs that need them, prefer OIDC over stored keys, and have a plan to rotate every secret a workflow could reach. Version 46.0.1 fixed the action.
@v45 or even @v45.0.7 still ran the malicious code, because the attacker pointed those existing tags at a new commit. Only a full commit SHA is fixed.27. What changed for JavaScript actions in 2026?
Runners switched to Node 24 by default on June 16, 2026, and removed Node 20 on September 23, 2026. The removal notice says the temporary ACTIONS_ALLOW_USE_UNSECURE_NODE_VERSION opt-out "is no longer available".
Action authors must set runs.using: node24 and publish a release. Workflow owners must update to action versions that support it.
Node 24 does not support macOS 13.4 and earlier or ARM32, so self-hosted runners on those platforms are no longer supported.
A pipeline that pins SHAs needs those bumps done on purpose, which is where Dependabot or Renovate earn their place.
28. Why did workflows using upload-artifact@v3 break?
GitHub stopped supporting v3 of actions/upload-artifact and actions/download-artifact on January 30, 2025, per the deprecation notice. v4 is faster, by up to 98% per GitHub, but behaves differently.
The main change: v4 artifacts are immutable, so several jobs can no longer upload into one artifact name. Each job uploads its own named artifact, and a later job downloads them by pattern and merges them.
Matrix builds that shared one artifact name were the ones that broke.
29. What changed in Argo CD 3.0?
Argo CD 3.0, released on May 6, 2025, was mostly about safer defaults. The 2.14 to 3.0 upgrade guide lists the changes:
- Resource tracking uses annotations instead of labels by default.
updateanddeleteRBAC rules apply only to the Application itself; its managed resources need explicitupdate/*ordelete/*rules.- RBAC for viewing logs is enforced by default.
- High-volume resources such as Endpoints, EndpointSlice and Lease are excluded from watching by default.
An upgrade that skips the RBAC review can silently remove permissions people relied on, so read the guide before bumping the chart.
30. Why did DORA add deployment rework rate?
It separates planned delivery from firefighting. A team can show high deployment frequency partly because it keeps shipping hotfixes. Rework rate counts the unplanned deploys caused by production incidents, so that pattern becomes visible.
DORA's guide groups the five metrics into throughput and instability. A candidate who knows the five, and can say which ones their last team measured and how, is ahead of one reciting the original four.
Signs of a Strong Answer
- They build once and deploy by digest, and can explain what breaks when environments rebuild.
- They pick a release strategy from the failure they fear most, not from habit.
- They plan database changes as expand and contract without prompting.
- They use OIDC for cloud access and pin third-party actions to commit SHAs.
- They treat flaky tests and slow pipelines as bugs with owners.
- They can name a DORA metric their team moved and what changed to move it.
Hiring DevOps Engineers
Engineers who can design and secure delivery pipelines are hard to find, and many strong ones work remotely from Asia. Second Talent matches companies with pre-vetted DevOps engineers, screened with questions like these.
Tell us the stack and we send a shortlist within 24 hours. Start hiring, or see our DevOps and Kubernetes interview guides.
Ready to hire? Hire DevOps Engineers: vetted AI-native talent, with first profiles in 24 hours.