TL;DR: MySQL interviews in 2026 test how a candidate finds and fixes slow queries, designs indexes, reasons about InnoDB locking and isolation, and runs replication. Candidates should know that MySQL 8.0 reached end of life in April 2026, that 8.4 and 9.7 are the LTS series, and that 8.4 removed the old MASTER and SLAVE statements.
MySQL 26.7.0, released on July 28, 2026, is the first MySQL version named by year and month. It is an Innovation release.
Teams that want long support run the LTS lines instead: 8.4, now at 8.4.12, and 9.7, the last LTS with the old numbering. Neither changes the interview basics: read the plan, fix the index, understand the locks.
- 1Upgrades must go 8.0 to 8.4 to 9.7; skipping an LTS series is not supported.
- 2MySQL 8.4 raised the default
innodb_io_capacityfrom 200 to 10000 and turned off the adaptive hash index by default. - 3
binlog_formatis deprecated: row-based logging is the only format with a future. - 4The slow query log's default threshold,
long_query_time, is 10 seconds, far too high for most web apps.
Fixing Slow Queries
1. How do you fix a slow MySQL query?
Find the queries that cost the most in total, read their execution plans, then fix the cause: usually a missing or unusable index, sometimes a query that asks for too much data. Changing server settings comes last.
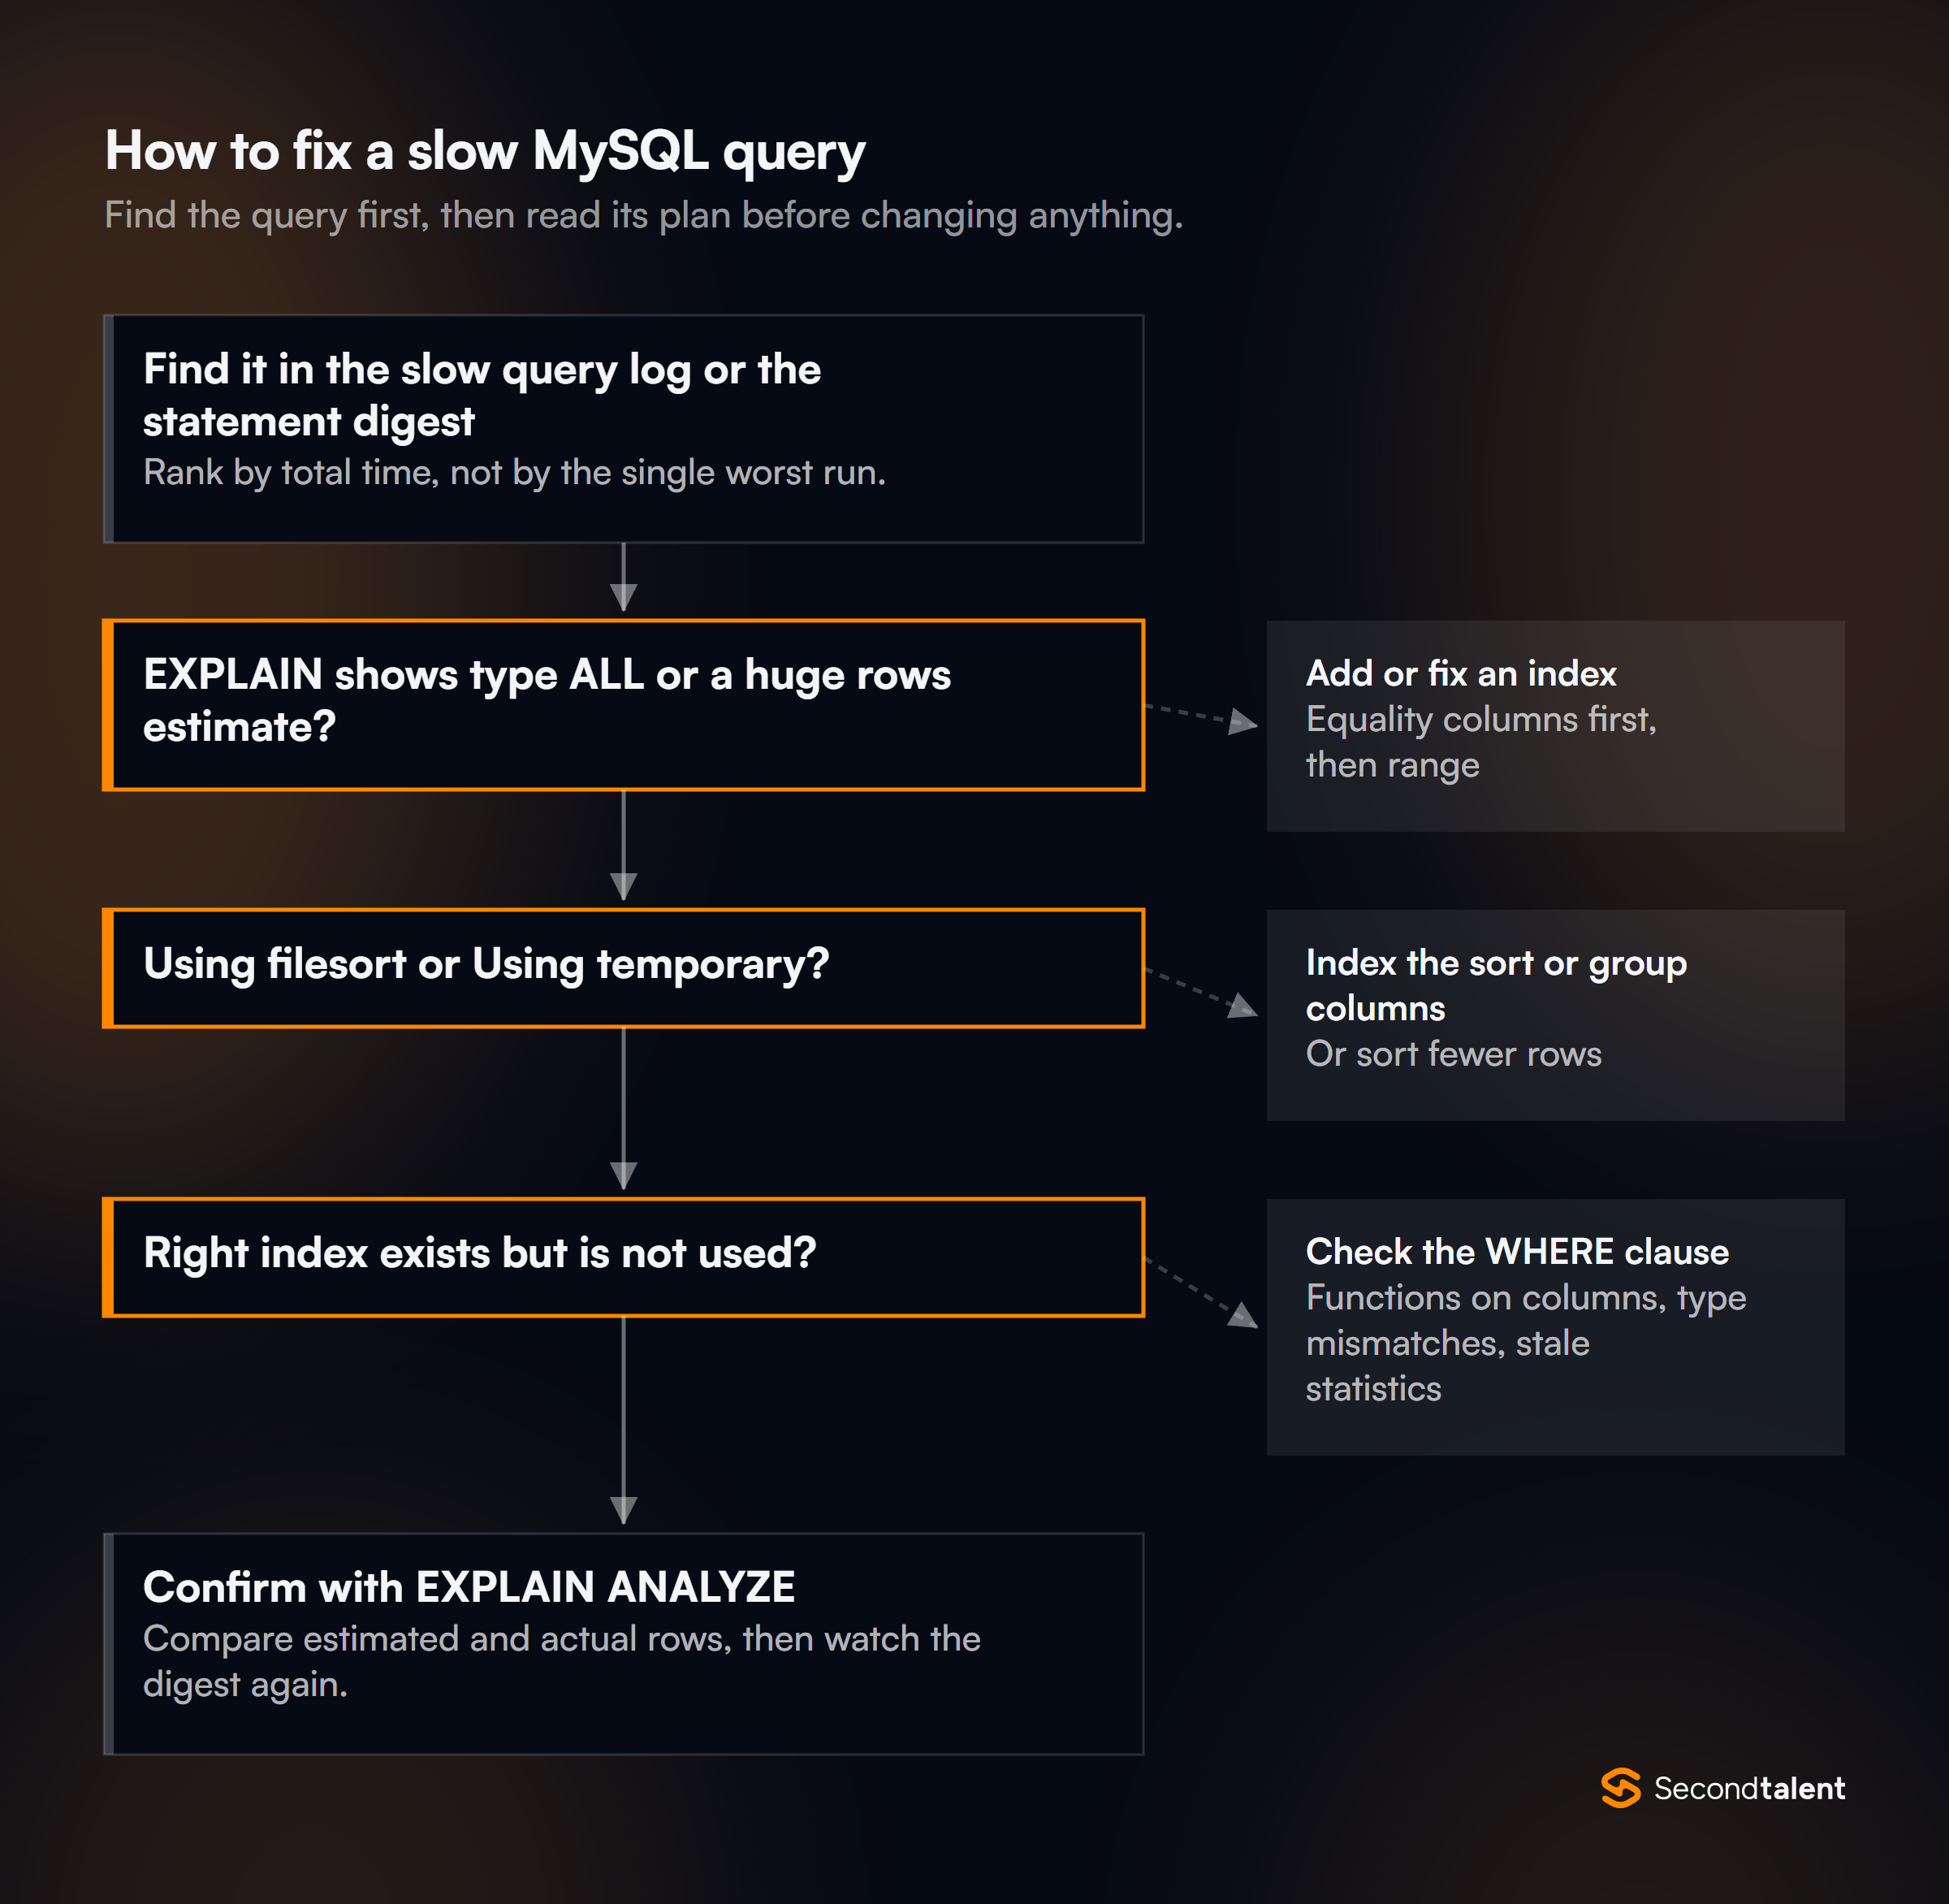
The order matters. A query that takes 50 ms but runs 20,000 times a minute costs more than a 5-second report that runs once an hour. After a change, confirm it with EXPLAIN ANALYZE and watch the same metrics again.
A fix that the optimizer ignores is not a fix.
2. How do you find the slow queries in the first place?
Use the slow query log or the Performance Schema statement digests. The slow query log records statements that run longer than long_query_time, which defaults to 10 seconds. Set it to something like 0.5 or 1 second for a web app.
SET GLOBAL slow_query_log = ON;
SET GLOBAL long_query_time = 0.5;
The digest table groups queries by shape, ignoring literal values, and ranks them by total time:
SELECT digest_text, count_star, sum_timer_wait/1e12 AS total_s
FROM performance_schema.events_statements_summary_by_digest
ORDER BY sum_timer_wait DESC LIMIT 10;
The sys schema wraps these in readable views, and pt-query-digest summarizes a slow log file. See the slow query log docs.
3. Which EXPLAIN columns matter most?
type, key, rows, filtered and Extra. type shows the access method, from best to worst roughly const, eq_ref, ref, range, index and ALL (a full table scan). key is the index chosen, and NULL means none.
rows times filtered estimates how many rows pass to the next step. In Extra, Using index means a covering index, while Using filesort and Using temporary point to sorting or grouping work that an index could avoid.
See the EXPLAIN output docs.
4. What does EXPLAIN ANALYZE add?
It runs the query and reports actual timings and row counts for each step, next to the optimizer's estimates. Plain EXPLAIN only shows the plan.
EXPLAIN ANALYZE
SELECT * FROM orders WHERE customer_id = 42 AND status = 'open';
The key signal is a large gap between estimated and actual rows. That means the optimizer is working from bad statistics, and it may pick the wrong index or join order. ANALYZE TABLE or a histogram usually fixes it.
Because it really executes the statement, be careful running it against slow queries on a busy primary.
5. Why would MySQL ignore an index that exists?
Usually because the query hides the column from the index, or the optimizer thinks a scan is cheaper. Common causes:
- A function on the column:
WHERE DATE(created_at) = '2026-09-01'. Rewrite as a range oncreated_at, or add a functional index. - A type mismatch: comparing a
VARCHARcolumn to a number forces a conversion on every row. - A leading wildcard:
LIKE '%term'cannot use a B-tree index. - The composite index does not start with the filtered column.
- The query matches so much of the table that a scan really is cheaper, or the statistics say so.
6. Why is LIMIT with a large OFFSET slow, and what is the fix?
Because MySQL still reads and throws away every skipped row. LIMIT 20 OFFSET 100000 reads 100,020 rows to return 20.
Keyset pagination fixes it: remember the last key from the previous page and continue from there, which uses the index directly.
SELECT id, title FROM posts
WHERE id < 918273
ORDER BY id DESC
LIMIT 20;
The trade-off is that users cannot jump to page 5,000 directly, which most feeds and APIs do not need.
Indexes
7. What is the difference between a clustered and a secondary index in InnoDB?
The clustered index is the table: InnoDB stores rows in primary key order inside it.
A secondary index stores the indexed columns plus the primary key value, so a lookup through it finds the key first, then reads the row from the clustered index.
Two design rules follow. Keep the primary key short, because every secondary index repeats it.
Prefer keys that insert in order, such as an auto-increment integer or a time-ordered UUID, because random UUIDv4 keys insert all over the tree and split pages.
If a table has no primary key, InnoDB uses the first unique non-null index, or adds a hidden row ID.
8. What is a covering index?
An index that contains every column a query needs, so MySQL answers from the index alone without reading the rows. EXPLAIN shows Using index in Extra.
CREATE INDEX idx_orders_cust_status_total
  ON orders (customer_id, status, total);

SELECT status, total FROM orders WHERE customer_id = 42;
Because secondary indexes already include the primary key, a query that selects only indexed columns plus id is covered too. Covering indexes cost write speed and space, so use them for hot queries, not every query.
9. How do you choose the column order in a composite index?
Put columns filtered by equality first, then the one column used for a range or sort. MySQL can use a leftmost prefix of the index, and it stops using later columns after the first range condition.
For WHERE tenant_id = ? AND status = ? AND created_at > ? ORDER BY created_at, the index (tenant_id, status, created_at) serves the filter and the sort. Putting created_at first would not.
The old rule "highest cardinality first" is a weak guide. The query's shape matters more than how selective each column is on its own.
10. What are invisible and functional indexes for?
An invisible index is kept up to date but ignored by the optimizer, so you can test dropping an index safely. Make it invisible, watch performance, and drop it or make it visible again in seconds, with no rebuild.
ALTER TABLE orders ALTER INDEX idx_old INVISIBLE;
CREATE INDEX idx_email_lower ON users ((LOWER(email)));
A functional index, the second line, indexes an expression. Queries that filter on LOWER(email) can then use it. JSON columns use the same idea through generated columns, or multi-valued indexes for arrays.
Transactions and Locks
11. How do the isolation levels behave in InnoDB?
InnoDB supports the four standard levels and defaults to REPEATABLE READ. Each level blocks more read anomalies than the one before it, at some cost to concurrency.
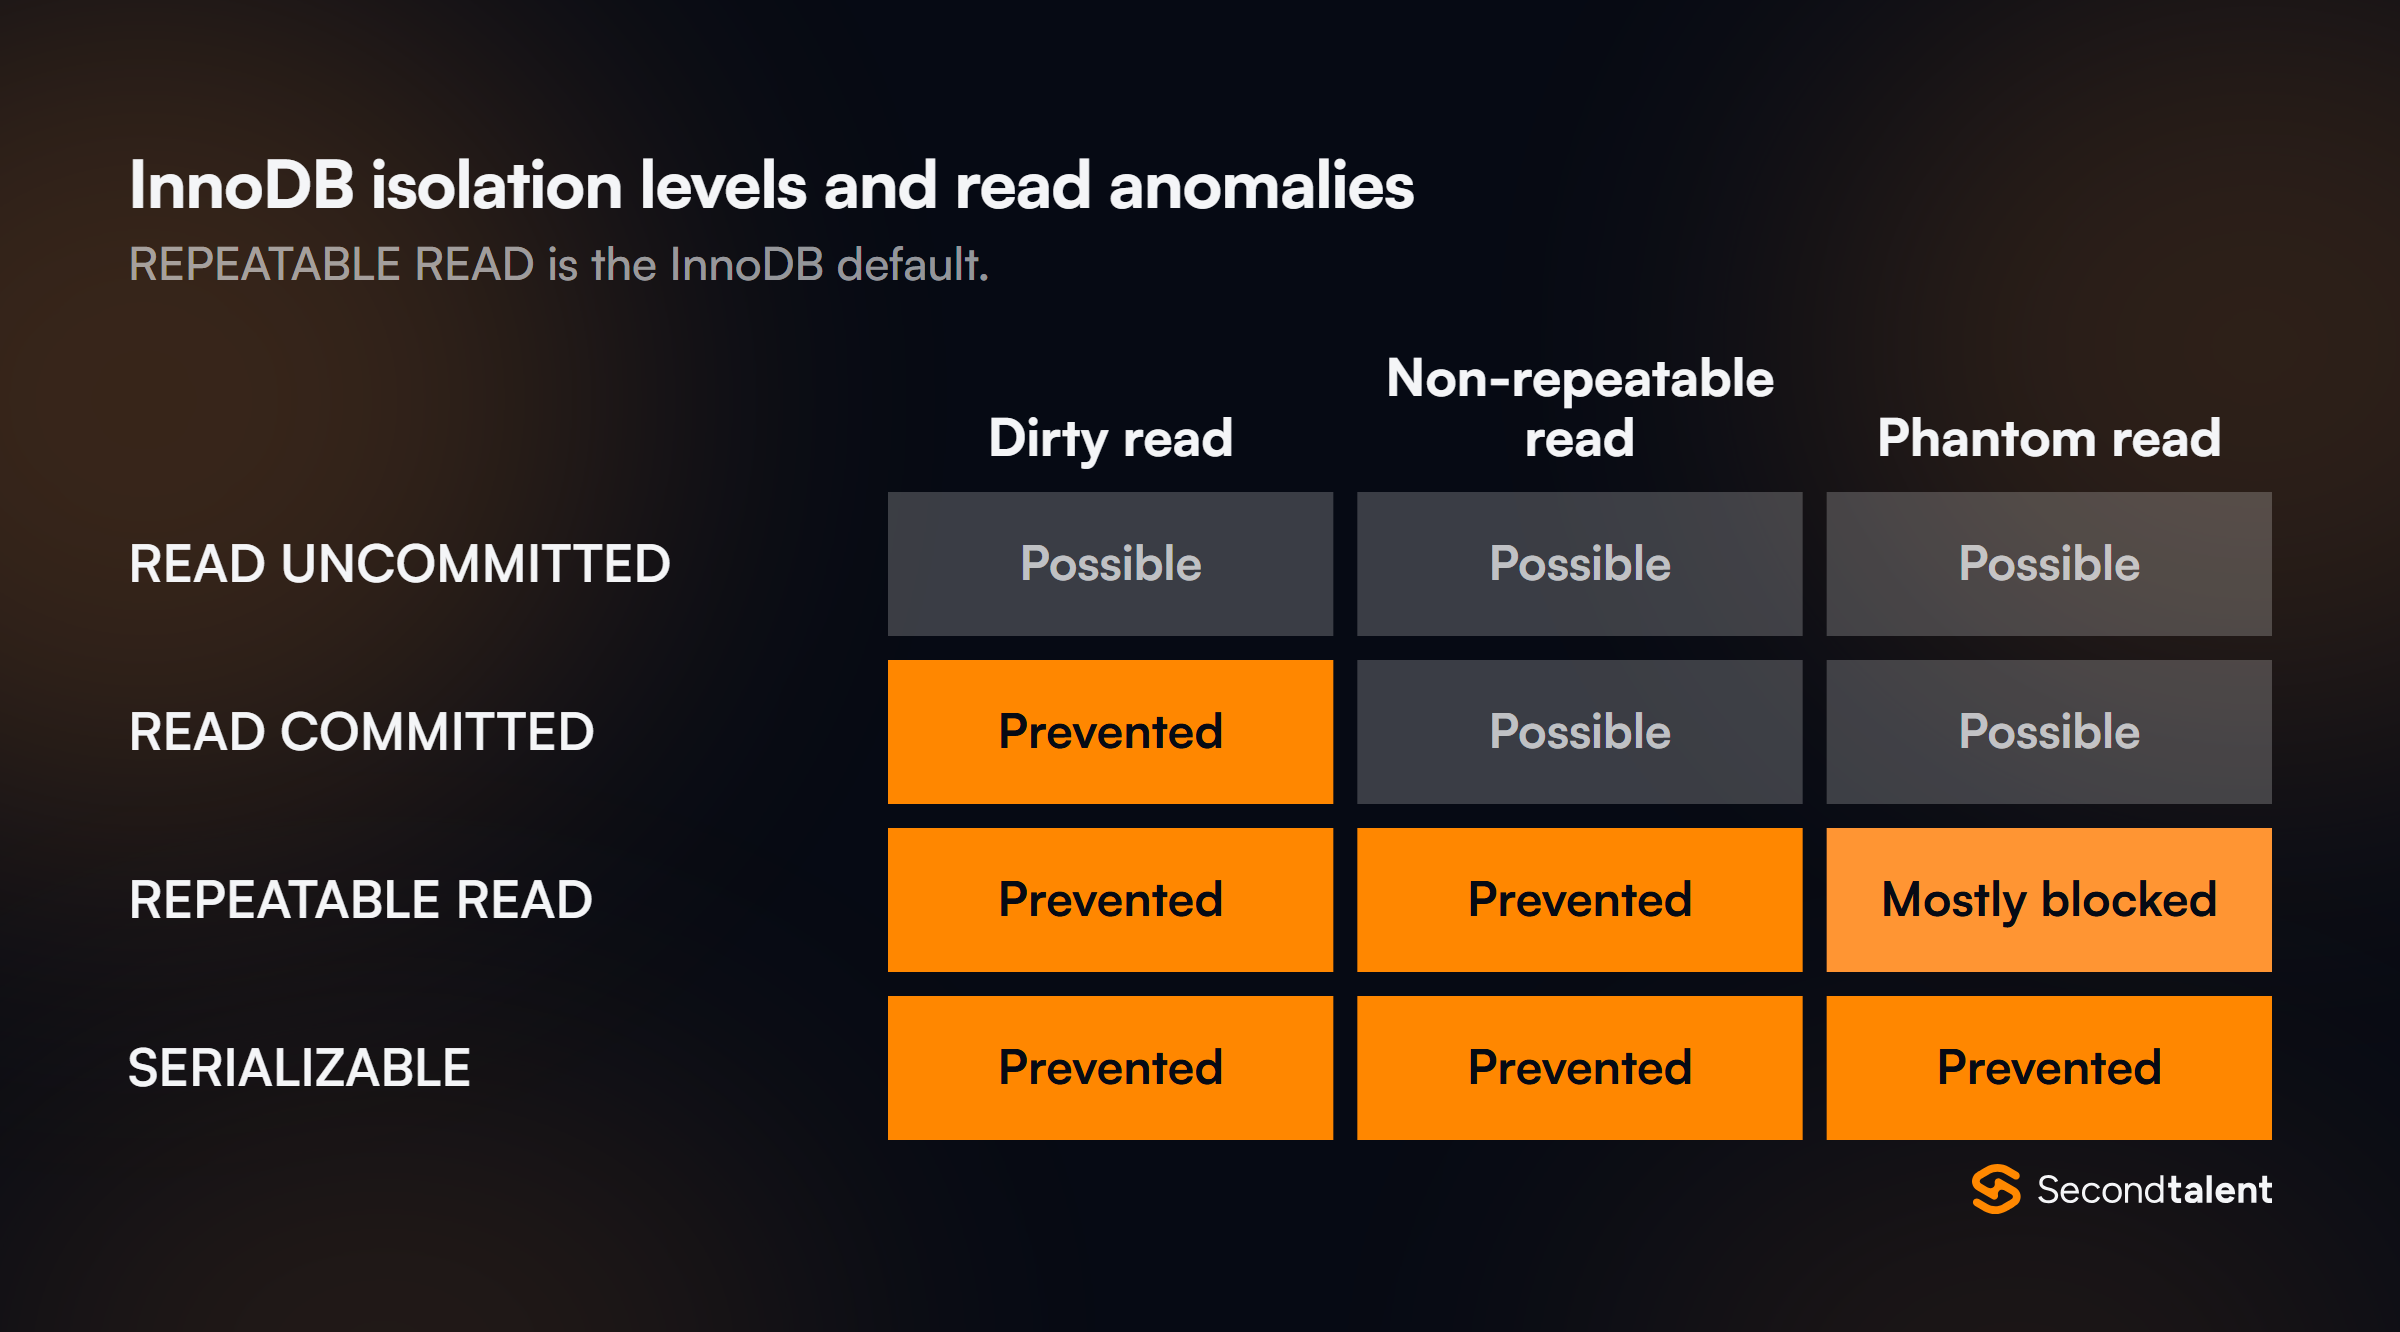
InnoDB's REPEATABLE READ goes further than the SQL standard requires. Plain reads use a snapshot taken at the first read, and locking reads use next-key locks, so phantoms are mostly blocked.
Many teams switch to READ COMMITTED to reduce gap locking and deadlocks, accepting that a transaction can see other transactions' commits. See the isolation level docs.
12. What is MVCC, and how does a consistent read work?
MVCC keeps older versions of rows in undo logs, so readers see a consistent snapshot without locking what writers change. A plain SELECT never blocks and is never blocked by row locks.
The catch is long transactions. A transaction left open for hours forces InnoDB to keep every older row version it might still need. The history list grows, purge falls behind, and queries slow down.
SHOW ENGINE INNODB STATUS shows the history list length, and information_schema.innodb_trx finds the old transaction.
13. What are gap locks and next-key locks?
A gap lock locks the space between index records, stopping other transactions from inserting into it. A next-key lock is a record lock plus a lock on the gap before that record.
InnoDB uses them in REPEATABLE READ for locking reads and updates, which is how it blocks phantom rows.
They also explain surprising lock waits. An UPDATE with a range condition, or one on a column without an index, can lock far more than the rows it changes. The phantom rows docs walk through an example.
14. How do you handle deadlocks?
Expect them, retry them, and reduce them. InnoDB detects a deadlock and rolls back one transaction with error 1213, so the app must catch it and retry the whole transaction.
To make them rarer: touch rows in the same order in every code path, keep transactions short, and index the columns in WHERE clauses of updates so fewer rows get locked.
SHOW ENGINE INNODB STATUS prints the latest deadlock with both statements and the locks they held, which is usually enough to find the conflicting code paths.
15. How do you build a job queue on a MySQL table?
Use SELECT ... FOR UPDATE SKIP LOCKED, so each worker claims rows that no other worker has locked, without waiting.
START TRANSACTION;
SELECT id FROM jobs
WHERE status = 'pending'
ORDER BY id
LIMIT 10
FOR UPDATE SKIP LOCKED;
-- mark them running, commit, then process
COMMIT;
Without SKIP LOCKED, workers queue behind each other on the same rows. NOWAIT is the other option: it fails at once instead of waiting. Both are documented under locking reads.
InnoDB Internals
16. How do you size the InnoDB buffer pool?
Big enough to hold the working set, the data and indexes the app touches often. The buffer pool docs say that on dedicated servers, "up to 80% of physical memory is often assigned" to it.
Leave room for per-connection buffers, temporary tables and the OS.
Check the result through the ratio of Innodb_buffer_pool_reads (disk reads) to Innodb_buffer_pool_read_requests. innodb_buffer_pool_size can be changed online, so a resize does not need a restart.
17. What are the redo log, the undo log and the binary log?
The redo log makes committed changes durable, the undo log lets InnoDB roll back and serve old row versions, and the binary log records changes for replication and point-in-time recovery.
- Redo log: InnoDB's write-ahead log. After a crash, InnoDB replays it to recover committed work not yet written to data files.
- Undo log: old row versions, used for rollback and for MVCC snapshots.
- Binary log: a server-level log of committed changes, read by replicas and by recovery tools.
With innodb_flush_log_at_trx_commit=1 and sync_binlog=1, a committed transaction survives a crash. Relaxing them buys write speed at the cost of losing recent commits.
18. How do you change a large table's schema without downtime?
Use an instant or online ALTER TABLE where MySQL supports it, and an online schema change tool where it does not. Per the online DDL docs, ALGORITHM=INSTANT can add a column at any position by changing only metadata.
ALTER TABLE orders ADD COLUMN notes TEXT, ALGORITHM=INSTANT;Asking for the algorithm explicitly makes the statement fail instead of silently copying the table.
For changes that need a rebuild, such as changing a column type, gh-ost or pt-online-schema-change copy the table in the background and swap it in. Online DDL on a primary still creates replication lag, since the replica runs the same work.
Schema Design
19. DATETIME or TIMESTAMP?
TIMESTAMP stores a UTC instant and converts it to and from the session time zone; DATETIME stores the value exactly as given. TIMESTAMP ends at 2038-01-19, which rules it out for dates far in the future, such as a 20-year contract end date.
- Converted to UTC on write, back on read
- Ends at 2038-01-19
- Result depends on the session time zone
- Stored exactly as given, no conversion
- Years 1000 to 9999
- The app decides the time zone
A common convention: store instants as DATETIME in UTC, with the app handling time zones, and keep the session time zone at UTC so nothing converts silently. Either way, pick one rule for the whole schema.
20. How do you query and index JSON in MySQL?
Store it in a JSON column, read values with -> and ->>, and index the paths you filter on through a generated column or a functional index.
ALTER TABLE events
  ADD COLUMN user_id INT
  GENERATED ALWAYS AS (payload->>'$.user.id') STORED,
  ADD INDEX idx_events_user (user_id);
For arrays, a multi-valued index with CAST(... AS type ARRAY) speeds up MEMBER OF and JSON_CONTAINS. JSON suits flexible attributes. Fields you join or filter on often should be real columns.
21. When is partitioning worth it?
Mainly for dropping old data fast and for queries that always filter on the partition key. Dropping a month's partition is nearly instant, while a DELETE of millions of rows is slow and bloats undo and the binary log.
Partitioning is not a general speed-up. Every unique key, including the primary key, must include the partition key, and queries that do not filter on it check every partition. See the partitioning docs.
22. Why use utf8mb4 instead of utf8?
Because MySQL's utf8 is an alias for utf8mb3, which stores at most 3 bytes per character and cannot hold emoji or many rarer characters. utf8mb4 is full UTF-8 and has been the default character set since MySQL 8.0.
The utf8 alias is deprecated, per the utf8mb3 docs. Old schemas still carry it and need a conversion that rewrites the table. Index length limits are counted in bytes, so long VARCHAR indexes may need a prefix after the switch.
Replication and HA
23. How does MySQL replication work?
The source writes committed changes to its binary log. Each replica's receiver thread copies those events into a local relay log, and applier threads run them.
Replication is asynchronous by default, so a replica can fall behind or lose the last transactions if the source dies.
Use GTIDs so every transaction has a global ID, which makes failover and re-pointing replicas far simpler than tracking file names and positions.
Semi-synchronous replication makes the source wait until a replica has received the transaction before confirming the commit. The replication docs cover both.
24. Which binary log format should you use?
Row-based, the default. It logs the changed rows themselves, so replicas end up with the same data even for statements with UUID(), NOW() or LIMIT without ORDER BY.
The choice is closing anyway. The binary log docs state that binlog_format is deprecated and that "only row-based logging should be employed".
Statement and mixed formats may be removed later. binlog_row_image=MINIMAL can shrink row events when size is a concern.
25. How do you measure and reduce replication lag?
Check Seconds_Behind_Source in SHOW REPLICA STATUS for a rough view, and use a heartbeat table, such as pt-heartbeat, for an exact one.
Seconds_Behind_Source only covers events the replica has already received, so it can look healthy while the receiver itself lags.
Lag usually comes from large transactions, long-running DDL, or an applier that cannot keep up. Break big writes into batches, run replicas on hardware as fast as the source, and use parallel appliers with replica_parallel_workers.
Reads that must see the user's own write should go to the source, or wait for the GTID to reach the replica.
26. What are Group Replication and InnoDB Cluster?
Group Replication keeps a group of servers in sync through a consensus protocol, so a transaction commits only when a majority agrees.
InnoDB Cluster packages it with MySQL Shell for setup and MySQL Router for routing clients to the current primary.
The default single-primary mode elects a new primary automatically when the old one fails, with no lost commits. It needs at least three members to survive one failure, and all tables need a primary key.
Large transactions and cross-region latency both slow commits, because every commit waits for the group.
What Changed Recently
27. What is the MySQL LTS and Innovation release model?
LTS series change only through fixes and get long support; Innovation releases add features and are supported only until the next one.
Per the release model docs, an LTS series gets "5 years of premier support and 3 years of extended support". Features can be added or removed only in the first release of an LTS series.
Both tracks are production quality. Most teams pick LTS, because Innovation releases can change behavior and remove features between versions. Innovation suits teams with strong automated tests who want new features early.
28. What does MySQL 8.0's end of life mean for a team still on it?
No more fixes: the 8.0 release notes say that "as of April 2026, with version 8.0.46, MySQL 8.0 reaches End of Life". The upgrade path is 8.4 LTS first, since skipping an LTS series is not supported.
The 8.0 to 8.4 upgrade has real work in it. Replication scripts using removed statements break (question 29). Accounts on mysql_native_password cannot log in until the plugin is enabled or they move to caching_sha2_password.
Several InnoDB defaults change, so benchmark before and after rather than assuming the same performance.
29. Which statements did MySQL 8.4 remove?
The old MASTER and SLAVE replication statements, which now fail with a syntax error. Per the 8.4 "What Is New" page:
CHANGE MASTER TOis nowCHANGE REPLICATION SOURCE TO.SHOW SLAVE STATUSis nowSHOW REPLICA STATUS.START SLAVEandSTOP SLAVEare nowSTART REPLICAandSTOP REPLICA.SHOW MASTER STATUSis nowSHOW BINARY LOG STATUS.RESET MASTERis nowRESET BINARY LOGS AND GTIDS.
Monitoring checks, failover scripts and ORMs that run these statements need updating before the upgrade, not after.
innodb_adaptive_hash_index and change buffering by default, raised innodb_io_capacity to 10000 and innodb_log_buffer_size to 64 MiB, and disabled mysql_native_password unless enabled at startup.30. What is MySQL 9.7, and why does it matter for upgrades?
It is the LTS series after 8.4, first released on April 21, 2026, and the last one with the old numbering. The 26.7 release model page calls 9.7.x LTS "the final release line using the sequential versioning model".
That page also says only 9.7.x LTS can upgrade directly into the calendar-versioned releases. So a team on 8.0 in 2026 has a two-hop path to reach current releases: 8.0 to 8.4, then 8.4 to 9.7.
Signs of a Strong Answer
- They rank queries by total time from the digest before tuning anything.
- They read
EXPLAIN ANALYZEfor gaps between estimated and actual rows, not just thetypecolumn. - They order composite index columns by equality then range, and can say why.
- They know InnoDB's
REPEATABLE READuses snapshots and next-key locks, and whenREAD COMMITTEDis the better default. - They retry deadlocked transactions in code and use
SKIP LOCKEDfor queues. - They use the 8.4 replication syntax and know the 8.0 to 8.4 to 9.7 upgrade path.
Hiring MySQL Developers
Engineers who can tune MySQL under real load are rarer than those who can write SQL, and many strong ones work remotely from Asia. Second Talent matches companies with pre-vetted back-end developers, screened with questions like these.
Tell us the stack and we send a shortlist within 24 hours. Start hiring, or see our PostgreSQL and Redis interview guides.